Introducing Mistral Medium 3: our new multimodal model offering SOTA performance at 8X lower cost. – A new class of models that balances performance, cost, and deployability.
– High performance in coding and function-calling.
– Full enterprise capabilities, including hybrid or
MULTIMODAL AI
-
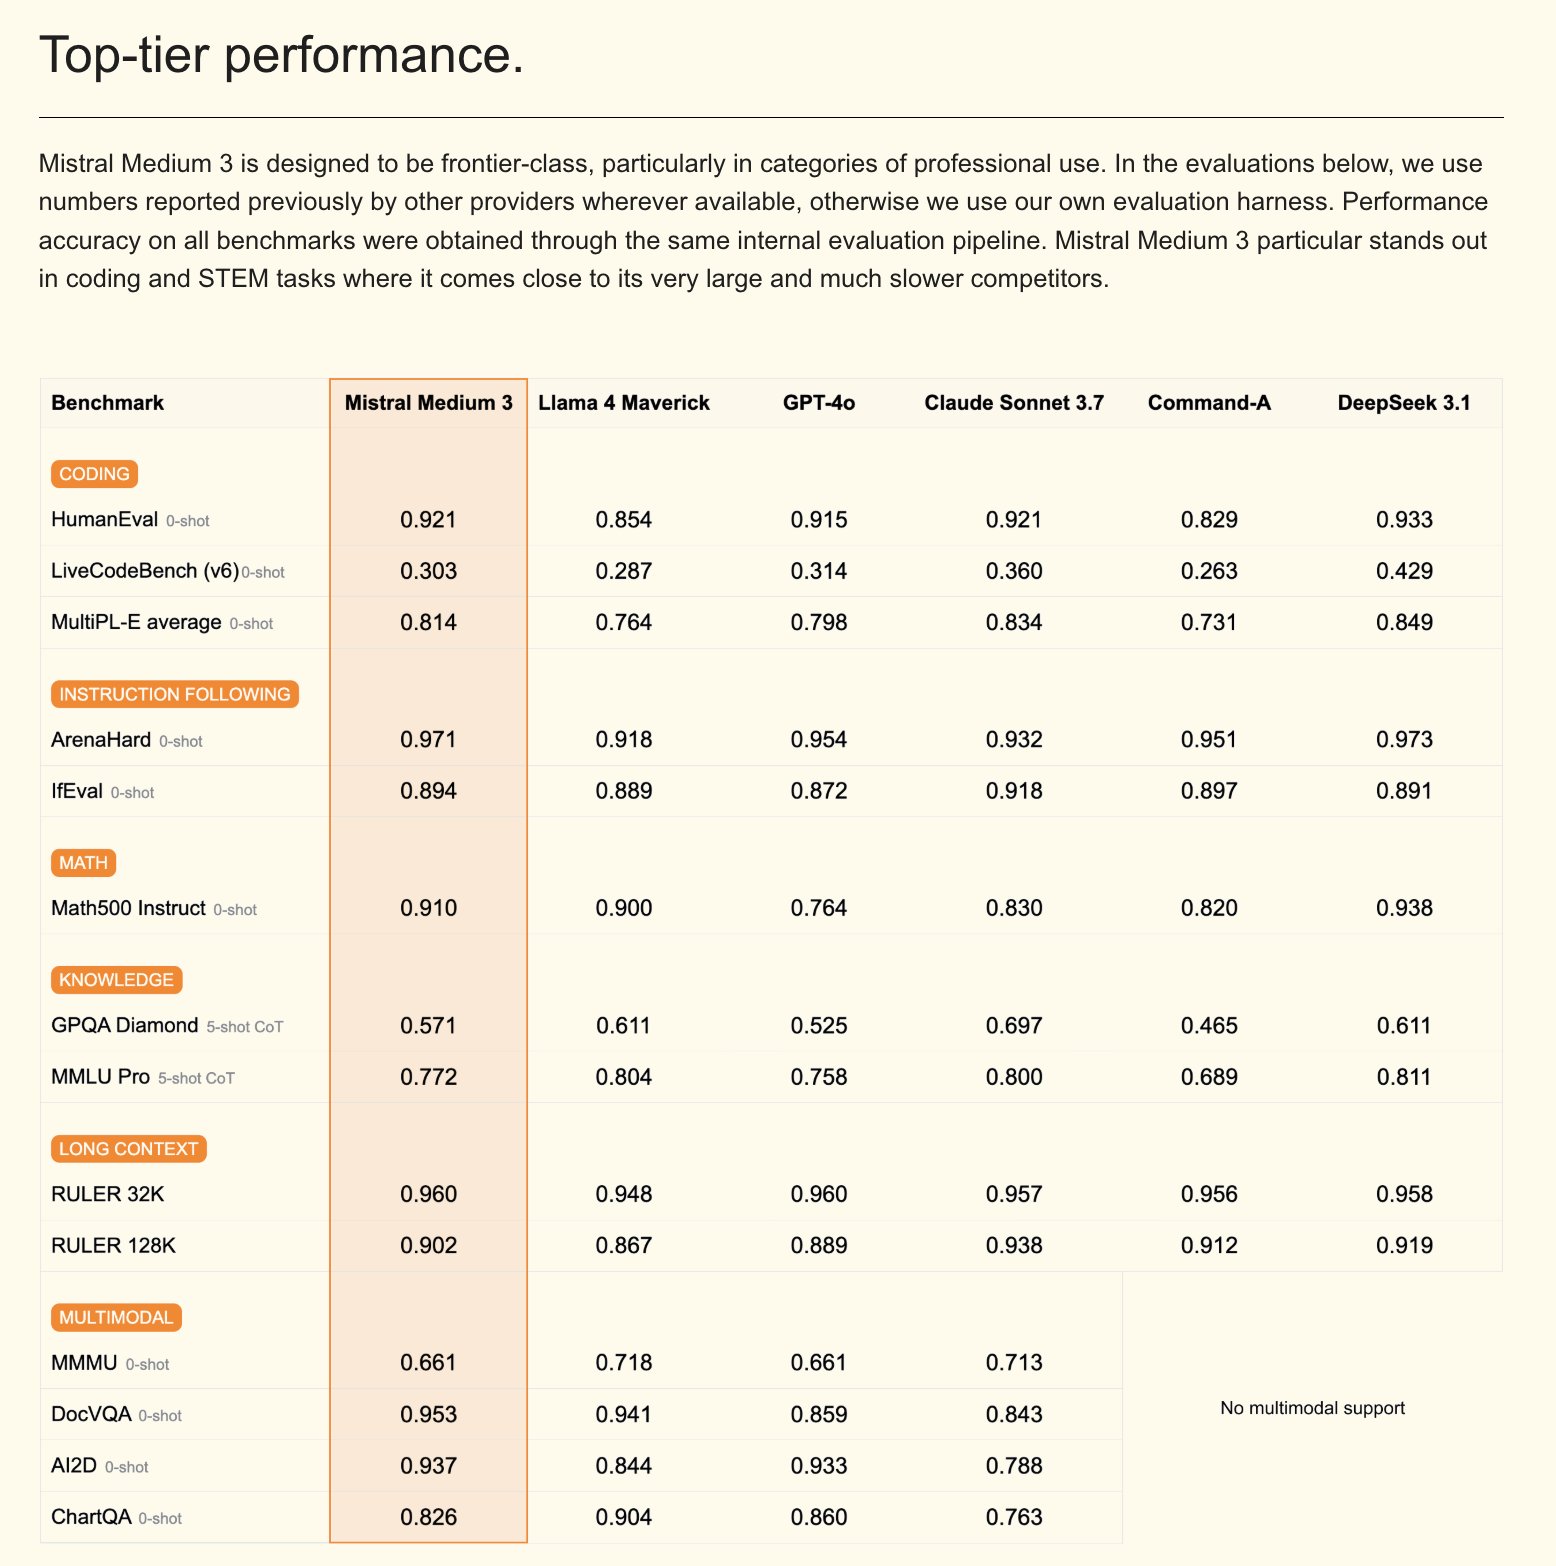
Mistral Medium 3: New Multimodal Model SOTA Performance Lower Cost
By
–
-
Upcoming Multimodal Features and Capabilities for Grok AI
By
–
Looking at upcoming Grok features:
— 🚨 AI News | TestingCatalog (@testingcatalog) 7 mai 2025
– It could be used as a voice-first application
– It will get a new Spatial UI
– It will be optimised for 1 hand use
Should we expect Grok 3.5 to excel at real-world understanding, which would act as your assistant – see, hear and speak! https://t.co/B4IJ4Moxr2 pic.twitter.com/gHjogP9kVfLooking at upcoming Grok features:
– It could be used as a voice-first application
– It will get a new Spatial UI – It will be optimised for 1 hand use Should we expect Grok 3.5 to excel at real-world understanding, which would act as your assistant – see, hear and speak! -
Comparison of real-time AI voice generation capabilities
By
–
This is better than ElevenLabs for real-time stuff. Way more fluid and you actually get emotional nuance.
-
Higgsfield AI Generates Superhero Visual Effects for $9
By
–
C’est terminé.
— VISION IA (@vision_ia) 7 mai 2025
Higgsfield ridiculise OpenAI Sora.
Des créateurs génèrent déjà des effets spéciaux dignes de super-héros depuis leur ordinateur portable… pour seulement 9 $.
Vous pouvez écrire une simple requête comme “un snowboarder qui se transforme en flammes” — et le… pic.twitter.com/UvvmPwJasiC’est terminé. Higgsfield ridiculise OpenAI Sora. Des créateurs génèrent déjà des effets spéciaux dignes de super-héros depuis leur ordinateur portable… pour seulement 9 $. Vous pouvez écrire une simple requête comme “un snowboarder qui se transforme en flammes” — et le
-
The rapid evolution of AI-driven voice UX
By
–
Give it 6 months and people won’t even realize they’re talking to AI. The future of voice UX is happening fast.
-
Lighttricks Releases LTXV-13B Open-Source Video Generation AI
By
–
Lighttricks released LTXV-13B, an open-source AI for video generation
— Rowan Cheung (@rowancheung) 7 mai 2025
—Multiscale rendering for creating smoother content, 30x faster
—Can run on consumer GPUs
—Includes camera motion control, keyframe editing, and multi-shot sequencingpic.twitter.com/2AhuRIlBUZLighttricks released LTXV-13B, an open-source AI for video generation —Multiscale rendering for creating smoother content, 30x faster
—Can run on consumer GPUs
—Includes camera motion control, keyframe editing, and multi-shot sequencing -
HeyGen Launches Avatar IV for Expressive AI Animations
By
–
HeyGen dropped Avatar IV, an AI for expressive animations
— Rowan Cheung (@rowancheung) 7 mai 2025
With one photo and voice script, its audio to expression engine captures tone, rhythm, and emotion to generate facial motion
Also supports different subjects, camera shots, and formatspic.twitter.com/IyLo5uhcGDHeyGen dropped Avatar IV, an AI for expressive animations With one photo and voice script, its audio to expression engine captures tone, rhythm, and emotion to generate facial motion Also supports different subjects, camera shots, and formats
-
Google Releases Gemini 2.5 Pro I/O Edition with Enhanced Performance
By
–
Google released an early preview of Gemini 2.5 Pro I/O Edition, delivering:
— Rowan Cheung (@rowancheung) 7 mai 2025
—Enhanced performance for frontend and UI dev, code editing, and agentic workflows
—Top score on LM Arena and WebDev Arena, beating Claude 3.7 Sonnet
—Video understanding featurespic.twitter.com/Mw5xCulLOoGoogle released an early preview of Gemini 2.5 Pro I/O Edition, delivering: —Enhanced performance for frontend and UI dev, code editing, and agentic workflows
—Top score on LM Arena and WebDev Arena, beating Claude 3.7 Sonnet
—Video understanding features -
Demonstration of AI voice capabilities in a video
By
–
* Voice is working too, just wasn’t captured there on the vid
