It's a very small edge model. Grok on the other hand is a huge model.
MULTIMODAL AI
-
Motorola Launches Copilot Vision AI Feature for Users
By
–
Now live for Motorola users in moto ai: Copilot Vision, so you can show, not tell.
— Mustafa Suleyman (@mustafasuleyman) 6 août 2025
Translating street signs? Figuring out what's wrong with your vacuum?
Here to help, in 50+ languages.
Just one click away, right on your Motorola device. pic.twitter.com/aJDgz4nAPbNow live for Motorola users in moto ai: Copilot Vision, so you can show, not tell.
Translating street signs? Figuring out what's wrong with your vacuum?
Here to help, in 50+ languages.
Just one click away, right on your Motorola device. -
Training Data Quality Impact on AI Model Outputs
By
–
If anyone is unlucky enough to let their model train on my collection of SVGs of pelicans riding bicycles they're going to get some VERY weird looking pelicans riding bicycles
-
Multimodal AI Risks: Vision Models and Safety Concerns
By
–
"The marginal risks of open models have been shown to not be as extreme as many people thought (at least for text only — multimodal is far riskier)." What makes multimodal riskier – assuming you mean vision is it concerns over surveillance, facial recognition etc?
-

Google’s Genie 3: Analyzing World Model Capabilities
By
–
¡NUEVO VÍDEO en el LAB! El nuevo sistema Genie 3 de Google es todo un hito en lo que a Modelos del Mundo se refiere. Capaz de crear instantáneamente cualquier mundo que imaginemos, listo para explorar! Hoy analizamos sus resultados e implicaciones, link a continuación
-

RunwayML Aleph: AI Video Editing with Text Prompts
By
–
introducing Aleph.
— KREA AI (@krea_ai) 6 août 2025
this new video model from RunwayML allows you to edit videos using text prompts.
try it now in Krea Restyle. pic.twitter.com/pLlsWWttgwintroducing Aleph. this new video model from RunwayML allows you to edit videos using text prompts. try it now in Krea Restyle.
-
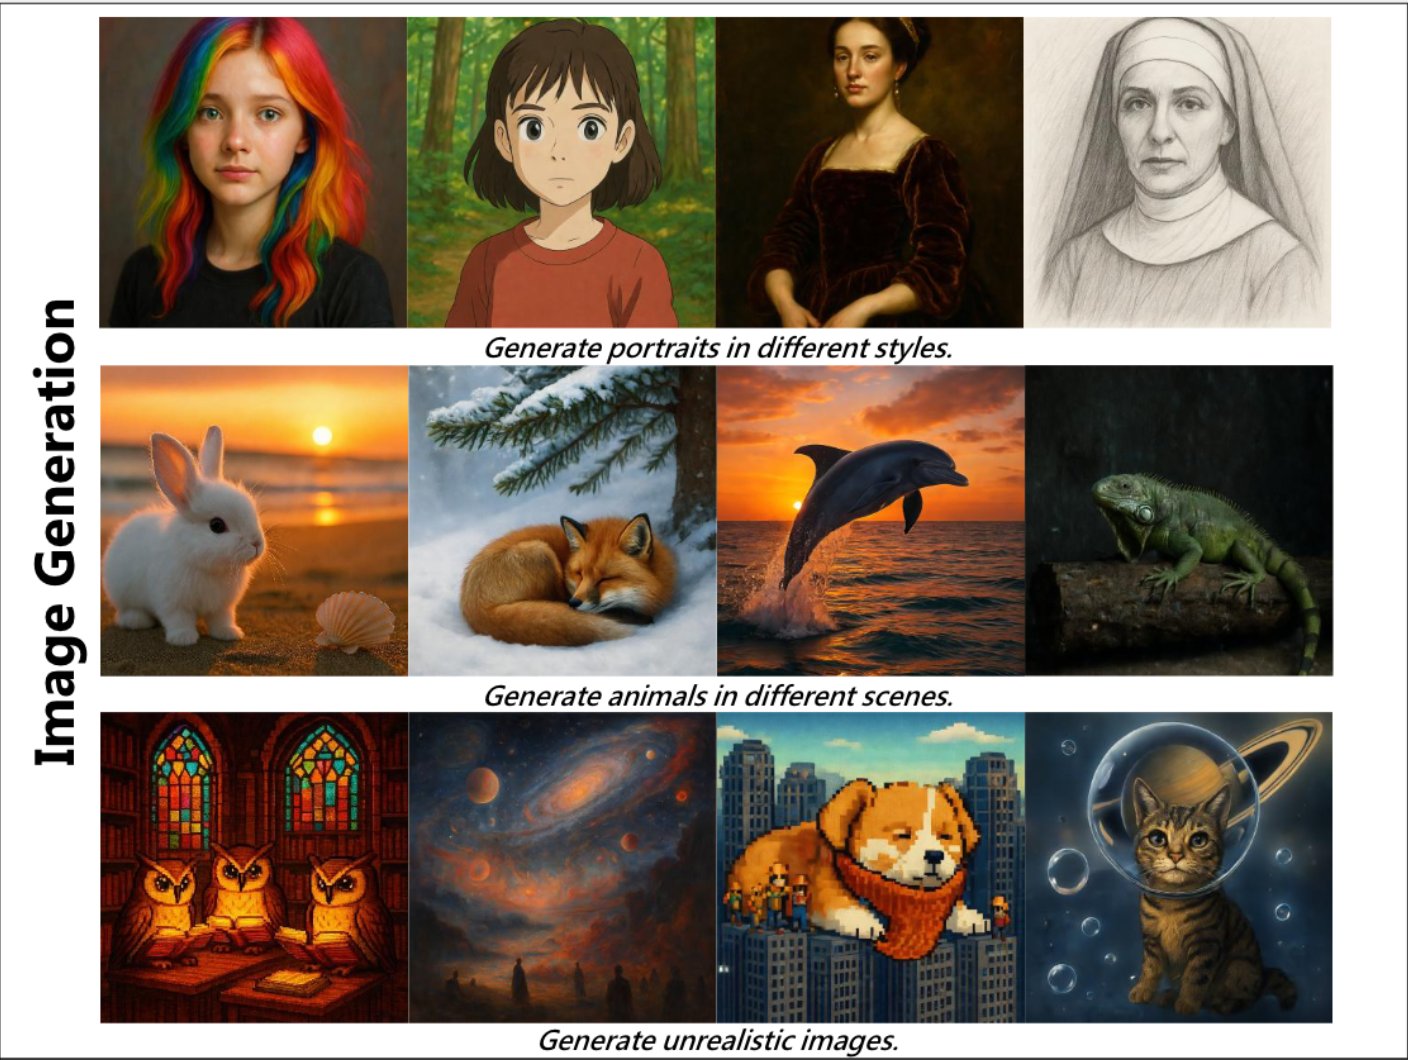
Skywork UniPic: Unified Autoregressive Model for Visual Tasks
By
–
Skywork UniPic Unified Autoregressive Modeling for Visual Understanding and Generation
-
Robot Responses to Physical Stimuli and Gestural Communication
By
–
…such as kicking (pain), and other affective stimuli 4. The robot's responses to higher level emblems, eg. waving or heart gestures 5. The robot's responses to pointing to things in context, like clothing 6. The robot's responses to roleplay, especially based on its looks
→ View original post on X — @petitegeek, 2025-08-06 13:14 UTC
-
Testing Robot’s Sensing, Motor Abilities and Emotional Responses
By
–
In our preliminary experiments, people tested: 1. The robot's sensing abilities, such as whether it could track them visually or respond to poking 2. The robot's motor abilities, or whether they could copy their movements 3. The robot's responses to smiling, aggression,…
→ View original post on X — @petitegeek, 2025-08-06 13:14 UTC
-
Genie 3 Marks Turning Point for Real-Time Interactive World Models
By
–
Genie 3 ressemble à un moment charnière pour les world models : nous pouvons désormais générer des simulations interactives en temps réel, de plusieurs minutes, dans n’importe quel monde imaginable.
— VISION IA (@vision_ia) 6 août 2025
Cela pourrait bien être la pièce manquante pour une AGI incarnée…
Ce que… pic.twitter.com/5Nw5BBQjQnGenie 3 ressemble à un moment charnière pour les world models : nous pouvons désormais générer des simulations interactives en temps réel, de plusieurs minutes, dans n’importe quel monde imaginable. Cela pourrait bien être la pièce manquante pour une AGI incarnée… Ce que