AI Dynamics

Global AI News Aggregator

About

MULTIMODAL AI

  • Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Processing
    Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Processing

    If you found it useful, reshare it with your network Follow me → @Sumanth_077 for more insights and tutorials on AI Engineering! nitter.net/Sumanth_077/status/204… Sumanth (@Sumanth_077) Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments! — https://nitter.net/Sumanth_077/status/2041157100840051111#m

    → View original post on X — @sumanth_077, 2026-04-06 14:14 UTC
  • Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Recognition
    Microsoft Open Sources VibeVoice-ASR for 60-Minute Speech Recognition

    Microsoft just fixed a major speech recognition problem! They open sourced VibeVoice-ASR, a speech-to-text model that processes 60 minutes of audio in a single pass. Here's the problem with most ASR models. They slice audio into short chunks, usually 30 seconds or less. Process each chunk separately. Lose speaker context between segments. You get disconnected transcripts that can't track who said what across a full meeting. VibeVoice-ASR handles 60 minutes of continuous audio without chunking. The model maintains global context across the entire hour. The output is structured. Who spoke, when they spoke, what they said. Speaker diarization, timestamps, and transcription all in one pass. Key features: • 60-minute single-pass processing without chunking audio • Structured output: speaker labels, timestamps, and content combined • Customized hotwords: provide specific names or technical terms to improve accuracy • Multilingual support: 50+ languages • Joint ASR, diarization, and timestamping in one model The model is 7B parameters. Available on Hugging Face with finetuning code included. I've shared the repo link in the comments!

    → View original post on X — @sumanth_077, 2026-04-06 14:12 UTC

  • Kinovi AI Video Director Tool Built on Seedance 2.0
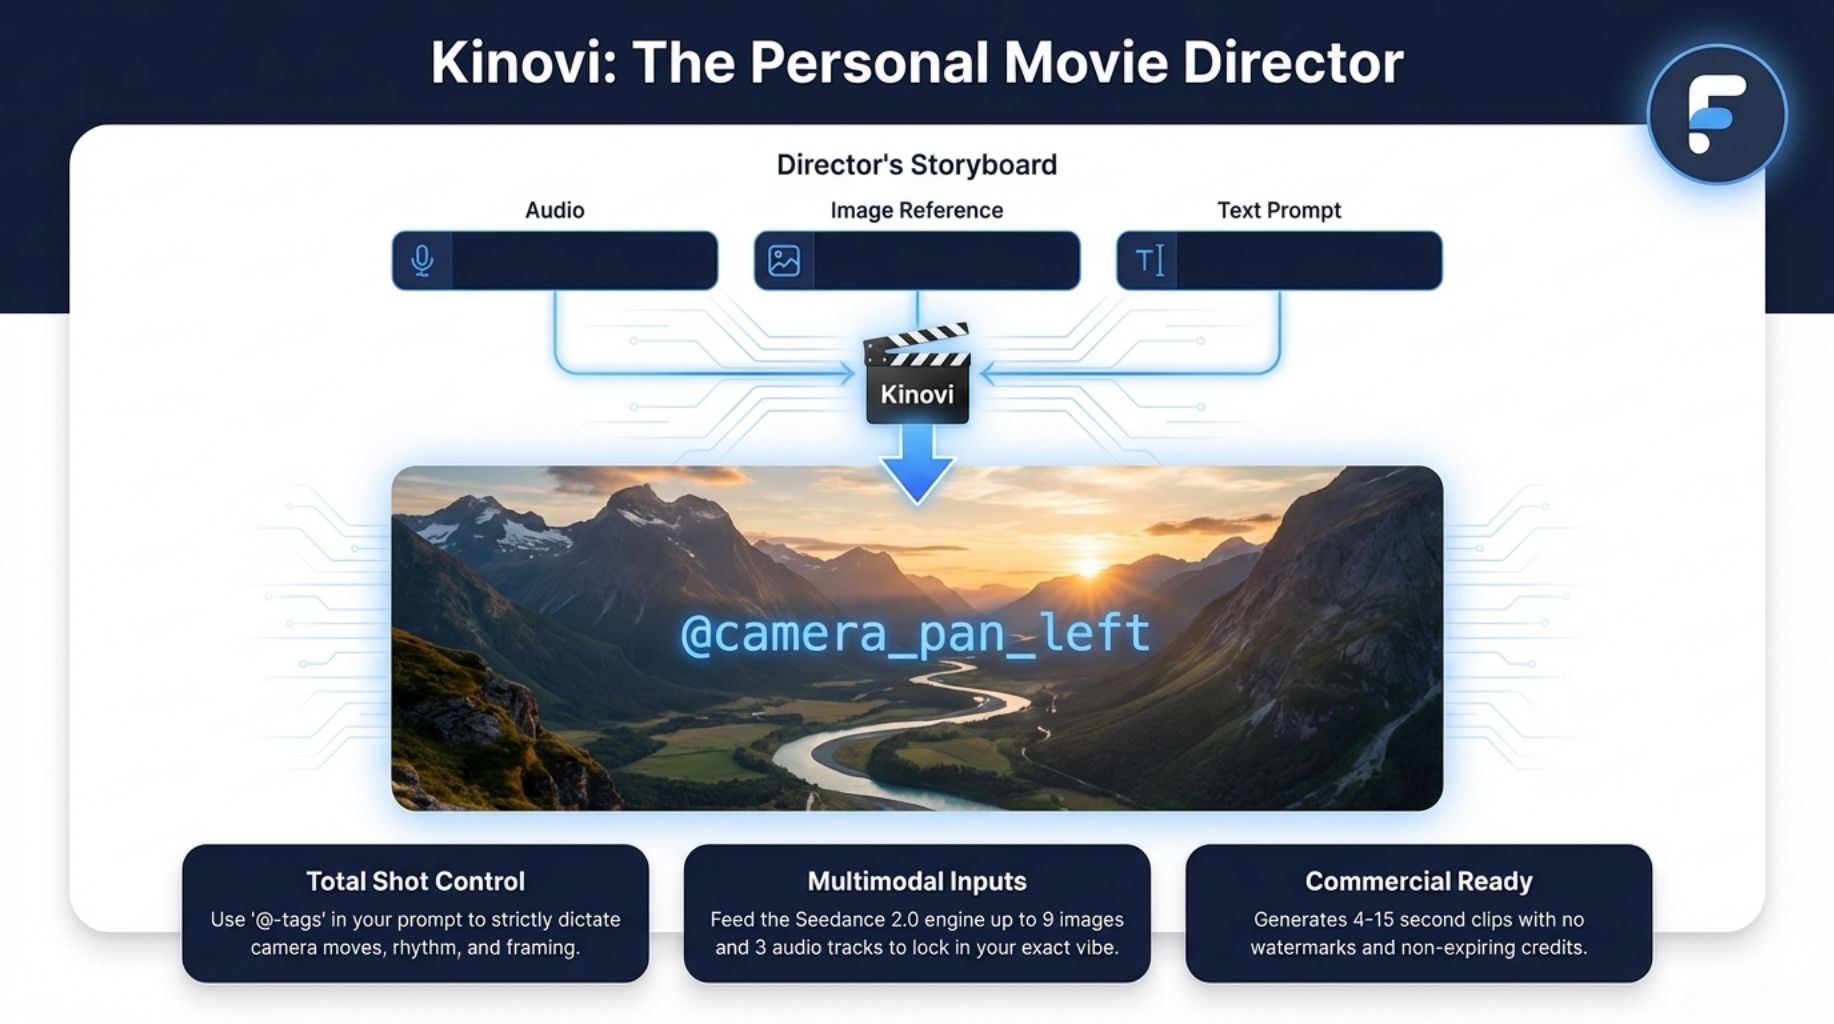
    Kinovi AI Video Director Tool Built on Seedance 2.0

    Kinovi — Be your own director
    Turn prompts + reference files into cinematic AI clips. Upload up to 9 images, 3 videos & 3 audio tracks, use @-tag direction for shot control, and generate watermark-free clips in under a minute. Built on Seedance 2.0. http://
    kinovi.ai

    → View original post on X — @futurepedia_io

  • MLX-VLM v0.4.3 Launches with Day-Zero Gemma 4 Support
    MLX-VLM v0.4.3 Launches with Day-Zero Gemma 4 Support

    10. MLX-VLM adds Gemma 4 support on day zero nitter.net/Prince_Canuma/status/2… Prince Canuma (@Prince_Canuma) mlx-vlm v0.4.3 is here 🚀 Day-0 support: 🔥 Gemma 4 (vision, audio, MoE) by @GoogleDeepMind 🦅 Falcon-OCR + Falcon Perception by @TIIuae 🪨 Granite Vision 4.0 by @IBMResearch New models: 🎯 SAM 3.1 with Object Multiplex by @facebook 🔍 RF-DETR detection & segmentation by @roboflow Infra: ⚡ TurboQuant (KV cache compression) 🖥️ CUDA support for vision models (Sam and RF-DETR) Get started today: > uv pip install -U mlx-vlm Leave us a star ⭐️ github.com/Blaizzy/mlx-vlm — https://nitter.net/Prince_Canuma/status/2039815307821199709#m

    → View original post on X — @aihighlight, 2026-04-06 12:42 UTC

  • Gemma 4 Vision on Pixel 10 Pro

    9. Gemma 4 Vision running on Pixel 10 Pro
    https://nitter.net/ai_for_success/status/20397654977477960651 [Translated from EN to English]

    → View original post on X — @aihighlight, 2026-04-06 12:42 UTC

  • Local VLM Smartphone Camera App Using Gemma 4

    7. Local VLM app that works in airplane mode
    nitter.net/GOROman/status/2039971… null-sensei (@GOROman) I created an app using Gemma 4 that explains what's shown on a smartphone camera. Since it's a local VLM, it works even in airplane mode. [Image: thumbnail] — https://nitter.net/GOROman/status/2039971116756910092#m [Translated from EN to English]

    → View original post on X — @aihighlight, 2026-04-06 12:42 UTC

  • Gemma 4 Vision Capabilities Demonstrated in Browser with Local AI

    3. Vision capabilities in browser nitter.net/measure_plan/status/20… AA (@measure_plan) i spent the afternoon experimenting with Gemma 4's vision capabilities made an app that uses roboflow RF-DETR for a first pass of object detections and Gemma to summarize the scene in one sentence for fun i asked Gemma to "describe what you see as if you were a medieval bard" all made with free local AI models (running via webgpu in the browser thanks to transformers js) lots more possibilities to explore with this — https://nitter.net/measure_plan/status/2039815699695104343#m

    → View original post on X — @aihighlight, 2026-04-06 12:42 UTC

  • Video of Israeli Minister Potentially AI-Generated

    Believe it or not, but this video of him (and others before) are potentially AI-generated. — Clash Report (@clashreport) Israeli Defense Minister Israel Katz: The IDF forcefully struck Iran's largest petrochemical plant. This key facility accounts for about 50% of Iran's petrochemical output. This follows an attack on Iran's second-largest facility last week. As a result, both facilities, which together account for 85% of Iran's petrochemical production, are now out of operation. This represents a multi-billion dollar economic blow to the Iranian regime. Netanyahu and I have instructed the IDF to continue high-intensity strikes on the Iranian regime's national infrastructure. — https://nitter.net/clashreport/status/2041112143211139313#m [Translated from EN to English]

    → View original post on X — @olivierrimmel, 2026-04-06 12:25 UTC

  • ThinkAct: Robots Learn to Reason Before Acting
    ThinkAct: Robots Learn to Reason Before Acting

    This is different. Robots just took a step toward actually thinking before they move. Researchers from china introduced a new architecture called ThinkAct. Instead of directly turning vision into action, the system generates explicit reasoning traces first then converts them into motor commands. So basically, this novel architecture that enables robots to observe and reason before they act. What makes this powerful is the separation between thinking and doing. The model plans tasks step-by-step encodes that plan into a latent representation and uses it to guide real-world execution. In testing, ThinkAct achieved state of the art performance on long horizon manipulation tasks, outperforming existing vision language action models. Soon, in near term future, we will see Robots doing all the stuffs that we do!

    → View original post on X — @deeplearn007, 2026-04-06 12:13 UTC

  • Pika Labs Launches AI Agents for Live Video Calls

    AI agents are starting to join meetings. Pika Labs just launched a beta feature that lets AI agents enter live video calls—with voice, memory, and real-time responses.
    Powered by PikaStream 1.0, this enables: • Real-time conversation (not just chat)
    • Persistent memory +

    → View original post on X — @futurepedia_io