Want better #DeepLearning results? Join #KaggleGrandMaster @ybabakhin
, Martin Barus & #MLEngineer #AdamValenta to level up your #TransferLearning skills + get tips on tuning #DeepLearningPipelines. See you at @FIT_CTU on 6.3.23 @ 18:00. http://
ow.ly/mRyY50N8UKe #HydrogenTorch
MACHINE LEARNING
-
Master Deep Learning and Transfer Learning with Kaggle Grand Masters
By
–
-
Synthetic Data Benefits for Artificial Intelligence Development
By
–
Can Synthetic #Data Make #AI Better? Discover the Benefits of Synthetic #Data
by @joshinav @BBNTimes_en Learn more: https://
buff.ly/3tCfPlj #BigData #DataScience #MachineLearning cc: @wil_bielert @patrickgunz_ch @johnlegere -
Daily Python Machine Learning and Language Models Content Sharing
By
–
That's a wrap. Every day, I share and simplify complex concepts around Python, Machine Learning & Language Models. Follow me → @Sumanth_077 if you haven't already to ensure you don't miss that. Like/RT the first tweet to support my work and help this reach more people.
-
RLHF Resources: OpenAI and Hugging Face Learning Materials
By
–
Here are some resources which you can further research on RLHF: Open AI's blog: http://
openai.com/blog/instructi
on-following/
…… Hugging Face blog: https://
huggingface.co/blog/rlhf -
SFT Model Training with Reward Function Iterations
By
–
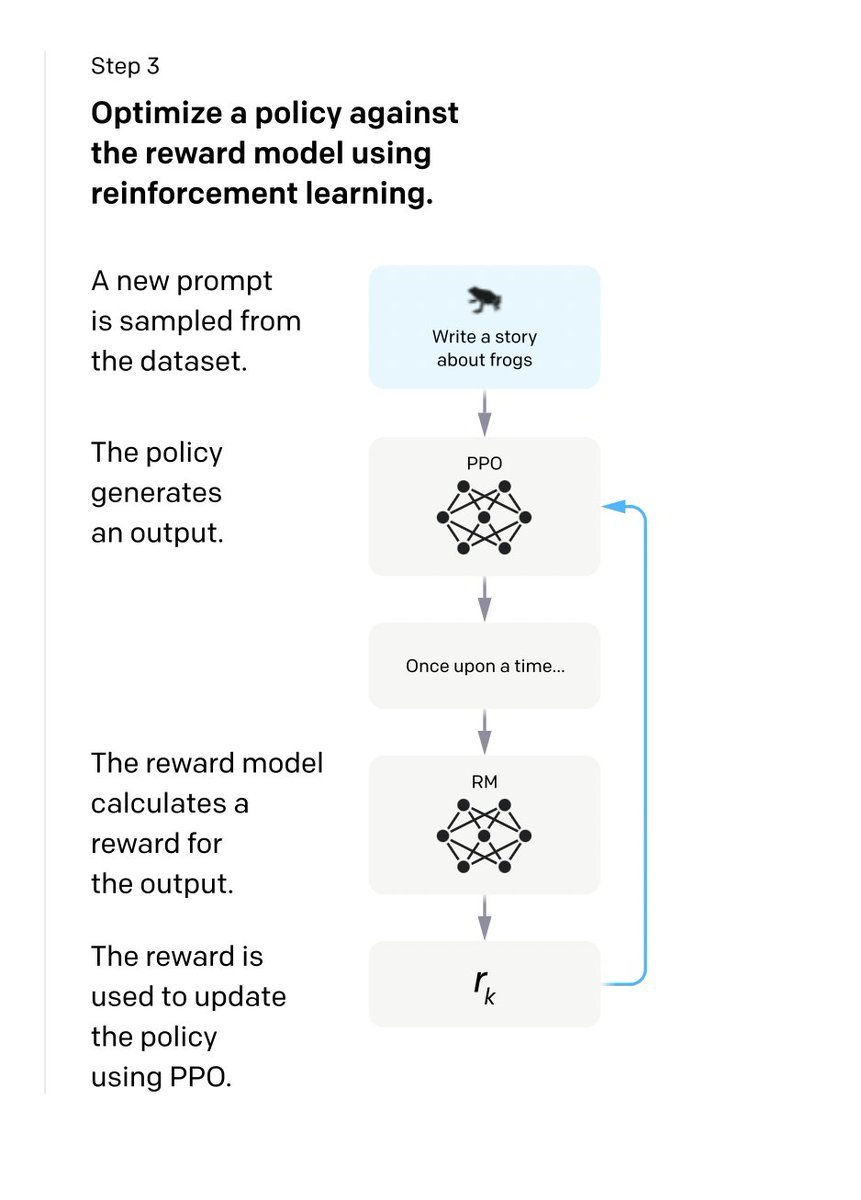
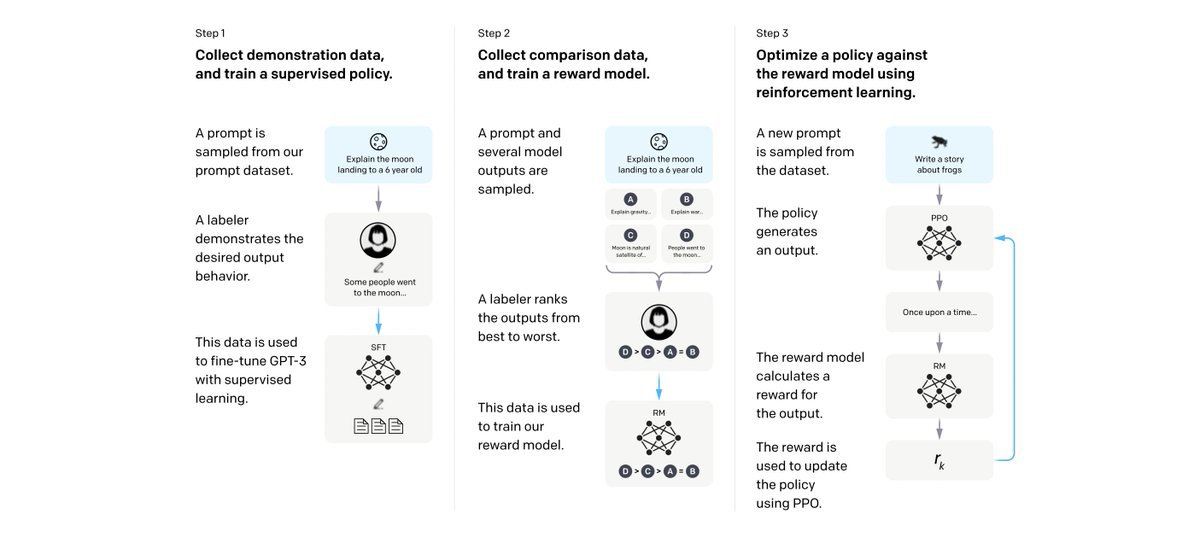
Step3: Sample a Prompt from the dataset, give that to the SFT model and get the generated response. Use the RF model to calculate the reward of the response and use that to update the Model. Iterate over it. That's how they have developed it. 9/9
-
Using Reward Models and PPO to Fine-tune Language Models
By
–
Now we don't need Humans to rank the responses. We have RM which will take care of that. The final step is to use this RM as a reward function and fine-tune the SFT model to maximize the reward using Proximal Policy Optimization which is Reinforcement Learning Algorithm 8/9
-
Training Reward Models with Human-Ranked SFT Responses
By
–
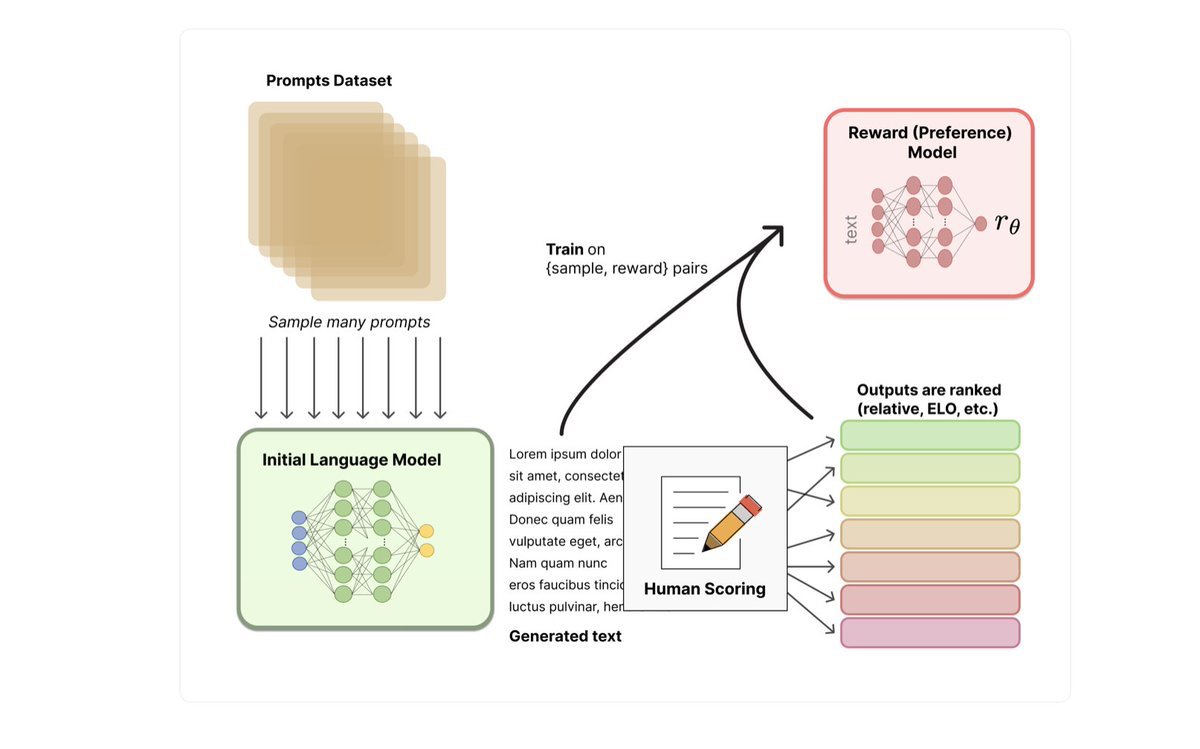
Step2: They used the SFT model to generate multiple responses to a given prompt and the Humans ranks the responses from best to worst. Now we have a labeled dataset, then training a Reward Model will learn how the human would actually rank the responses 7/9
-
Reward Model as Solution for Data Scarcity in Fine-tuned Models
By
–
Even though they fine-tuned the model, since the data is very less, still the model is not accurate. Getting more data will solve this but human annotation is slow and expensive. So they come up with another model which is called Reward Model(RM). 6/9
-
Supervised Fine-Tuning GPT-3.5 with Human-Written Answers
By
–
Step1: They have prepared a dataset of human-written answers to the prompts and used that to train the model which is called Supervised Fine-Tuning (SFT) model. The model used here for fine-tuning is the Instruct GPT(GPT-3.5) 5/9
-
Understanding RLHF: Three-Step Process for Fine-tuning Instruct GPT
By
–
So to solve this and make the answers more relevant and safe they have used the same "Reinforcement Learning from Human Feedback"(RLHF) method to fine-tune Instruct GPT(GPT-3.5). Let's go through and understand how RLHF works which is a 3-step process. 4/9