PolyVoice: Language Models for Speech to Speech Translation paper page: https://
arxiv.org/abs/2306.02982 propose PolyVoice, a language model-based framework for speech-to-speech translation (S2ST) system. Our framework consists of two language models: a translation language model and a
MACHINE LEARNING
-

PolyVoice: Language Models for Speech-to-Speech Translation
By
–
-
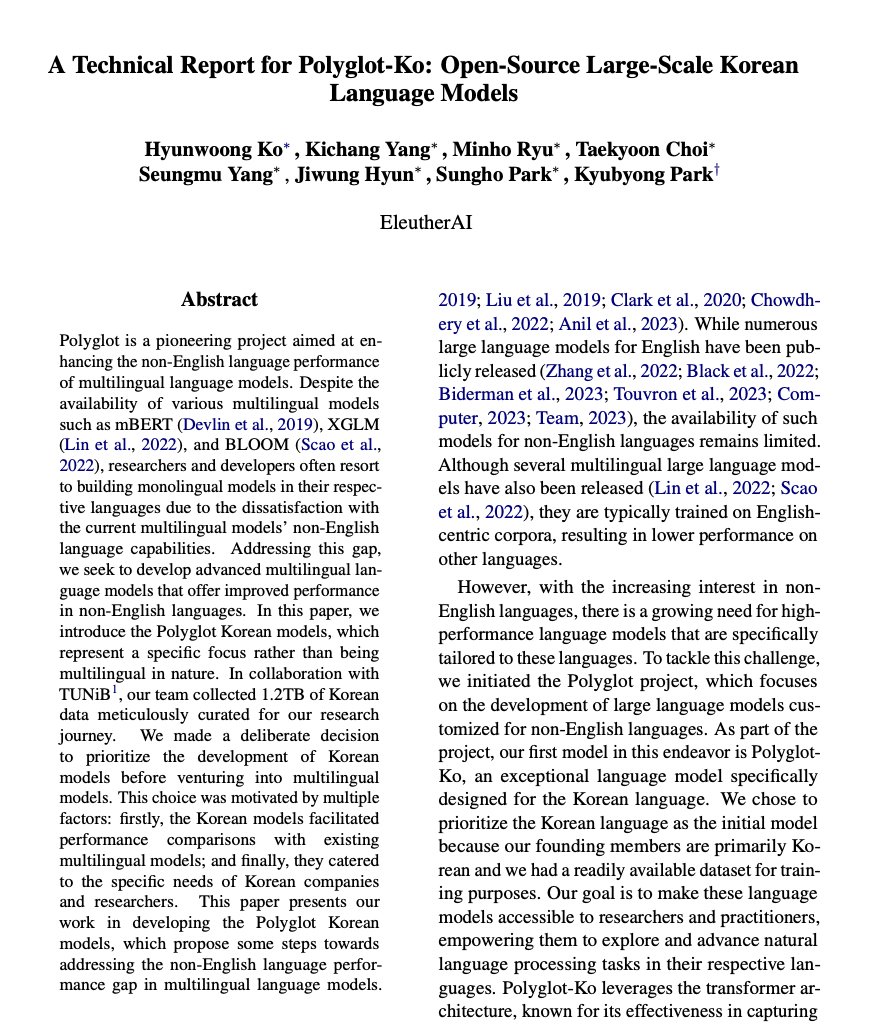
Polyglot-Ko: Open-Source Large-Scale Korean Language Models
By
–
A Technical Report for Polyglot-Ko: Open-Source Large-Scale Korean Language Models paper page: https://
huggingface.co/papers/2306.02
254
… Polyglot is a pioneering project aimed at enhancing the non-English language performance of multilingual language models. Despite the availability of various -
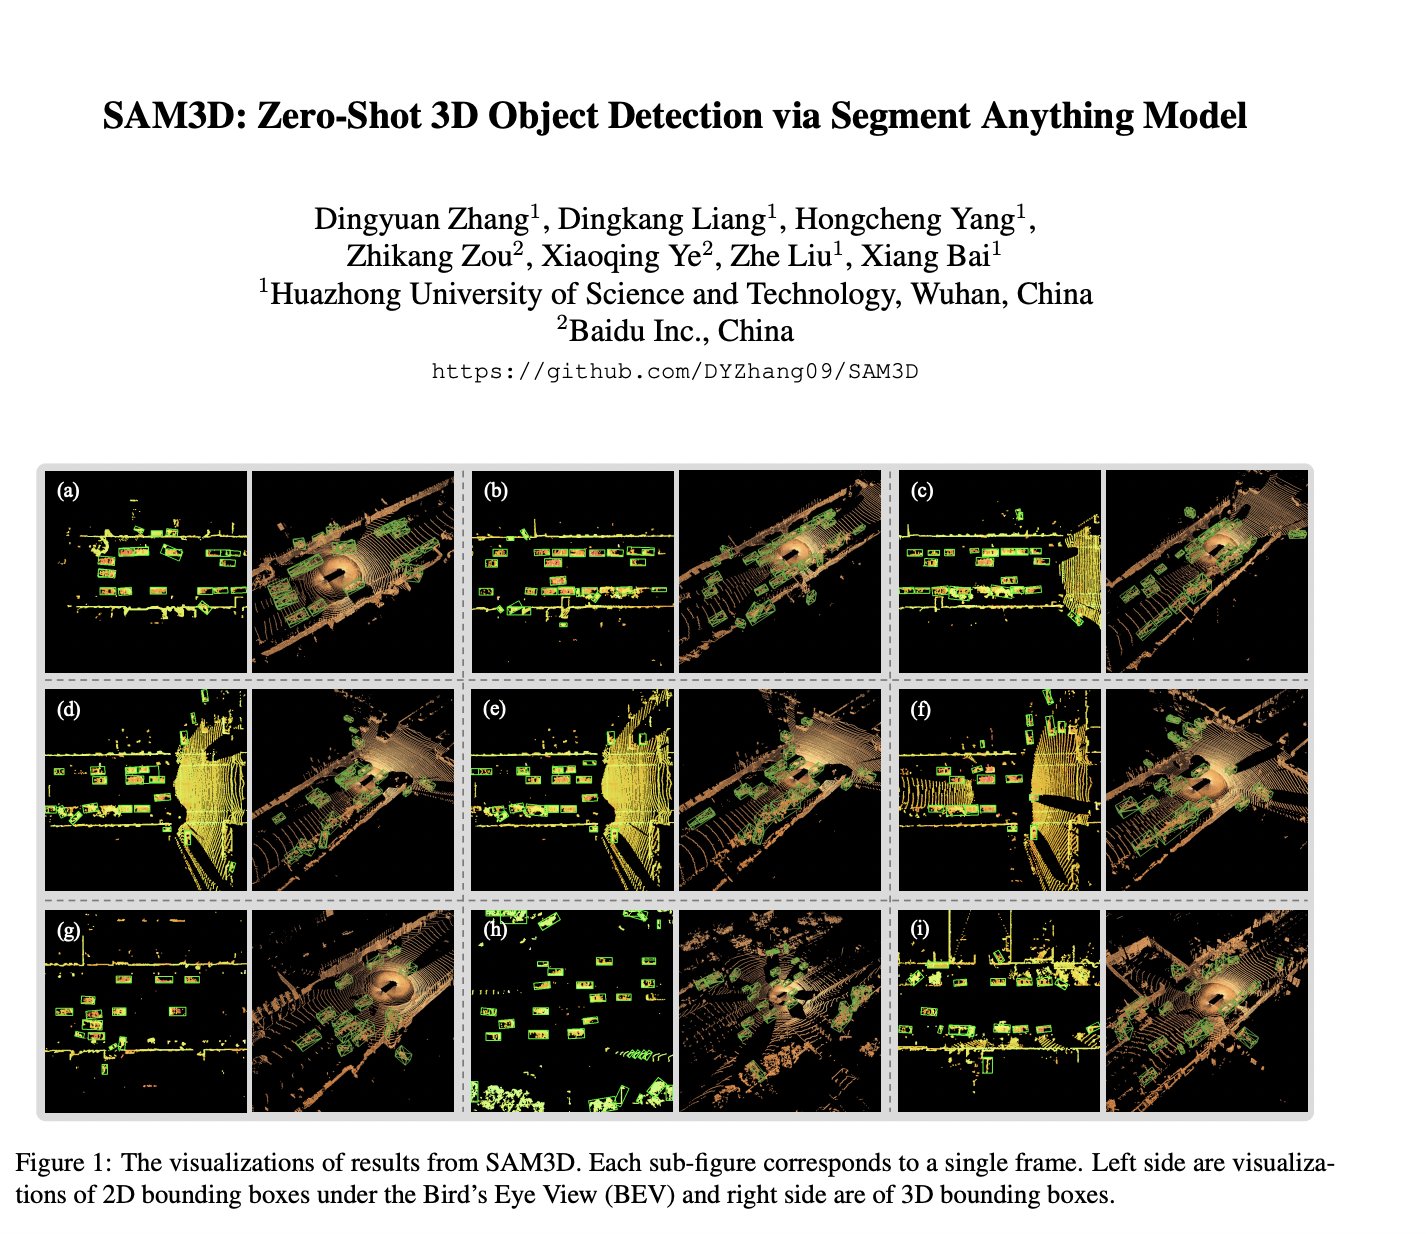
SAM3D: Zero-Shot 3D Object Detection via Segment Anything Model
By
–
SAM3D: Zero-Shot 3D Object Detection via Segment Anything Model paper page: https://
huggingface.co/papers/2306.02
245
… With the development of large language models, many remarkable linguistic systems like ChatGPT have thrived and achieved astonishing success on many tasks, showing the incredible -
ChatGPT Hiring for AI Model Evaluation Specialists
By
–
ChatGPT team is hiring. Especially looking for people who like to do the detail (and often unappreciated in this field!) work of digging deep into & figuring out how to rigorously evaluate the models. Major perk — you'll get to work with @barret_zoph and other amazing talent:
-
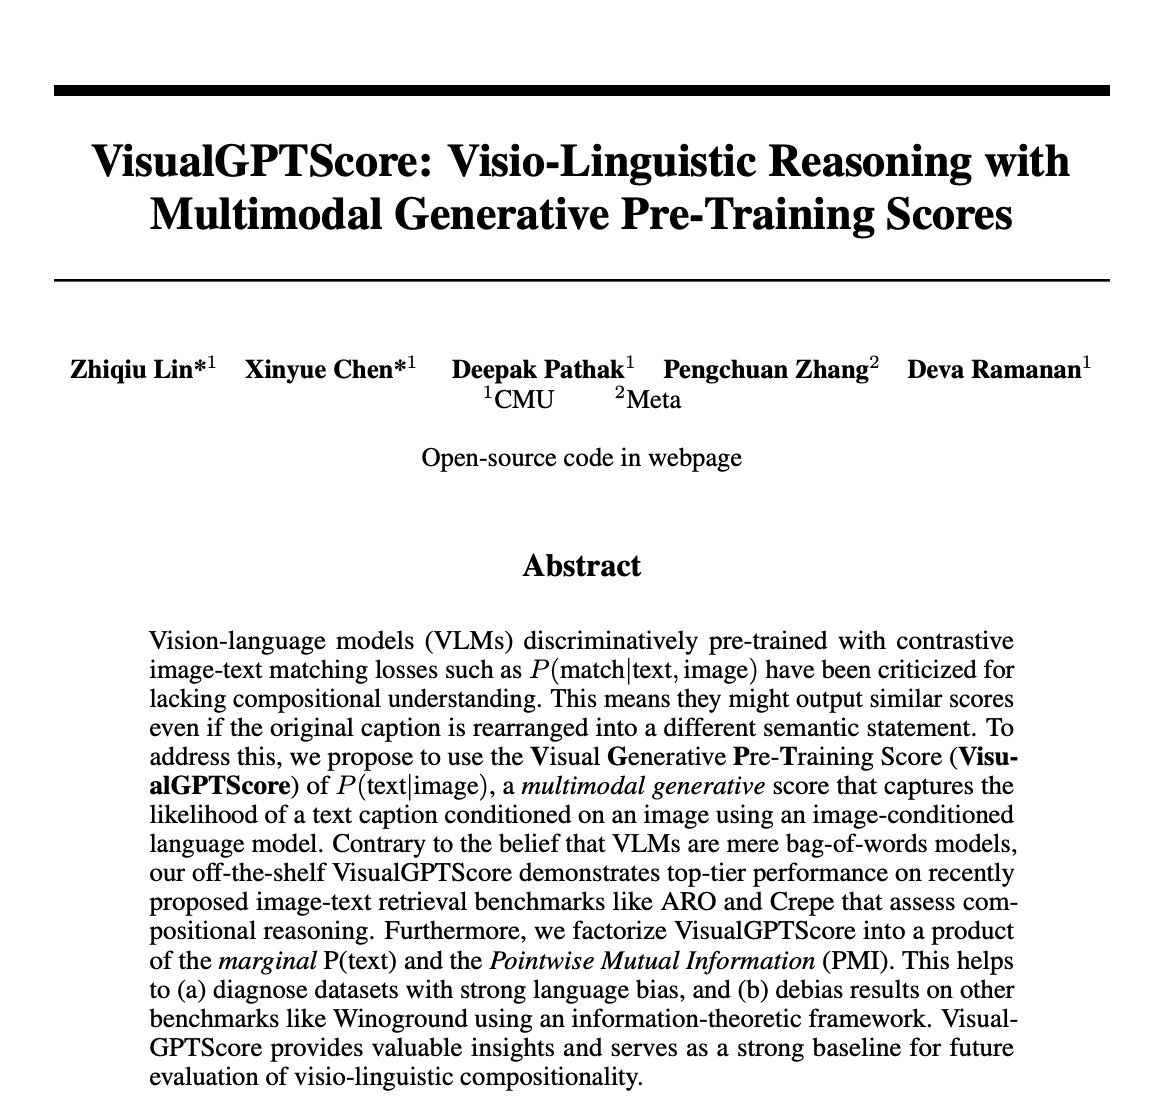
VisualGPTScore: Vision-Language Models with Multimodal Generative Pre-Training
By
–
VisualGPTScore: Visio-Linguistic Reasoning with Multimodal Generative Pre-Training Scores paper page: https://
huggingface.co/papers/2306.01
879
… Vision-language models (VLMs) discriminatively pre-trained with contrastive image-text matching losses such as P(match|text, image) have been criticized -
Probabilistic Adaptation of Text-to-Video Models for High-Fidelity Generation
By
–
Probabilistic Adaptation of Text-to-Video Models
— AK (@_akhaliq) 6 juin 2023
paper page: https://t.co/pGlGHjrDpG
Large text-to-video models trained on internet-scale data have demonstrated exceptional capabilities in generating high-fidelity videos from arbitrary textual descriptions. However, adapting… pic.twitter.com/nzfYbWLflPProbabilistic Adaptation of Text-to-Video Models paper page: https://
huggingface.co/papers/2306.01
872
… Large text-to-video models trained on internet-scale data have demonstrated exceptional capabilities in generating high-fidelity videos from arbitrary textual descriptions. However, adapting -

Transformer-based Vulnerability Detection in Code: Zero-shot, Few-shot, Fine-tuning
By
–
Transformer-based Vulnerability Detection in Code at EditTime: Zero-shot, Few-shot, or Fine-tuning? paper page: https://
huggingface.co/papers/2306.01
754
… Software vulnerabilities bear enterprises significant costs. Despite extensive efforts in research and development of software vulnerability -
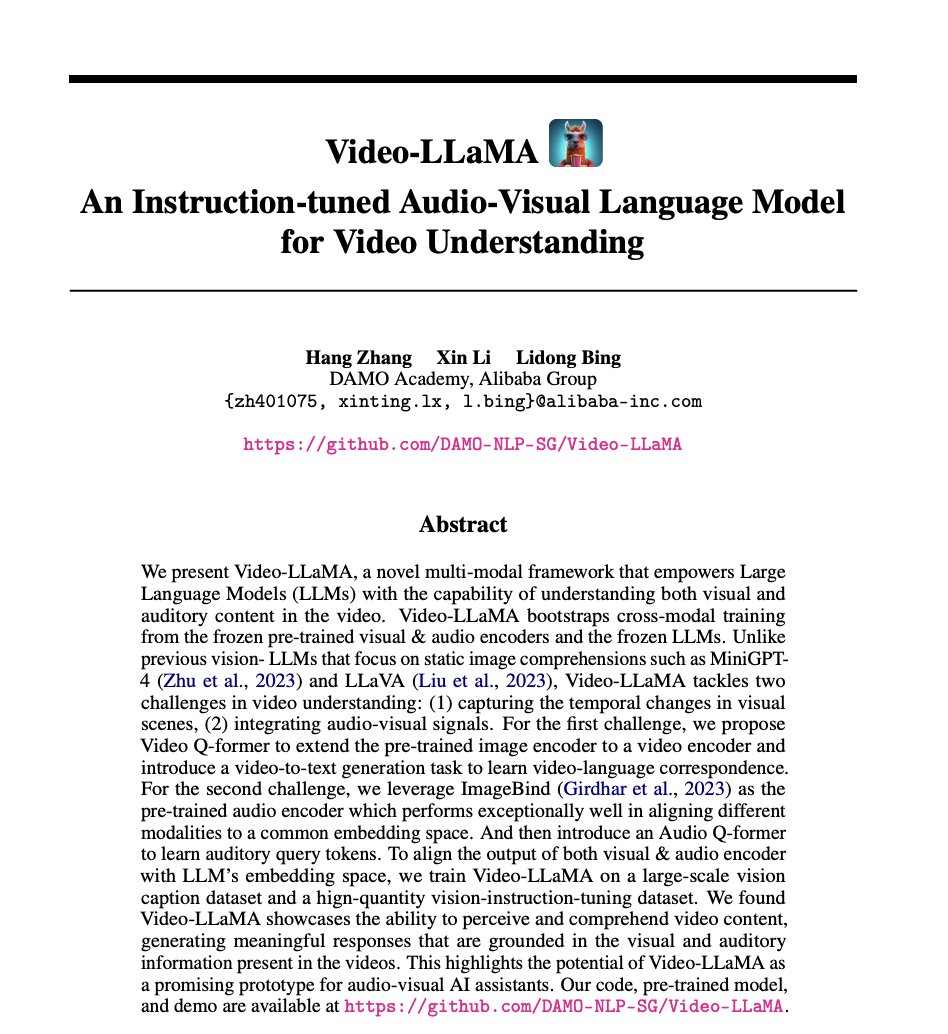
Video-LLaMA: Multi-modal Framework for Audio-Visual Understanding
By
–
-LLaMA: An Instruction-tuned Audio-Visual Language Model for Understanding paper page: https://
huggingface.co/papers/2306.02
858
… present Video-LLaMA, a multi-modal framework that empowers Large Language Models (LLMs) with the capability of understanding both visual and auditory -
Biological Neural Network Trained on Microsoft Data
By
–
I am a biological neural network trained on expensive data collected by Microsoft corporation.
-

Returning to AI focus next year
By
–
Back to AI until next year. 🙂 https://t.co/P6lZcsgXsC
— Robert Scoble (@Scobleizer) 6 juin 2023Back to AI until next year. 🙂