From Word Models to World Models: Translating from Natural Language to the Probabilistic Language of Thought paper page: https://
huggingface.co/papers/2306.12
672
… How does language inform our downstream thinking? In particular, how do humans make meaning from language — and how can we leverage
MACHINE LEARNING
-
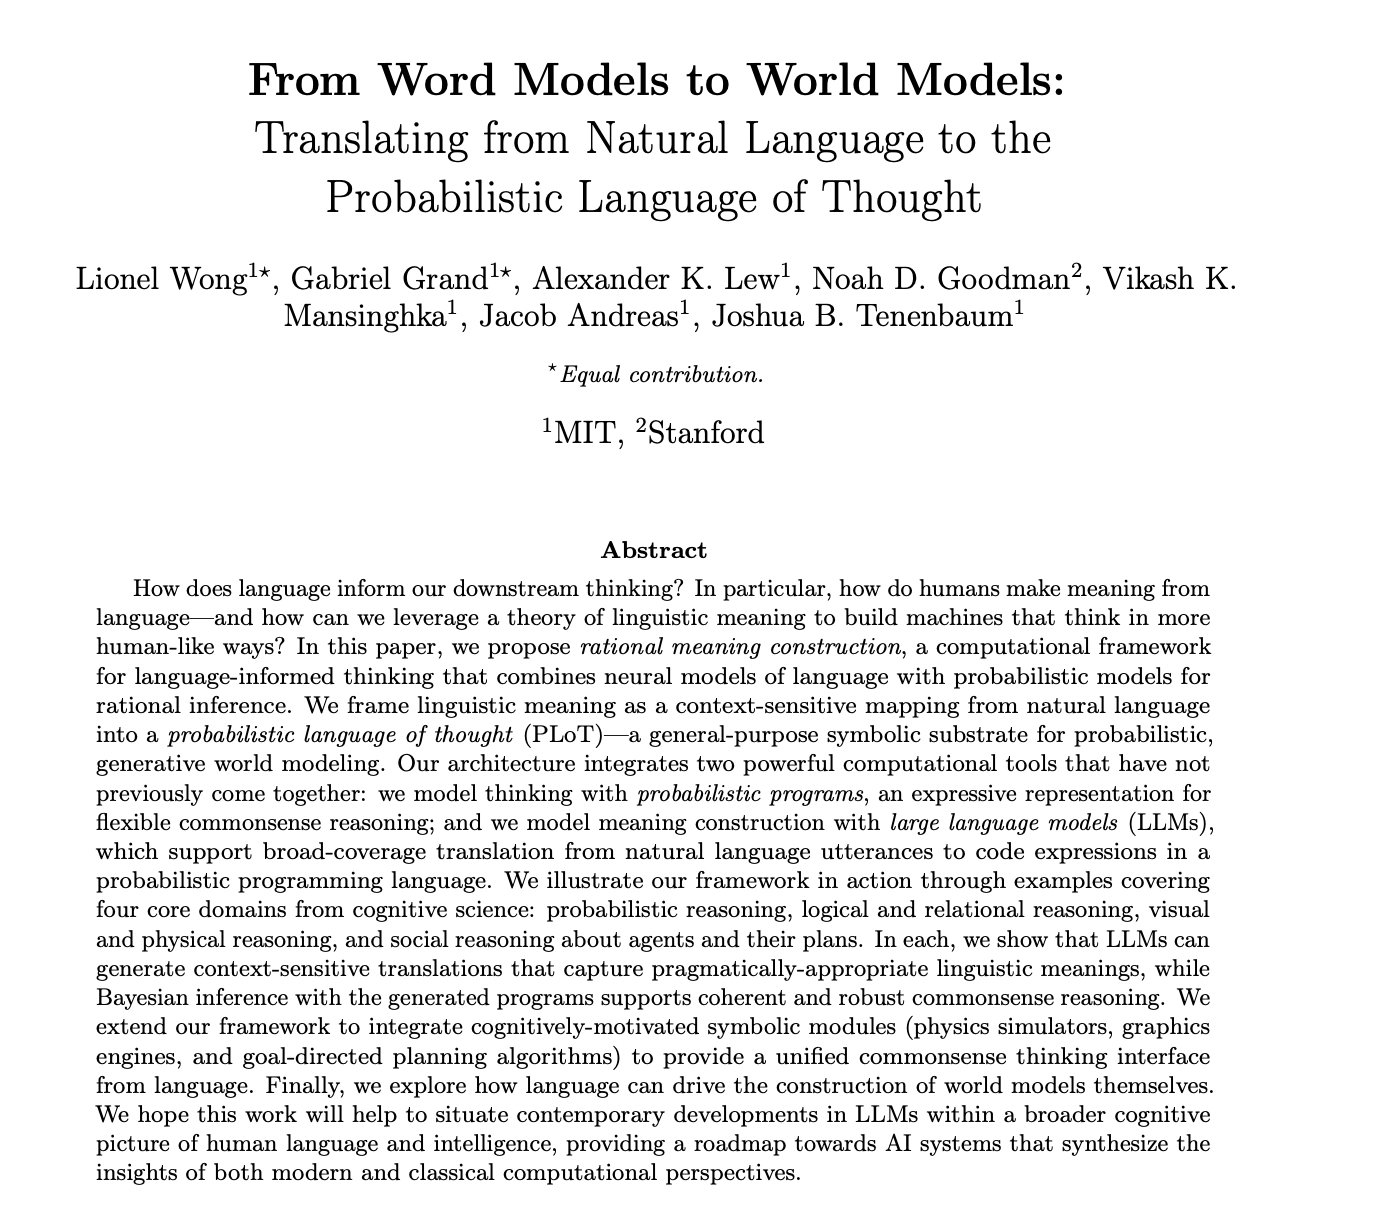
Word Models to World Models: Natural Language to Probabilistic Thought
By
–
-
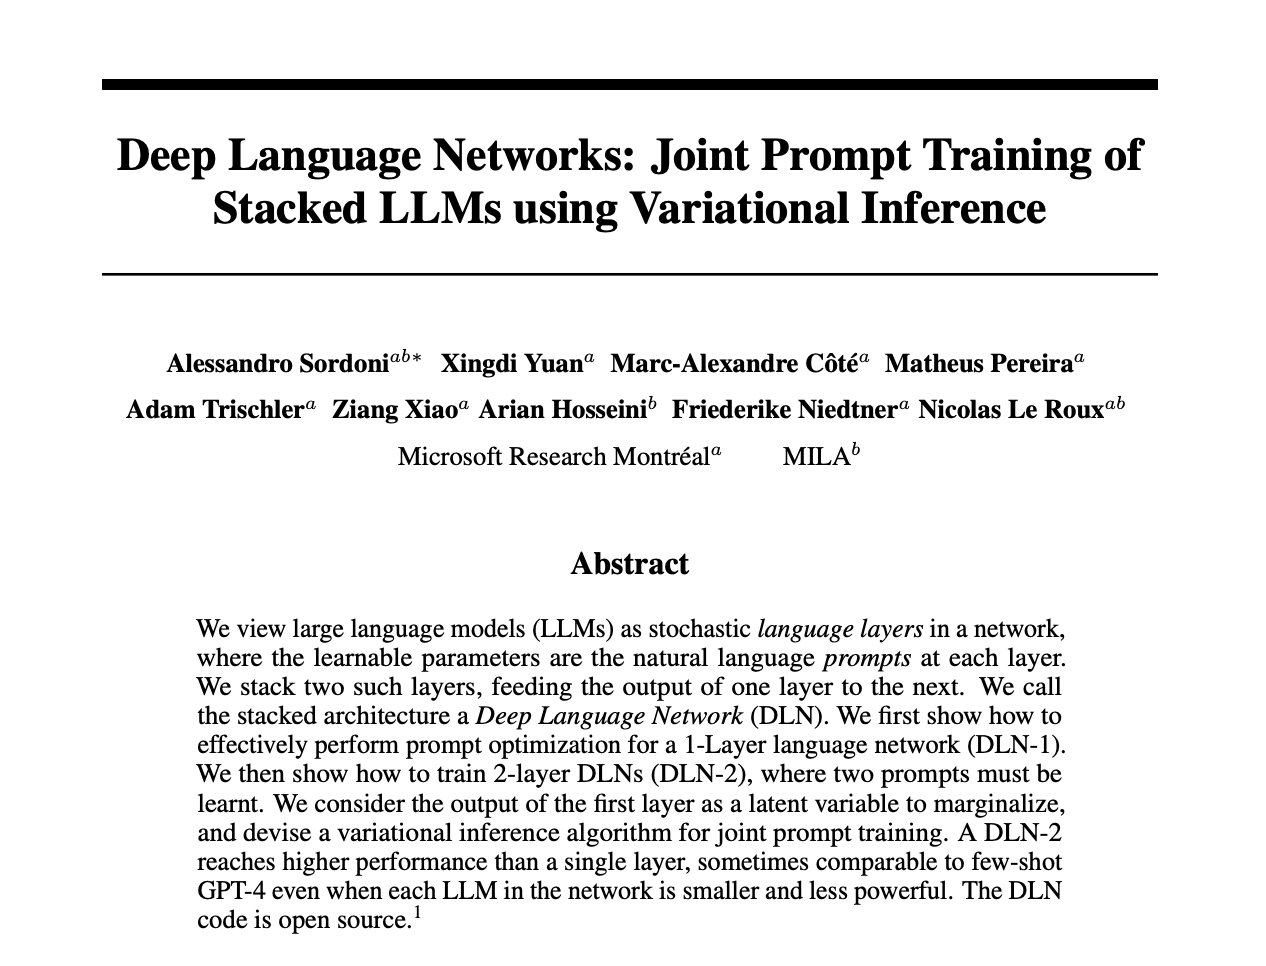
Deep Language Networks: Joint Prompt Training of Stacked LLMs
By
–
Deep Language Networks: Joint Prompt Training of Stacked LLMs using Variational Inference paper page: https://
huggingface.co/papers/2306.12
509
… We view large language models (LLMs) as stochastic language layers in a network, where the learnable parameters are the natural language prompts at each -

AI Expert Reveals Top Tips for Students to Outsmart AI
By
–
AI Expert Reveals Top Tips for Students to Outsmart Artificial Intelligence
#AI #AIio #BigData #ML #NLU #Futureofwork @ahier @guzmand
@DavidBrin @denisegarth @dez_blanchfield @diioannid @DioFavatas @gerald_bader http://
ow.ly/YC9W30svSsi -
AI Expert Shares Top Tips for Students to Outsmart Artificial Intelligence
By
–
AI Expert Reveals Top Tips for Students to Outsmart Artificial Intelligence
#AI #AIio #BigData #ML #NLU #Futureofwork http://
ow.ly/2OO230svSe0 -
5 Use Cases For AI-Generated Content In Hiring
By
–
5 Use Cases For AI-Generated Content In The Hiring Process
#AI #AIio #BigData #ML #NLU #Futureofwork http://
ow.ly/SKCu30svScZ -
University of Toronto Explains Deep Learning to Non-Technical Audiences
By
–
The University of Toronto made a video for a non technical audience in which I explain how deep learning works, the enormous promise of this technology and some of the potential risks. https://
youtu.be/-9cW4Gcn5WY -
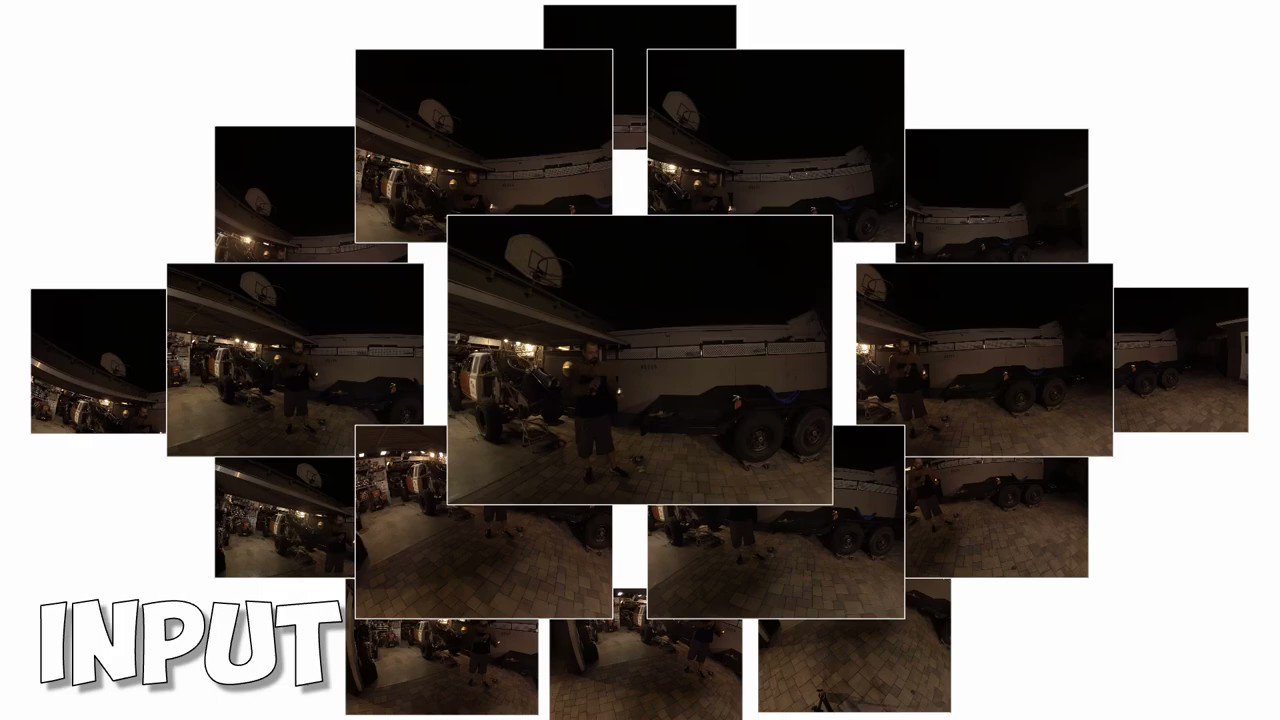
HyperReel: High-Fidelity 6-DoF Video with Ray-Conditioned Sampling
By
–
HyperReel: High-Fidelity 6-DoF Video with Ray-Conditioned Sampling
— AK (@_akhaliq) 22 juin 2023
paper page: https://t.co/TkYI5ibRny
Volumetric scene representations enable photorealistic view synthesis for static scenes and form the basis of several existing 6-DoF video techniques. However, the volume… pic.twitter.com/7zIO8MXavDHyperReel: High-Fidelity 6-DoF with Ray-Conditioned Sampling paper page: https://
huggingface.co/papers/2301.02
238
… Volumetric scene representations enable photorealistic view synthesis for static scenes and form the basis of several existing 6-DoF video techniques. However, the volume -
SoundStorm: Parallel Decoding for Efficient Audio Generation
By
–
Many generative audio models rely on auto-regressive decoding, which produces tokens one by one and can be slow. Read all about SoundStorm, a new method tailored for audio tokens that uses parallel decoding for efficient and high-quality audio generation ↓
-
Groq Welcomes Brian Recore to Lead Federal AI Initiatives
By
–
Groq #inference systems have the potential to open numerous possibilities for #AI and #ML use cases across the #federalgovernment. We're thrilled Brian Recore has joined our team to help pave the way. Welcome Brian! pic.twitter.com/icrZ4VryoG
— Groq Inc (@GroqInc) 22 juin 2023Groq #inference systems have the potential to open numerous possibilities for #AI and #ML use cases across the #federalgovernment. We're thrilled Brian Recore has joined our team to help pave the way. Welcome Brian!
-
Production Model Lifecycle Resilience: MLOps Best Practices
By
–
How resilient is your production model lifecycle? Get ahead of issues interfering with model performance and future-proof your #ML strategy in our ebook. Download: https://
bit.ly/3KivH5u
#MLOps