Check out this blog post by Luis Serrano on sentence similarity! He dives into the importance of embeddings in large language models & explains dot product and cosine similarity. Add some excitement to your tech reads! Read more:
MACHINE LEARNING
-
UAI 2023 Proceedings Volume 216 Now Available on PMLR
By
–
Volume 216 Proceedings of UAI 2023 https://
proceedings.mlr.press/v216/ Is now available on PMLR. -
Mathematicians and AI Collaboration Achieving Surprising Results
By
–
Instead of #AI replacing mathematicians this decade, we are likely to experience collaboration between the fields of mathematics and artificial intelligence that can achieve surprising results by leveraging the respective strengths of mathematicians and #machinelearning.
-
Statler: State-Maintaining Language Models for Embodied Reasoning
By
–
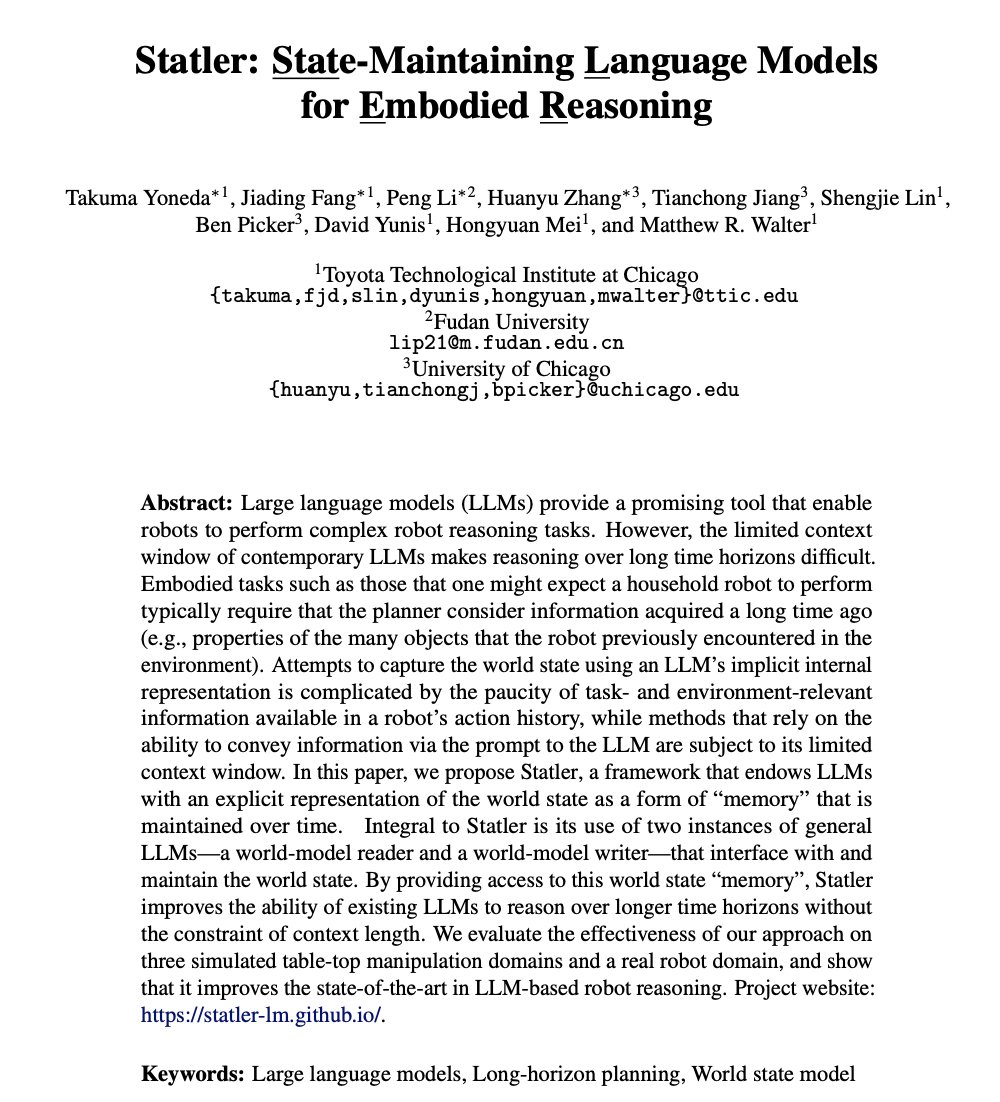
Statler: State-Maintaining Language Models for Embodied Reasoning paper page: https://
huggingface.co/papers/2306.17
840
… Large language models (LLMs) provide a promising tool that enable robots to perform complex robot reasoning tasks. However, the limited context window of contemporary LLMs -
ReMaX: Relaxing Mask Transformers for Efficient Panoptic Segmentation
By
–
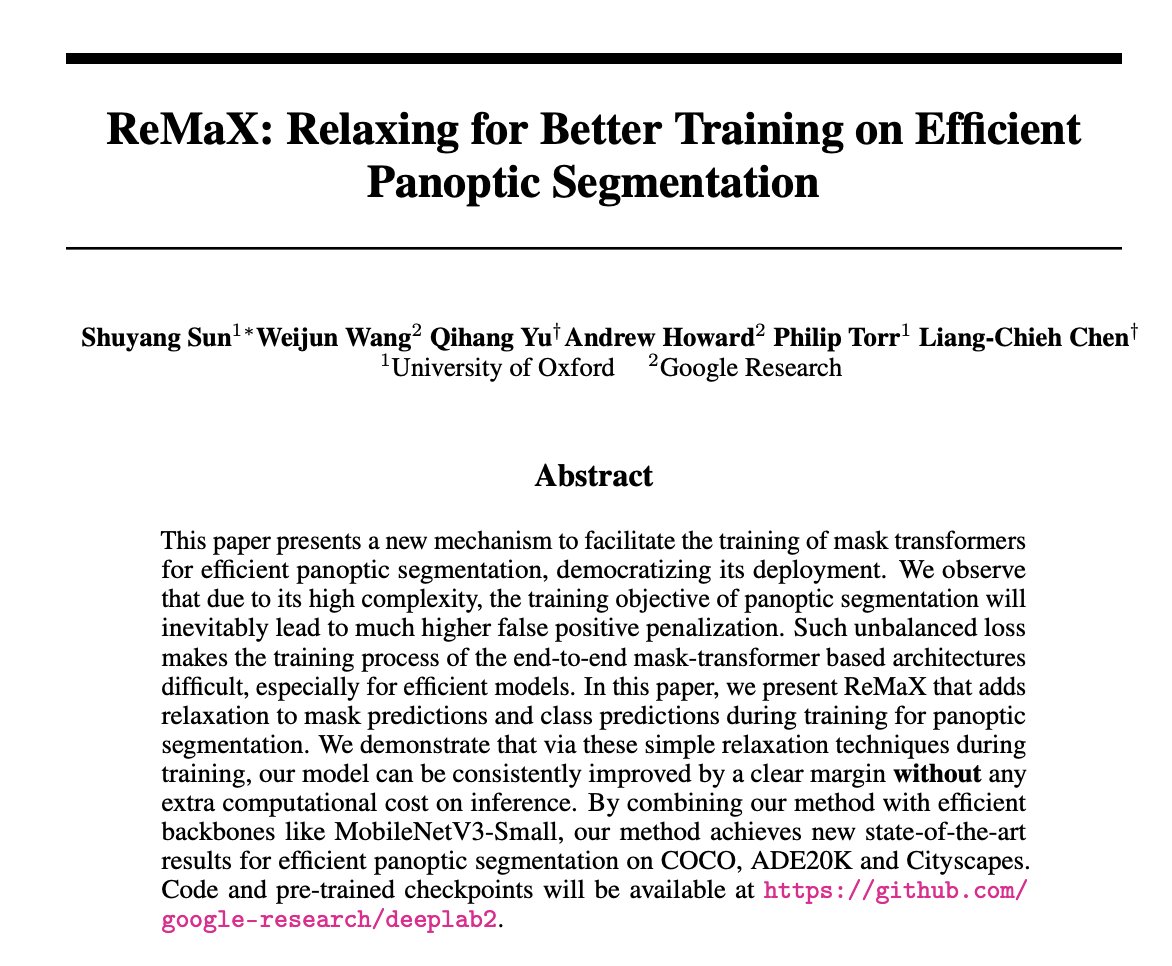
ReMaX: Relaxing for Better Training on Efficient Panoptic Segmentation paper page: https://
huggingface.co/papers/2306.17
319
… paper presents a new mechanism to facilitate the training of mask transformers for efficient panoptic segmentation, democratizing its deployment. We observe that due to -

Hardwiring ViT Patch Selectivity into CNNs using Patch Mixing
By
–
Hardwiring ViT Patch Selectivity into CNNs using Patch Mixing paper page: https://
huggingface.co/papers/2306.17
848
… Vision transformers (ViTs) have significantly changed the computer vision landscape and have periodically exhibited superior performance in vision tasks compared to convolutional -
Shaped Transformer: Attention Models in Infinite Depth-Width Limit
By
–
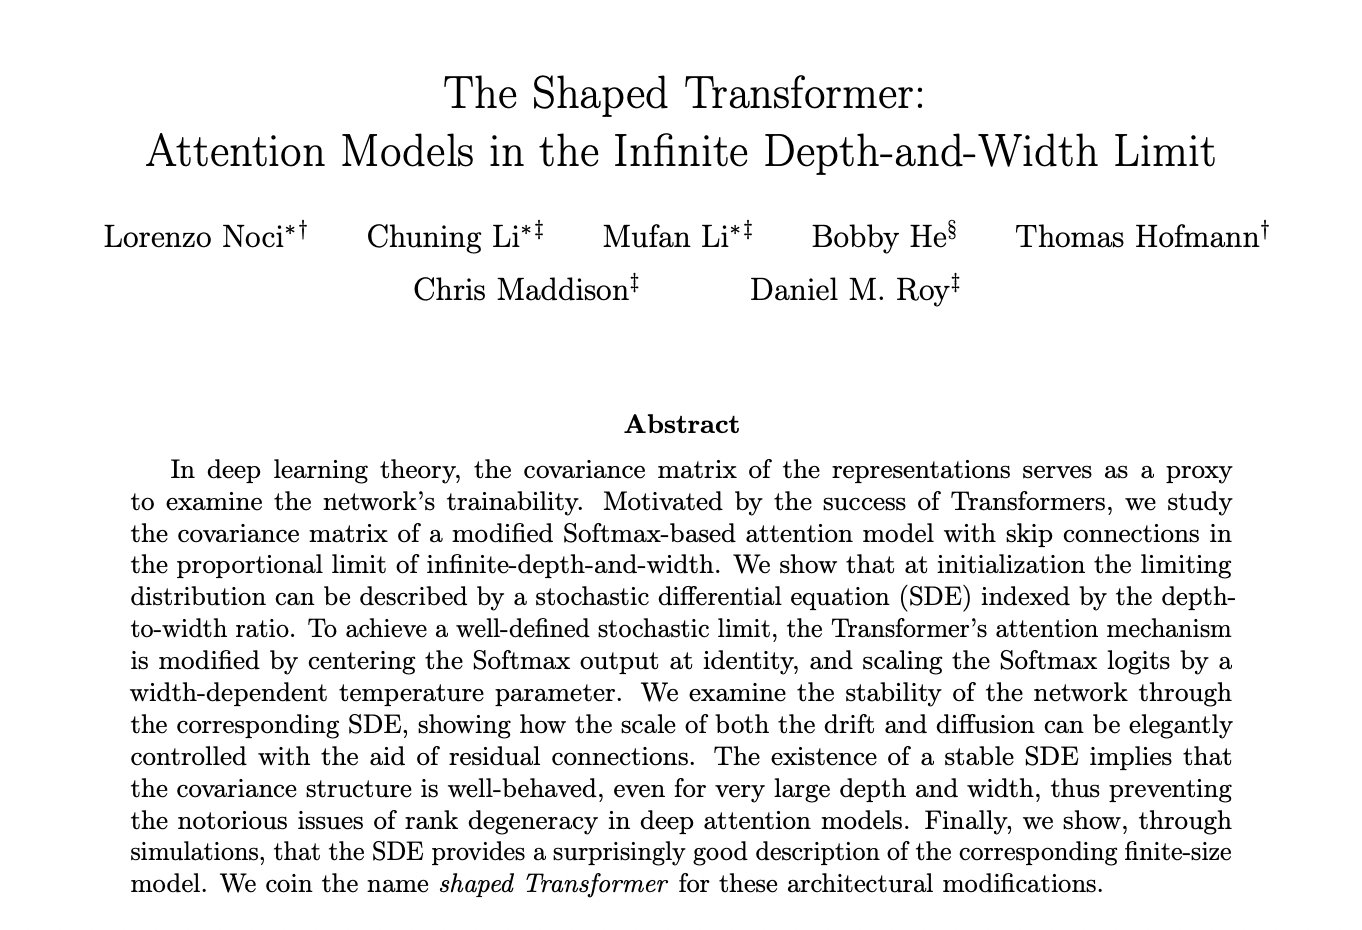
The Shaped Transformer: Attention Models in the Infinite Depth-and-Width Limit paper page: https://
huggingface.co/papers/2306.17
759
… In deep learning theory, the covariance matrix of the representations serves as a proxy to examine the network's trainability. Motivated by the success of -
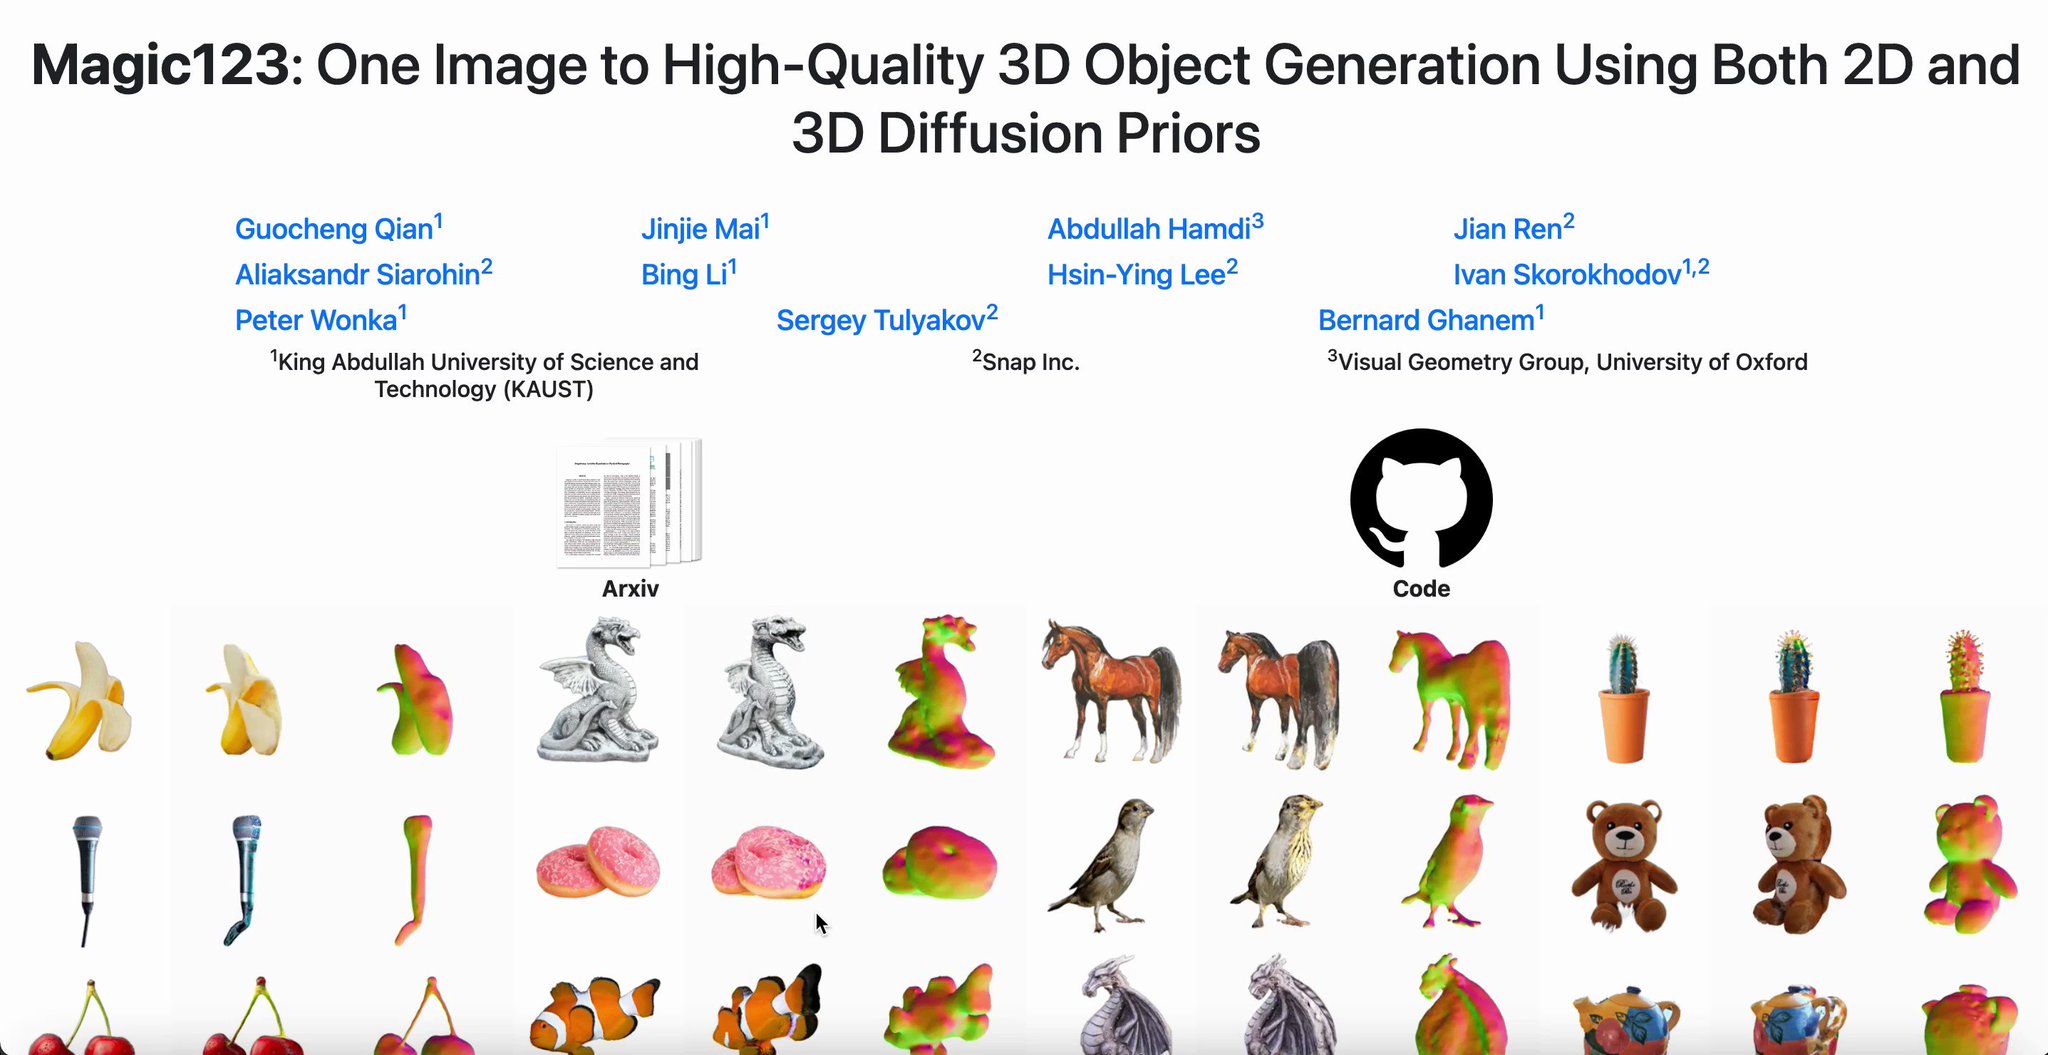
Magic123: Generate High-Quality 3D Objects from Single Images
By
–
Magic123: One Image to High-Quality 3D Object Generation Using Both 2D and 3D Diffusion Priors
— AK (@_akhaliq) 3 juillet 2023
paper page: https://t.co/h869cnIX32
present Magic123, a two-stage coarse-to-fine approach for high-quality, textured 3D meshes generation from a single unposed image in the wild using… pic.twitter.com/nnhlRzqDMnMagic123: One Image to High-Quality 3D Object Generation Using Both 2D and 3D Diffusion Priors paper page: https://
huggingface.co/papers/2306.17
843
… present Magic123, a two-stage coarse-to-fine approach for high-quality, textured 3D meshes generation from a single unposed image in the wild using -
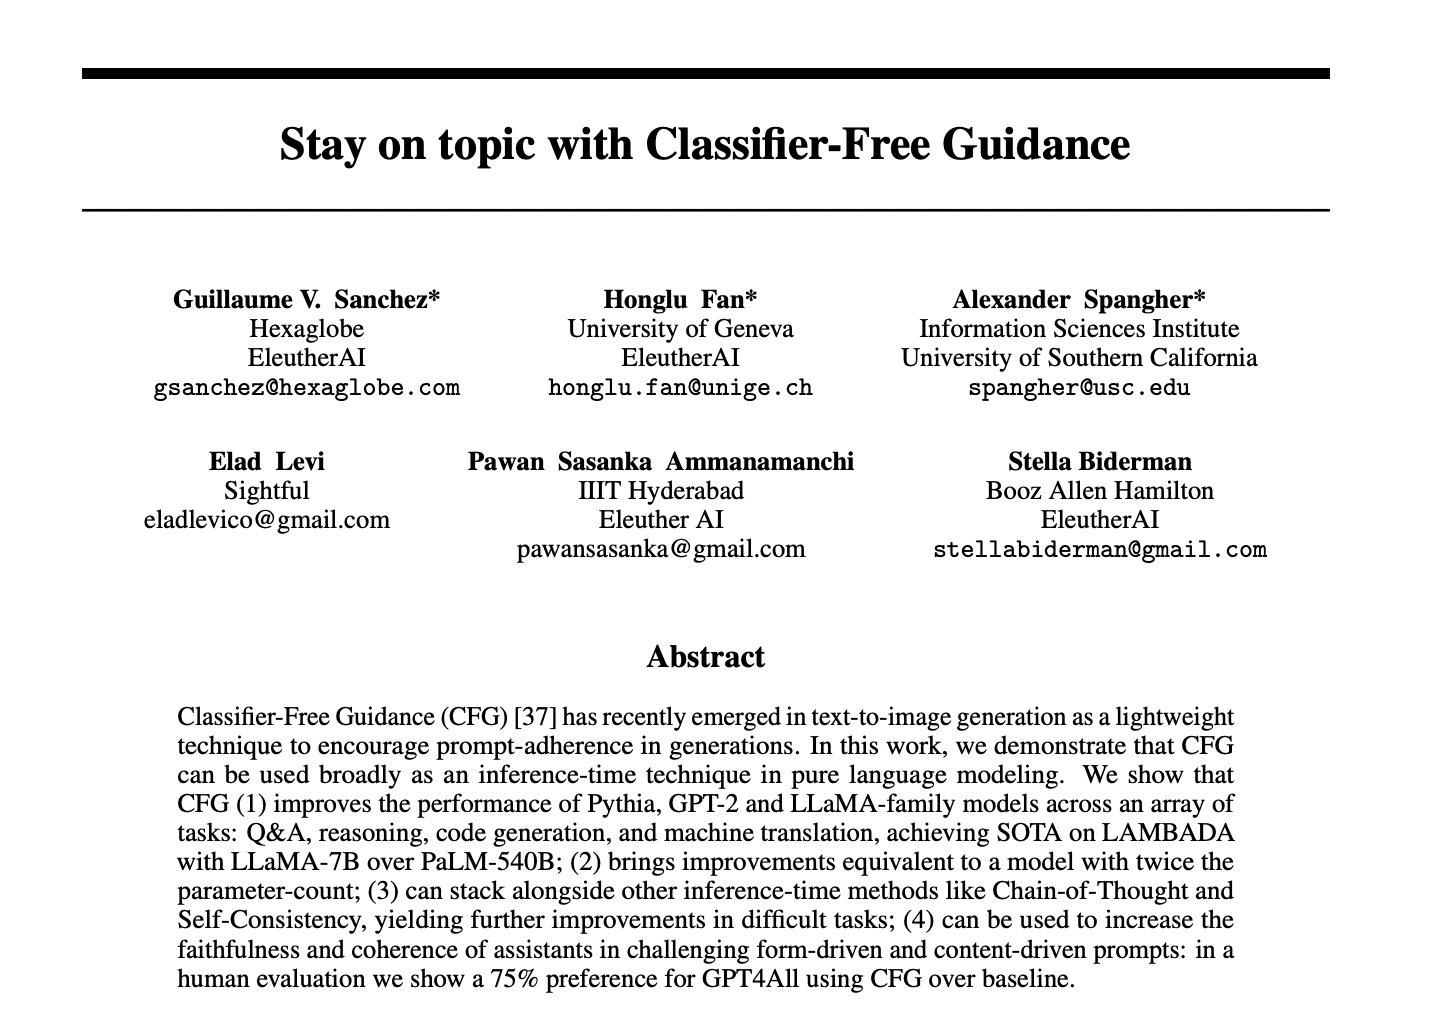
Classifier-Free Guidance Improves Prompt Adherence in Image Generation
By
–
Stay on topic with Classifier-Free Guidance paper page: https://
huggingface.co/papers/2306.17
806
… Classifier-Free Guidance (CFG) has recently emerged in text-to-image generation as a lightweight technique to encourage prompt-adherence in generations. In this work, we demonstrate that CFG can be -
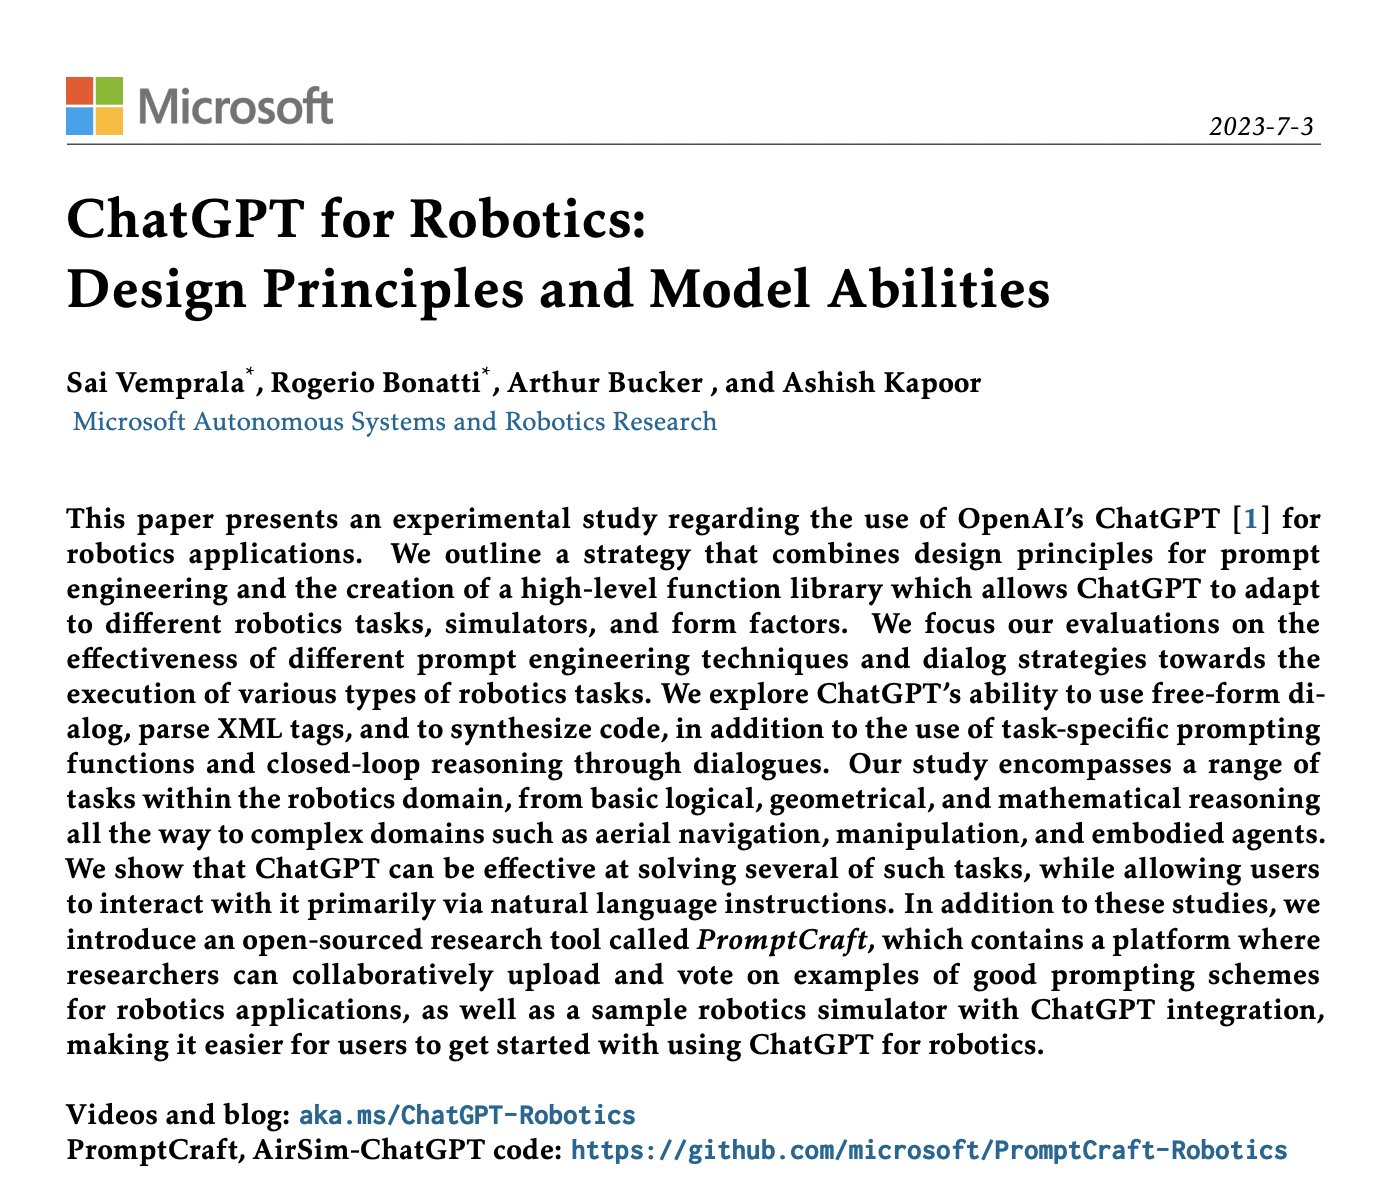
ChatGPT for Robotics: Design Principles and Model Abilities
By
–
ChatGPT for Robotics: Design Principles and Model Abilities paper page: https://
huggingface.co/papers/2306.17
582
… paper presents an experimental study regarding the use of OpenAI's ChatGPT for robotics applications. We outline a strategy that combines design principles for prompt engineering and