enable webgpu in your chrome and then just add tensors as you go. It's for small NNs
MACHINE LEARNING
-
WebGPU enables machine learning directly in your browser
By
–
Check this out. With WebGPU + a handy UI, you'll be able to do ML straight in the browser. https://
covizdemo.vercel.app -
BioAutoMATED: AI Platform Accelerates Biological Research
By
–
Revolutionize your biological research with BioAutoMATED! This automated machine-learning platform empowers researchers to quickly generate AI models and accelerate scientific discovery using AutoML. Learn more about its capabilities and impact here: https://
rb.gy/mr78l -
Test-Time Training Framework for Video Stream Prediction
By
–
Test-Time Training on Video Streams
— AK (@_akhaliq) 12 juillet 2023
paper page: https://t.co/joD2zLc9dJ
Prior work has established test-time training (TTT) as a general framework to further improve a trained model at test time. Before making a prediction on each test instance, the model is trained on the same… pic.twitter.com/AzPRbHhChtTest-Time Training on Streams paper page: https://
huggingface.co/papers/2307.05
014
… Prior work has established test-time training (TTT) as a general framework to further improve a trained model at test time. Before making a prediction on each test instance, the model is trained on the same -
Anthropic AI’s Claude 2 now available in US/UK, a long-awaited ChatGPT competitor.
By
–
If you’re in the US/UK, you can take Anthropic AI’s Claude 2 for a spin today. Claude is ChatGPT’s long awaited competition that can accept prompts hundreds of pages long: https://
anthropic.com/index/claude-2 -
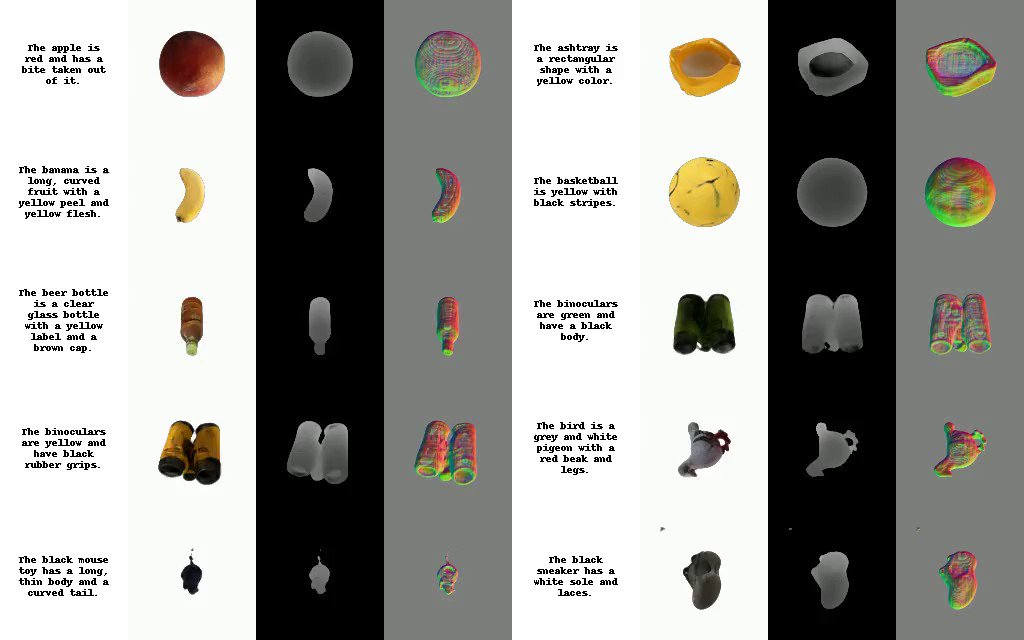
AutoDecoding Latent 3D Diffusion Models for Asset Generation
By
–
AutoDecoding Latent 3D Diffusion Models
— AK (@_akhaliq) 12 juillet 2023
paper page: https://t.co/ftMUZW1hxg
present a novel approach to the generation of static and articulated 3D assets that has a 3D autodecoder at its core. The 3D autodecoder framework embeds properties learned from the target dataset in… pic.twitter.com/IPja1uHPRNAutoDecoding Latent 3D Diffusion Models paper page: https://
huggingface.co/papers/2307.05
445
… present a novel approach to the generation of static and articulated 3D assets that has a 3D autodecoder at its core. The 3D autodecoder framework embeds properties learned from the target dataset in -
Collaborative Score Distillation for Consistent Visual Synthesis
By
–
Collaborative Score Distillation for Consistent Visual Synthesis
— AK (@_akhaliq) 12 juillet 2023
paper page: https://t.co/Lb1yiocpqq
Generative priors of large-scale text-to-image diffusion models enable a wide range of new generation and editing applications on diverse visual modalities. However, when… pic.twitter.com/NzO05zCI8fCollaborative Score Distillation for Consistent Visual Synthesis paper page: https://
huggingface.co/papers/2307.04
787
… Generative priors of large-scale text-to-image diffusion models enable a wide range of new generation and editing applications on diverse visual modalities. However, when -
Ex-PyTorch Leaders Launch ML Infrastructure Startup
By
–
a few ex-PyTorch folks started an ML Infra company last year, and now they have a twitter account.
also, @jiayq the infamous Caffe author and PyTorch 1.0 co-lead just left Alibaba to start an ML Infra company.
worth following to see what magic they will create. -
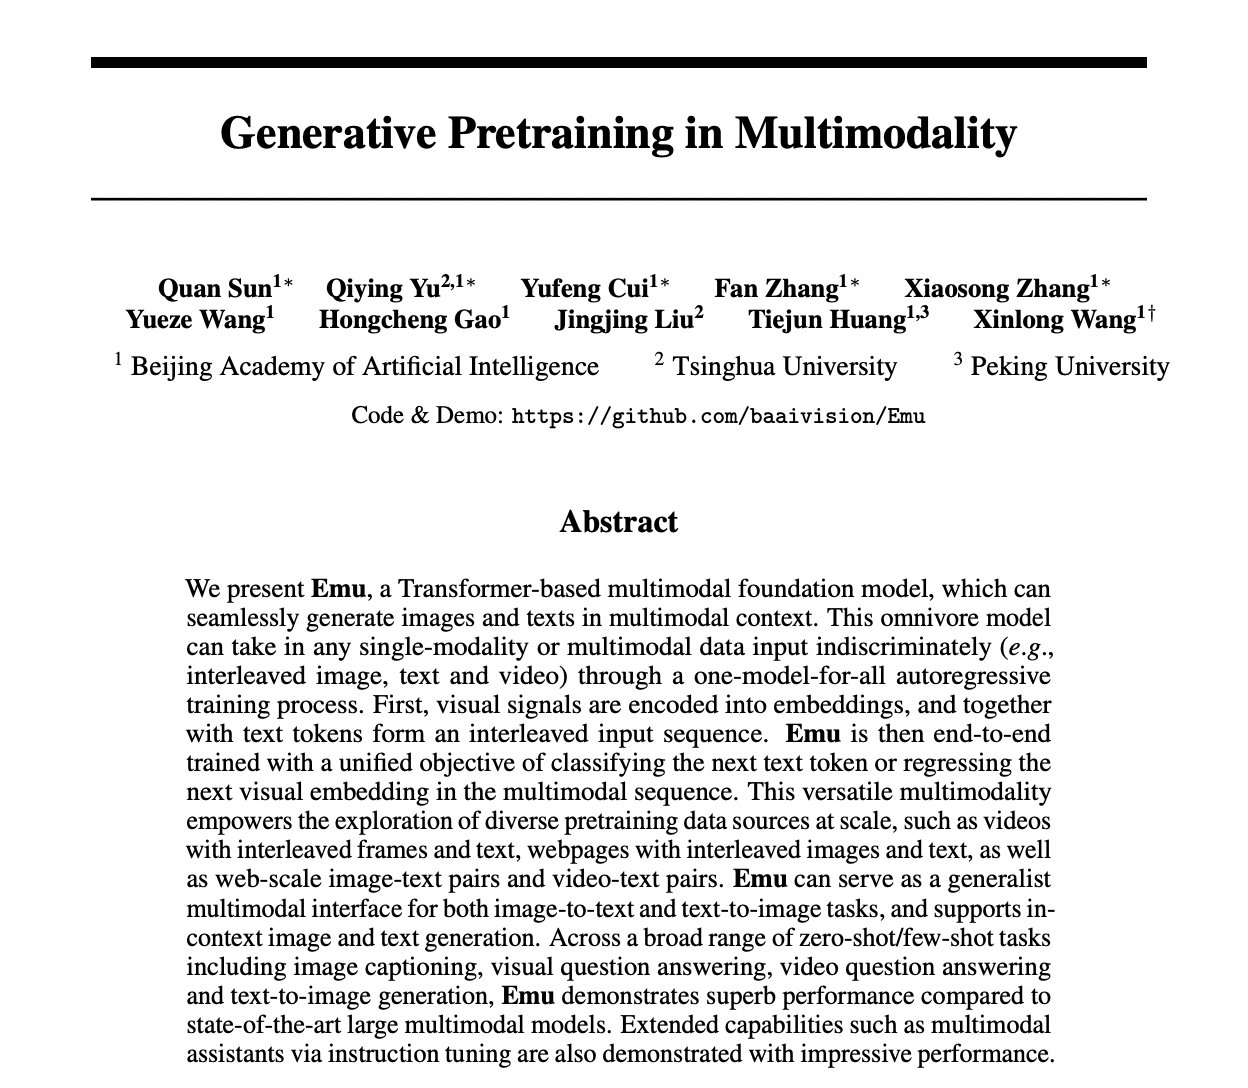
Emu: Multimodal Foundation Model for Image and Text Generation
By
–
Generative Pretraining in Multimodality paper page: https://
huggingface.co/papers/2307.05
222
… present Emu, a Transformer-based multimodal foundation model, which can seamlessly generate images and texts in multimodal context. This omnivore model can take in any single-modality or multimodal data