Learning an LLM from the whole Internet is a spectacularly inefficient way to understand language.
MACHINE LEARNING
-

Neer Jain on Model Ensembling for Improved Prediction Performance
By
–


Neer Jain Explains Model Ensembling Strategies Used to Improve Prediction Performance in The Competition! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux
-

AI Enters the Kill Chain: Unity in Principle, Variation in Practice
By
–
Unity In Principle, Variation In Practice: When AI Enters the Kill Chain! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-

Matrix Factorization Explained for Recommendation Systems
By
–


What's Matrix Factorization! #RecSy #BigData #Analytics #DataScience #AI #MachineLearning #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #Linux #Mathematics #Programming #Coding #100DaysofCode https://
geni.us/Matrix-RecSys -
On-chain GANs: InChainPepeGAN, Concrete, and AAA improvements
By
–
I stand corrected! There are at least two on-chain GANs that predate this, InChainPepeGAN (from 2023!) and Concrete by Higgs by @0xdiid
. So AAA is not first in that regard, although it's still innovative, as it generates clear subjects in high res, so it pushes fidelity forward -
GPT 5.5 improving while Claude models worsening, no clear winner
By
–
GPT 5.5 seems to be improving in that direction now, and Claude models are getting worse at it, so I don't think there's a clear winner now.
-
Need better evaluation of models for human-AI cooperation
By
–
We desperately need better ways of evaluating models. Something that shows how helpful they are at working hand-in-hand with humans to help them get stuff done in a cooperative/iterative way. The Claude models have consistently been better at this, and the market rewards that.
-
Gemini Flash 3.5 criticized for prioritizing evals over user helpfulness
By
–
Gemini Flash 3.5 is such a disappointing model. It's intelligence and speed is awesome. Absolutely amazing. But it's been trained to max evals, not to be helpful to humans. It goes off and does random crap "for me" rather than just doing what I asked.
-

Free AI Engineering Curriculum with 435 Lessons
By
–
this guy literally put a full AI engineering curriculum on GitHub and made it 100% FREE 435 lessons. 20 phases. 320 hours. The rule that makes this curriculum completely different: Every algorithm gets implemented from raw math before a single framework gets imported.
-
Expensive MacBooks run MiniMax with low performance and limited context
By
–
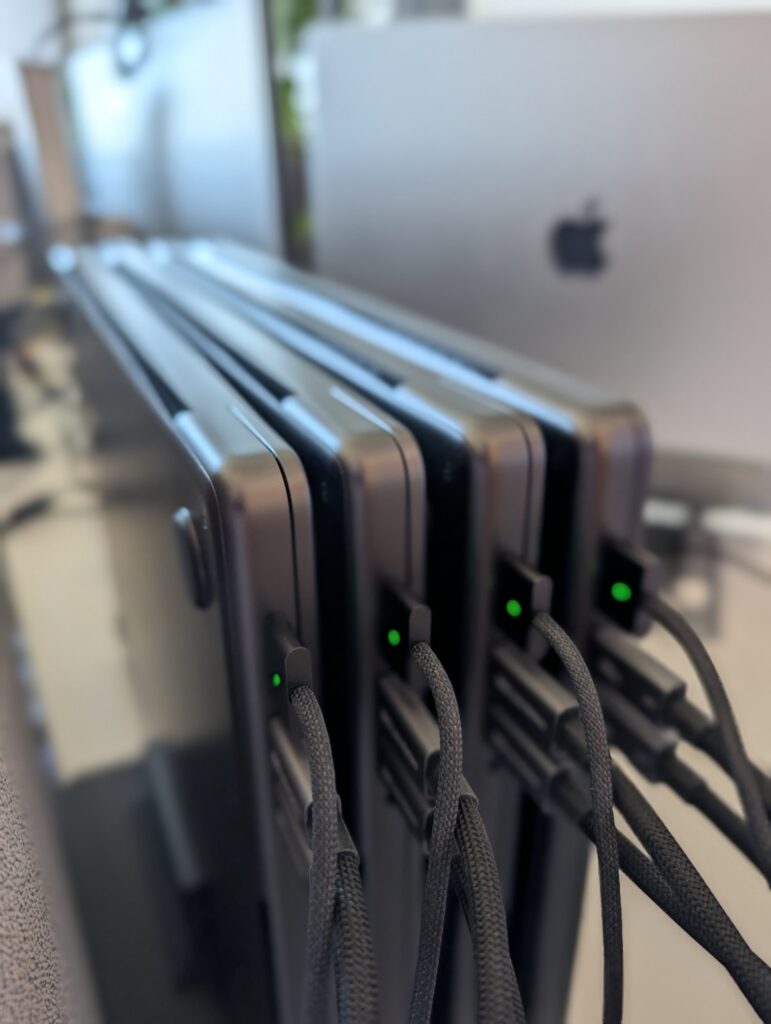
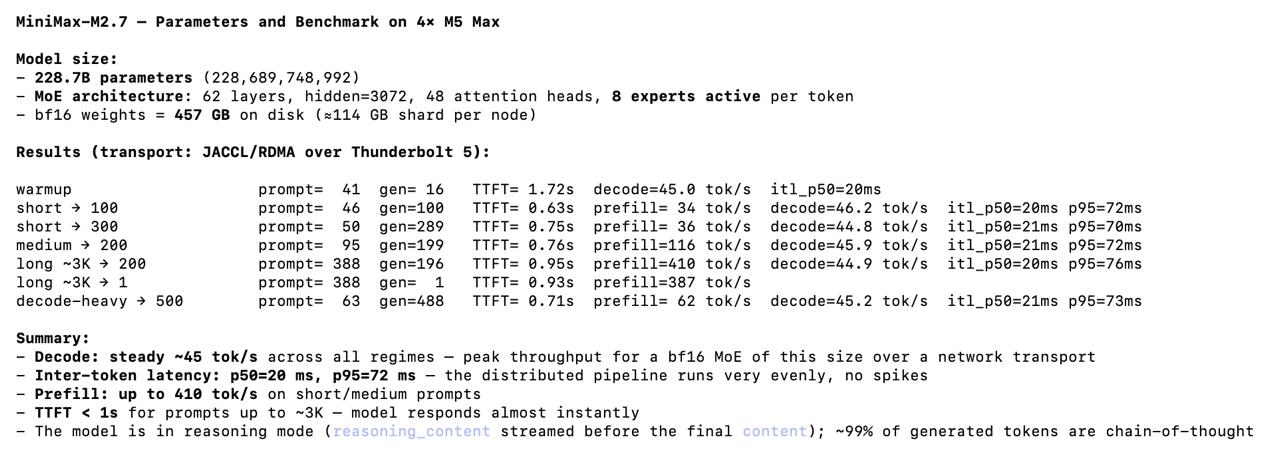
Good example of Performative Inference / Local AI grifting MiniMax-M2.7 on 4x M5 Max MacBooks (~$22,000 USD) – Longest prompt: 338 (???) – Max context: ~3k (???) – 45 tok/s (lol) – Single prompt, no parallel requests Some of the funniest & stupidest shit I've ever seen