i think it's the information-sharing/generalization part that makes what we'd call understanding happen
MACHINE LEARNING
-
Scaling Laws Show LLMs Cannot Memorize Training Data
By
–
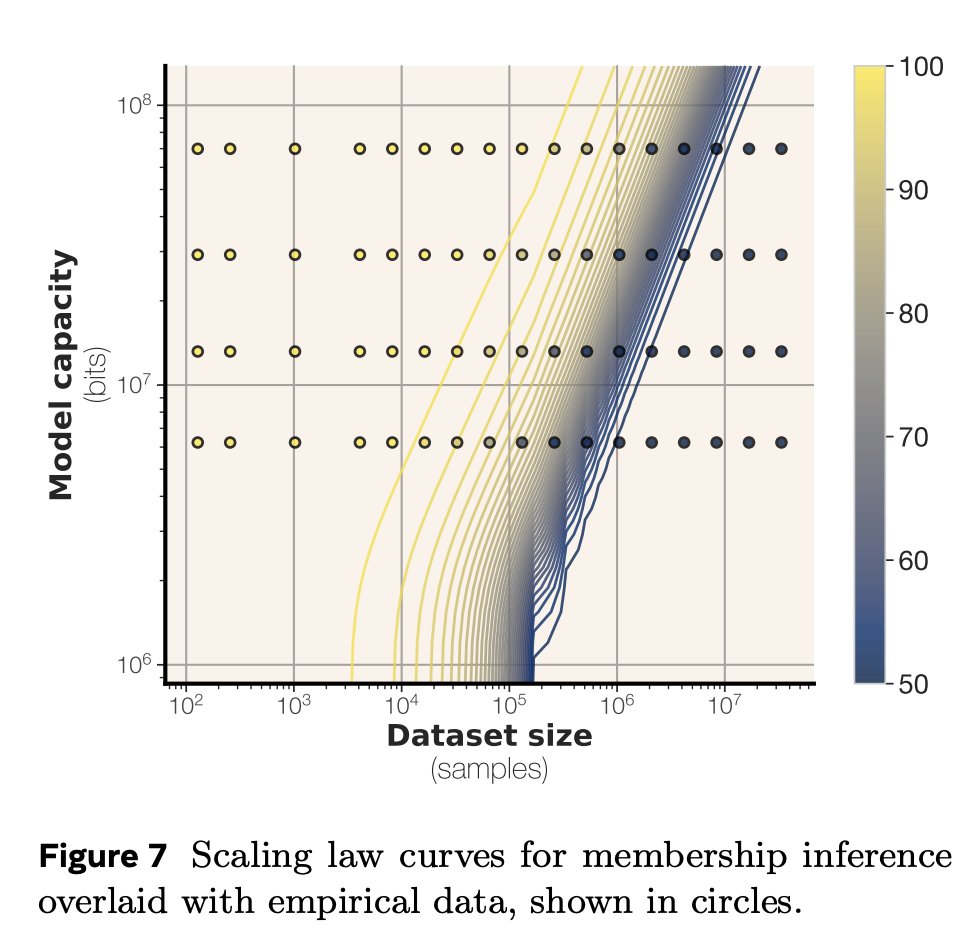
and finally we can compute membership inference success rate across all our models, ending up with this scaling law main takeaway: models trained on massive datasets (e.g. every LLM that comes out) can't memorize their training data there's simply not enough capacity
-
Transformer Parameter Efficiency and Bitwise Usage Analysis
By
–
we also compute capacity in bf16 and it drops a bit, to 3.5ish. but that's a relative increase in bitwise usage (11% of bits or so to 22% of bits) (my first thought was that transformers are doing a bad job of using params efficiently, but now im not sure. it's not *that* bad)
-
Model Training: Memorization vs Generalization in Language Models
By
–
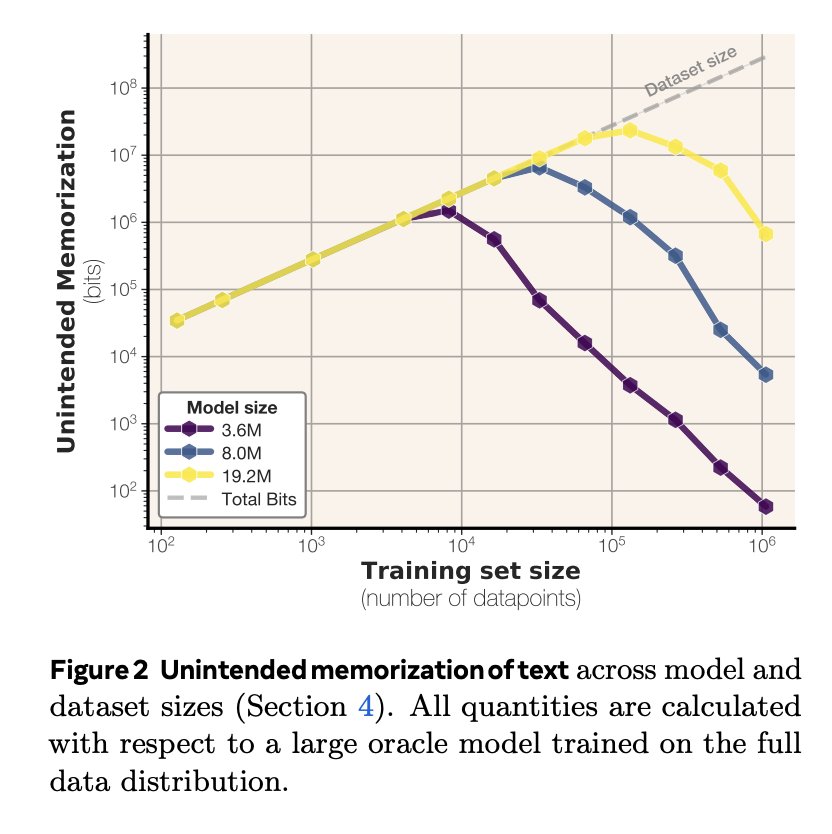
when we train on text data, the curves look different models memorize examples to the extent that they can fit them in their parameters beyond this point, the models discard per-example mem. in favor of shared info (*generalization*) see how the lines start to slope downward:
-
Model Memorization Fixed Capacity Training Saturation Analysis
By
–
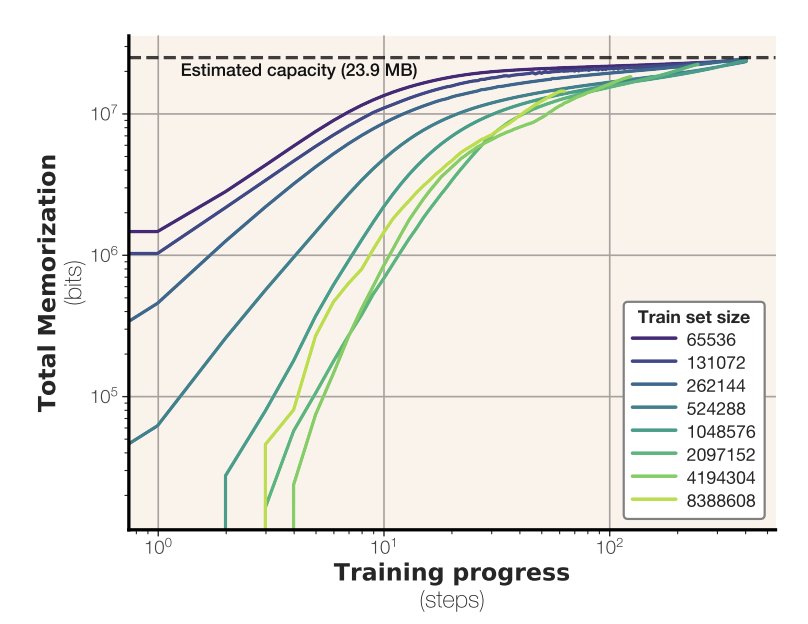
we train all of our models until they "saturate" which usually happens around 1M steps using a very large batch size models memorize the same amount, regardless of training datasize meaning they have fixed capacity and instead "spread it thinner" when trained on more examples
-
Grokking in AI Models: How Learning Achieves Capacity Saturation
By
–
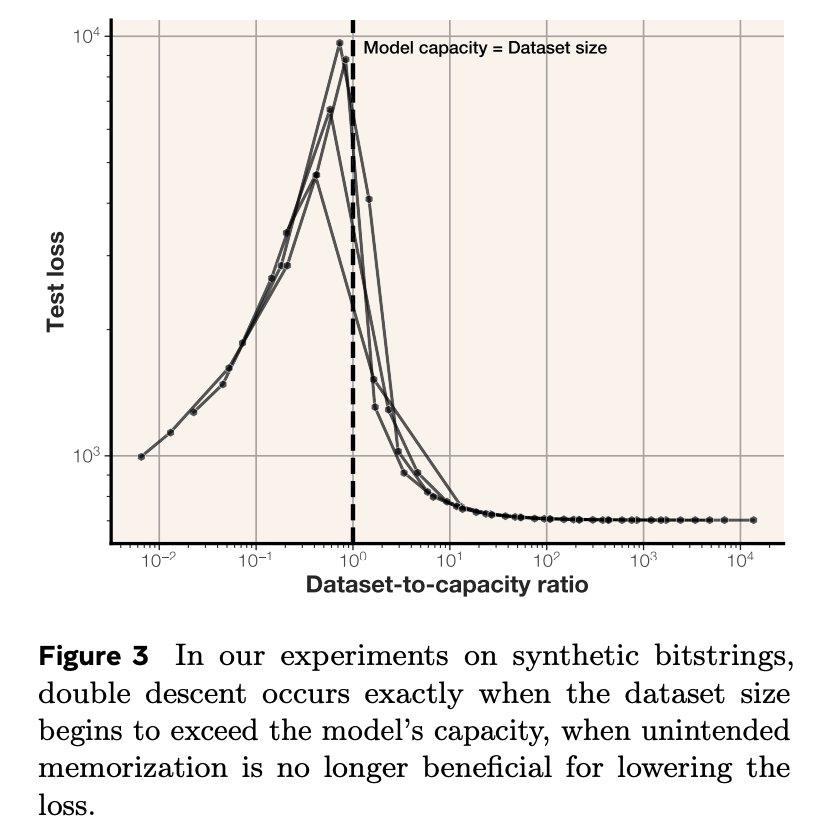
this gives a pretty good explanation into how models learn in particular, it explains grokking grokking occurs *exactly* when capacity saturates. this is where models can't perfectly fit every training example, so they have to share info bt examples in a smart way
-

GPT Model Capacity Analysis: Linear Trend at 3.6 Bits-Per-Parameter
By
–
we then compute the capacity of different models (GPT models with varying numbers of layers and hidden dimensions) averaged over hundreds of models in fp32, we get the following curve, indicating a linear trend of around 3.6 bits-per-parameter, regardless of the exact details:
-

Measuring Model Memorization with Random Uniform Strings
By
–
this all started from a quest to come up with a proper measurement of model memorization it's hard to compute *per-example* memorization, because models "share" info between datapoints so we start with random uniform strings, where sharing isn't possible. and we get this:
-

SAS Hackathon 5th Year Global Competition Launches June
By
–
It is coming up on that time again… the annual #SASHackathon kickoff celebration! For our 5th year, we're bringing coders, data scientists and analytics gurus together globally to compete in our month-long event. Join us online June 11 to get registration details and hear
-
Formal Arguments Required for Large Model Limitation Claims
By
–
I think that strong claims about the limits of large end-to-end trained models require a formal argument or decisive empirical support, because they go beyond what is scientifically known