OdysseyBench tests true agentic competence: • Contextual recall (across ~5K tokens)
• Multi-step reasoning
• Cross-app state tracking
• Intent inference through casual, noisy dialogue
• Tool execution (simulated, but grounded) It’s not toy data. It’s full workflow
MACHINE LEARNING
-
OdysseyBench Evaluates Core AI Agentic Competencies
By
–
-

OdysseyBench and HOMERAGENTS: A Multi-Agent Generation Pipeline
By
–
OdysseyBench is built using HOMERAGENTS, a multi-agent generation pipeline: • HOMERAGENTS+: Converts atomic tasks into multi-turn workflows • HOMERAGENTS-NEO: Synthesizes entirely new tasks using simulated app exploration Each task is: • Goal-driven
• Dialogue-based
• -
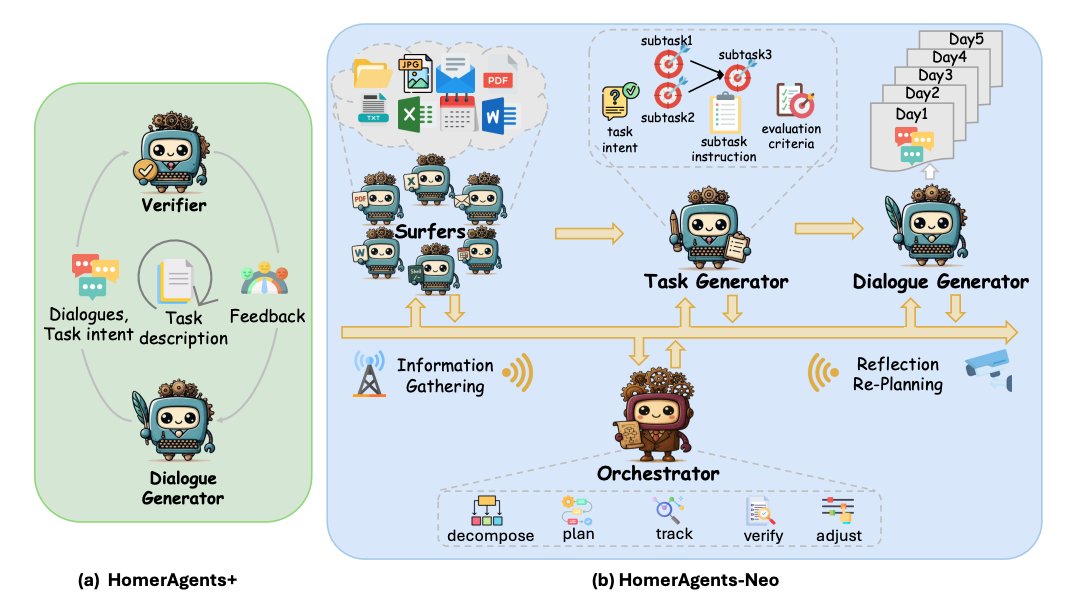
OdysseyBench: A New Benchmark for Long-Horizon AI Agent Tasks
By
–
What is OdysseyBench? A long-horizon benchmark of 602 multi-day, multi-application tasks: • Word, Excel, PDF, Email, Calendar
• 300 tasks from OfficeBench (restructured)
• 302 brand-new, complex tasks Each task is wrapped in realistic user–assistant dialogue over 5 days. -
OdysseyBench Introduced to Evaluate Long-Running AI Agent Capabilities
By
–
Today’s agents are “good” at: • Summarizing one doc
• Responding to one email
• Updating one file But in the real world? Tasks last 5 days, jump between apps, involve partial context, and require real memory. That’s what OdysseyBench simulates. -
HuggingFace improves accessibility to AI mastery
By
–
HuggingFace is making AI mastery a lot more approachable.
-

DLI2025 Attendees Master LLM and Reinforcement Learning in Hands-On Sessions
By
–


Following a day of deep-dive tutorials, attendees at #DLI2025 got to put their knowledge to the test in practical, hands-on sessions! @tejuafonja, Annie Qurat Ul Ain, and @jabez_magomere guided the Large Language Model practical, demystifying complex concepts and providing a chance to work with the technology directly. Simultaneously, Siddarth Singh, Sasha Abramowitz, and Ruan de Kock led the Reinforcement Learning session, turning theory into practice.
→ View original post on X — @shakir_za, 2025-08-19 06:38 UTC
-

Ai2 Launches MoNaCo: Multi-Step Evidence Synthesis Benchmark
By
–
Ai2 launched MoNaCo, a new eval that tests how well models stitch together evidence across dozens of sources It includes 1,315 multi‑step questions, retrieval, filtering & aggregation across text and tables, and 40+ distinct documents per query
-
100+ Free Step-by-Step AI Agents and RAG Systems Tutorials
By
–
100+ free step-by-step tutorials with code covering: AI Agents RAG Systems Voice AI Agents MCP AI Agents Multi-agent Teams Autonomous Game Playing Agents P.S: Don't forget to subscribe for FREE to access future tutorials.
-

Kirk Borne Offers Over 3600 Free Resources for X Subscribers
By
–
I continue adding more FREE resources for my @X Subscribers to access: 𝗼𝘃𝗲𝗿 𝟯6𝟬𝟬 𝗿𝗲𝘀𝗼𝘂𝗿𝗰𝗲𝘀 𝗮𝗿𝗲 𝗻𝗼𝘄 𝗮𝘃𝗮𝗶𝗹𝗮𝗯𝗹𝗲. Subscribe for only US$4.99/month. #MachineLearning #AI #DataScience #Python #Mathematics #Statistics #SQL #GenAI #AgenticAI
-
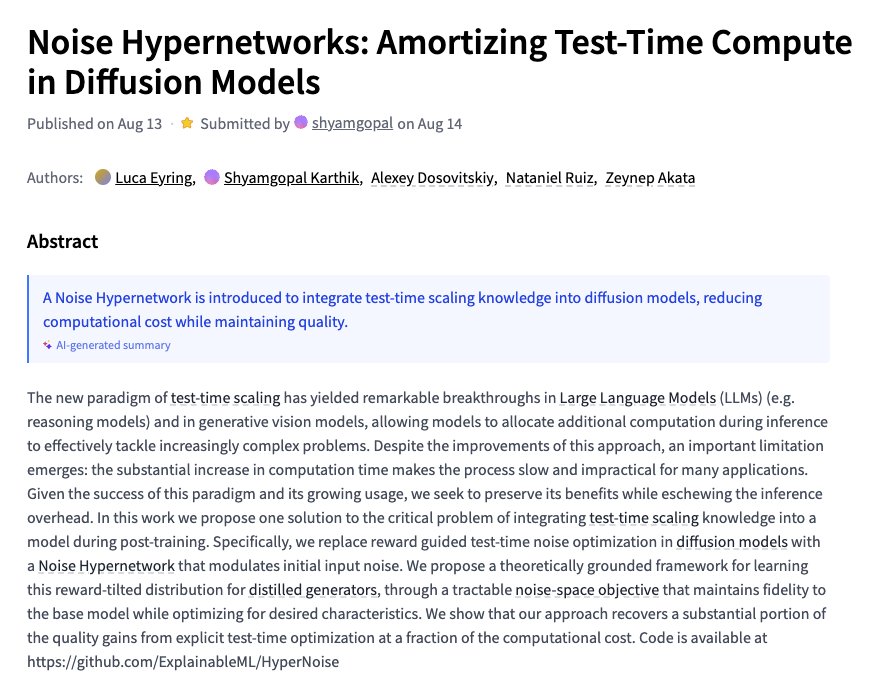
Noise Hypernetworks: Amortizing Test-Time Compute in Diffusion Models
By
–
Noise Hypernetworks Amortizing Test-Time Compute in Diffusion Models