You can argue that bio brains have vastly more weights that are mostly sparse, because the space of neurons that could have been connected to is very large, with synapses exploring and getting pruned. Simulating bio connectivity would be expensive on GPUs! Bio neurons look good
MACHINE LEARNING
-
No-Code AI and Top 10 Machine Learning Trends 2025
By
–
How could you use no-code AI to boost your projects? Top 10 Machine Learning Trends to Watch in 2025 https://
graphite-note.com/machine-learni
ng-trends/
… #AI #MachineLearning #IoT #WMC26 #5G -
Attention not fundamental; geometric evolution needed for hidden representations
By
–
This isn't claiming attention is dead. But it proves attention isn't fundamental. "What one fundamentally needs is not attention itself, but a sufficiently expressive geometric evolution mechanism for hidden representations." The era of exploring geometric alternatives to
-
What if intelligence needs no attention? Grassmann flows answer
By
–
The philosophical shift is profound: Before: "How do we make attention cheaper/faster?" Now: "What if we don't need attention at all?" The real question: What's the minimal geometric structure needed for intelligence? Attention is ONE answer. Grassmann flows prove it's not
-
Depth and local windows reduce Grassmann trails, replacing attention
By
–
The deeper you go, the better it gets. At 6 layers: Grassmann trails by 15%
At 12 layers: Grassmann trails by only 11% The model learns to approximate richer interactions through depth and local multi-scale windows. This is proof of concept that attention isn't necessary. -

Grassmann model trails in perplexity but leads in SNLI accuracy
By
–
Does it actually work in practice? Wikitext-2 (language modeling): 13M param Grassmann model: 275.7 perplexity
13M param Transformer: 248.4 perplexity
Gap: ~11% behind SNLI (natural language inference): Grassmann head: 85.50% validation accuracy
Transformer head: 85.45% -

Attention quadratic vs Grassmann linear scaling complexity gap
By
–
The complexity story is WILD: Standard attention: O(L²d) – quadratic scaling with sequence length
Grassmann mixing: O(Ld²) – LINEAR scaling (for fixed rank r) This isn't just theoretical. As sequences get longer, the gap becomes exponential. -

Grassmann flows replace attention with geometric evolution
By
–
The alternative is mathematically beautiful: Grassmann flows replace attention with controlled geometric evolution on a manifold. – Reduce hidden states to r=32 dimensions (from d=256)
– Encode token pairs as 2D subspaces on Gr(2,r)
– Use Plücker coordinates to create geometric -

Massive attention matrices cause Transformer interpretability crisis
By
–
Here's the interpretability crisis no one talks about: Every Transformer layer creates an L×L attention matrix. Across 96 layers and 96 heads in GPT-4, that's a MASSIVE evolving tensor cloud. The paper proves this is why we can't interpret these models not their size, but their
-
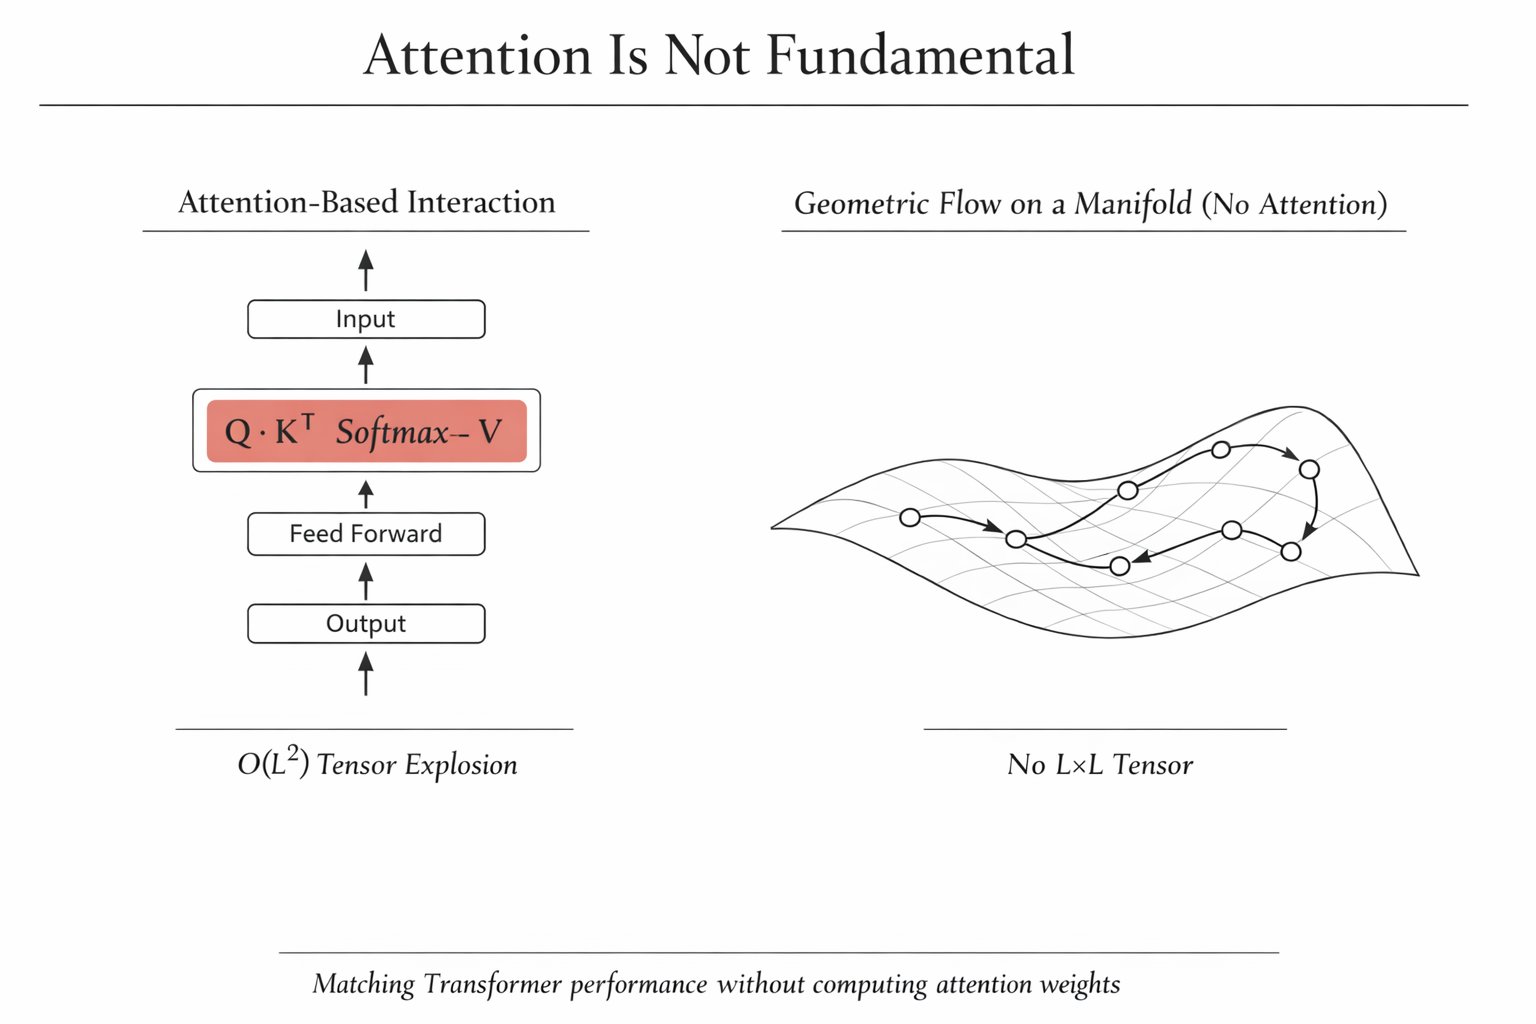
Transformer performance matched without computing attention weights
By
–
This paper just murdered the foundation of every AI model you've ever used. A researcher proved you can match Transformer performance WITHOUT computing a single attention weight. Here's what changed (and why this matters now):