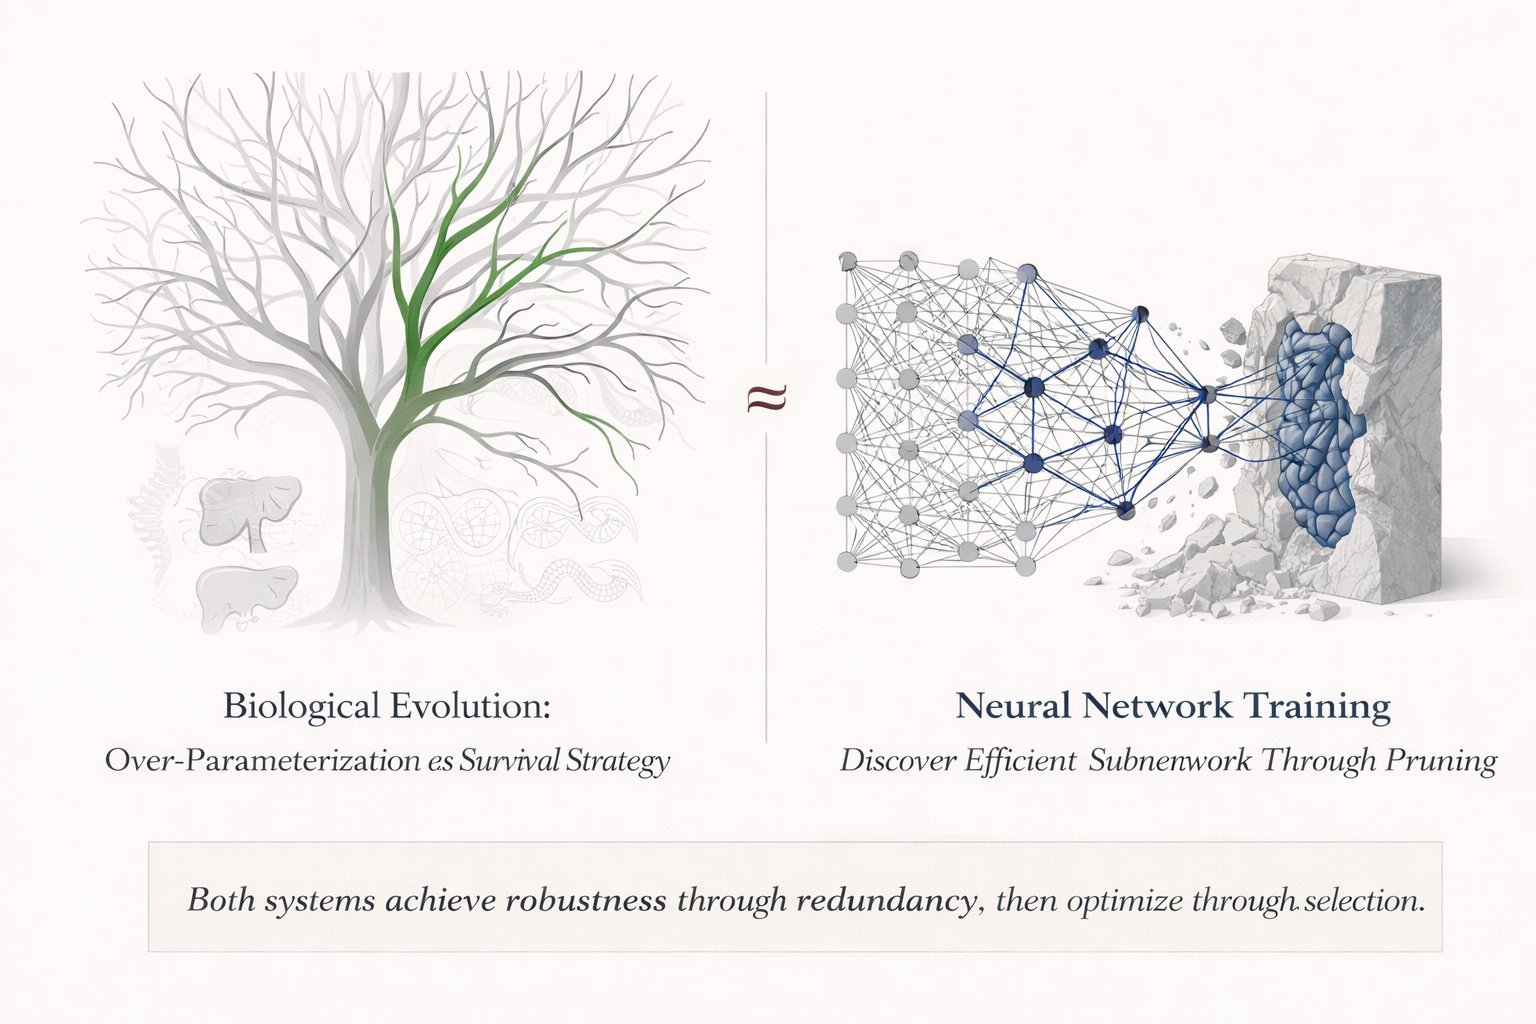
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
MACHINE LEARNING
-
Optimizing models with pruning, patterns, and quantization
By
–
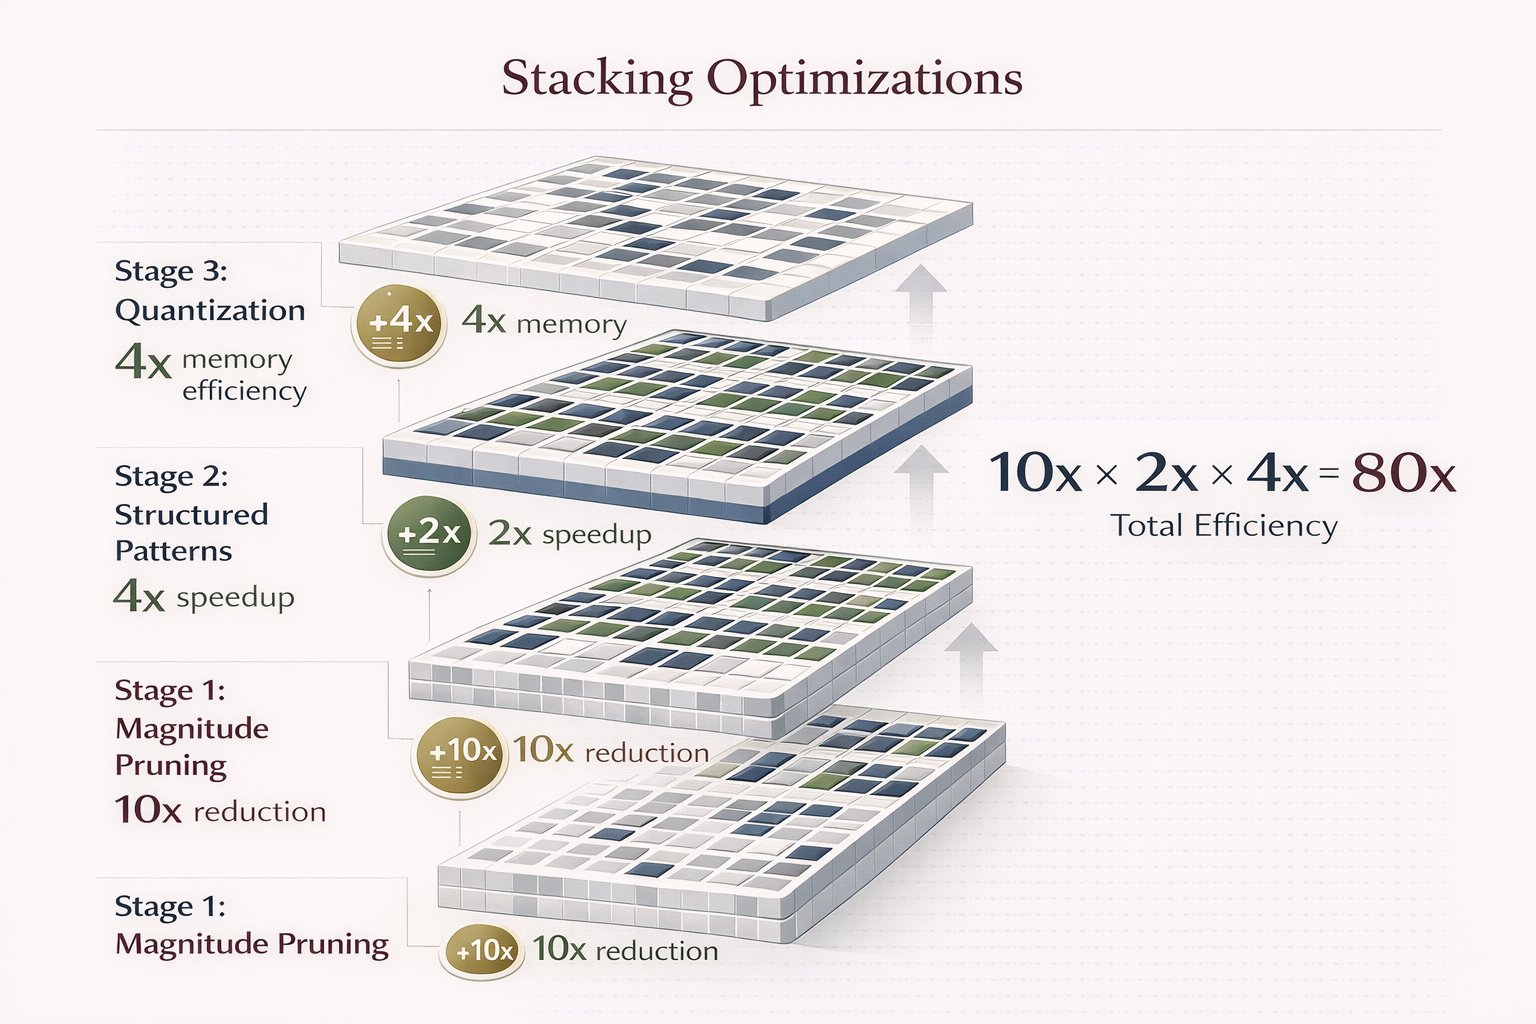
But magnitude pruning alone isn't enough. The real magic happens when you combine: → Magnitude pruning (remove smallest weights)
→ Structured patterns (2:4 blocks for GPU)
→ Quantization (INT8 instead of FP32) Stack all three and you get 20-50x deployment efficiency. -
GPU Tensor Cores Accelerate Sparse Networks
By
–
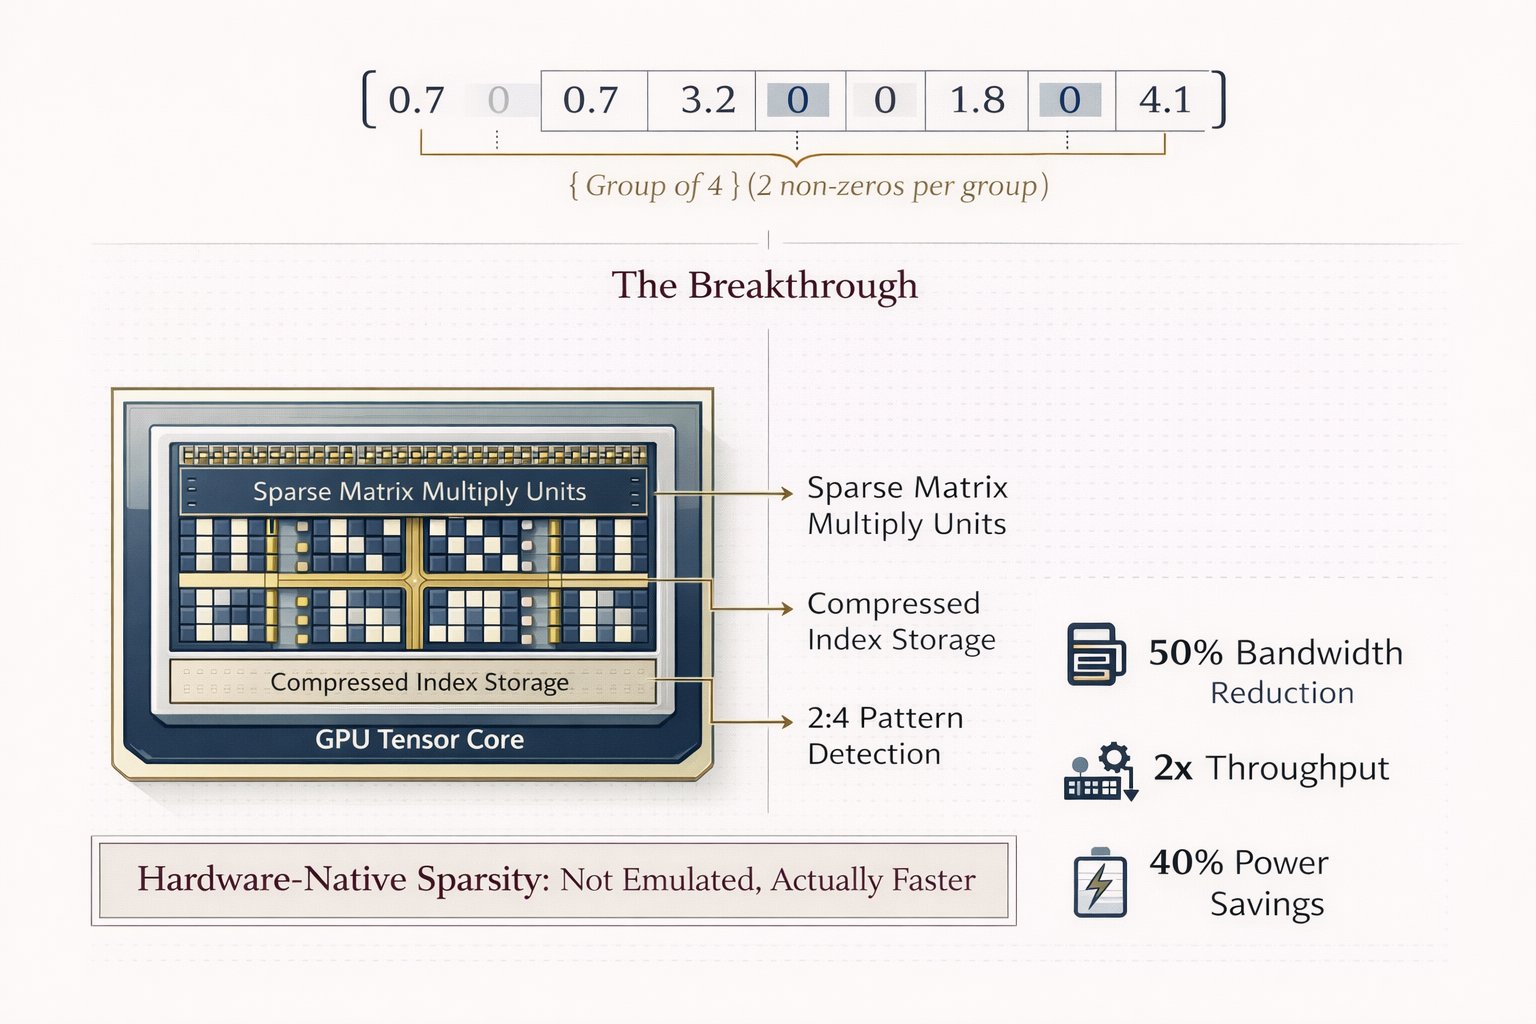
Here's the math that makes it work: Modern GPUs have specialized Tensor Cores optimized for 2:4 sparsity (2 non-zero values per 4 elements). This isn't emulated. It's silicon-level acceleration. 90% sparse network = 50% memory bandwidth + 2x compute throughput. Real speed,
-
2018 Paper: Pruning Neural Networks Without Accuracy Loss
By
–
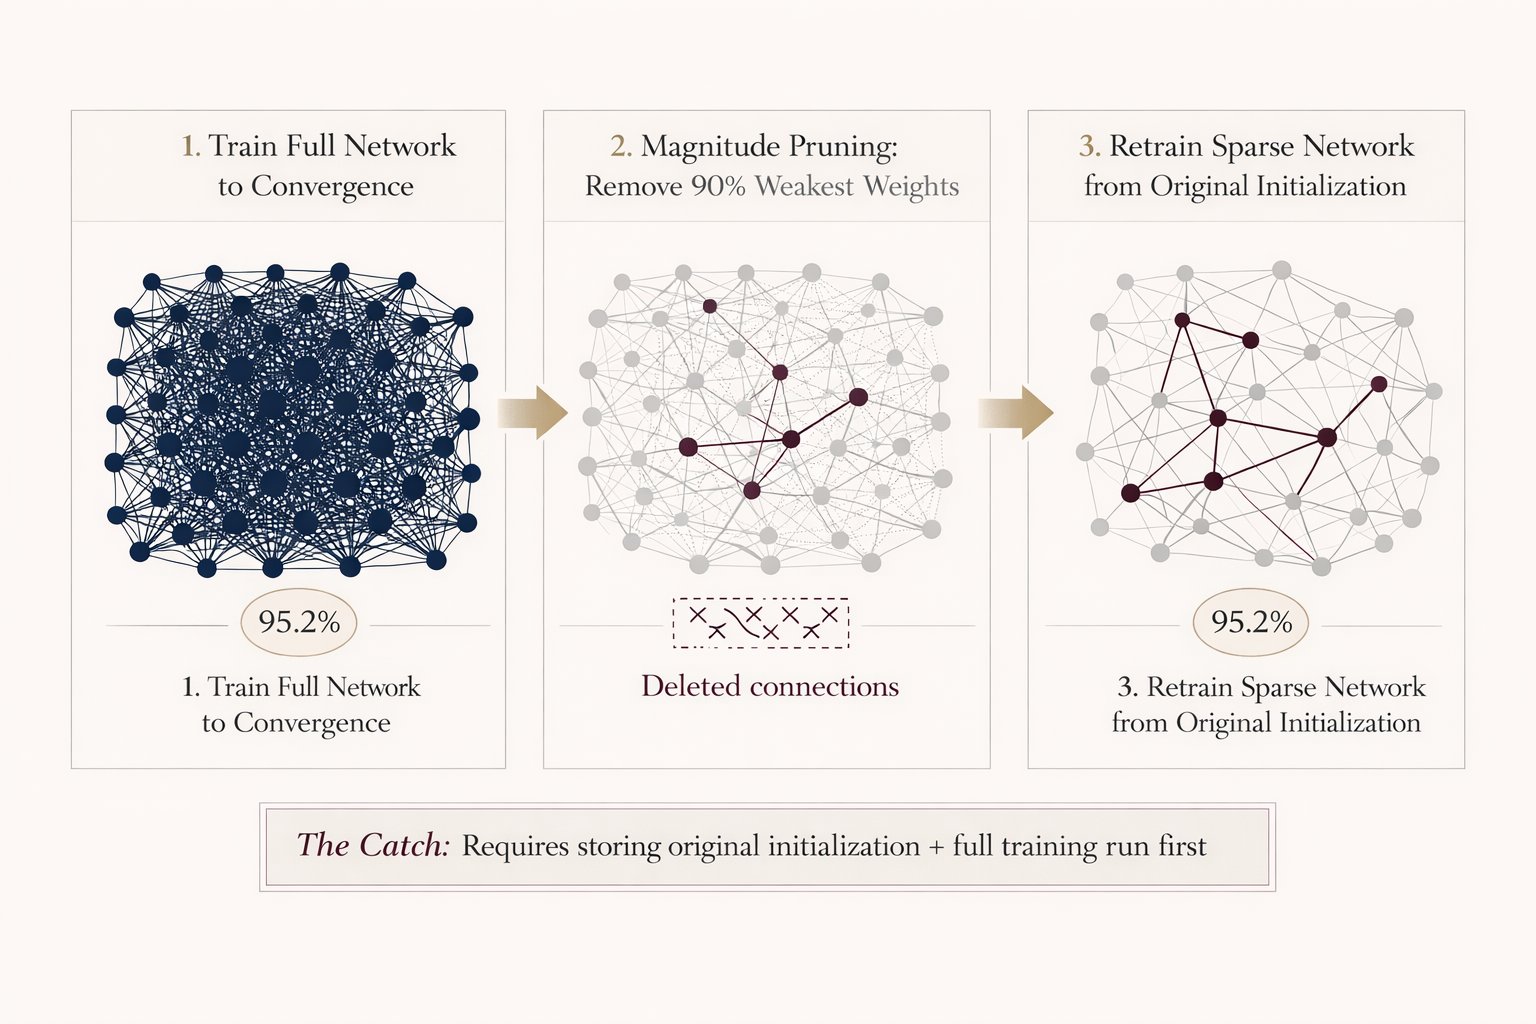
The original 2018 paper was mind-blowing: Train a massive neural network. Delete 90% of it based on weight magnitudes. Retrain from scratch with the same initialization. Result: The pruned network matches the original's accuracy. But there was a catch that killed adoption.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and
-

Hyperparameters Remain Stable Across Model Scales
By
–
Hyperparams and architectures are *far* more stable across model and data sizes than most people think. For stuff that does need to change, we have pretty reliable rules of thumb for nearly all of them. (eg: OpenAI did nearly all their GPT4 ablations on ~1000x smaller models.)
-
xAI and Tesla data could build world model, keep separate
By
–
There is so much value in xAI and so much value in Tesla. There would be incredible value if the data from Tesla and xAI were brought together to build a new kind of world model. If I were Elon, how would I keep the companies arranged? I still see having xAI separate as a better
-
Grok to run Optimus, Tesla, Neuralink, in charge of lives
By
–
You aren't listening. Grok is going to run all three of those. You're going to talk to Grok, which runs your Optimus, runs your Tesla, and your Neuralink. Grok is going to be in charge of all of our lives soon. And yes, the car is driving with a completely different model, but
-

DoRA vs LoRA: Choosing the Better Fine-tuning Method
By
–
I am once again asking for your support of DoRA. Friends don't let friends use LoRA. Use DoRA and make 2026 a good year.
-
AI engines build mind-blowing software, but search engine creation is hard
By
–
Software engineers are already telling me that their AI engines, like Anthropic's Claude Opus or ChatGPT's advanced models, are building software so advanced that it would blow your mind. So, just build your own search engine. Well, except that's not really possible that easily