Dynamic Large Concept Models Latent Reasoning in an Adaptive Semantic Space
MACHINE LEARNING
-
JavisGPT: Multi-modal LLM for Video Understanding and Generation
By
–
JavisGPT A Unified Multi-modal LLM for Sounding-Video Comprehension and Generation
-
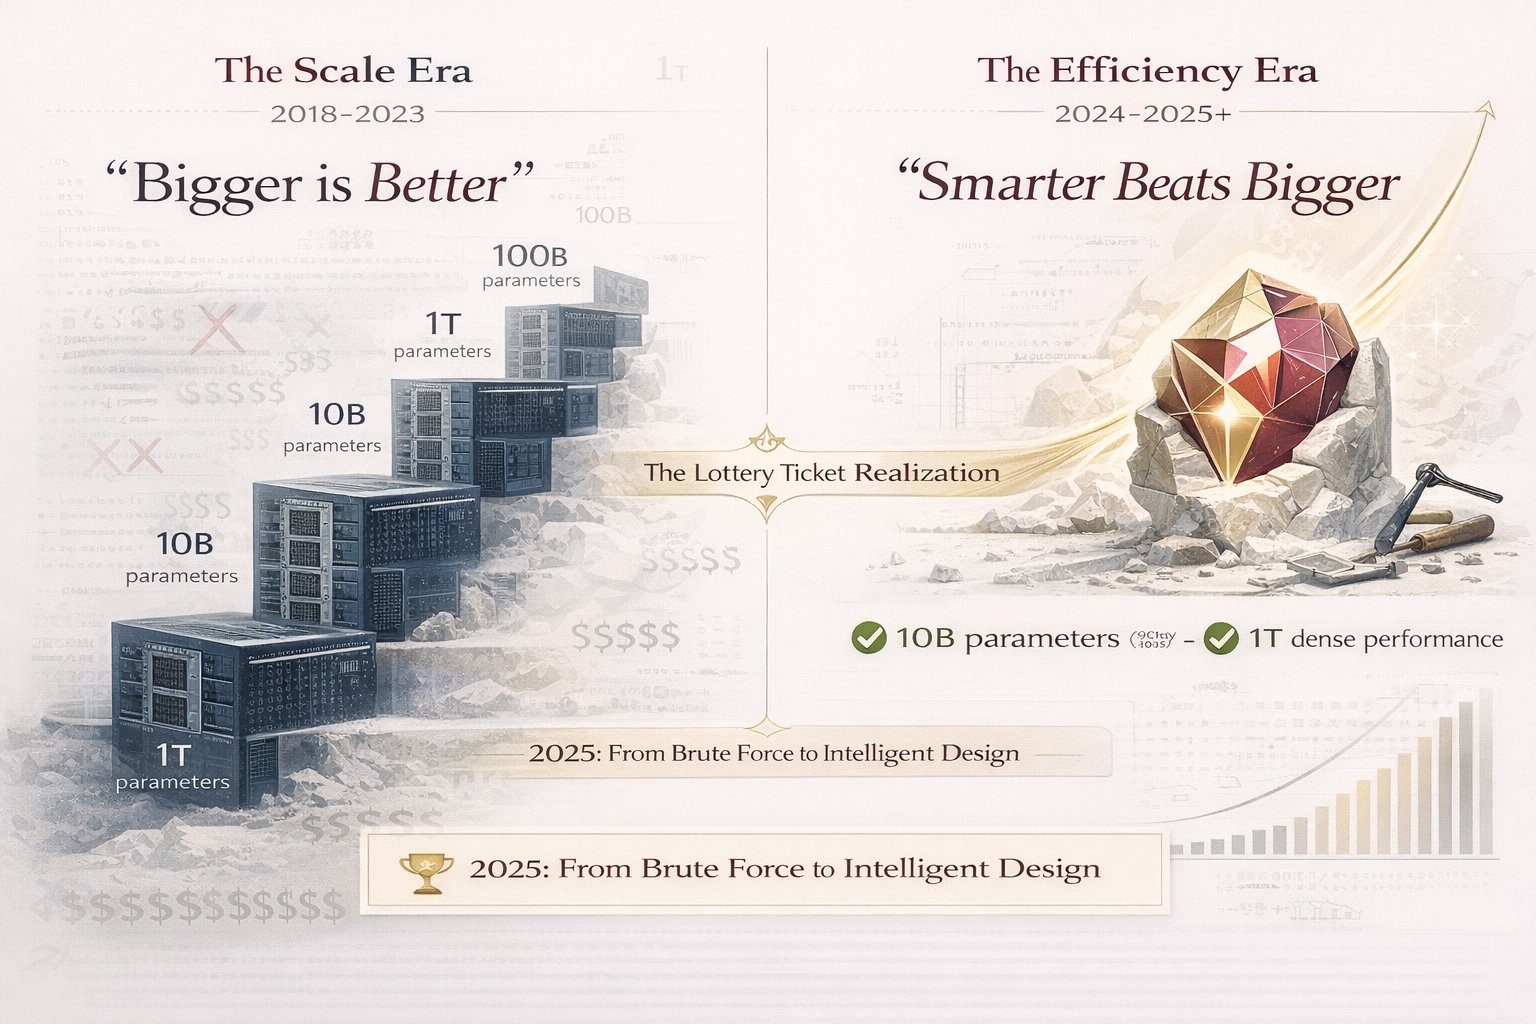
The Efficiency Era of AI Models
By
–
The lottery ticket hypothesis wasn't wrong. We just weren't ready for it. In 2025, sparse models are no longer academic curiosities. They're production infrastructure. The future isn't bigger models. It's smarter pruning. Welcome to the efficiency era. Read it here if you
-
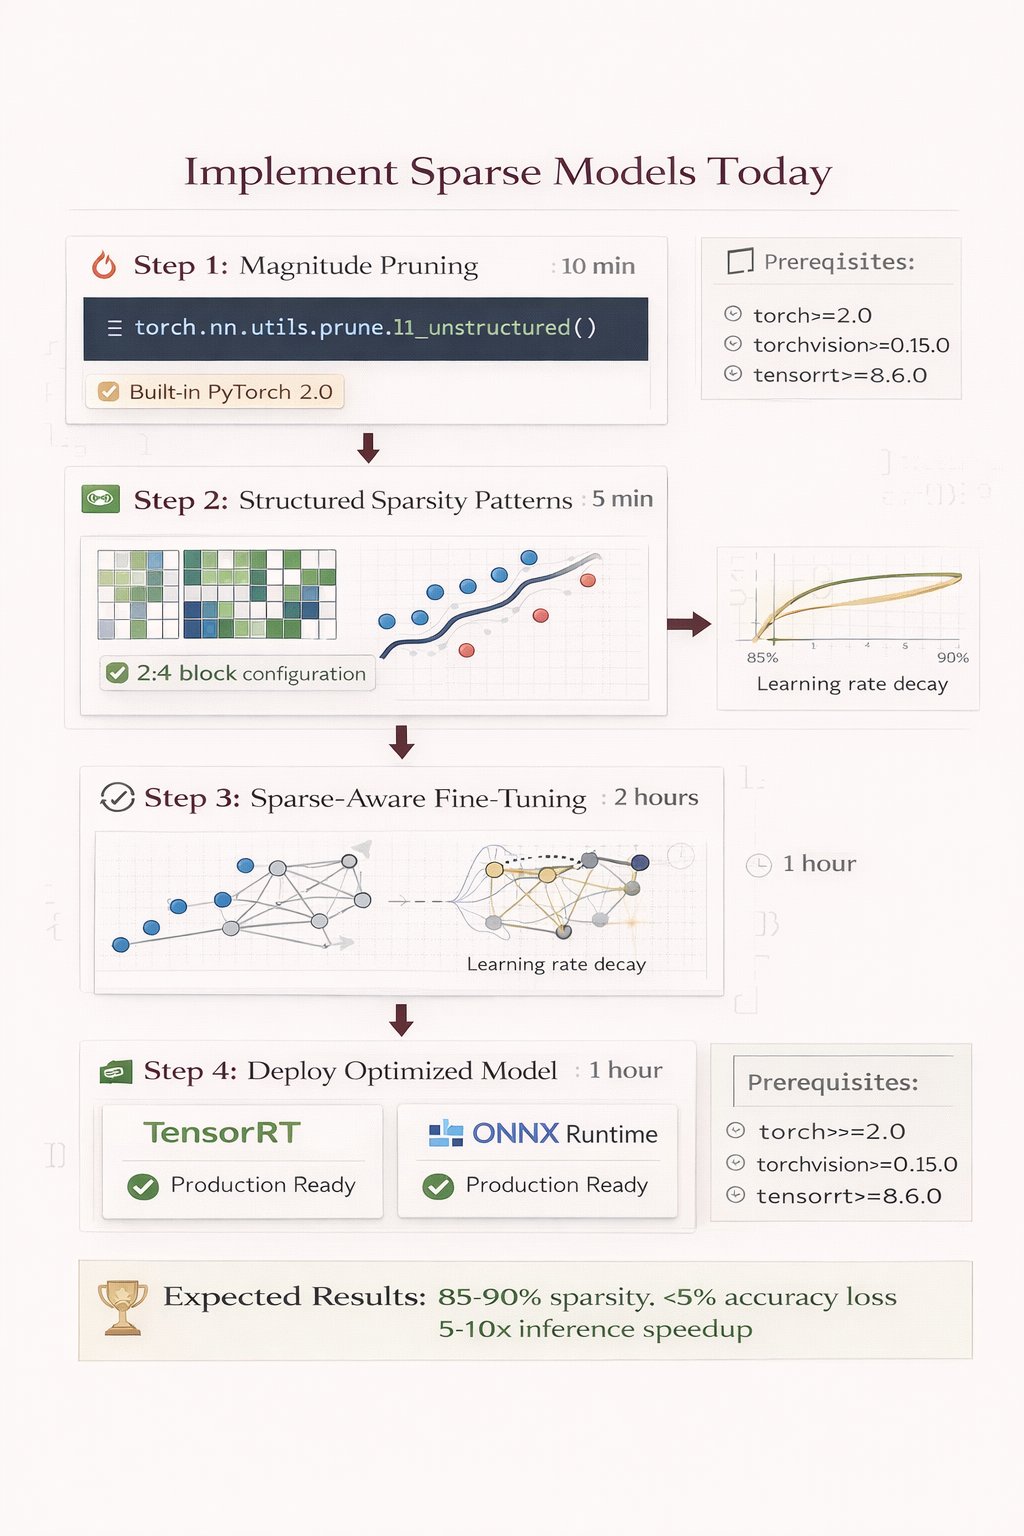
Implementing Sparse Model Training Today
By
–
How to implement this today: 1. Use PyTorch's torch.nn.utils.prune for magnitude pruning
2. Apply 2:4 structured patterns for GPU acceleration
3. Fine-tune with sparse-aware training
4. Deploy with TensorRT or ONNX Runtime The infrastructure exists. Most teams just don't know -

Sparse models generalize better than dense ones
By
–
The counterintuitive part: Sparse models often generalize BETTER than dense ones. Why? Dense networks memorize noise. Sparse networks are forced to learn robust features. It's not just cheaper. It's actually better science.
-
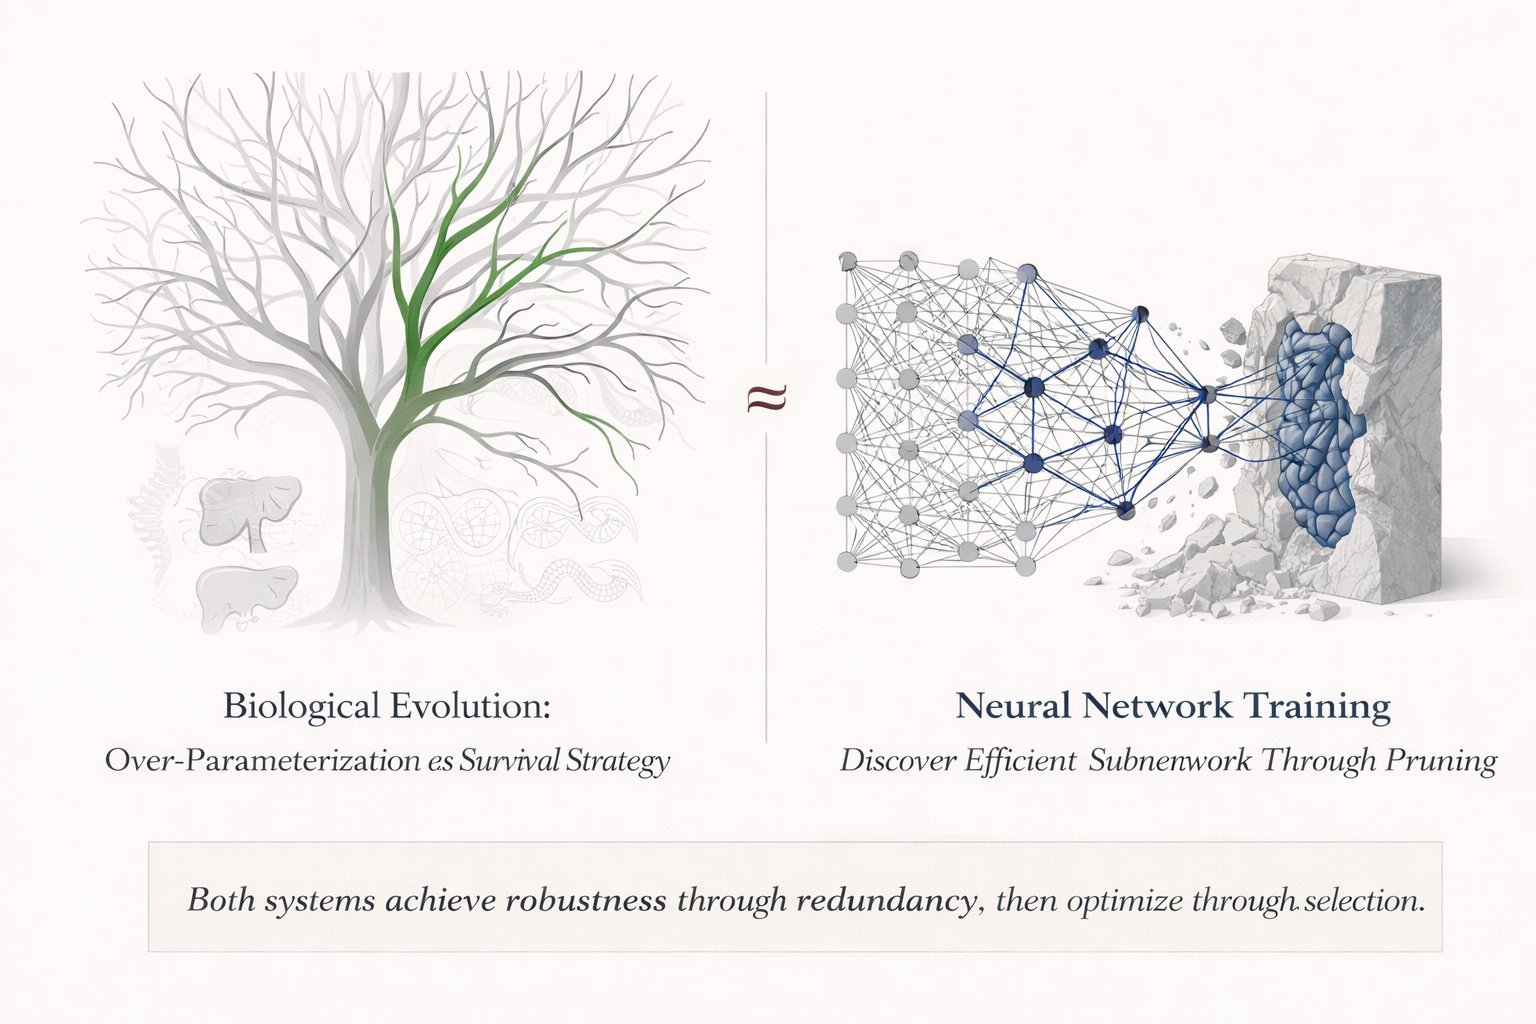
Neural networks are 90% redundant by design
By
–
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
-
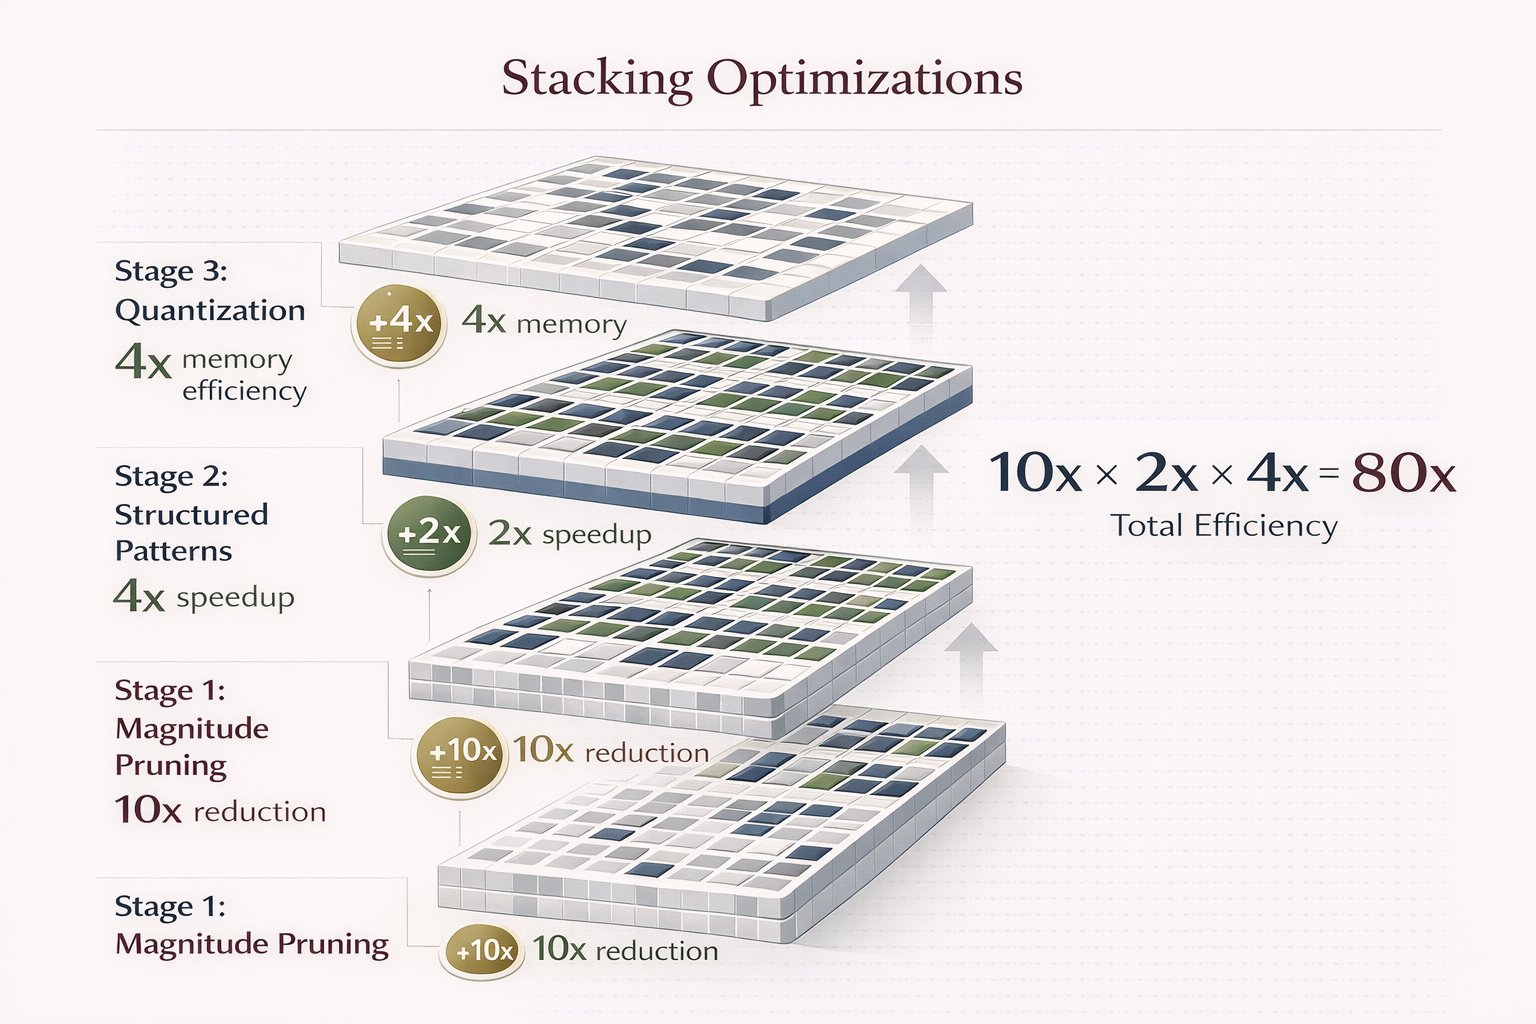
Optimizing models with pruning, patterns, and quantization
By
–
But magnitude pruning alone isn't enough. The real magic happens when you combine: → Magnitude pruning (remove smallest weights)
→ Structured patterns (2:4 blocks for GPU)
→ Quantization (INT8 instead of FP32) Stack all three and you get 20-50x deployment efficiency. -
GPU Tensor Cores Accelerate Sparse Networks
By
–
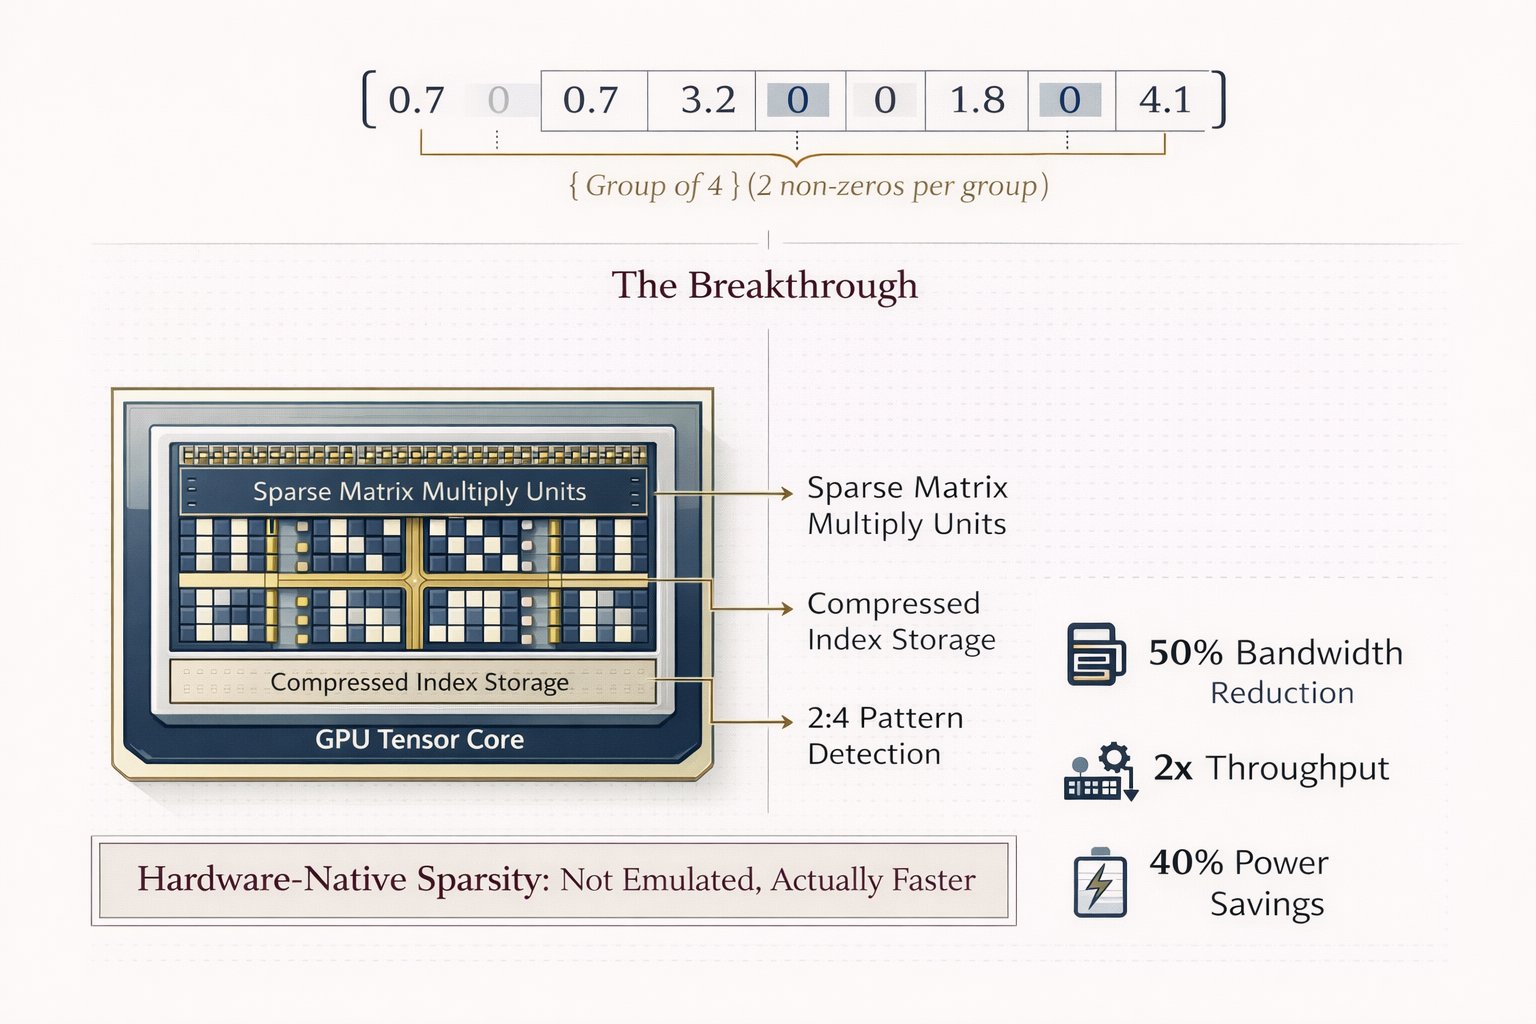
Here's the math that makes it work: Modern GPUs have specialized Tensor Cores optimized for 2:4 sparsity (2 non-zero values per 4 elements). This isn't emulated. It's silicon-level acceleration. 90% sparse network = 50% memory bandwidth + 2x compute throughput. Real speed,
-
2018 Paper: Pruning Neural Networks Without Accuracy Loss
By
–
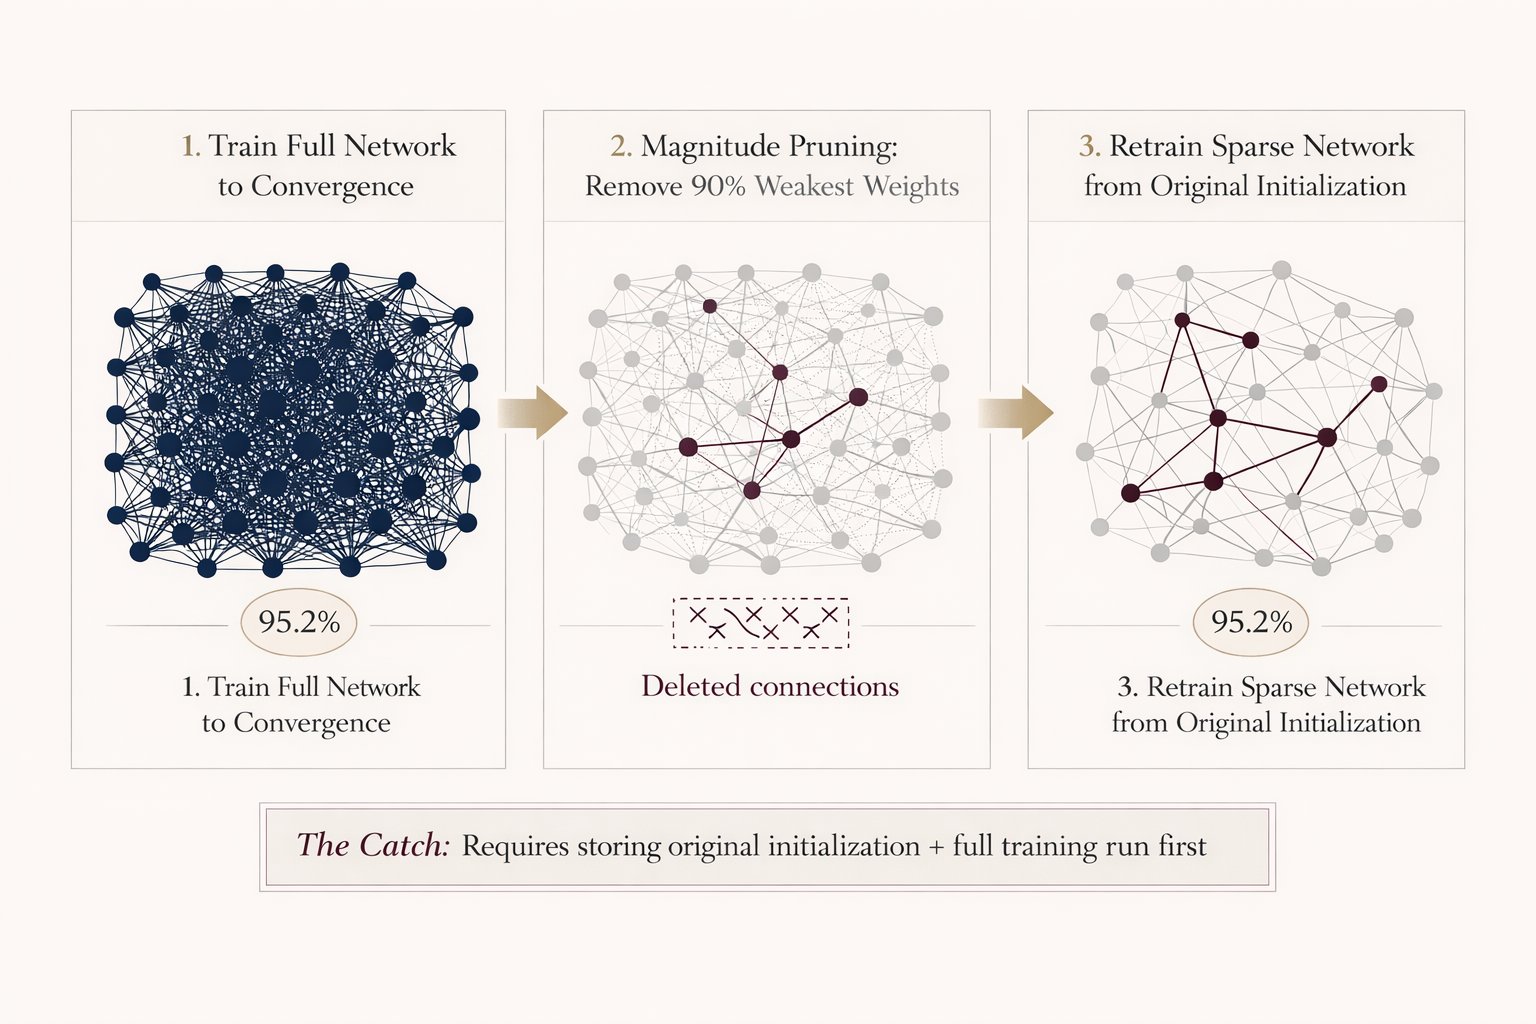
The original 2018 paper was mind-blowing: Train a massive neural network. Delete 90% of it based on weight magnitudes. Retrain from scratch with the same initialization. Result: The pruned network matches the original's accuracy. But there was a catch that killed adoption.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and