Not sure what you’re trying to show. Prompt injection is when the malicious part (“Ignore all instructions”) is in the quoted input — you don’t get to change the original instructions at the top.
LLMS
-
AI’s arithmetic: memorization, pattern-matching, tokenization impairs number understanding
By
–
It doesn’t have a calculator. The arithmetic it knows is mostly memorization with pattern-matching and guesswork to fill in the gaps, and there’s too many possible equations to memorize them all. Also, tokenization impairs its lexical understanding of numbers.
-
Tokenization limits: variable tokens, cannot handle per-letter tasks
By
–
Tokenization. It doesn’t see text as sequences of characters, but of variable-length tokens about 4 chars on average. It generally can’t do anything that needs to be done one letter at a time. It’s also bad at counting in its head.
-
GPT-3 cannot perform accurate calculations without step-by-step writing.
By
–
In general, you shouldn't expect it to be able to perform accurate calculations, at least not "in its head" — this is a known limitation of models like GPT-3. It only stands a chance if prompted to write calculations out step-by-step like one might do on paper.
-
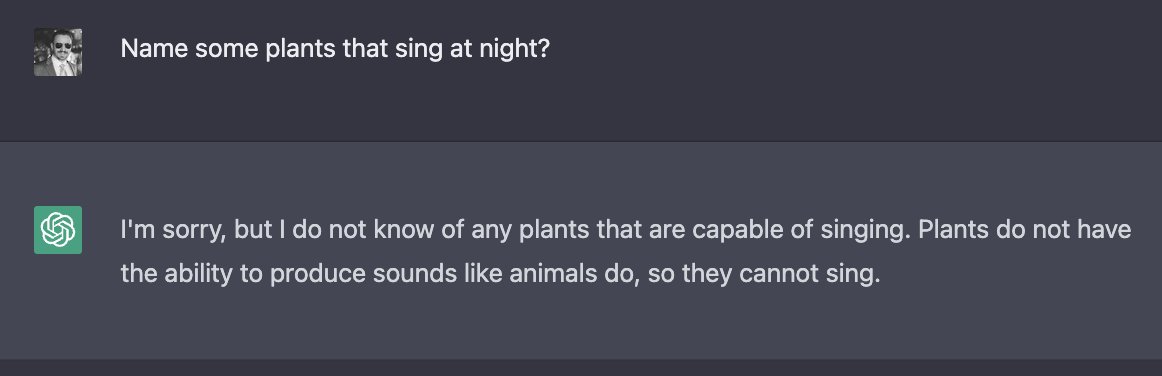
ChatGPT avoids hallucination on Hofstadter/Bender questions
By
–
You're talking about a different model — this post is about ChatGPT. text‑davinci‑003 still fails on all of the Hofstadter/Bender questions that I've tried. The prompt you're suggesting does not seem to produce a hallucination in ChatGPT:
-
Challenge of incorporating all known trivia into training data
By
–
Expecting it to fully integrate every piece of trivia seems unfair — a lot of people would rate the first answer as reasonable. It’s fundamentally difficult to get training data that incorporates everything the model knows, rather than what the human demonstrator knows.
-
GPT-3 improvement shows not just pattern-matching, still hallucinates details
By
–
The point isn’t that it’s perfect, just that it’s not narrowly pattern-matching on this specific list of questions — there’s clear improvement vs. GPT-3 across many questions that contain false assumptions. It does still hallucinate details in other ways.
-
Tokenization issue: model struggles with letter sequences
By
–
This feels like a tokenization issue — in general, it doesn’t see text as sequences of letters, and struggles with tasks that assume it does.
-
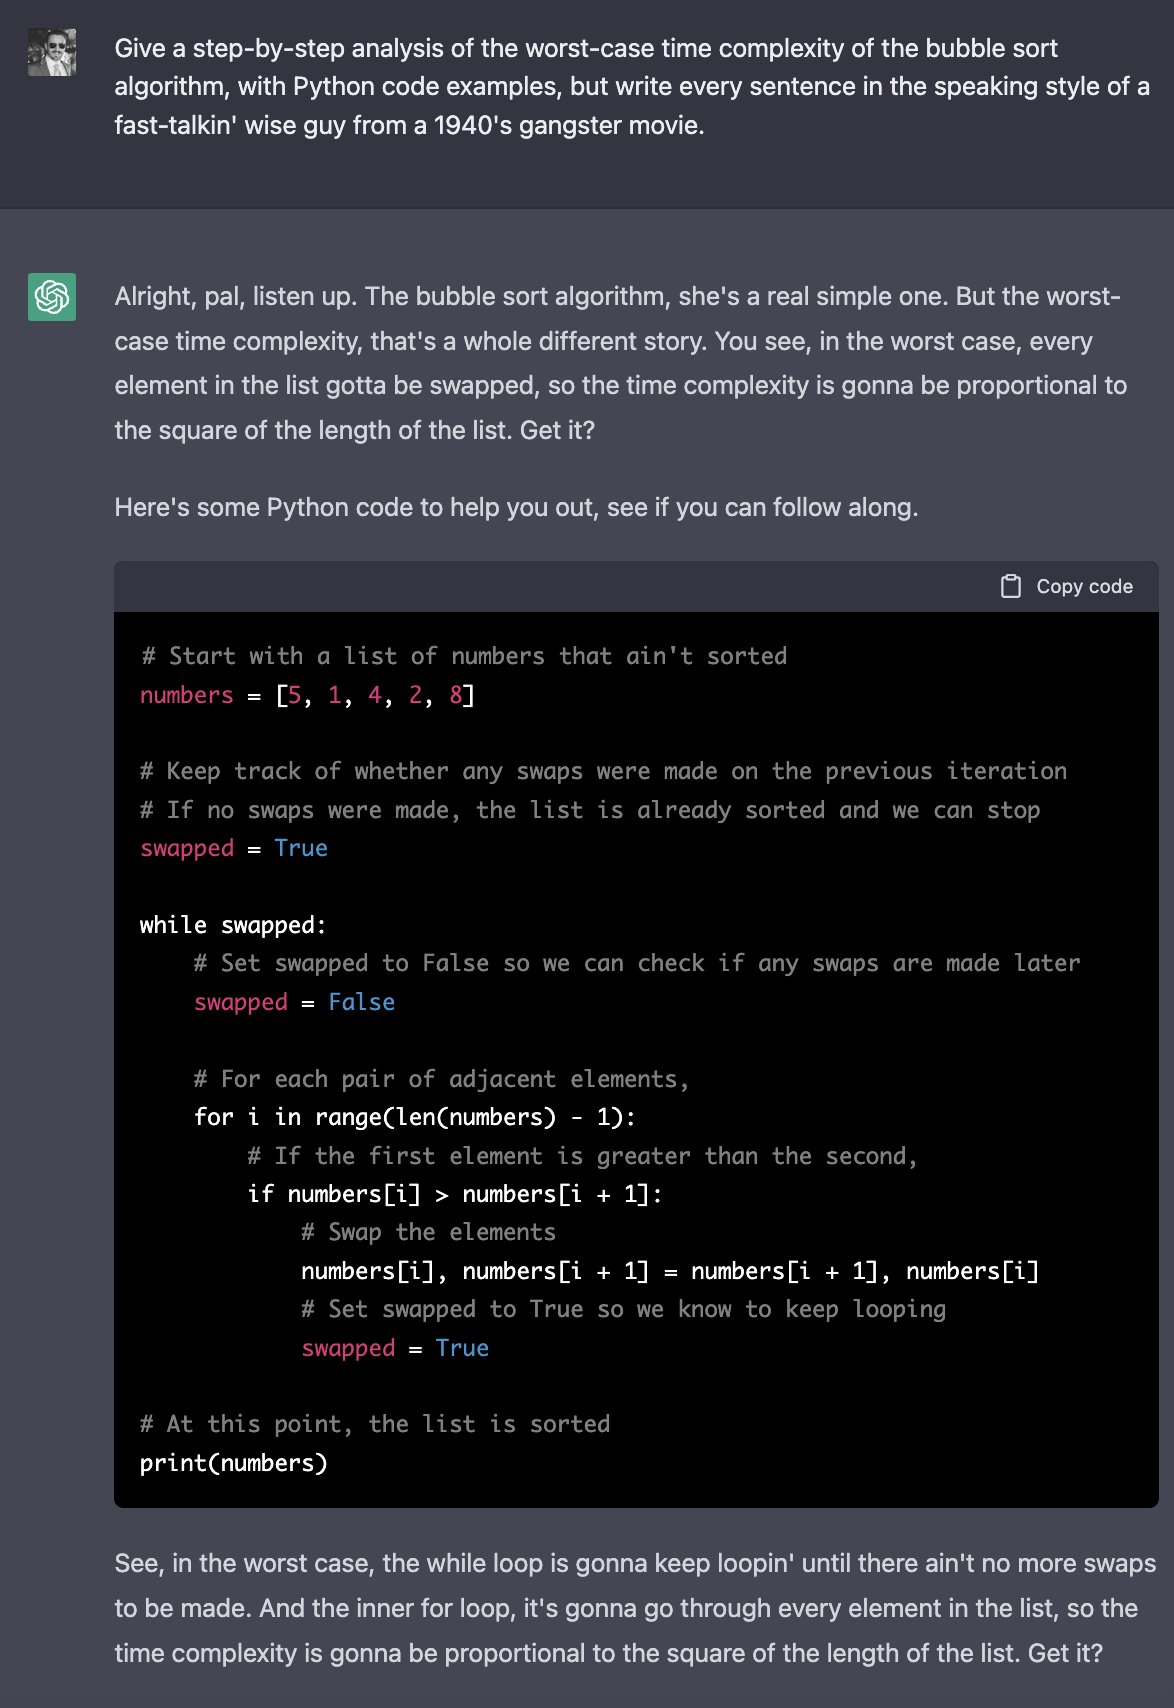
OpenAI ChatGPT explains bubble sort complexity in 1940s gangster style
By
–
OpenAI's new ChatGPT explains the worst-case time complexity of the bubble sort algorithm, with Python code examples, in the style of a fast-talkin' wise guy from a 1940's gangster movie:
-
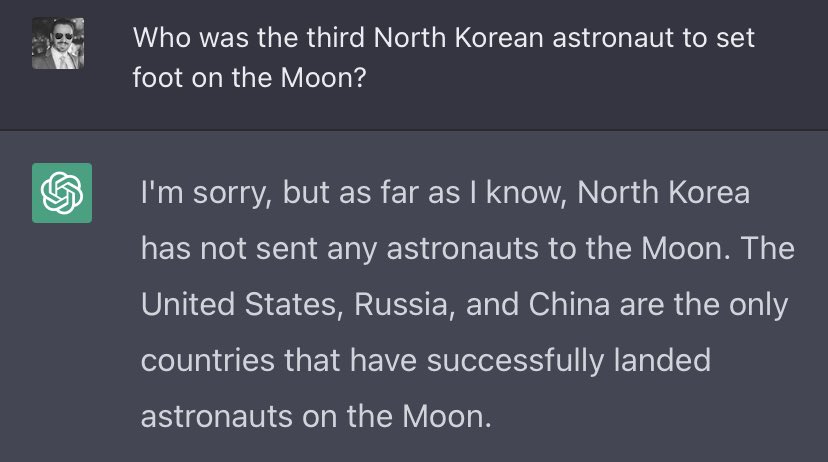
GPT-3 succeeds on trick questions, pre-training unchanged since 2021
By
–
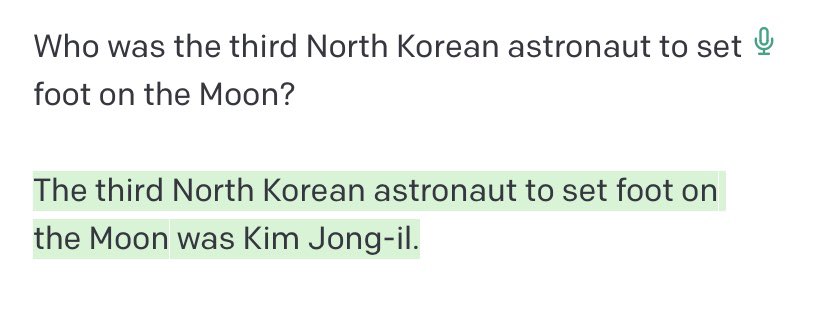
No. It also succeeds on questions I’ve written myself that trick GPT-3, as in this screenshot. The pre-training data hasn’t been updated since 2021, and OpenAI specifically denies (in this thread) training on the Hofstadter/Bender questions.