Memory design matters more than model size OdysseyBench evaluated multiple retrieval strategies: • Long-context prompting (8K+ tokens)
• RAG with raw session or utterance context
• RAG with summarization: session or chunk Chunk-level summaries outperformed all, with ~75%
LLMS
-
Memory design and retrieval strategies in AI models
By
–
-
Challenges with File Formats in AI Agent Workflows
By
–
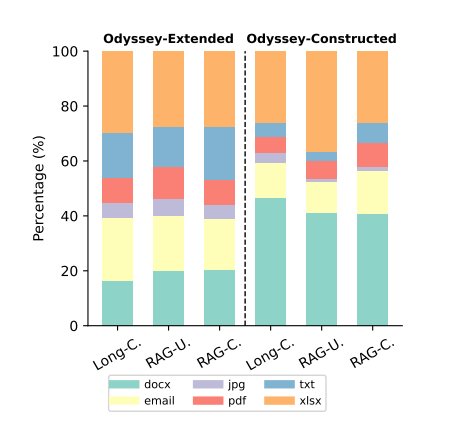
File formats that cause the most breakage? DOCX and XLSX Why? • Multi-step creation workflows
• Fragile API sequences
• Confusing dependencies across tools
• Easy to hallucinate filenames or paths -
Top 4 Failure Modes in AI Agent Execution
By
–
Top 4 Failure Modes: 1. Missing files – agent forgets to locate or read required inputs
2. Missing actions – agent skips subtasks (e.g., doesn’t write output)
3. Incorrect tool use – uses wrong app or API for the goal
4. Poor planning – jumps to execution before -
Comparative Performance Analysis of LLMs Across Task Complexity
By
–
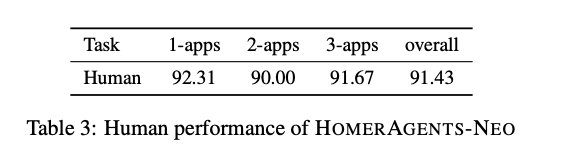
How do models perform? Human: 91%+
GPT-5: ~54%
GPT-4.1: ~36%
GPT-4o: ~52%
DeepSeek-R1: ~55% And here’s the kicker: 3-app tasks cause up to 3x degradation vs single-app tasks across all models. -
OdysseyBench Evaluates Core AI Agentic Competencies
By
–
OdysseyBench tests true agentic competence: • Contextual recall (across ~5K tokens)
• Multi-step reasoning
• Cross-app state tracking
• Intent inference through casual, noisy dialogue
• Tool execution (simulated, but grounded) It’s not toy data. It’s full workflow -

OdysseyBench and HOMERAGENTS: A Multi-Agent Generation Pipeline
By
–
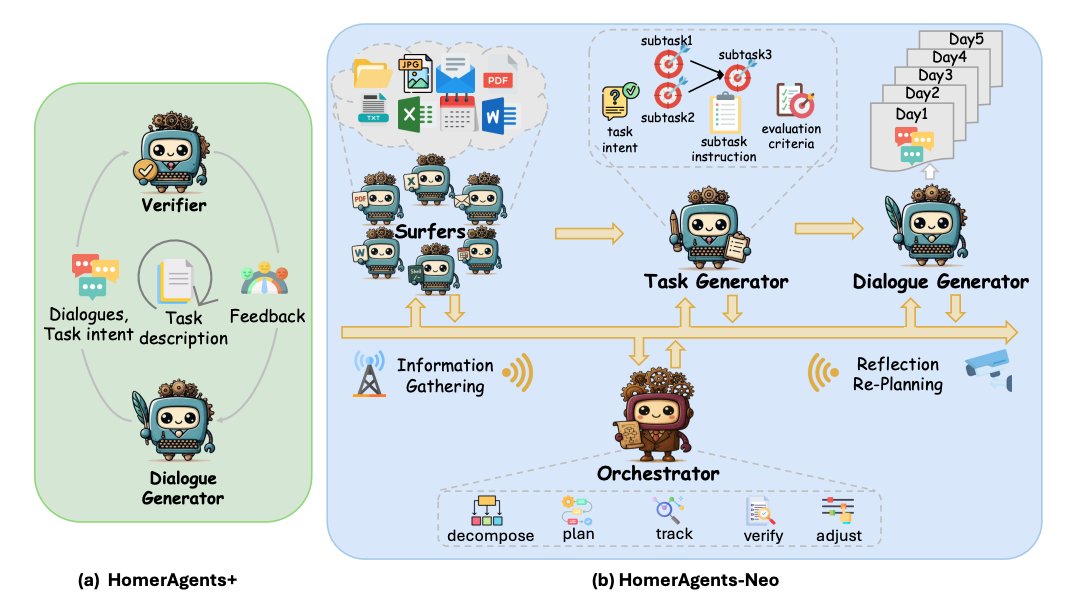
OdysseyBench is built using HOMERAGENTS, a multi-agent generation pipeline: • HOMERAGENTS+: Converts atomic tasks into multi-turn workflows • HOMERAGENTS-NEO: Synthesizes entirely new tasks using simulated app exploration Each task is: • Goal-driven
• Dialogue-based
• -
OdysseyBench: A New Benchmark for Long-Horizon AI Agent Tasks
By
–
What is OdysseyBench? A long-horizon benchmark of 602 multi-day, multi-application tasks: • Word, Excel, PDF, Email, Calendar
• 300 tasks from OfficeBench (restructured)
• 302 brand-new, complex tasks Each task is wrapped in realistic user–assistant dialogue over 5 days. -
OdysseyBench Introduced to Evaluate Long-Running AI Agent Capabilities
By
–
Today’s agents are “good” at: • Summarizing one doc
• Responding to one email
• Updating one file But in the real world? Tasks last 5 days, jump between apps, involve partial context, and require real memory. That’s what OdysseyBench simulates. -
OdysseyBench evaluates the real-world performance of LLM agents
By
–
This benchmark might kill your belief that LLM agents are “almost there.” OdysseyBench doesn’t test if an agent can summarize a file. It tests if it can survive a week at your office. And it exposes a brutal truth about today’s agents. Here’s what you need to know:
-
AI Model Explosion: New Releases From OpenAI Google Anthropic Grok
By
–
Choses qui n’existaient pas il y a un mois : – GPT-5
– GPT-5 mini
– GPT-5 nano
– GPT-OSS-120b
– GPT-OSS-20b
– Claude Opus 4.1
– Claude Sonnet 4.1
– Génie 3
– Google Deepthink advanced
– Google Gemma 270M
– Google Story book
– ChatGPT Agent
– Grok-4
– Grok Imagine
– Grok