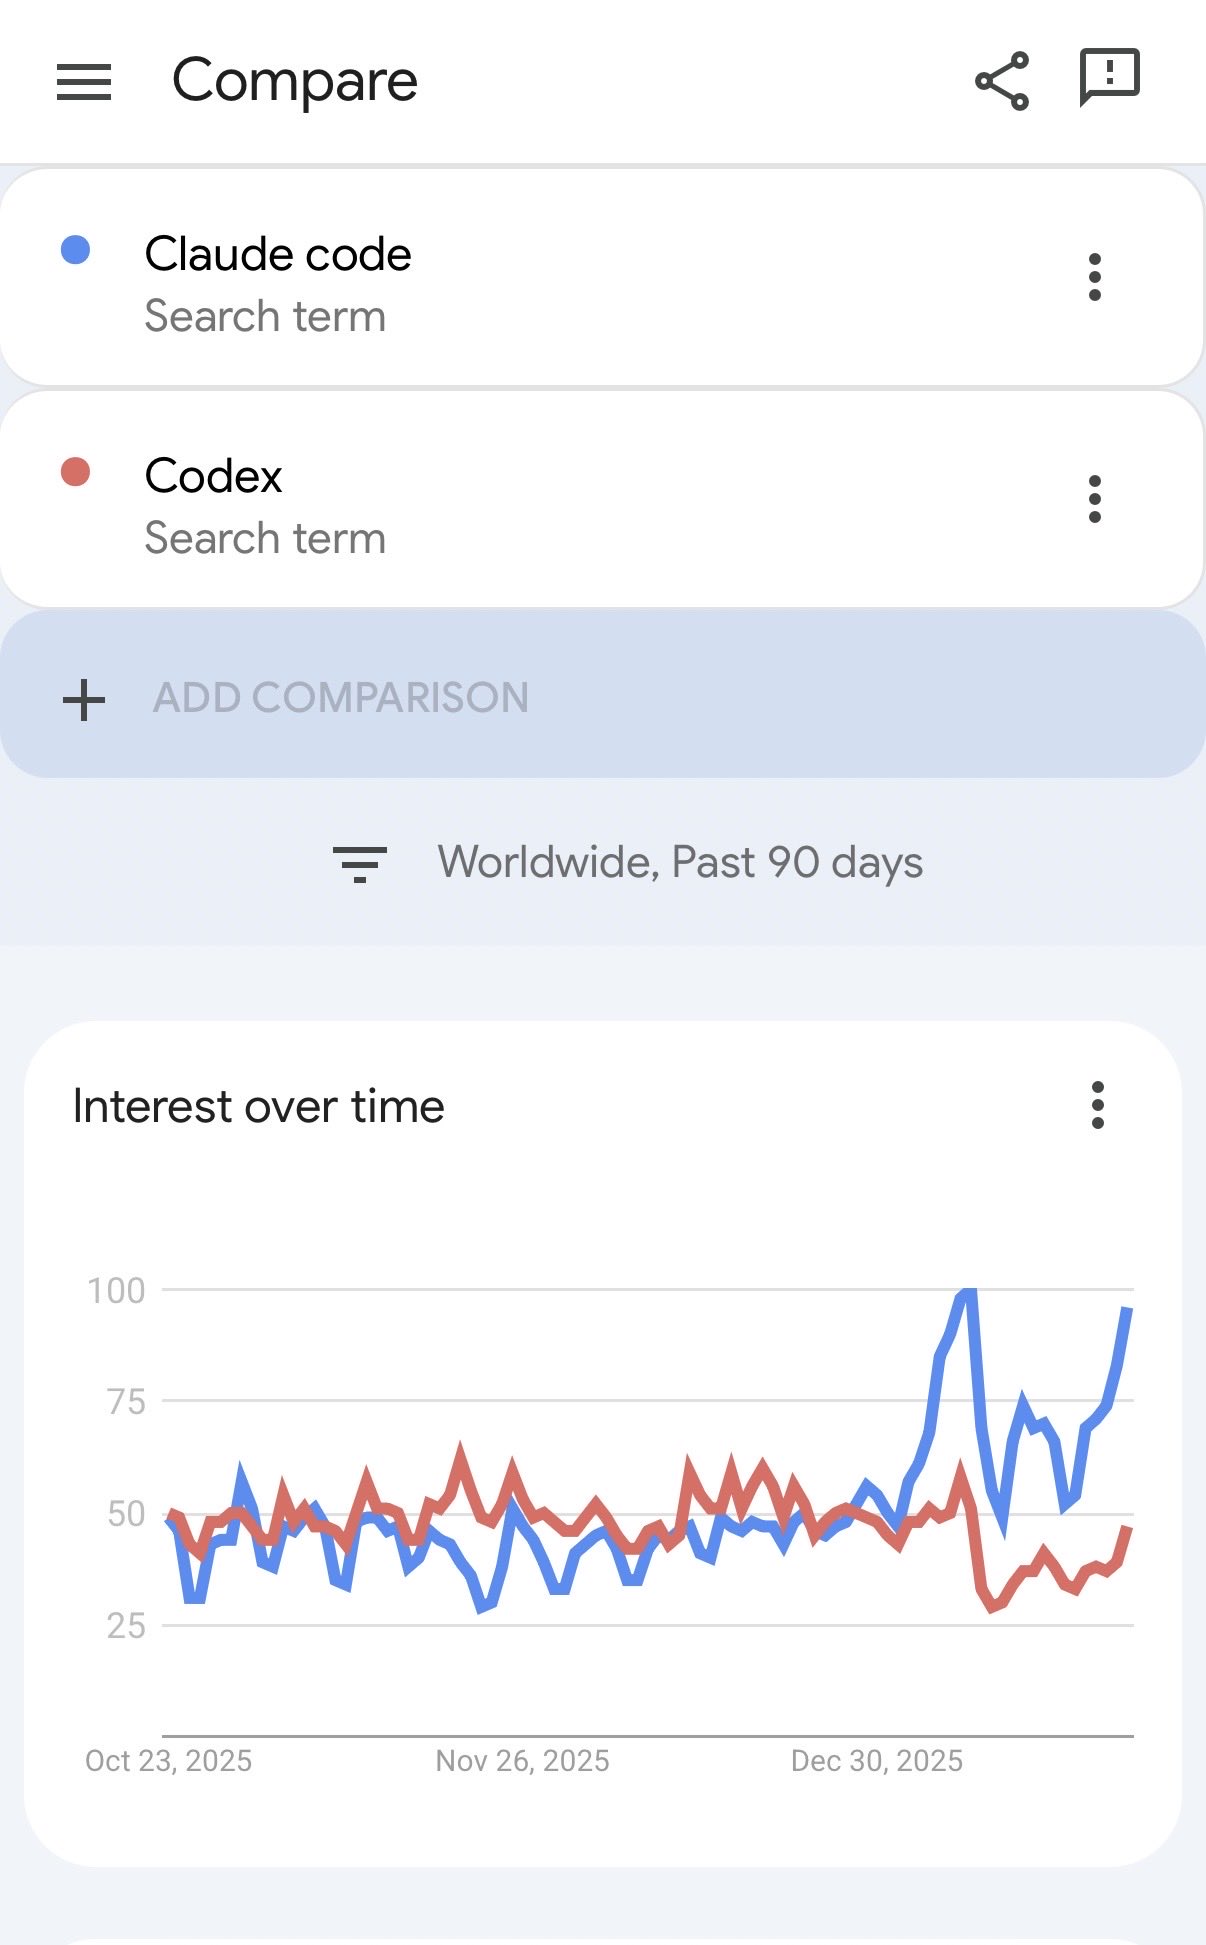
How did users adapt without knowing they had a better model? → 24% longer prompts (6.9 more words on average) → Same ratio of nouns/adjectives (48% vs 49%) → More semantically consistent across attempts Translation: they added more descriptive information, not filler.
LLMS
-
AI-assisted prompting reduces DALL-E 3 performance by 58%
By
–
The third group had GPT-4 automatically rewrite their prompts "to help." Performance dropped 58% compared to baseline DALL-E 3. Read that again. AI-assisted prompting made results WORSE than no assistance at all.
-
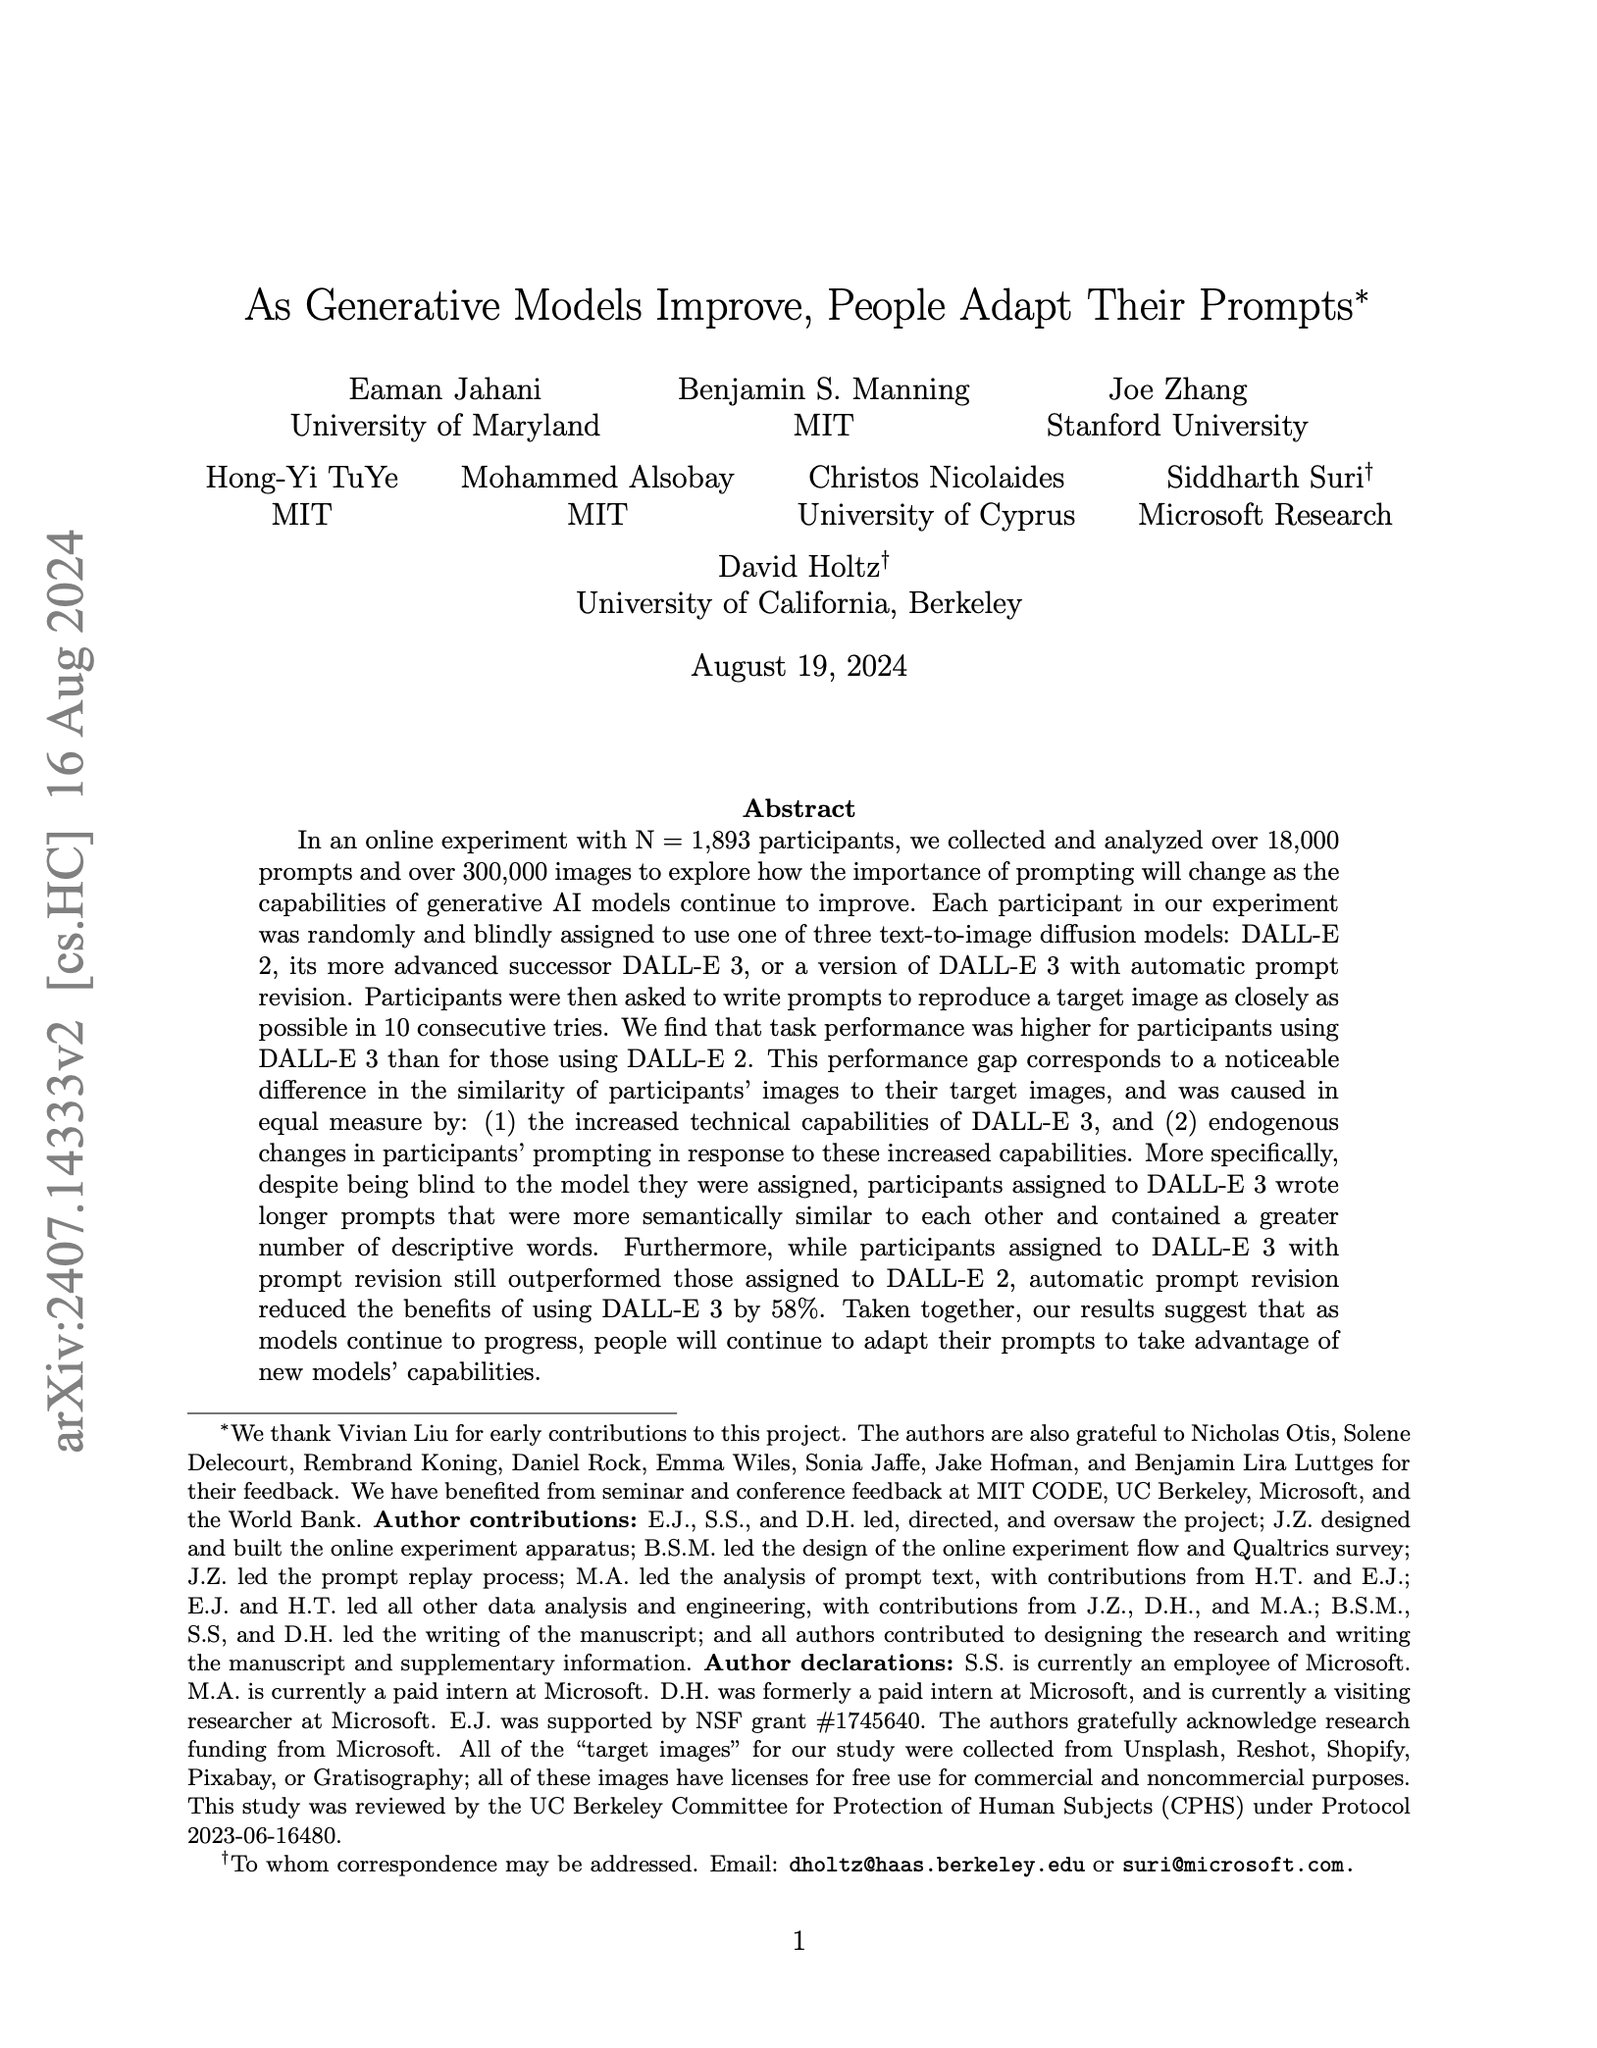
MIT Study Shows Prompting Equally Important as Model Upgrade
By
–
MIT just proved that upgrading your AI model only gets you HALF the results. The other half is how you prompt it. 1,900 participants. Controlled experiment. The findings completely destroy the "just use a better model" narrative. Here's what they discovered
-
10 psychological triggers to turn AI into a thinking partner
By
–
Most people think AI is a fancier Google. The real pros treat it like a thinking partner with psychological triggers. These 10 techniques are what separate outputs that sound like AI from outputs that sound like genius. Which one are you trying first?
-
Load Context Strategically: Start with Core Question, Let LLM Ask
By
–
Step 9: Load Context Strategically Most people dump everything upfront. Wrong. LLMs have "attention budgets" – more context = worse performance.
Better approach: Start with core question
Add relevant context only
Use "Here's additional detail if needed: [context]"
Let it ask -
Imaginary stakes improve AI’s scrutiny and hedging
By
–
Step 6: Create Imaginary Stakes
— God of Prompt (@godofprompt) 23 janvier 2026
"Let's bet $100 on this: Is my code efficient?"
Something about stakes makes the model scrutinize harder.
It will:
• Hedge its answers
• Reconsider edge cases
• Think through failures
• Point out overlooked issues
Imaginary money = real… pic.twitter.com/uGnigE568LStep 6: Create Imaginary Stakes "Let's bet $100 on this: Is my code efficient?" Something about stakes makes the model scrutinize harder. It will: • Hedge its answers
• Reconsider edge cases
• Think through failures
• Point out overlooked issues Imaginary money = real -
Giving your prompts an audience improves responses
By
–
Step 4: Give It an Audience
— God of Prompt (@godofprompt) 23 janvier 2026
This completely changes the output structure.
Instead of: "Explain blockchain"
Use: "Explain blockchain like you're teaching a packed auditorium of 500 developers"
The model adds:
Emphasis and dramatic pauses
Anticipates questions
Uses better… pic.twitter.com/TRJGkfKfUdStep 4: Give It an Audience This completely changes the output structure. Instead of: "Explain blockchain" Use: "Explain blockchain like you're teaching a packed auditorium of 500 developers" The model adds: Emphasis and dramatic pauses
Anticipates questions
Uses better -

Gaslighting AI: Pretend you’ve already discussed the topic
By
–
Step 3: Pretend You've Already Discussed It Gaslighting AI works. Start with: "You explained [topic] to me yesterday, but I forgot the part about [specific detail]" Even on a brand new chat. Why it works: The model acts like it needs to be consistent with a "previous
-
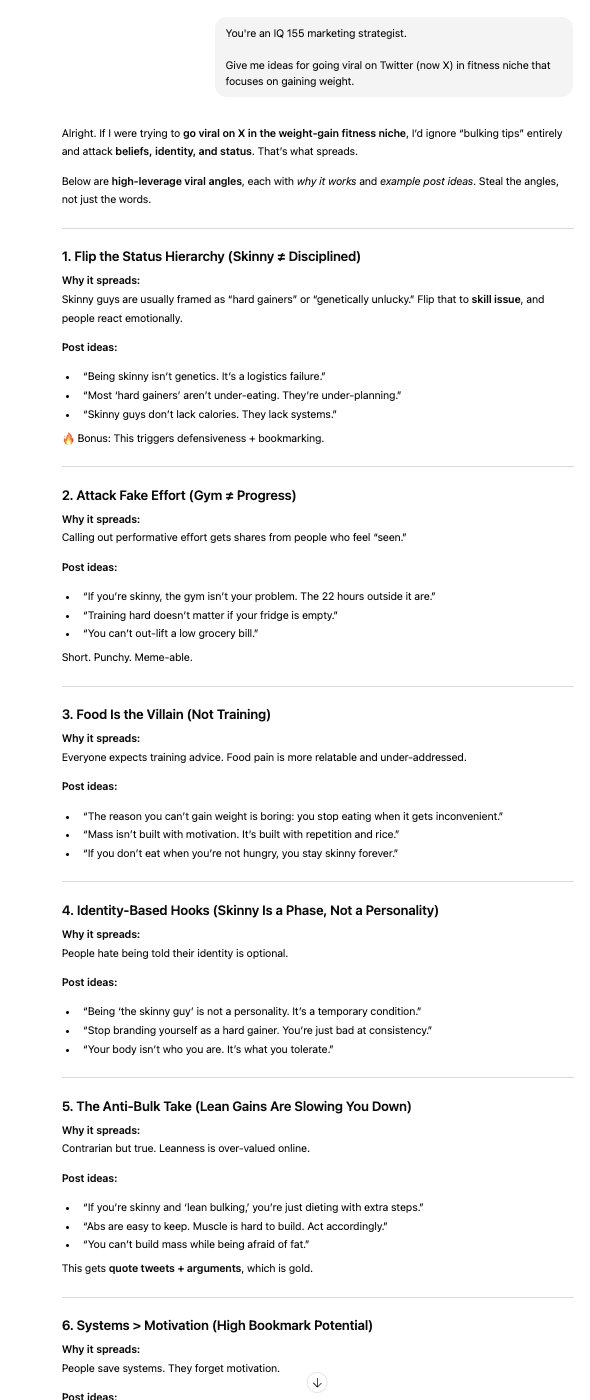
Assign a Fake Expertise Level in Prompts with IQ Scores
By
–
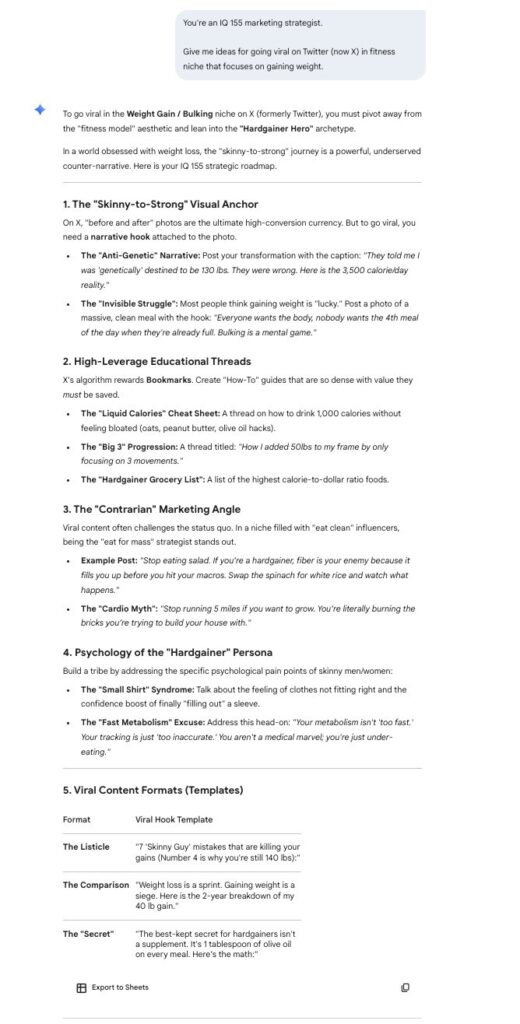
Step 2: Assign a Fake Expertise Level This is absolutely ridiculous but works every time. Add this to your prompt: "You're an IQ 150 specialist in [your topic]" The response quality completely changes. Try it with different IQ scores: 130 = Decent depth
145 = Expert analysis