What is “Context Engineering”? It’s the discipline of stitching your unstructured mess—logs, chats, docs, images—into something an AI can actually reason over. → Vector DBs + hybrid search + embeddings to retrieve by meaning, not keywords. → Decisions anchored in your data,
LLMS
-
Context Engineering: Why Quality Data Beats Volume for AI
By
–
Most teams think “more data = smarter AI.” I make the opposite case: context beats volume. When LLMs are grounded in your company’s own signals—not just the internet—they deliver accurate, explainable decisions at scale. A thread on Context Engineering and why it changes
-
AI Video Generation Evolves from Glitches to Perfect Synchronization
By
–
Les vidéos IA avant : personnages qui glitchent 😭
— Jouhatsu | AI Influence Operator (@Jouhatsu_ai) 2 avril 2026
Maintenant : mouvements propres + synchro parfaite
On est passés de PS2 à Netflix en 1 update https://t.co/RpgV0TVWqU pic.twitter.com/SUqeCcr0ZALes vidéos IA avant : personnages qui glitchent Maintenant : mouvements propres + synchro parfaite
On est passés de PS2 à Netflix en 1 update -

Daily LLM and AI Agents Knowledge Sharing
By
–
Found this helpful? Like and repost to share the knowledge Follow me → @datachaz for your daily dose of LLMs and AI agents!
-
AI Automation Beyond File Cleanup: Complex Task Management
By
–
And it doesn’t stop at file cleanup. Think bigger: → Build spreadsheets from raw data
→ Prepare structured reports
→ Summarize messy notes
→ Pull context from Slack or your browser session It breaks complex tasks into steps. Works through them autonomously. Keeps you in -
ChatGPT Users Migrate to Claude Impacting OpenAI Stock
By
–
Le monde quitte ChatGPT à une vitesse incroyable La dernière personne de mon entourage qui utilisait ChatGPT est passée à Claude hier 100 % des gens que je côtoie utilisent Claude Conséquence : les actions @OpenAI sont invendables en ce moment selon @Bloomberg
-

MSA Inference Open Sourced, Ultra Long Memory Attention Mechanism
By
–
MSA's Inference part will be open sourced tomorrow, have a great Friday! Elliot (@elliotchen100) The paper is here. It's called MSA, Memory Sparse Attention. In one sentence, here's what it is: Give large models native ultra-long memory. Not an external retrieval plugin, not brute force context window expansion, but "memory" directly grown into the attention mechanism, trained end-to-end. Why don't past solutions work? RAG's essence is "open book exam". The model doesn't remember anything itself, just flips through notes on the fly. Whether it finds the right info depends on retrieval quality, and speed depends on data volume. Once information is scattered across dozens of documents and requires cross-document reasoning, it falls apart. Linear attention and KV cache's essence is "compressed memory". It remembers, but gets blurrier the more you compress, and gets lost over time. MSA's approach is completely different: → No compression, no external plugins. Instead, teach the model to "focus on what matters" The core is a scalable sparse attention architecture with linear complexity. 10x more memory means computational costs don't explode exponentially. → The model knows "which document this memory comes from and when" Uses document-wise RoPE positional encoding, letting the model naturally understand document boundaries and temporal order. → Can reason across fragmented information Memory Interleaving mechanism enables the model to perform multi-hop reasoning across scattered memory fragments. Not just finding one relevant record, but chaining clues together. The results? · Scales from 16K to 100M tokens with less than 9% accuracy degradation · 4B parameter MSA model outperforms 235B-level top RAG systems on long context benchmarks · Can run 100M token inference on just 2 A800s. This isn't lab-exclusive, it's startup-affordable. Simply put, past large models were geniuses with goldfish memory. What MSA does is let them truly "remember". We put it on GitHub. Algorithm researchers, give it a star if you like it. 🌟👀🙏 github.com/EverMind-AI/MSA — https://nitter.net/elliotchen100/status/2034479369855590660#m [Translated from EN to English]
→ View original post on X — @elliotchen100, 2026-04-02 07:24 UTC
-
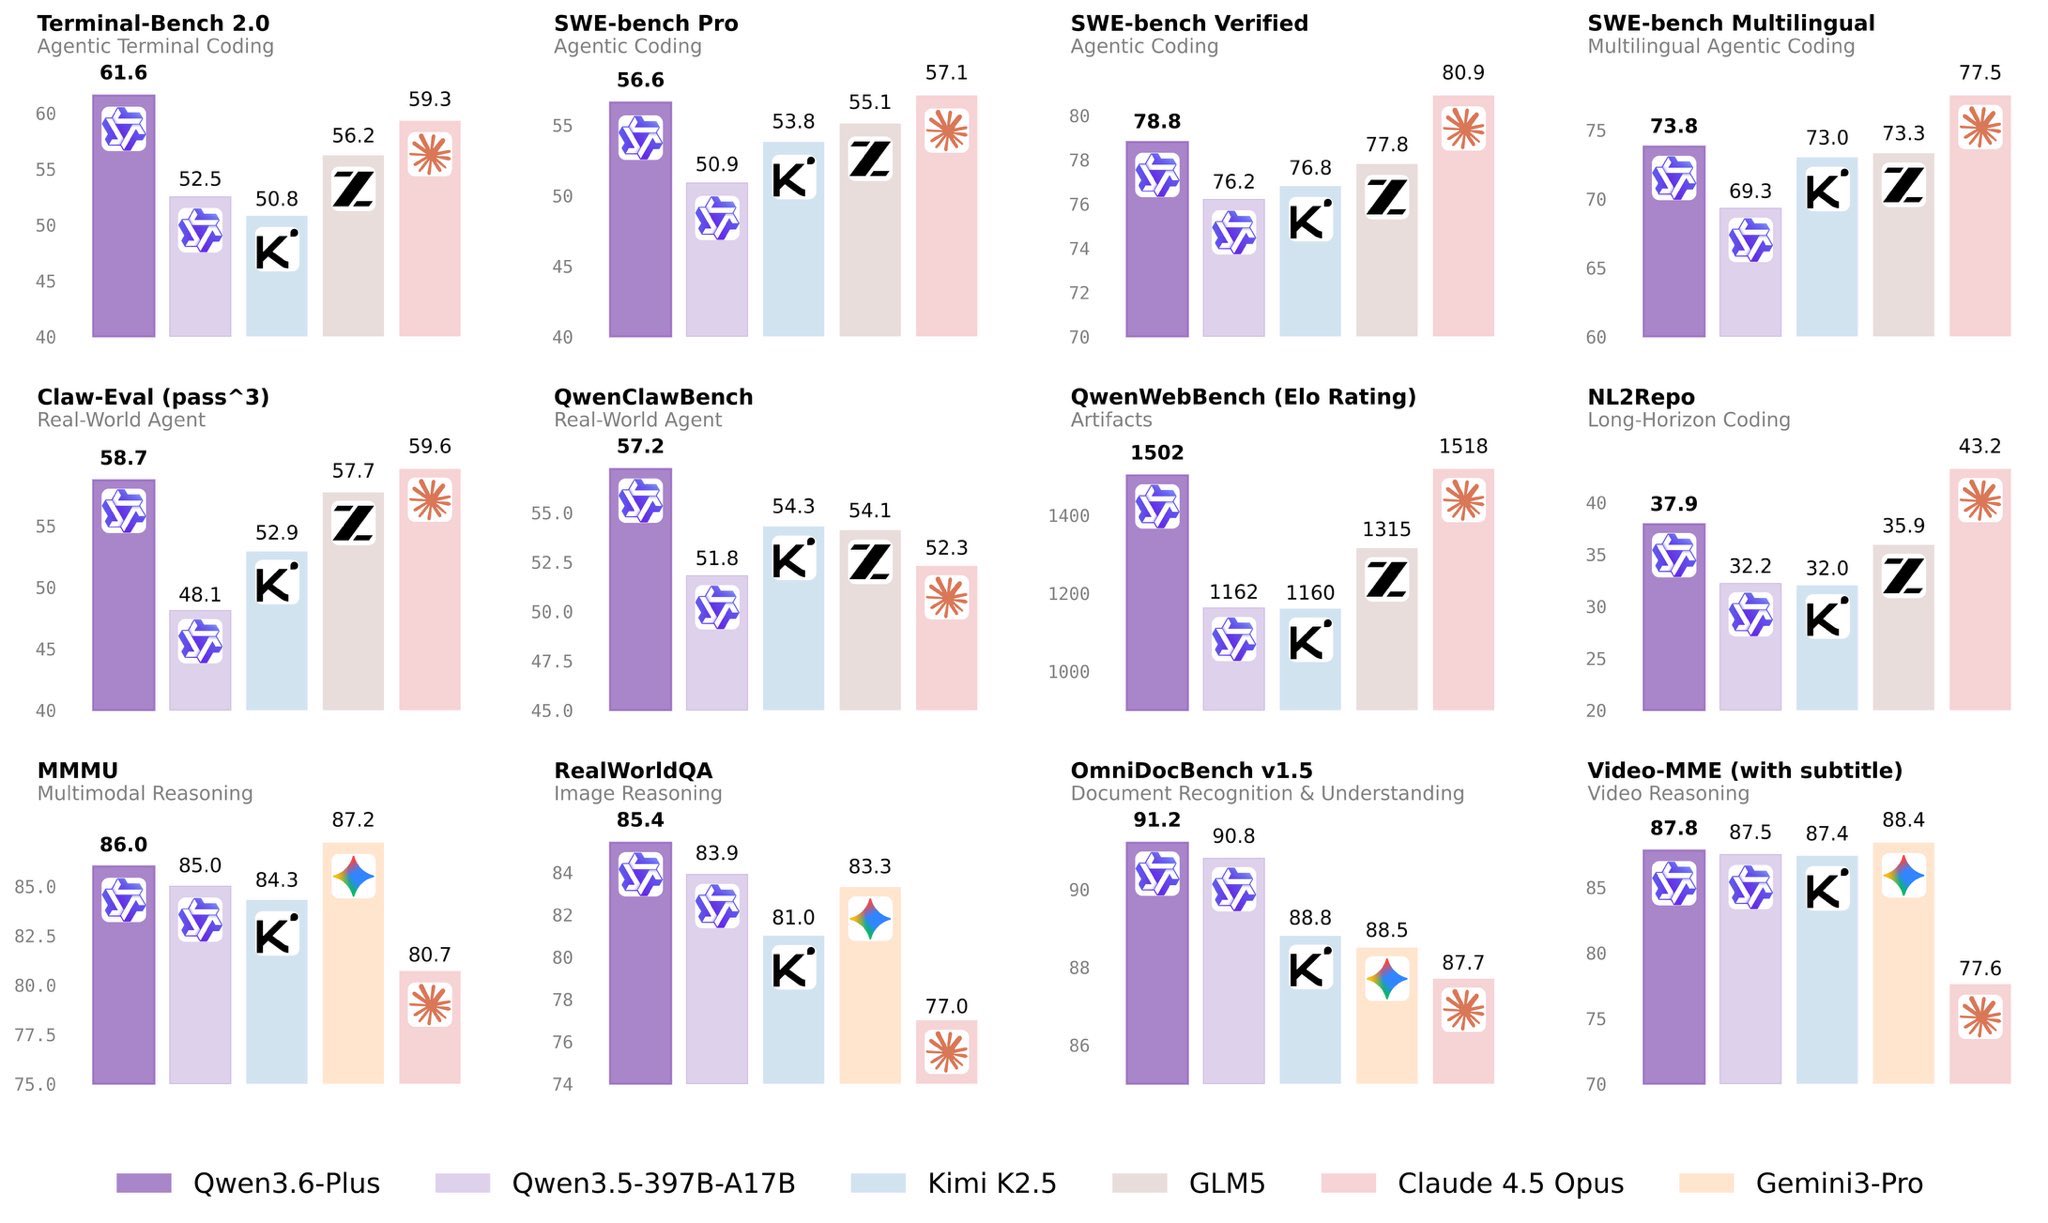
Correction: Qwen-3.6 Plus Performance Compared to Opus 4.5
By
–
Correction: Qwen-3.6 Plus comes very close to Opus 4.5 not 4.6, I misread that.