who trains llama 70B these days though. too much of a toy workload
LLMS
-
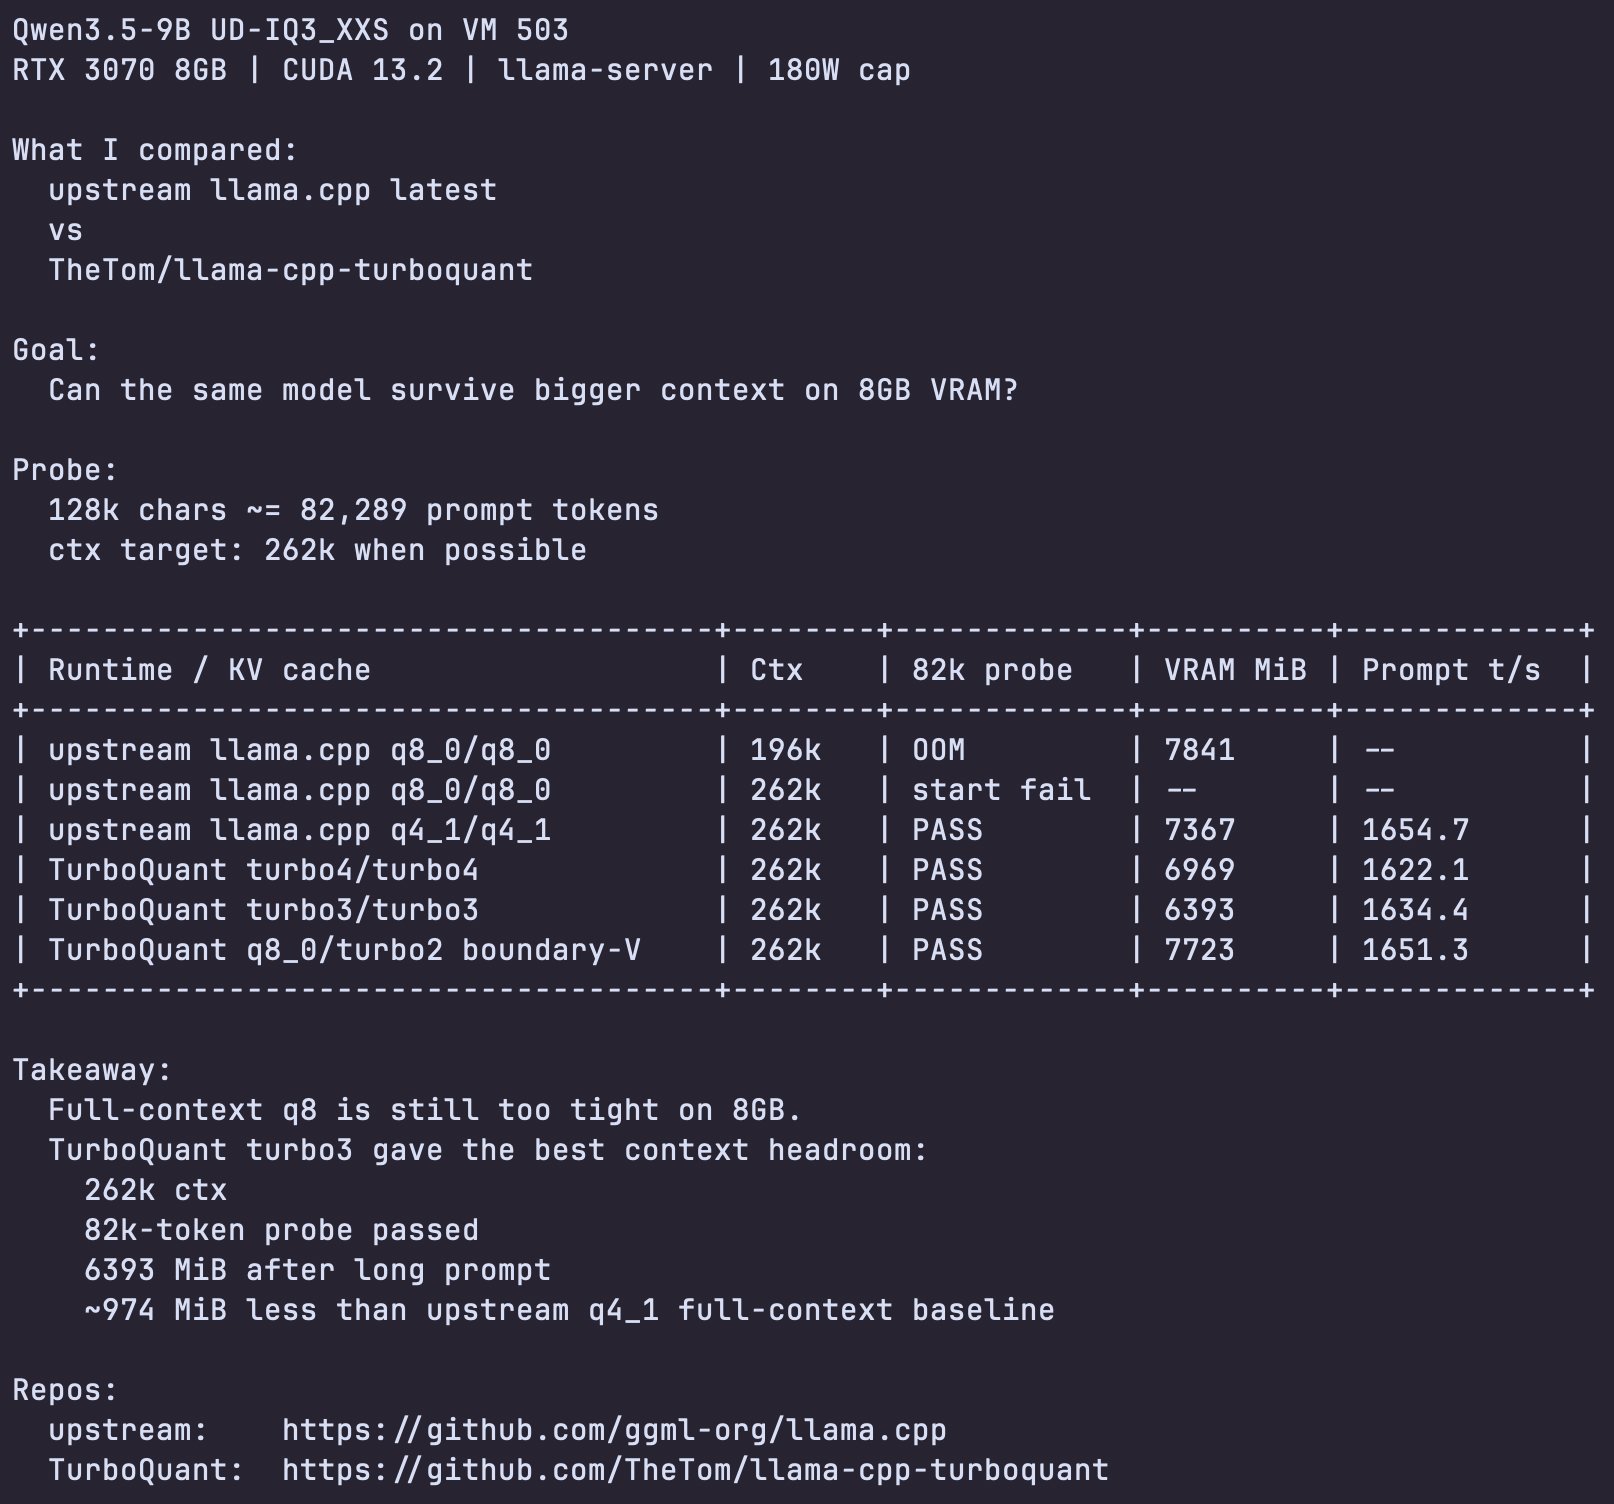
Qwen3.5 9B benchmarked: TurboQuant avoids OOM at full context
By
–
Benchmarked the same Qwen3.5 9B UD-IQ3_XXS GGUF on an RTX 3070 8GB using – Latest upstream llama.cpp VS – TheTom's TurboQuant llama.cpp fork TurboQuant allowed me to reach full context length without OOM, more in the screenshot below
-
Grok AI receives criticism for low quality outputs
By
–
grok is great for those who don't care what they get
-
OpenAI leads reasoning capabilities, DeepSeek close behind
By
–
I feel like OpenAI is the only lab that really nailed reasoning. DeepSeek was probably the closest, but need to see a frontier model from them to be sure. Gemini's reasoning was quite weird and all over the place. Claude's reasoning never used to matter (non thinking were
-
NVIDIA Vera Rubin outperforms Mac Mini for Hermes model
By
–
It is an NVIDIA Vera Rubin. Can run Hermes better than a Mac Mini. Like thousands of times faster. 🙂
-

Master Any LLM: Comprehensive Guide to Large Language Models
By
–
Master Any #LLM
by @ingliguori #GenerativeAI #ArtificialIntelligence #MachineLearning #MI -
Make No Mistakes: Key Prompt Engineering Strategy
By
–
"make no mistakes" was the key prompt here tbh.
-
Pi Uses Codex App Server OpenAI Completions Endpoint
By
–
Pi uses Codex App Server, I believe. By "regular" I mean the OpenAI completions REST endpoint.
-
Grok 4.4 and 4.5 Release Timeline Announced
By
–
Supplemental training has been added to 4.3. Grok 4.4 will be twice the size (1T) with training data through early April. Probably ready for release in early May. Grok 4.5 will be 1.5T and hopefully out by late May.