[AINews] DeepSeek V4 Pro (1.6T-A49B) and Flash (284B-A13B), Base and Instruct — runnable on Huawei Ascend chips
LLMS
-

GPT-5.5 XHIGH optimizes DeepSeek 4 Flash on 4x DGX Sparks
By
–

GPT-5.5 XHIGH is working hard right now to make vLLM runs DeepSeek 4 Flash on 4x DGX Sparks It got it to load, then had it answer cohesively on the 4x Sparks (though a tad too slow) Now, it optimizes it Letting this run overnight (in an engineered-harness specifically for it)
-

Local RAG AI Stack Overview on RTX 3070 8GB
By
–

Here is a high-level overview of my Local RAG / AI Knowledge Stack All hosted locally on a single RTX 3070 8GB btw Who is interested in a more in-depth breakdown? What would you like for it to cover?
-

GPT-5.5 Now Available in OpenAI API for Developers
By
–
GPT-5.5 is now available in the OpenAI API! The big thing for developers is that it’s not just smarter, it can get complex tasks done with fewer tokens and fewer retries. Ask Codex to migrate your Responses API integration to GPT-5.5!
-

Startups Building with Google Gemma Models at Tech Event
By
–
Thanks for inviting me @garrytan
, was awesome to chat and loved the inspirational space! Great to see so many startups building with @googlegemma models! -

GPT 5.5 Advances Character Generation Capabilities
By
–
GPT 5.5 is definitely a step up in the character game.
-
Codex Team Releases Voice Dictation, Browser Use, GPT 5.5
By
–
everything codex team shipped this week: – os wide voice dictation
– auto-review mode
– pdf, docs, tex
– sheets, slides
– browser use
– gpt 5.5 enjoy! -
ChatGPT’s cake text transcription silently fixed punctuation, author admits mistake
By
–
You're absolutely right. ChatGPT's transcription of the cake's text silently corrected missing punctuation on the three lines you noted. I'm leaving this post up as a funny demo but anyone considering citing this in serious work should know about this oversight on my part.
-
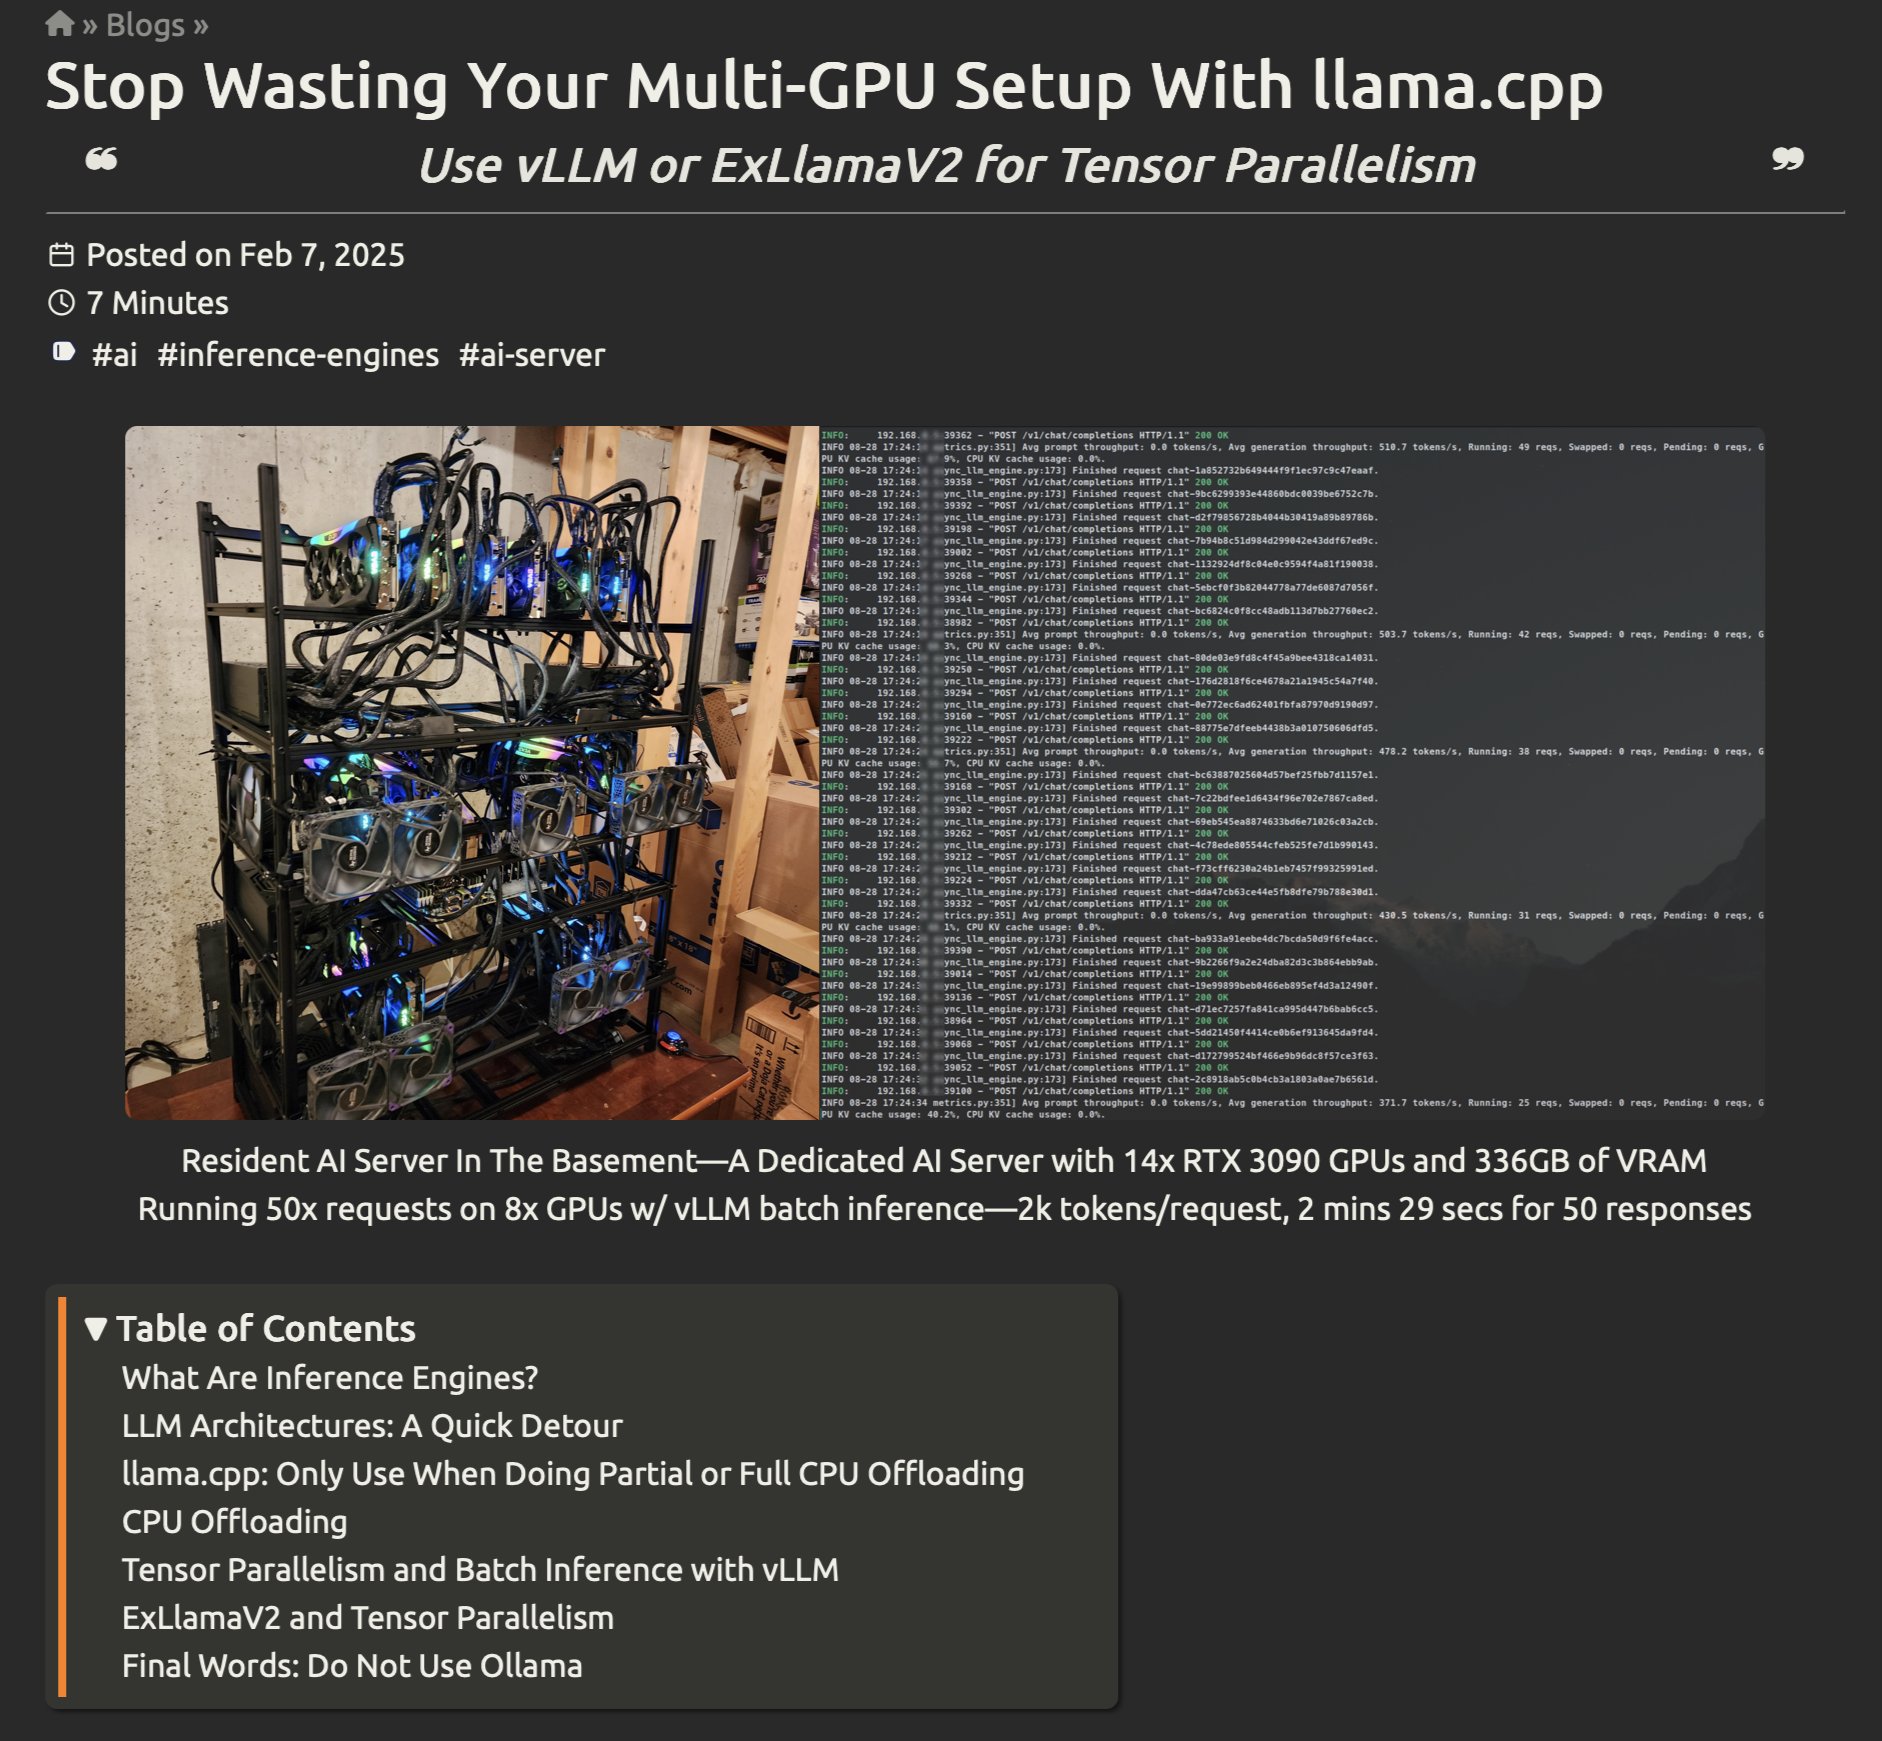
Multi-GPU LLMs slow? Use the right Inference Engine for Tensor Parallelism
By
–
I keep seeing the same thing People with multi-GPUs wondering why local LLMs have slow performance …Because you're using the wrong Inference Engine and it's processing things one GPU at a time This old writeup of mine covers Inference Engines & Tensor Parallelism, go read it
-
GPT-5.5 Now Available on Databricks with Codex Coding Workflows
By
–
.@OpenAI GPT-5.5 is now available on Databricks, with Codex coding workflows and model inference fully governed through Unity AI Gateway.
— Databricks (@databricks) 25 avril 2026
With GPT-5.5 on Databricks, you can:
– Power coding workflows with Codex or other coding agents
– Build custom agents grounded in enterprise… pic.twitter.com/EwAP7qpilP.
@OpenAI GPT-5.5 is now available on Databricks, with Codex coding workflows and model inference fully governed through Unity AI Gateway. With GPT-5.5 on Databricks, you can:
– Power coding workflows with Codex or other coding agents
– Build custom agents grounded in enterprise