10/ Know what burns the most tokens The biggest token consumers in order: long conversations, large file uploads, web search, extended thinking on every prompt, and Opus on small tasks. If you keep hitting the limit and do not know why, it is one of those five. Probably more
LLMS
-
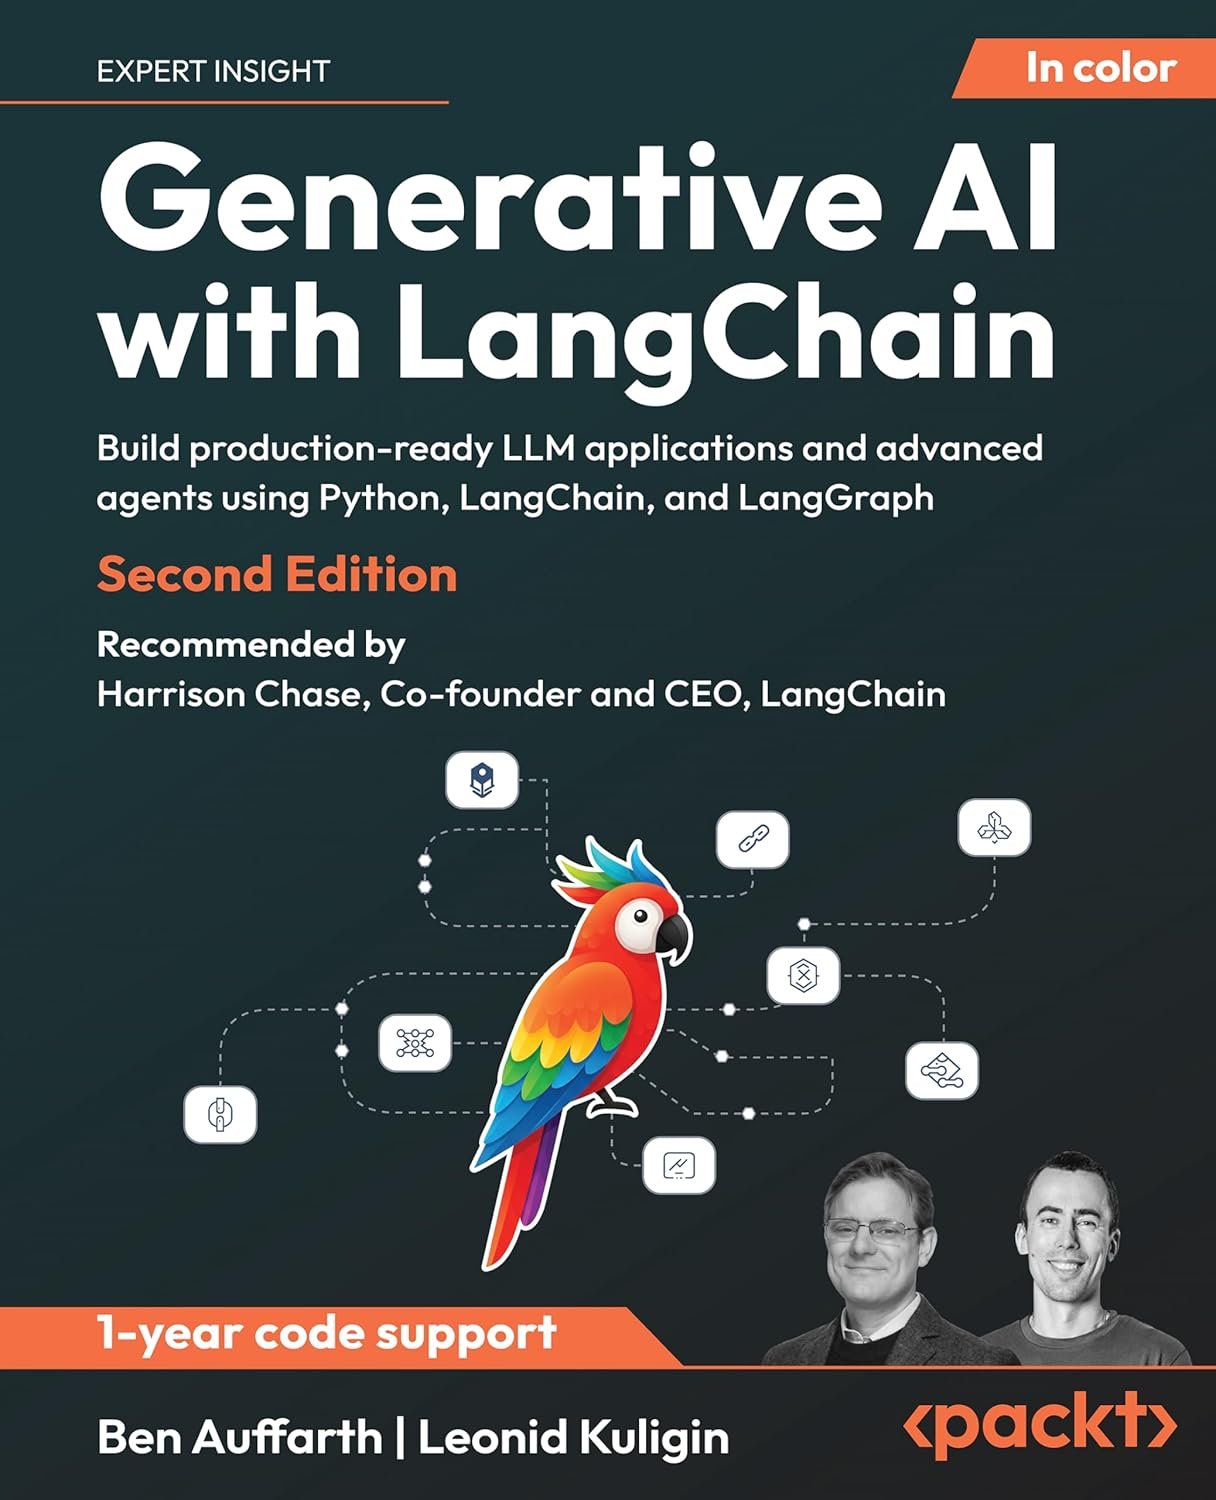
LangChain 2nd Edition: Production LLM Applications and Advanced Agents
By
–
The 2nd Edition of this book has arrived, with Agentic AI updates: "Generative AI with LangChain — Build Production-ready LLM Applications and Advanced Agents using Python and LangGraph" at https://
amzn.to/3JEeS6K v/ @PacktDataML 𝓦𝓱𝓪𝓽 𝓨𝓸𝓾 𝓦𝓲𝓵𝓵 𝓛𝓮𝓪𝓻𝓷:
Design and -
Optimize Claude Usage Within 5 Hour Rolling Window
By
–
9/ Split your work across the 5 hour window Claude uses a rolling 5 hour window. It starts the moment you send your first message and resets 5 hours later. If you burn your entire limit in one morning session, the rest of the day you are locked out until reset. Two or three
-
Claude Model Matching: Right Tool for Each Task
By
–
8/ The model match table Haiku: quick replies, grammar checks, formatting, brainstorming
Sonnet: writing, analysis, code, serious drafts, document review Opus: deep research, rigorous logic, complex multi-step problems Using Opus to fix a typo costs 5x what it should. The -

Unlocking Data with Generative AI and RAG Integration
By
–
Unlocking Data with #GenerativeAI and RAG — Enhance Generative AI systems by integrating internal data with large language models using RAG: http://
amzn.to/3PtFHdv v/ @PacktDataML -
Optimize AI Model Selection by Task Complexity and Cost
By
–
7/ Stop using Opus for Haiku tasks Opus is roughly 5x more expensive per task than Sonnet. Sonnet is more expensive than Haiku. Quick reply, formatting fix, brainstorm? Haiku.
Writing, analysis, code, real drafts? Sonnet. Deep research, complex reasoning, long document review? -
Optimize Claude: Disable Unused Features to Save Tokens
By
–
6/ Turn off features you are not using Web search, research mode, and connectors add tokens to every response even when you do not need them. If you are writing your own content or asking a knowledge question Claude already knows, turn them off. The icons are right next to the
-
Stack Questions for Better AI Responses
By
–
3/ Stack your questions into one message Three separate prompts cost three full reads of your conversation history. One prompt with three questions costs one read. The answers are usually better too because Claude sees the full goal at once. Example: "I need three things from
-

LLM and RAG Applications Guide: LangChain Python Tutorial
By
–
"Generative AI and RAG for Beginners: A Practical Step-by-Step Guide to Building LLM and RAG Applications with LangChain and Python" Get your copy at https://
amzn.to/3MZZ9R5 Independently published: December 2025
Print length: 255 pages -
Optimize Claude conversations by starting fresh every 20 messages
By
–
2/ Start a new chat every 20 messages By message 30, a single question can cost 50,000 tokens because Claude is reprocessing everything that came before it. When the chat gets long, ask Claude to summarize and continue fresh.
Prompt: "Summarize the key points of this