Looking for a competitive edge in the stock market? Dive into the world of historical stock data. Packages like @alpha_vantage & @YahooFinance provide access to a variety of financial data sources for analysis & prediction purposes. Read more:
INNOVATION
-
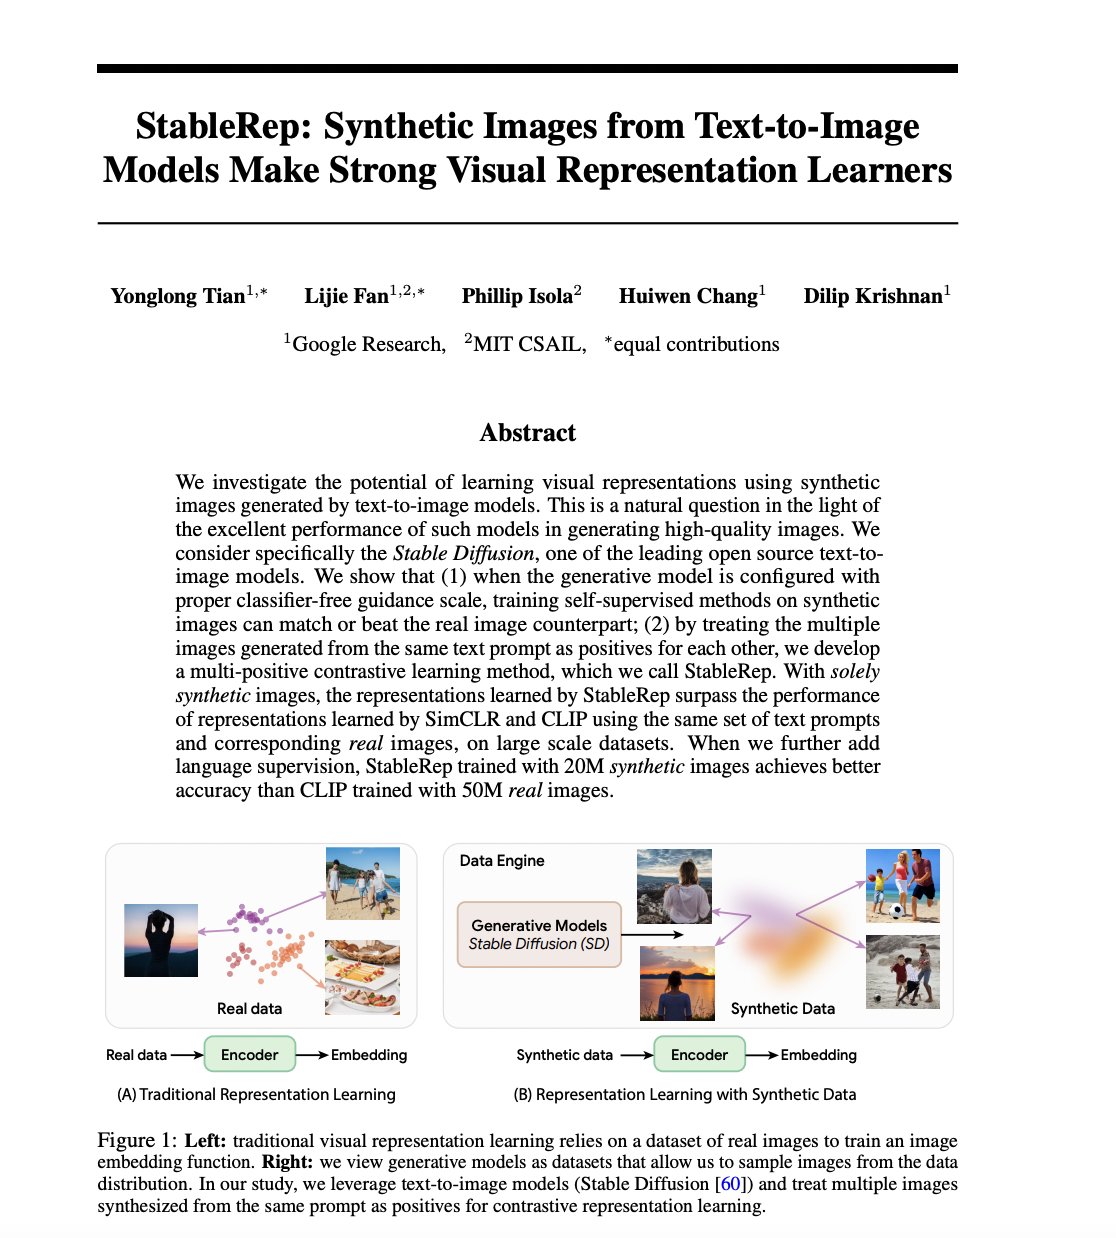
StableRep: Learning Visual Representations from Synthetic Text-to-Image Models
By
–
StableRep: Synthetic Images from Text-to-Image Models Make Strong Visual Representation Learners paper page: https://
huggingface.co/papers/2306.00
984
… We investigate the potential of learning visual representations using synthetic images generated by text-to-image models. This is a natural -
SnapFusion: Fast Text-to-Image Generation on Mobile Devices
By
–
SnapFusion: Text-to-Image Diffusion Model on Mobile Devices within Two Seconds
— AK (@_akhaliq) 2 juin 2023
paper page: https://t.co/ykIrW1u1Uo
present a generic approach that, for the first time, unlocks running text-to-image diffusion models on mobile devices in less than 2 seconds. We achieve so by… pic.twitter.com/rJjPjCjRDwSnapFusion: Text-to-Image Diffusion Model on Mobile Devices within Two Seconds paper page: https://
huggingface.co/papers/2306.00
980
… present a generic approach that, for the first time, unlocks running text-to-image diffusion models on mobile devices in less than 2 seconds. We achieve so by -
NVIDIA AI Agent Powered by GPT-4 Outperforms AutoGPT
By
–
Another article about our work https://t.co/MbeR69BbOO https://t.co/jKOkFCLG7n
— Prof. Anima Anandkumar (@AnimaAnandkumar) 2 juin 2023Another article about our work https://
gamingdeputy.com/nvidias-ai-age
nt-is-connected-to-gpt-4-outperforms-autogpt-and-writes-code-independently-to-dominate-my-world-without-human-intervention/
… -
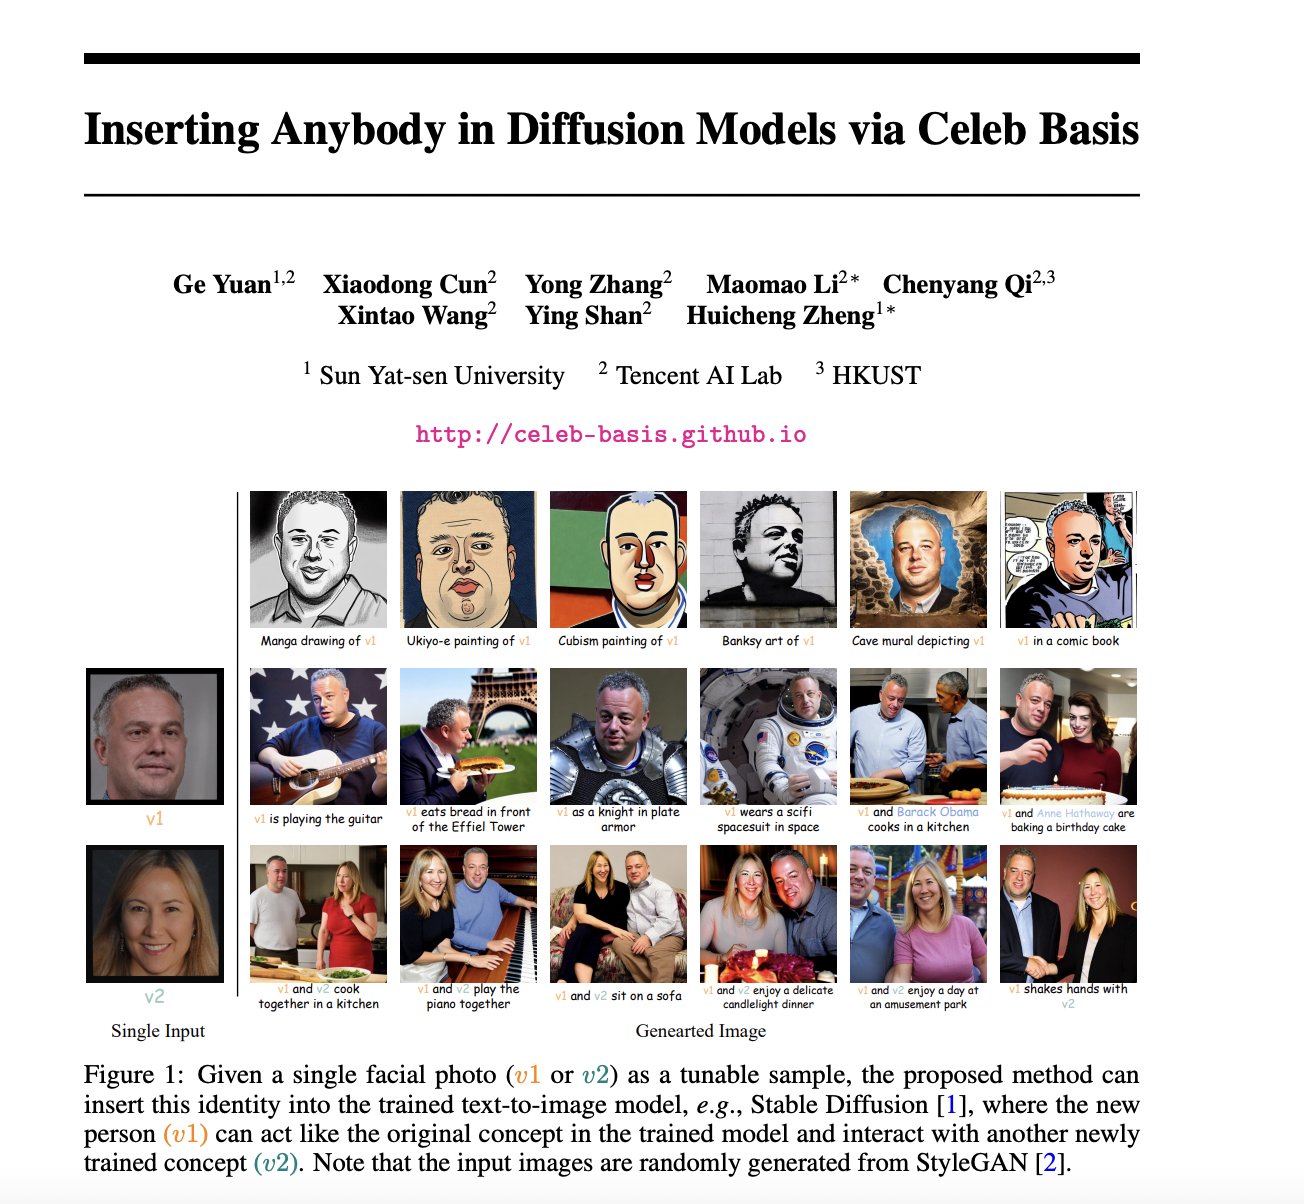
Inserting Any Person into Diffusion Models with Single Photo
By
–
Inserting Anybody in Diffusion Models via Celeb Basis paper page: https://
huggingface.co/papers/2306.00
926
… propose a new personalization method that allows for the seamless integration of a unique individual into the pre-trained diffusion model using just one facial photograph and only 1024 -
Wuerstchen: Efficient Text-to-Image Model Pretraining Technique
By
–
Wuerstchen: Efficient Pretraining of Text-to-Image Models paper page: https://
huggingface.co/papers/2306.00
637
… introduce Wuerstchen, a novel technique for text-to-image synthesis that unites competitive performance with unprecedented cost-effectiveness and ease of training on constrained -
ByteFormer: Transformers Processing Raw File Bytes for Image Classification
By
–
Bytes Are All You Need: Transformers Operating Directly On File Bytes paper page: https://
huggingface.co/papers/2306.00
238
… ByteFormer, achieves an ImageNet Top-1 classification accuracy of 77.33% when training and testing directly on TIFF file bytes using a transformer backbone with -
Connected Surgery: AI-powered surgical platform launched at APHP
By
–
Connected Surgery: an AI-based surgery platform launched by Caresyntax, Relyens and Intel. Learn more about this innovation in the operating rooms of APHP: https://actuia.com/actualite/lancement-de-connected-surgery-un-programme-associant-caresyntax-…
-
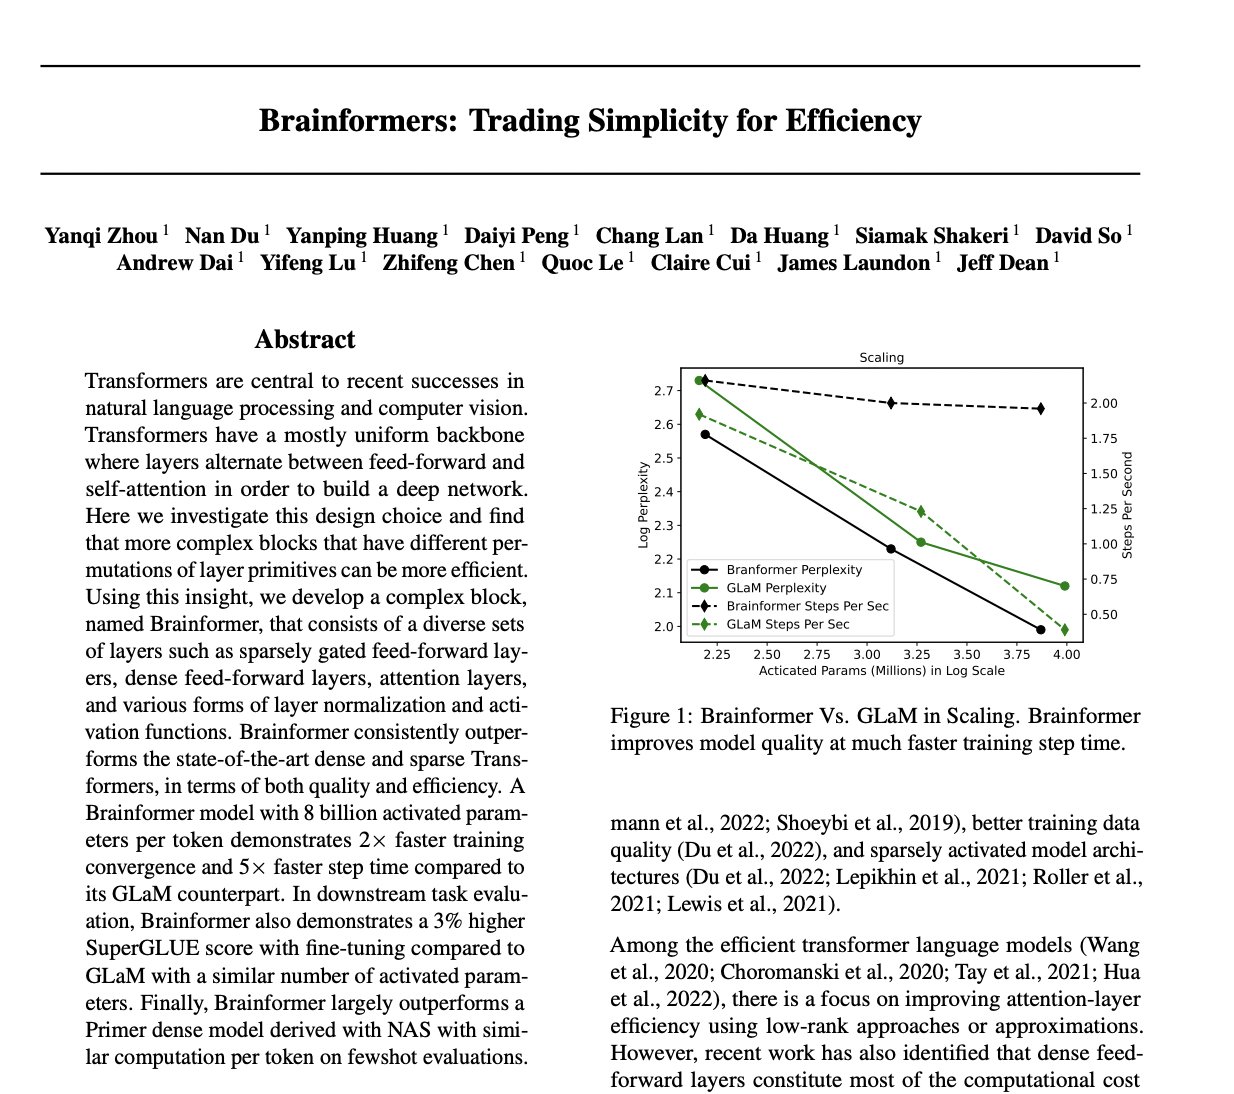
Brainformers: Trading Simplicity for Efficiency in Transformers
By
–
Brainformers: Trading Simplicity for Efficiency paper page: https://
huggingface.co/papers/2306.00
008
… develop a complex block, named Brainformer, that consists of a diverse sets of layers such as sparsely gated feed-forward layers, dense feed-forward layers, attention layers, and various forms -

Hiera: Hierarchical Vision Transformer Simplified Architecture
By
–
Hiera: A Hierarchical Vision Transformer without the Bells-and-Whistles abs: https://
arxiv.org/abs/2306.00989 Modern hierarchical vision transformers have added several vision-specific components in the pursuit of supervised classification performance. While these components lead to