What’s the weirdest application for generative AI you’ve seen thus far? (I ask knowing “weird” means different things to just about everybody.)
INNOVATION
-
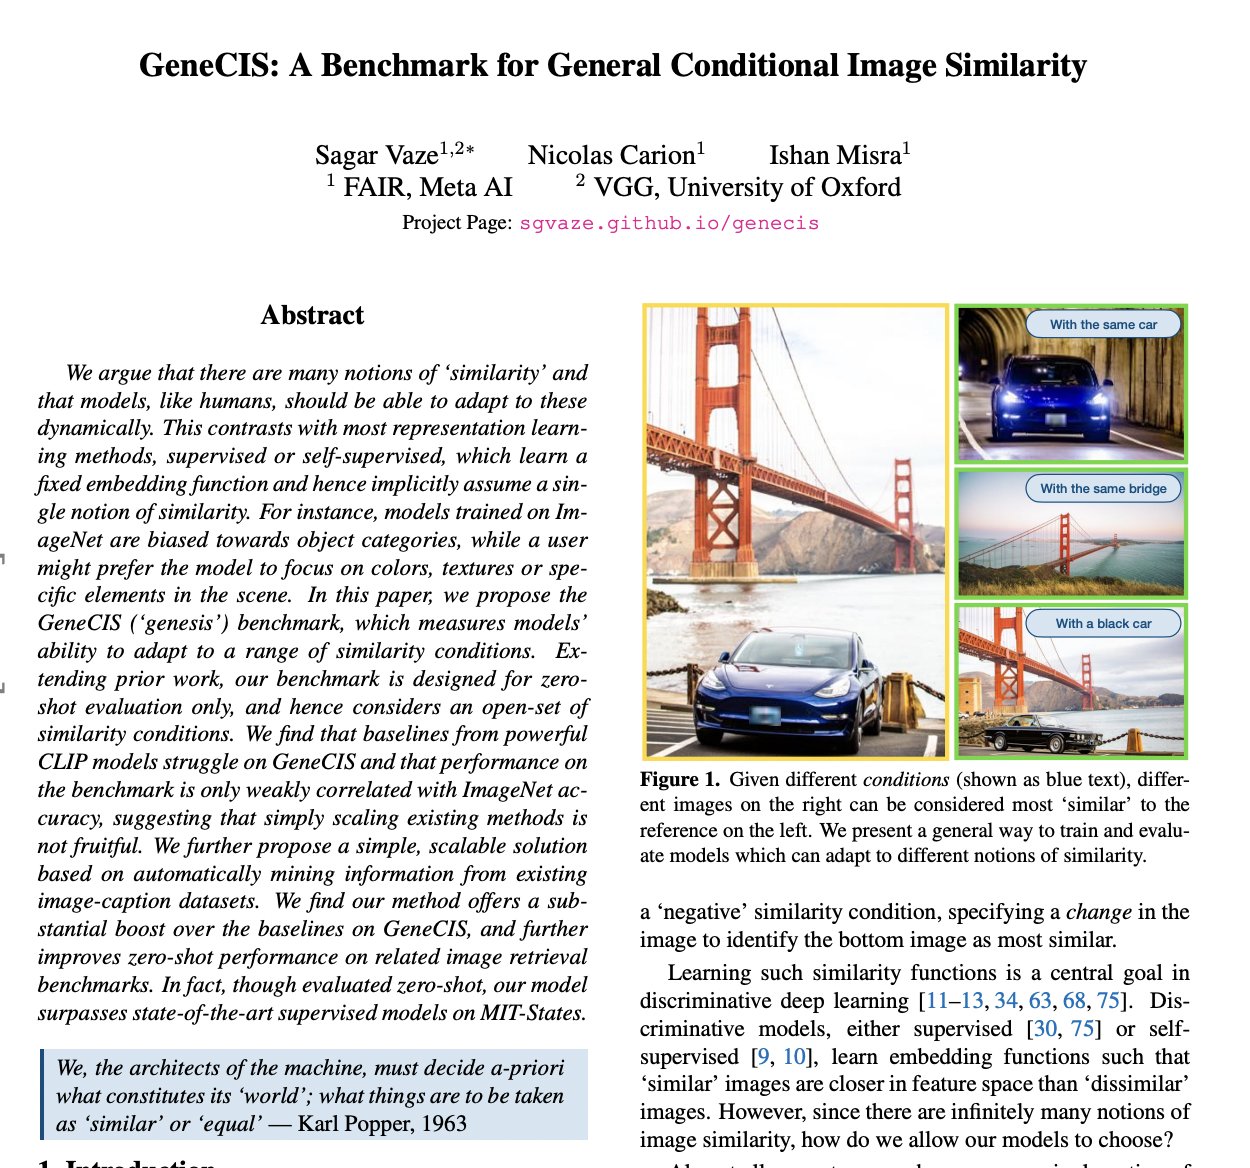
GeneCIS: Benchmark for General Conditional Image Similarity
By
–
GeneCIS: A Benchmark for General Conditional Image Similarity paper page: https://
huggingface.co/papers/2306.07
969
… argue that there are many notions of 'similarity' and that models, like humans, should be able to adapt to these dynamically. This contrasts with most representation learning -

GLoRA: Generalized LoRA for Efficient Model Fine-tuning
By
–
One-for-All: Generalized LoRA for Parameter-Efficient Fine-tuning paper page: https://
huggingface.co/papers/2306.07
967
… present Generalized LoRA (GLoRA), an advanced approach for universal parameter-efficient fine-tuning tasks. Enhancing Low-Rank Adaptation (LoRA), GLoRA employs a generalized -
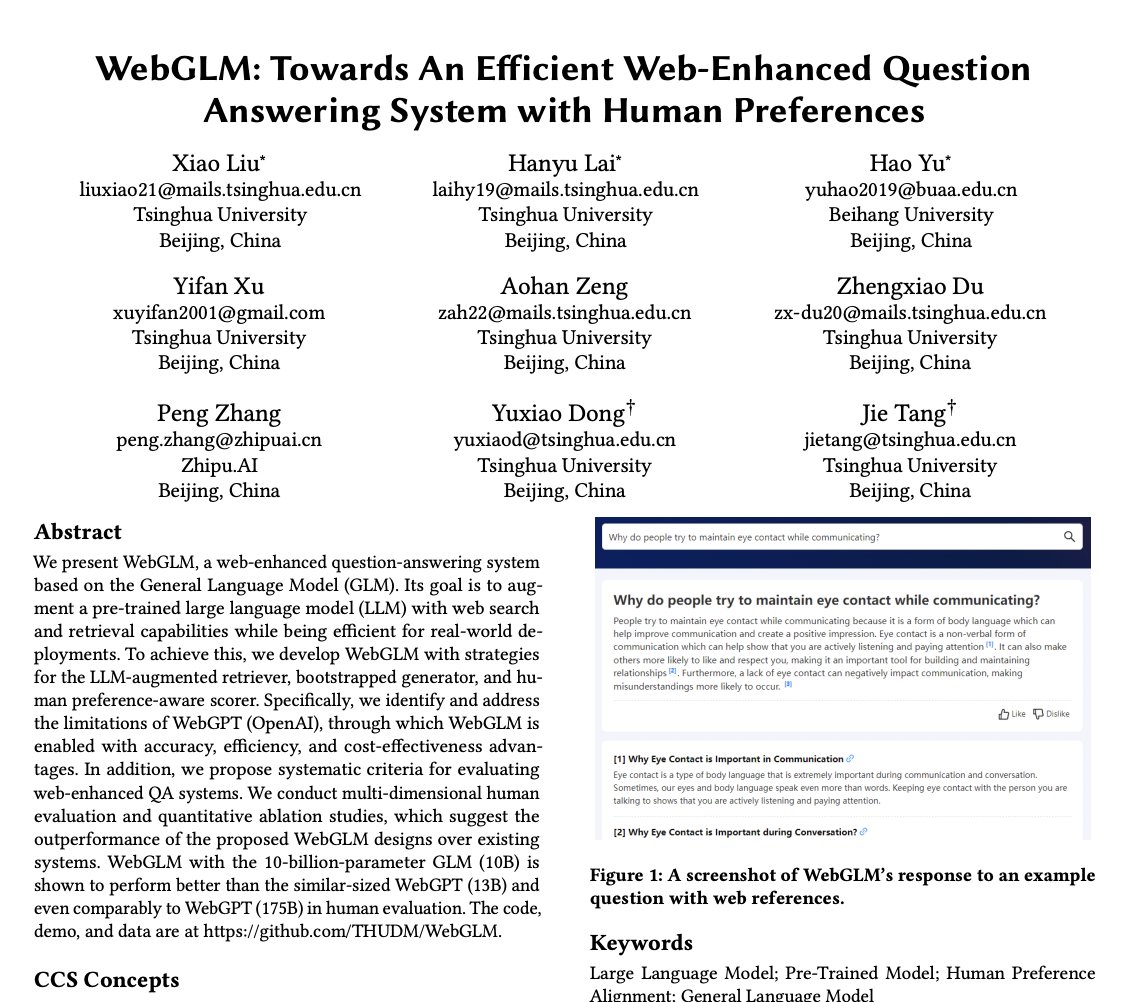
WebGLM: Efficient Web-Enhanced Question Answering System
By
–
WebGLM: Towards An Efficient Web-Enhanced Question Answering System with Human Preferences paper page: https://
huggingface.co/papers/2306.07
906
… present WebGLM, a web-enhanced question-answering system based on the General Language Model (GLM). Its goal is to augment a pre-trained large language -
Algorithmic Innovation: The Next Frontier Beyond Scaling
By
–
biggest questions in ai: – since the transformer, most AI improvement was via scaling up & great engineering
– almost no algorithmic ideas have driven performance, besides RLHF
– future gains will likely require algorithmic innovation how long will they take? who does them? -
Chains vs Agents: Deterministic vs Nondeterministic AI Systems
By
–
assuming im understanding you correctly, this is me is the difference between "chains" and "agents" (at least as far as how I think about them) chains = deterministic sequence of steps = code shell
agents = nondeterministic sequence of steps = llm shell -

Image Captioners as Scalable Vision Learning Models
By
–
Image Captioners Are Scalable Vision Learners Too paper page: https://
huggingface.co/papers/2306.07
915
… Contrastive pretraining on image-text pairs from the web is one of the most popular large-scale pretraining strategies for vision backbones, especially in the context of large multimodal -
Instant Multi-View Head Capture through Learnable Registration
By
–
Instant Multi-View Head Capture through Learnable Registration
— AK (@_akhaliq) 14 juin 2023
paper page: https://t.co/cgIfWuUvki
Existing methods for capturing datasets of 3D heads in dense semantic correspondence are slow, and commonly address the problem in two separate steps; multi-view stereo (MVS)… pic.twitter.com/8h3YoWOHIwInstant Multi-View Head Capture through Learnable Registration paper page: https://
huggingface.co/papers/2306.07
437
… Existing methods for capturing datasets of 3D heads in dense semantic correspondence are slow, and commonly address the problem in two separate steps; multi-view stereo (MVS) -

New AI Functionality Unlocked: Day Zero Launch
By
–
you can tell from the lack of proper grammar that its been a long day Big s/o to @veryboldbagel and @nfcampos but its only day zero! Looking forward to seeing what new functionality this unlocks
-
Rerender A Video: Zero-Shot Text-Guided Video Translation
By
–
Rerender A Video: Zero-Shot Text-Guided Video-to-Video Translation
— AK (@_akhaliq) 14 juin 2023
paper page: https://t.co/Ac6ct1naXx
Large text-to-image diffusion models have exhibited impressive proficiency in generating high-quality images. However, when applying these models to video domain, ensuring… pic.twitter.com/Il8xSgsW1kRerender A Video: Zero-Shot Text-Guided Video-to-Video Translation paper page: https://
huggingface.co/papers/2306.07
954
… Large text-to-image diffusion models have exhibited impressive proficiency in generating high-quality images. However, when applying these models to video domain, ensuring