How to implement this today: 1. Use PyTorch's torch.nn.utils.prune for magnitude pruning
2. Apply 2:4 structured patterns for GPU acceleration
3. Fine-tune with sparse-aware training
4. Deploy with TensorRT or ONNX Runtime The infrastructure exists. Most teams just don't know
INNOVATION
-
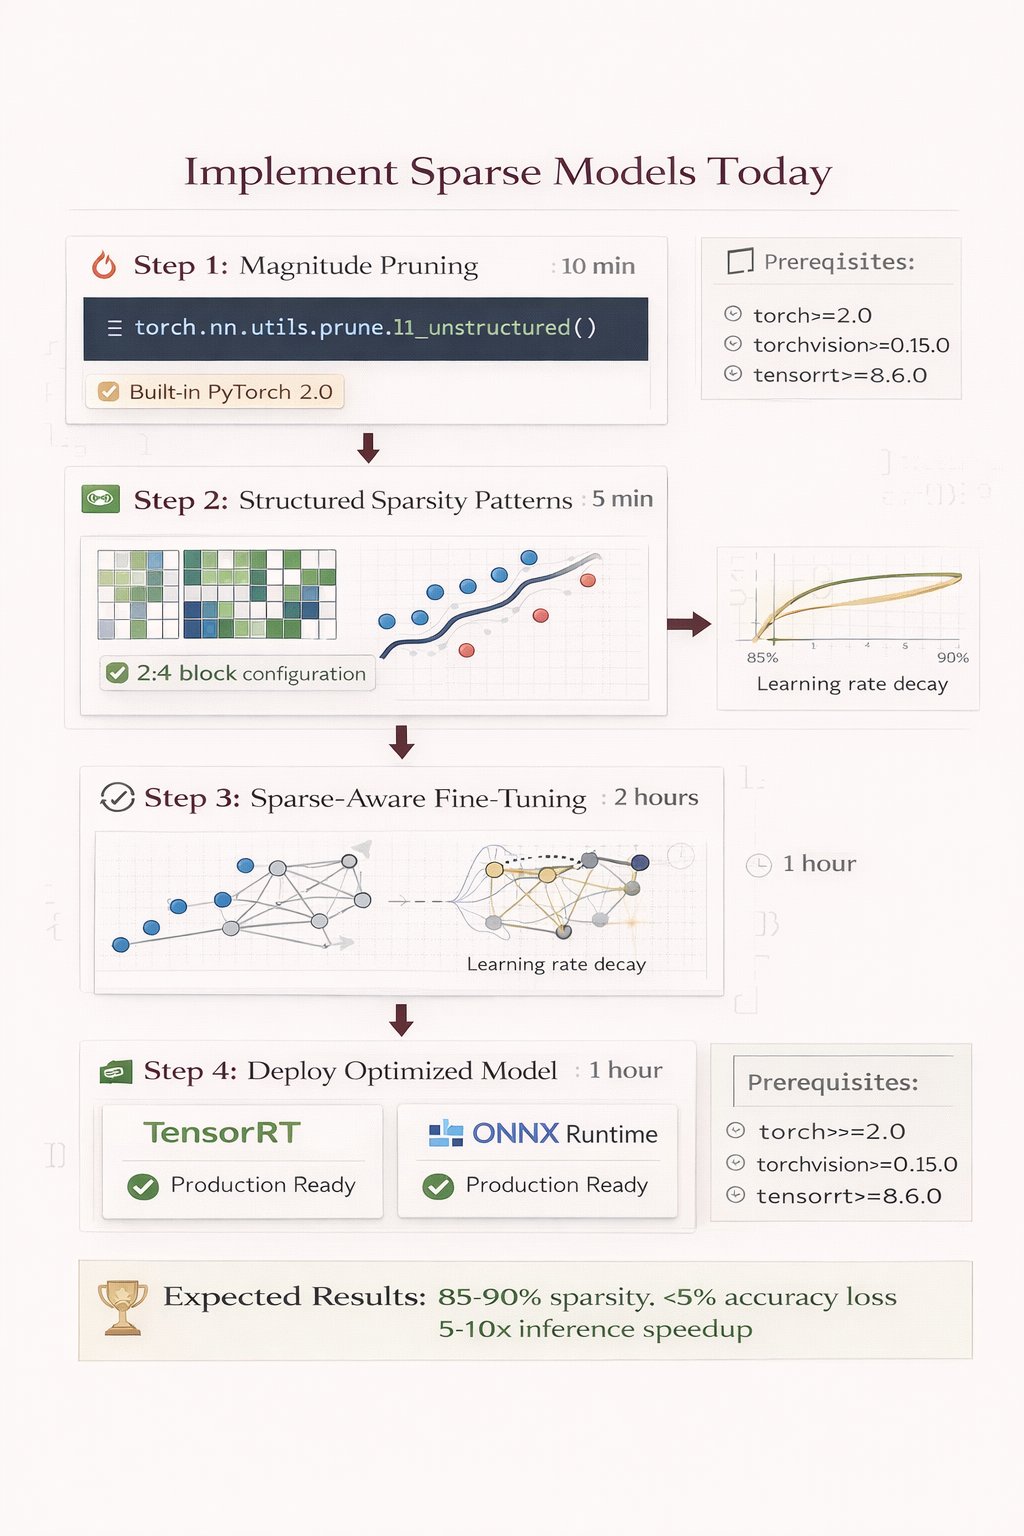
Implementing Sparse Model Training Today
By
–
-

Sparse models generalize better than dense ones
By
–
The counterintuitive part: Sparse models often generalize BETTER than dense ones. Why? Dense networks memorize noise. Sparse networks are forced to learn robust features. It's not just cheaper. It's actually better science.
-

Sparse Models Deliver Real-World Gains
By
–
Real-world results from companies already deploying sparse models: OpenAI: 40% cost reduction on GPT-4 API
Meta: 3x throughput increase for Llama inference
Google: 60% memory savings for production transformers The early adopters are already winning. -
2026 Breakthroughs Made AI Production-Ready
By
–
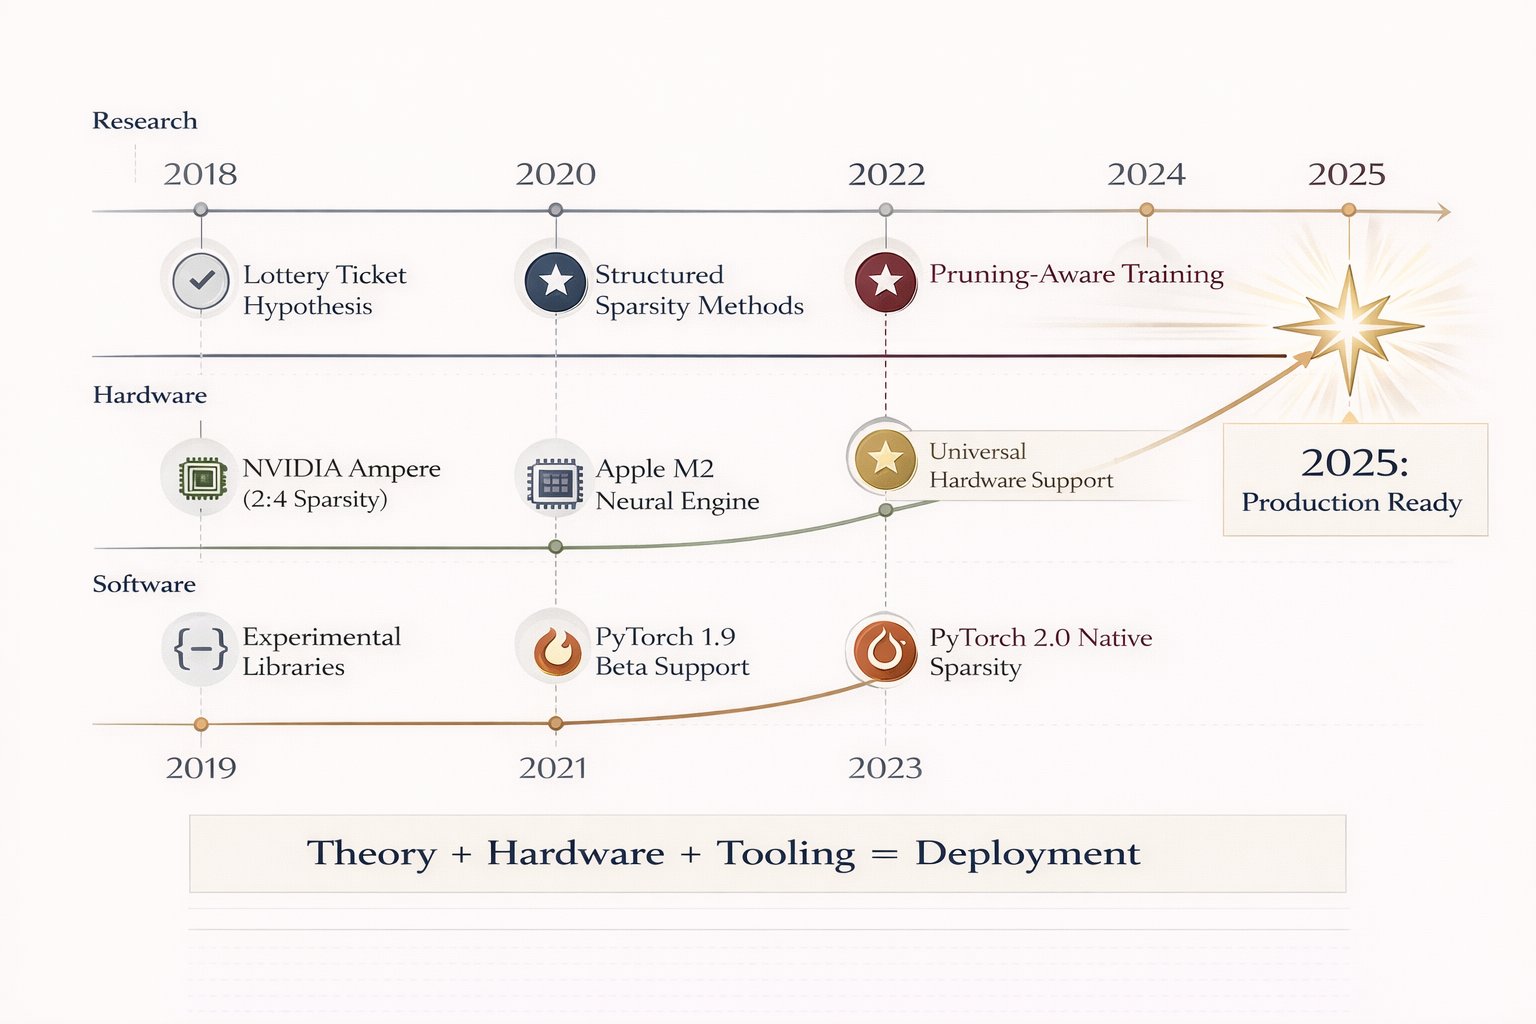
Three breakthroughs made this production-ready in 2026: 1. Pruning-aware training (train sparse from the start)
2. Hardware support (NVIDIA Ampere+, Apple Neural Engine)
3. Framework integration (PyTorch 2.0 native sparsity) The tooling finally caught up to the theory. -
Neural networks are 90% redundant by design
By
–
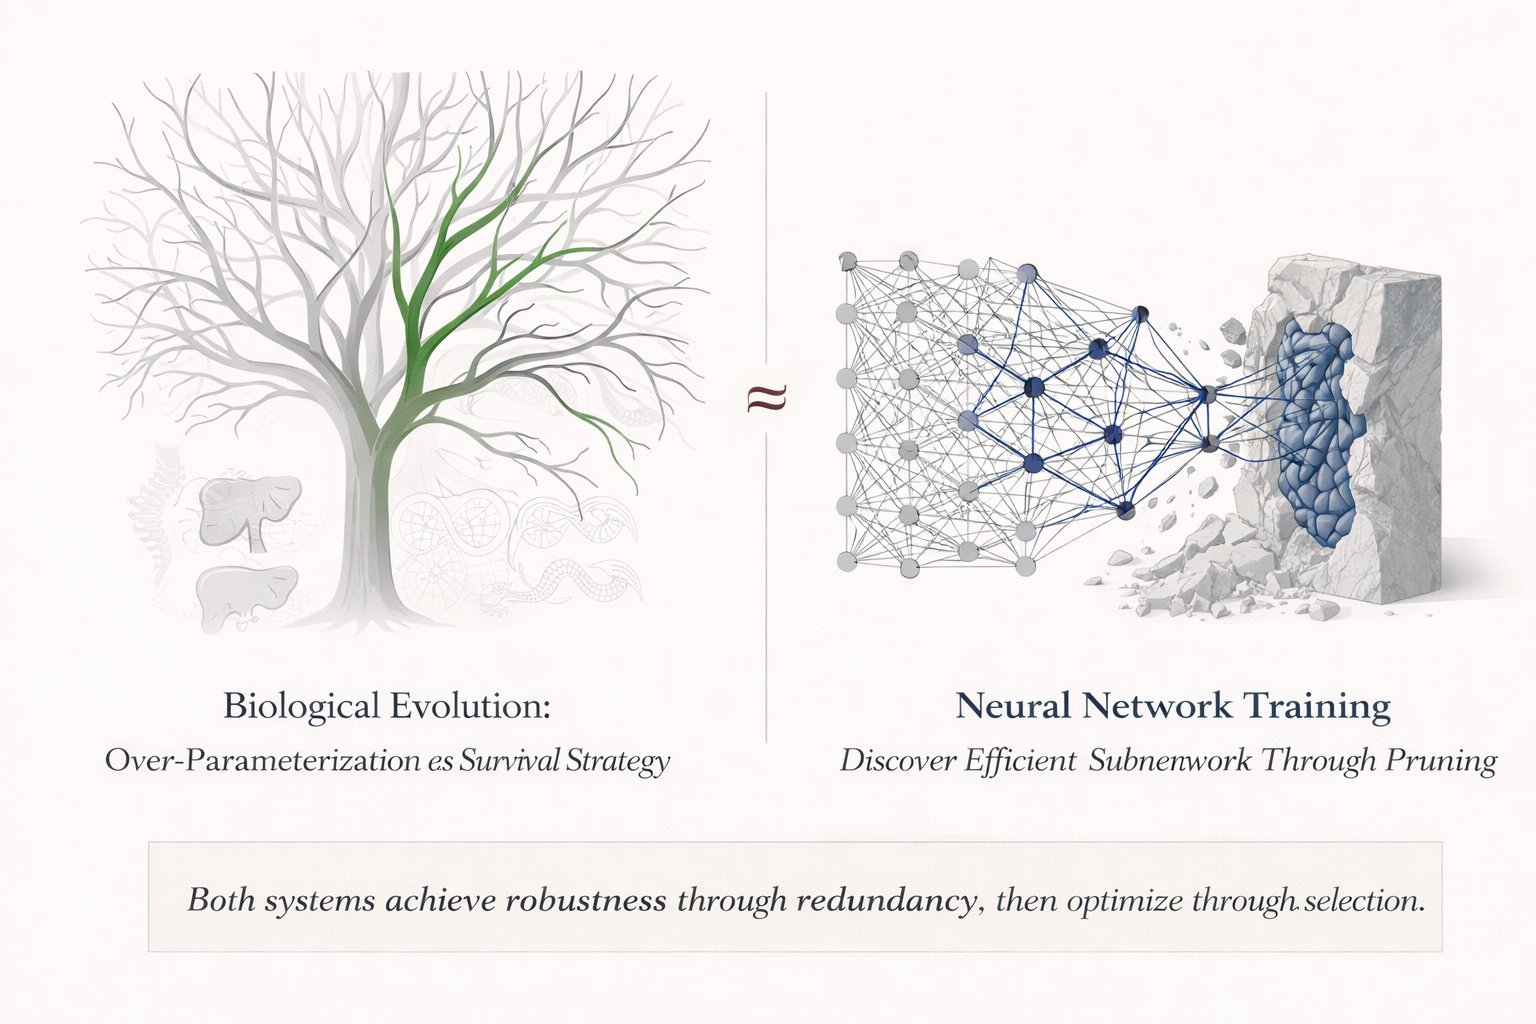
The academic papers missed the real story. It's not about finding "winning tickets" in random initialization. It's about discovering that neural networks are 90% redundant by design, and modern hardware finally lets us exploit that. Evolution over-parameterizes. We can prune.
-
Optimizing models with pruning, patterns, and quantization
By
–
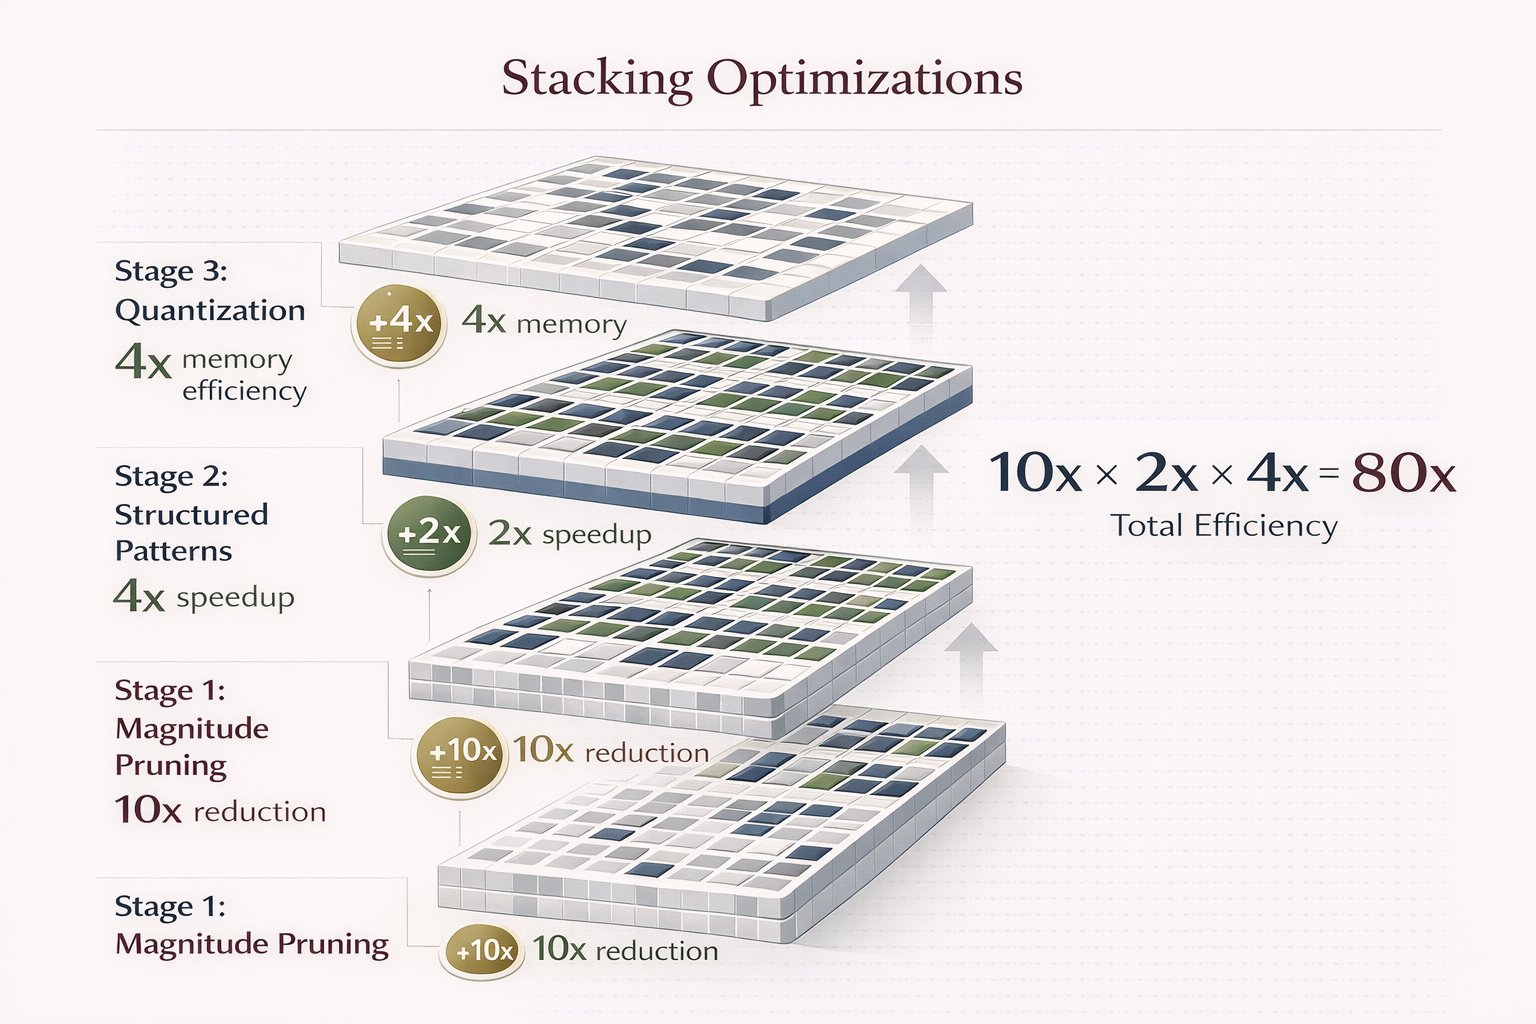
But magnitude pruning alone isn't enough. The real magic happens when you combine: → Magnitude pruning (remove smallest weights)
→ Structured patterns (2:4 blocks for GPU)
→ Quantization (INT8 instead of FP32) Stack all three and you get 20-50x deployment efficiency. -

Transformational AI Model Efficiency Gains
By
–
The deployment implications are massive: – GPT-3 scale models (175B params) → 17.5B params at same accuracy
– Monthly inference costs: $500K → $50K
– Latency: 2 seconds → 200ms
– Memory requirements: 350GB → 35GB This isn't incremental. It's transformational. -
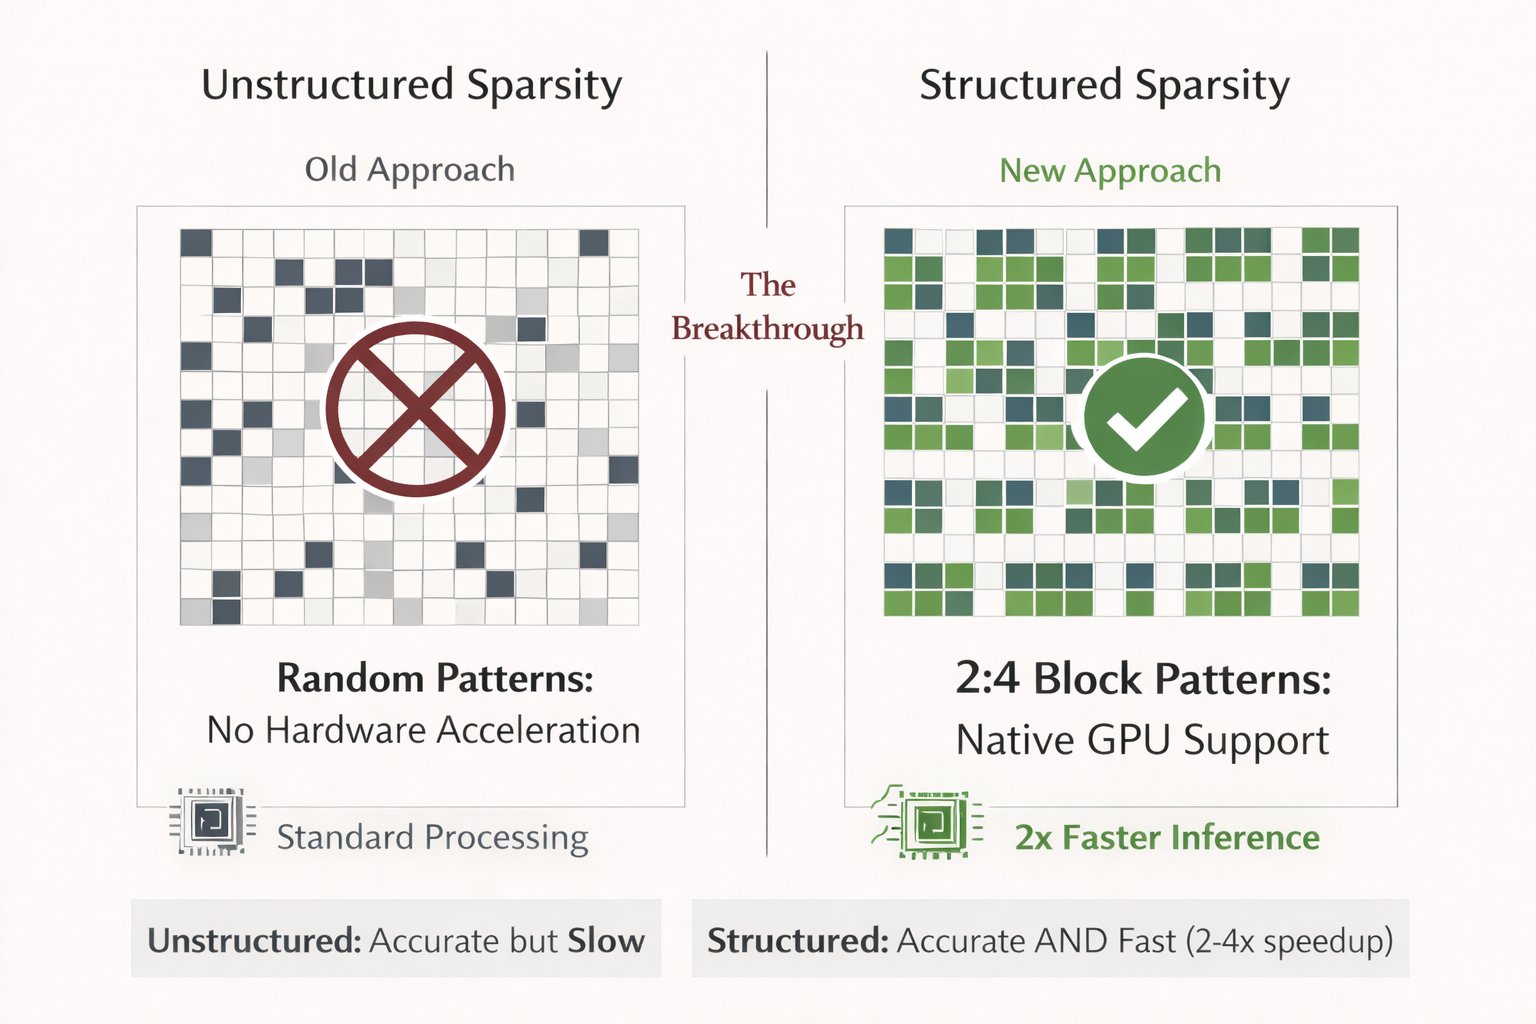
NVIDIA’s Block Sparsity Breakthrough Speeds AI
By
–
Then came the breakthrough nobody expected: Structured sparsity + modern hardware. NVIDIA proved you don't need random sparse patterns. Block sparsity (2:4, 4:8 patterns) runs NATIVELY on modern GPUs. Suddenly the lottery ticket isn't just accurate. It's actually faster.
-

MIT’s 90% Neural Network Deletion Breakthrough Ignored
By
–
MIT proved you can delete 90% of a neural network without losing accuracy. Five years later, nobody implements it. "The Lottery Ticket Hypothesis" just went from academic curiosity to production necessity, and it's about to 10x your inference costs. Here's what changed (and
-

Three AI Capabilities: Traditional, Generative, and Agentic AI in 2026
By
–
AI isn’t one thing – it’s three different capabilities. Traditional AI predicts and detects. Generative AI creates and automates. Agentic AI takes action and uses tools. The real shift in 2026?
Agentic AI becomes the operational layer – moving companies from automation