Unity presents IPAdapter-Instruct Resolving Ambiguity in Image-based Conditioning using Instruct Prompts discuss: https://
huggingface.co/papers/2408.03
209
… Diffusion models continuously push the boundary of state-of-the-art image generation, but the process is hard to control with any nuance:
GENERATIVE AI
-

IPAdapter-Instruct: Resolving Ambiguity in Image-based Conditioning
By
–
-
3D Object Generation via Image Diffusion with UV Maps
By
–
An Object is Worth 64×64 Pixels: Generating 3D Object via Image Diffusion
— AK (@_akhaliq) 7 août 2024
discuss: https://t.co/G6KGltWvMR
We introduce a new approach for generating realistic 3D models with UV maps through a representation termed "Object Images." This approach encapsulates surface geometry,… pic.twitter.com/vYP35buY89An Object is Worth 64×64 Pixels: Generating 3D Object via Image Diffusion discuss: https://
huggingface.co/papers/2408.03
178
… We introduce a new approach for generating realistic 3D models with UV maps through a representation termed "Object Images." This approach encapsulates surface geometry, -
Google Announces CoverBench for Complex Claim Verification
By
–
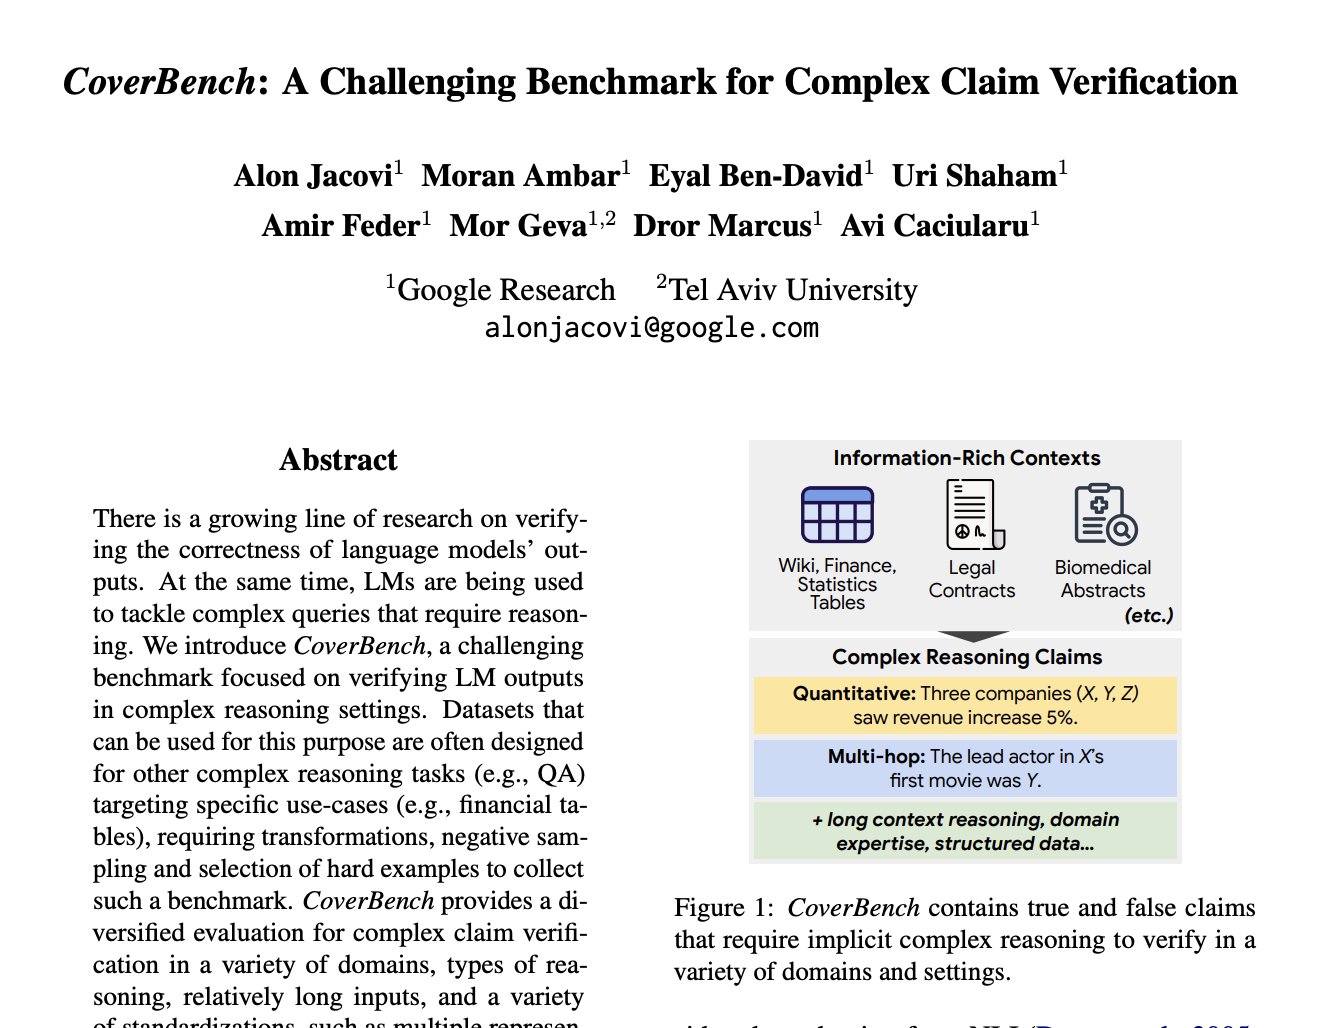
Google announces CoverBench A Challenging Benchmark for Complex Claim Verification discuss: https://
huggingface.co/papers/2408.03
325
… There is a growing line of research on verifying the correctness of language models' outputs. At the same time, LMs are being used to tackle complex queries that -
Google: Test-Time Compute Scaling More Effective Than Model Parameters
By
–
Google announces Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters discuss: https://
huggingface.co/papers/2408.03
314
… Enabling LLMs to improve their outputs by using more test-time computation is a critical step towards building generally self-improving -
Diffusion Models as Visual Data Mining Tools
By
–
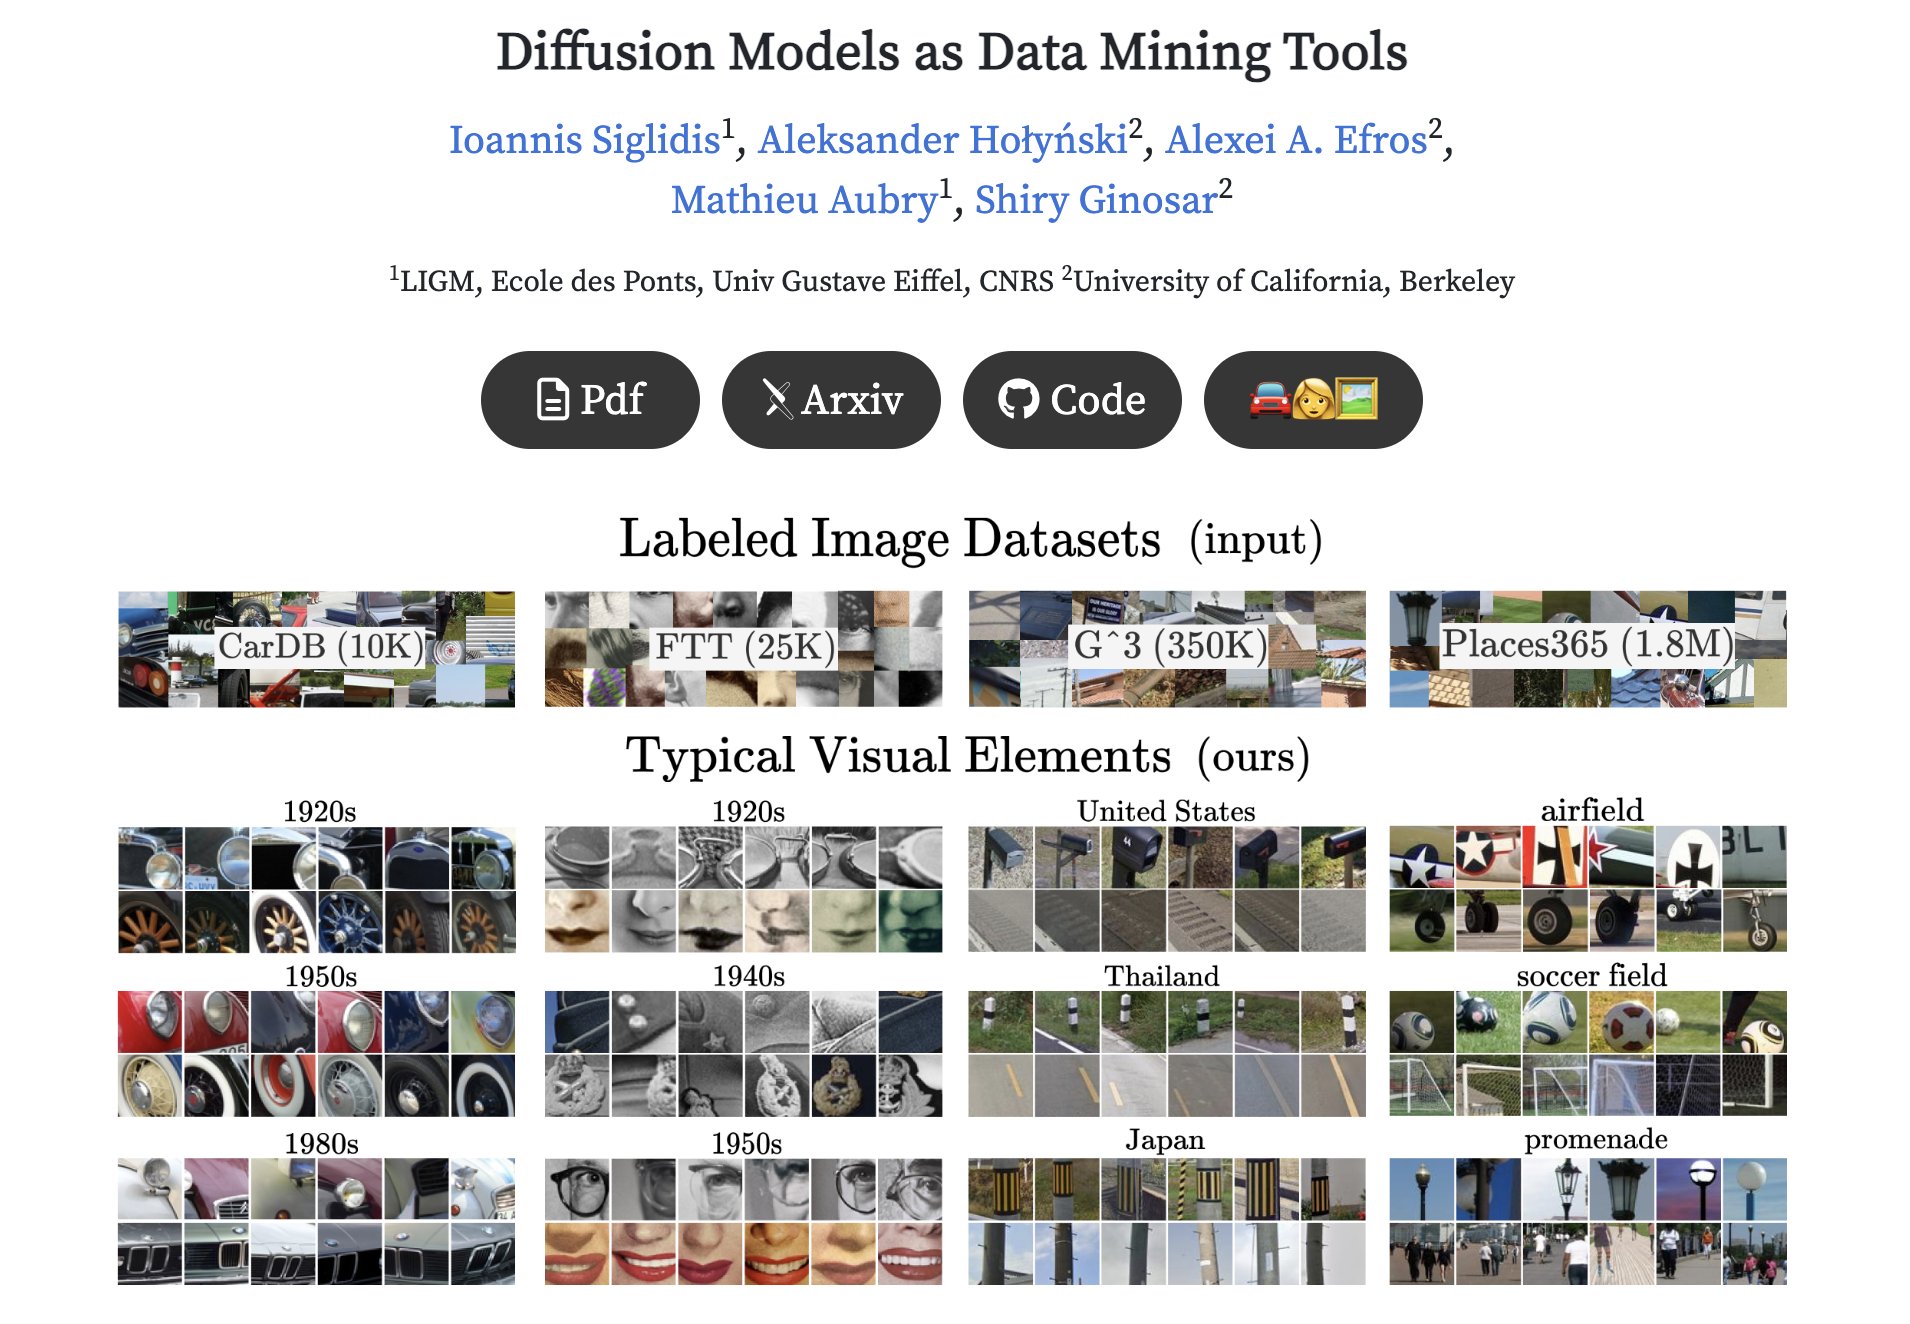
Diffusion Models as Data Mining Tools discuss: https://
huggingface.co/papers/2408.02
752
… This paper demonstrates how to use generative models trained for image synthesis as tools for visual data mining. Our insight is that since contemporary generative models learn an accurate representation of -

MMIU: Evaluating Large Vision-Language Models with Multiple Images
By
–
MMIU Multimodal Multi-image Understanding for Evaluating Large Vision-Language Models discuss: https://
huggingface.co/papers/2408.02
718
… The capability to process multiple images is crucial for Large Vision-Language Models (LVLMs) to develop a more thorough and nuanced understanding of a scene. -

Working with Multiple AI Chats Simultaneously
By
–
You can also work with 2 different chats at the same time
-
Sonnet and Opus Add Tags for Tool Use Integration
By
–
Sonnet and Opus also add tags when doing tool use.
-
Performance improvements for LLM chat response streaming
By
–
from release notes at least "Improved performance when streaming chat responses."
-

Building Open-Source Local LLMs Workshop AWS GenAI
By
–
Join us on August 14 at the AWS GenAI Loft in SF for a workshop on building open-source local LLMs. Learn to integrate an open-source chat interface, a locally hosted language model, and a retrieval system. Network with AI engineers and get tips from Cohere and AWS experts.