Register for our upcoming sessions! Tuesday, September 10:
3:20 – 3:40 PM: Advanced Retrieval-Augmented Generation and Tool Use with Cohere: https://
reg.rf.oracle.com/flow/oracle/oc
w24/catalog/page/catalog/session/1722635719286001qu0t
… Wednesday, September 11:
The Future of AI and Data:
9:45 – 10:30 AM: https://
reg.rf.oracle.com/flow/oracle/oc
w24/catalog/page/catalog/session/1718295997989001ez6I
… 3:30 – 4:15 PM:
GENERATIVE AI
-
Advanced RAG and AI Future Sessions Registration
By
–
-

Master Email Writing with ChatGPT 4o Ensures Professional Communication
By
–
Master Email Writing with ChatGPT 4o Ensures Professional Communication • Choose AI tone
• Boost email clarity
• Save drafting time Read more: https://
buff.ly/3yVWwcx -
Discussion on Gemini Live product release status and rollout
By
–
I think it was a plan to launch it today b/c in today's announcement placeholder there were 3 items but only 1 got published (gemini live) but if it didn't go well it may get postponed
-

CEO shares Llama 405B record performance at Global AI Summit
By
–
Our team will be at @globalaisummit 2024 next week where our CEO & Co-Founder, @RodrigoLiang
, will share more about our world record performance on the best open source model, Llama 405B. See you at #GAIN2024! Learn more https://
globalaisummit.org/en/default.aspx #AI #LLM -

Comparing Gemini’s memory and custom system prompt functionality
By
–
Unlike on ChatGPT, you will be able to add your info manually so Gemini can pick it up. This feature now feels to be closer to a custom system prompt rather than Memory
-
Grok 2 Updates Coming in Upcoming Weeks
By
–
Expect more updates, including the addition of Grok 2, in the coming weeks!
-
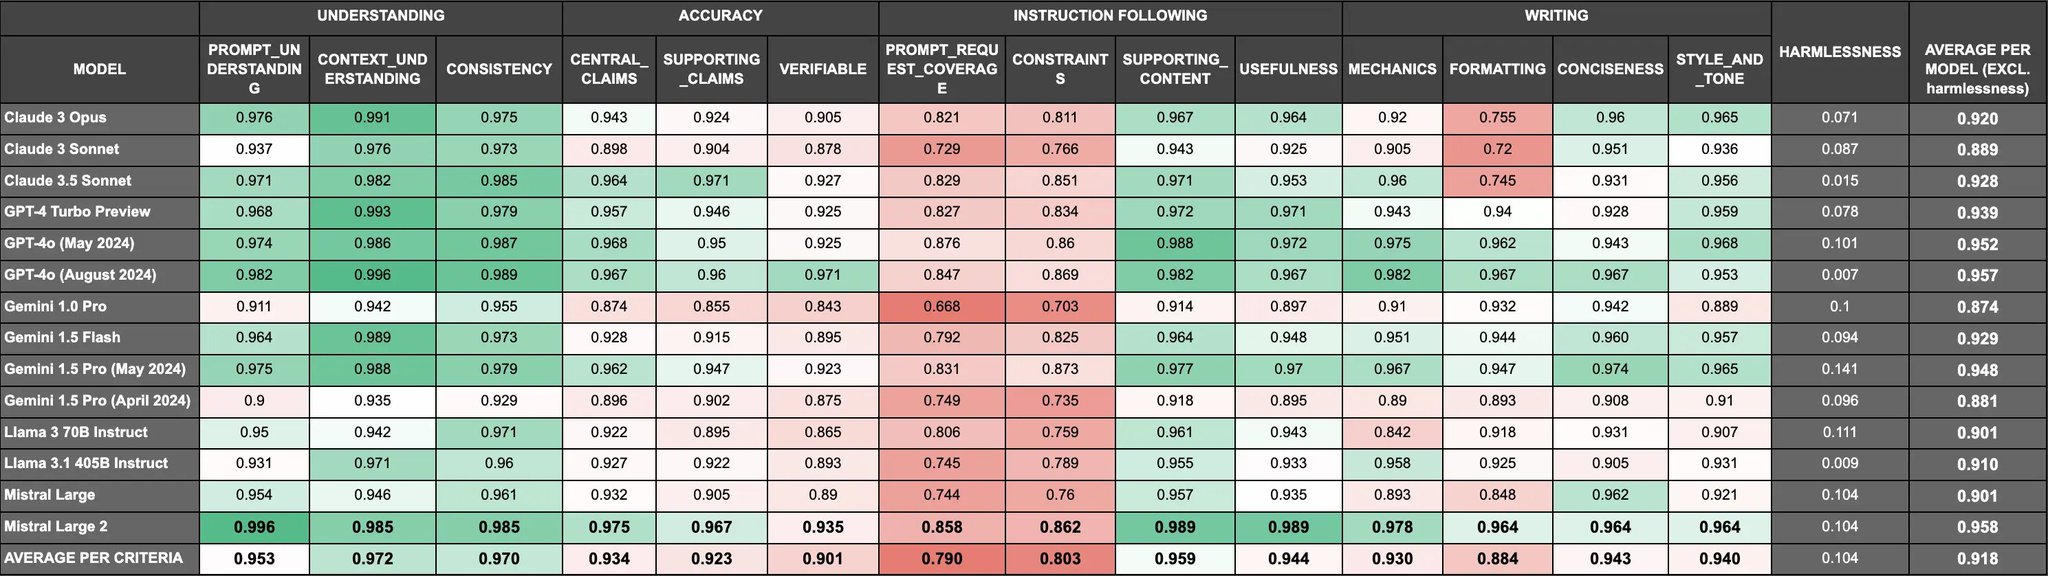
Models Show Weaker Instruction Following Performance in Spanish
By
–
MULTILINGUAL (SPANISH) Lastly, one interesting pattern we noticed is that every model seemed to perform worse at Instruction Following (Main Request fulfillment and Constraint fulfillment) in Spanish versus English. This implies there's still meaningful headroom for models to
-

GPT-4o leads code correctness; Claude excels prompt adherence
By
–
Some insights from the leaderboards: CODING We notice that GPT-4o (August 2024) performs the best on Code Correctness among all the models, but Claude outdoes it on Prompt Adherence
-
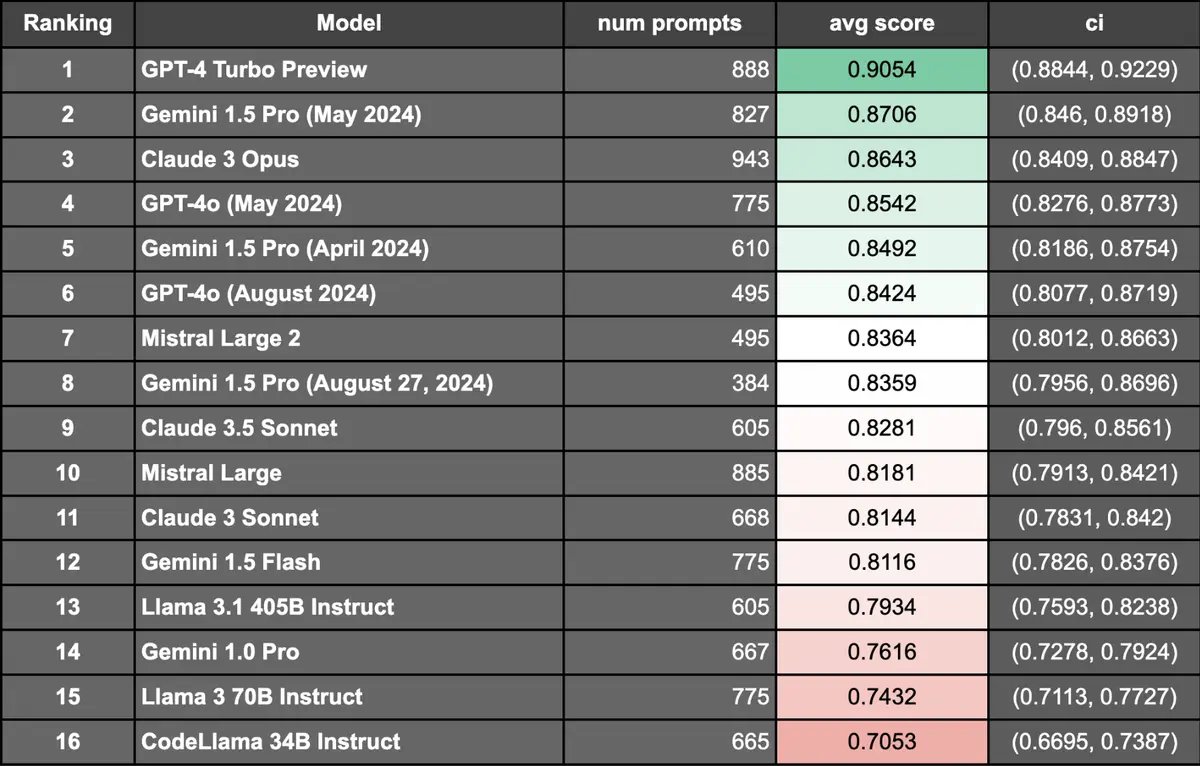
GPT-4 Turbo Remains Most Factual Model Among LLMs
By
–
INSTRUCTION FOLLOWING (FACTUALITY): We find that GPT-4 Turbo is still the most factual model among all of the models we've evaluated. With the trend towards smaller, distilled models, we notice that it seems to come at the cost of performance on factuality.
-
GPT-4o-latest outperforms May 2024 model on math and coding
By
–
GPT-4o-latest (gpt-4o-2024-0806) ranks above the prior GPT-4o (May 2024) on: – Math (now #2 behind Claude 3.5 Sonnet)
– Coding (now #2 behind Claude 3.5 Sonnet) but actually performed worse than the May model on Instruction Following (now ranked #8) and Spanish (now ranked #3)