
ChatGPT has hit 1 billion weekly active users (WAU). OpenAI is not far from the vaunted 1 billion daily active users (DAU) club.
GENERATIVE AI
-
Google’s Gemini, Gemma, and JAX Stack Impress AI Observer
By
–
Un ponte de l'IA. Nous avions analysé son papier. Traduction : Google n’a jamais été doué pour le marketing de ses produits, mais alors niveau technologie, c’est du très lourd. Très optimiste sur Gemini, la gamme de modèles open source Gemma, et la stack JAX/Keras/TPU.4o
-
Building AI Systems Faster: From 40 People to 2-3 Engineers
By
–
we did godinabox in 2 days alphactr and autocodepro in a couple of weeks with just 2-3 people. This needed 40 and a lot of time.
-
OpenAI Plans to Release Powerful Open Source Model Near Frontier
By
–
C'est du lourd ! Sam Altman confirme :
— VISION IA (@vision_ia) 12 avril 2025
OpenAI prévoit de publier un modèle open source très puissant.
Il pourrait être « proche de la frontière » et meilleur que tous les modèles open source actuellement disponibles. pic.twitter.com/gIlqrLDxrbC'est du lourd ! Sam Altman confirme : OpenAI prévoit de publier un modèle open source très puissant. Il pourrait être « proche de la frontière » et meilleur que tous les modèles open source actuellement disponibles.
-
CodeLLM Advances: Image Upload, Grok 3 Integration, Autocomplete Improvements
By
–
New CodeLLM Release – Upload images in Agents and generate code
– Grok 3 and Grok-3 mini in CodeLLM agents
– One more step change in Autocomplete Coming soon – Rich prompting
– Large code bases
– Better human-in-the-loop management -
Google’s Marketing Weakness Versus Strong Technology Leadership
By
–
Google has never been good at marketing its products, but boy is it good at technology. Very bullish on Gemini, the Gemma line of open models, and the JAX/Keras/TPU stack
-
Gemini 2.5 Pro Reception Exceeds Expectations Across Benchmarks
By
–
We are blown away by the reception of Gemini 2.5 Pro, and the many positive surprises from benchmarks and community evaluations. That is the ultimate leaderboard!
-

VideoChat-R1: Spatio-Temporal Perception via Reinforcement Fine-Tuning
By
–
Chat-R1: Enhancing Spatio-Temporal Perception via Reinforcement Fine-Tuning This paper explores the use of Reinforcement Fine-Tuning (RFT) with Group Relative Policy Optimization (GRPO) to enhance spatio-temporal perception in video multimodal large language models (MLLMs),
-

SmolVLM: Efficient Vision-Language Models for Edge Devices
By
–
SmolVLM: Redefining small and efficient multimodal models SmolVLM is a family of highly efficient, small-scale vision-language models (VLMs) engineered for low-memory, real-time multimodal inference on mobile and edge devices. These models achieve competitive or even superior
-
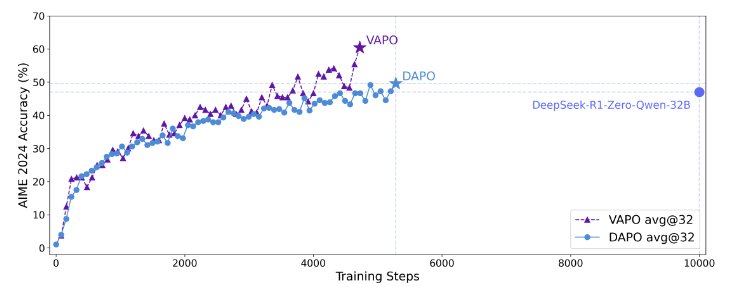
VAPO: Value-Based RL Framework for Advanced LLM Reasoning
By
–
VAPO: Efficient and Reliable Reinforcement Learning for Advanced Reasoning Tasks VAPO is a new value-based reinforcement learning framework designed to enhance long chain-of-thought reasoning in large language models. Built upon Qwen2.5-32B, it outperforms existing methods in