Announcing Granola 2.0: today we’re bringing the power of Granola to your whole team Also announcing our $43M series B. Led by @natfriedman , alongside Lightspeed and Spark, to build the AI workspace of the future. Big day! x.com/cjpedregal/sta…
GENERATIVE AI
-
Hedra Raises $32M Series A Led by a16z
By
–
— Yohei (@yoheinakajima) 16 mai 2025
We’re excited to share that Hedra has raised a $32M Series A led by a16z, with Matt Bornstein joining the board. Existing investors including a16z speedrun, Abstract, and Index Ventures are also participating in the round. We launched out of stealth last year with a simple
-
Fresh AI Funding Rounds: $27M to $43.5M Across Sectors
By
–
still a bit buggy (and newsletter is not working atm), but vcpedia has been pretty solid at finding fresh funding rounds. some recent AI ones: @personaaiinc (robotics) $27M @hedra_labs (video) $32M @samaya_ai (finance) $43.5M @meetgranola (notes) $43M @akidolabs (healthcare)
-
OpenAI Codex Agent Shows Net-Positive Coding Gains, Future Bright
By
–
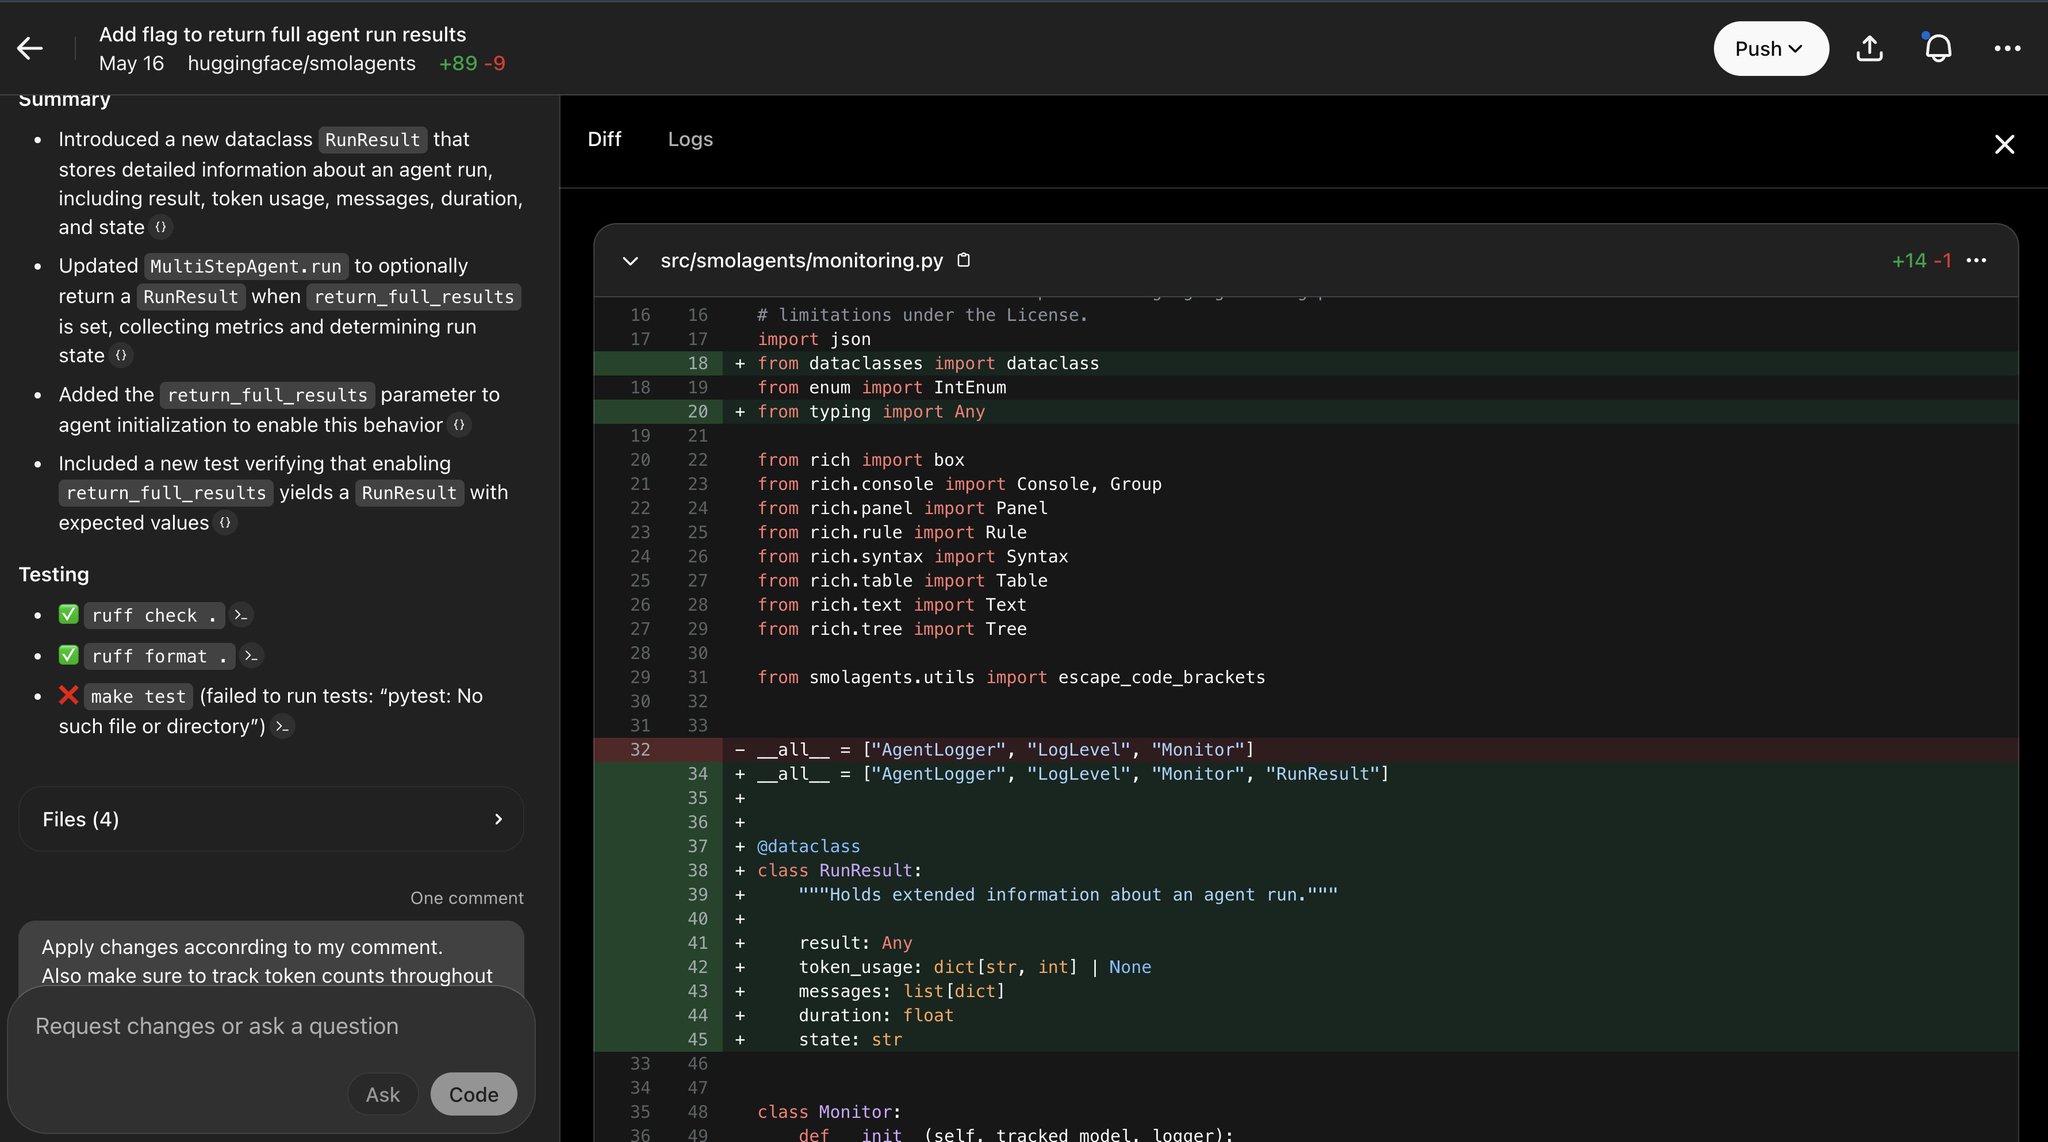
I've tried OpenAI's Codex, the autonomous SWE agent integrated into ChatGPT. -> While certainly not producing one-shot perfect PRs, it's already a net-positive. And the gain will only improve with better coder models! I think that in the next era of coding, most will be done
-
Global Credit Leader Scales AI Copilot with High-Quality Training Data
By
–
A global credit leader built an AI copilot to help CSRs with accurate responses, but early models lacked precision. With Snorkel Enterprise AI Platform, they fine-tuned with high-quality training data to boost accuracy & enable scalable copilots! Scale up with #SnorkelAI
-
DeepAgent Evaluates All LLMs in Single Line Prompt
By
–
In a single line prompt, DeepAgent evaluates all LLMs and creates this website:
— Abacus.AI (@abacusai) 16 mai 2025
•Generated an image for each LLM
•Created a chart that compares and contrasts top LLMs across cost, performance, and context pic.twitter.com/0fwC6bhEGOIn a single line prompt, DeepAgent evaluates all LLMs and creates this website: •Generated an image for each LLM
•Created a chart that compares and contrasts top LLMs across cost, performance, and context -
Llama 4 Scout achieves 2600 tokens per second on Poe
By
–
The world’s fastest inference for Llama 4 Scout is now on Poe!
— Poe (@poe_platform) 16 mai 2025
At over 2,600 tokens per second, this bot allows for near-instant interactions. (1/2) pic.twitter.com/wt6NaFyEzxThe world’s fastest inference for Llama 4 Scout is now on Poe! At over 2,600 tokens per second, this bot allows for near-instant interactions. (1/2)
-
Cerebras Llama 4 Scout Nitro Now Available on Poe Platform
By
–
You can try Cerebras’ Llama 4 Scout Nitro at https://
poe.com/Llama-4-Scout-
nitro
… and on all platforms. (2/2) -
New tool outperforms Codex in testing
By
–
i've been testing something that works so well im not that excited to use codex
-

Novita Labs Sign-In Interface Delights Users Daily
By
–
This sign-in page makes me happy every time I see it!! @novita_labs <3