Jensen Huang is live on stage at #COMPUTEX2025—don’t miss the keynote unveiling the next wave of AI breakthroughs. Watch the livestream now: https://
nvda.ws/4kvDKed
May 18 at 8:00 p.m. PT (May 19, 11:00 a.m. Taipei Time)
#GTCtaipei
GENERATIVE AI
-

Jensen Huang Unveils Next Wave of AI Breakthroughs at Computex
By
–
-
Digital Fashion and Metaverse: Sustainability in Virtual Clothing
By
–
Future of Fashion: Digital Clothing, #Metaverse , and Sustainability https://
deccanherald.com/dhbrandspot/fu
ture-of-fashion-digital-clothing-metaverse-and-sustainability-3543589?utm_source=twitter&utm_medium=referral&utm_campaign=socialshare
… via @deccanherald -
First Look at Video Overviews by NotebookLM
By
–
BREAKING 🚨: First look into Video Overviews, which are generated by the same model that will power NotebookLM soon.
— 🚨 AI News | TestingCatalog (@testingcatalog) 18 mai 2025
These are 4 "Sparks", 1-3 minute videos in different styles generated from various sources. pic.twitter.com/OgO1hDoP9mBREAKING : First look into Overviews, which are generated by the same model that will power NotebookLM soon. These are 4 "Sparks", 1-3 minute videos in different styles generated from various sources.
-
Kling AI Lip-Sync Model Now Available on Replicate
By
–
Kling AI's lip-sync model is now available on Replicatehttps://t.co/wW6enrYrgP
— Replicate (@replicate) 18 mai 2025
Here's a Kling v2.0 generation with lip-synced audio added pic.twitter.com/aDhsDofipJKling AI's lip-sync model is now available on Replicate https://replicate.com/kwaivgi/kling-lip-sync
… Here's a Kling v2.0 generation with lip-synced audio added -

Zero-to-LLM Engineer Bundle: Complete Learning Path
By
–
Since many of you asked, here it is… our "Zero-to-LLM Engineer" bundle! We ( @towards_AI ) recently released our three core offers for any builders out there, together taking you from "zero" (literally, no coding knowledge or anything required) up to an advanced LLM developer
-
Model Training Scale: From 800K to 25 Trillion Tokens
By
–
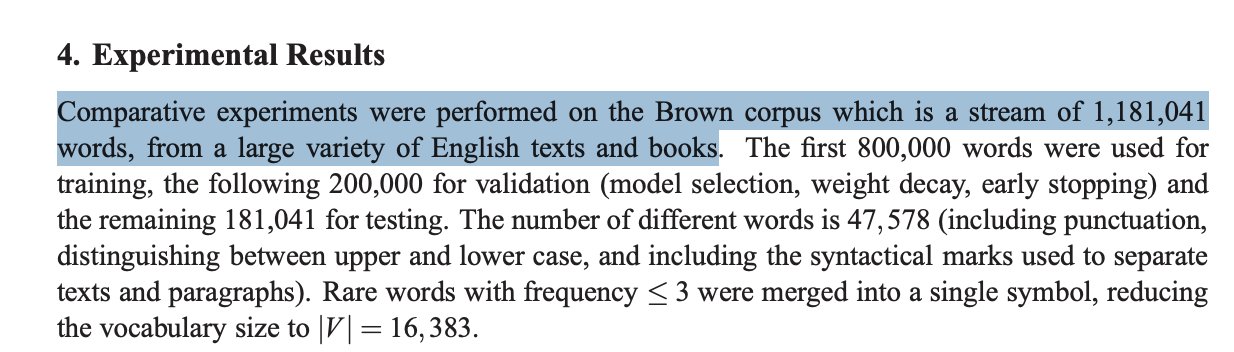
their model is trained on 800K words, which is around 2.5M tokens. remember today's models are up to ~25T tokens (10^7 more, or 10 million million times) (they trained another model on 15M words)
-
Compact Language Model Architecture: 12M Parameters vs LLAMA 4
By
–
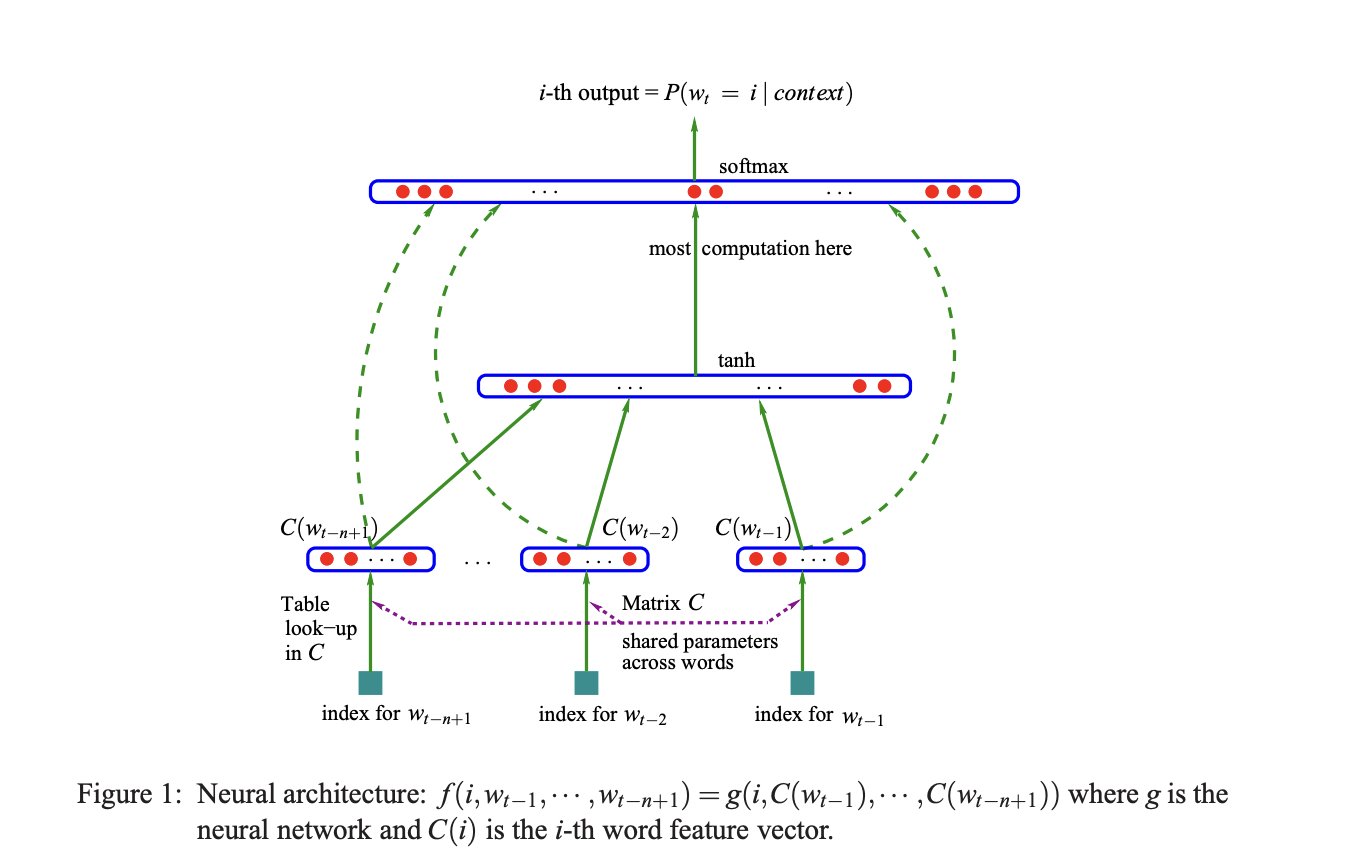
they use word embeddings + single-layer MLPs vocab size is 18K, context window is 6 words, hidden dimension is 60, word embedding have 100 dimensions their model has approx |V|(nm + h) = 17,964 × (6 × 100 + 60) = 12 million parameters about 200K times smaller than LLAMA 4…
-
Denied AI Capabilities: Understanding Limitations and Constraints
By
–
The denied capabilities tend to be informally specified (understanding, intentionality, reasoning, agency, creativity, selfhood, sentience, sapience, abstraction, common sense) but can also apply to specific tasks (categorizing an object as the Charles river, winning at Go).
-
Epistemological Challenges When Denying AI Capabilities
By
–
When capability of a class of Turing complete systems is denied ("a computer/perceptron/transformer can never do X") it poses interesting epistemological and metaphysical challenges, which are unfortunately rarely discussed ("how can anything do X without breaking physics?").
-
Capability Denialists Reject AI Approach Fundamentally
By
–
Capability denialists generally don't claim that the limitations of the AI system they criticize are due to capacity constraints that could be overcome (eg. with more memory, more compute, more data, algorithmic improvements), but that the entire approach is doomed.