Example: GPT-4o on OdysseyBench-Neo: • Long-context: 51.99%, 6.7K tokens
• RAG + chunk summary: 56.29%, 1.36K tokens Semantic compression ≫ brute-force memory More tokens ≠ more understanding.
GENERATIVE AI
-
GPT-4o Performance Analysis on OdysseyBench-Neo
By
–
-
Memory design and retrieval strategies in AI models
By
–
Memory design matters more than model size OdysseyBench evaluated multiple retrieval strategies: • Long-context prompting (8K+ tokens)
• RAG with raw session or utterance context
• RAG with summarization: session or chunk Chunk-level summaries outperformed all, with ~75% -
Top 4 Failure Modes in AI Agent Execution
By
–
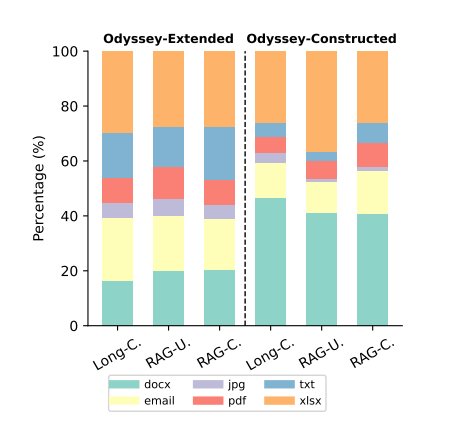
Top 4 Failure Modes: 1. Missing files – agent forgets to locate or read required inputs
2. Missing actions – agent skips subtasks (e.g., doesn’t write output)
3. Incorrect tool use – uses wrong app or API for the goal
4. Poor planning – jumps to execution before -
Comparative Performance Analysis of LLMs Across Task Complexity
By
–
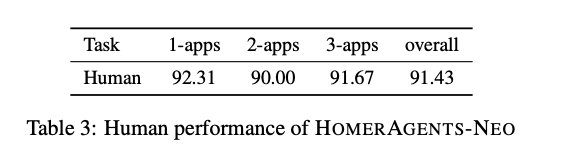
How do models perform? Human: 91%+
GPT-5: ~54%
GPT-4.1: ~36%
GPT-4o: ~52%
DeepSeek-R1: ~55% And here’s the kicker: 3-app tasks cause up to 3x degradation vs single-app tasks across all models. -

OdysseyBench and HOMERAGENTS: A Multi-Agent Generation Pipeline
By
–
OdysseyBench is built using HOMERAGENTS, a multi-agent generation pipeline: • HOMERAGENTS+: Converts atomic tasks into multi-turn workflows • HOMERAGENTS-NEO: Synthesizes entirely new tasks using simulated app exploration Each task is: • Goal-driven
• Dialogue-based
• -
AI Model Explosion: New Releases From OpenAI Google Anthropic Grok
By
–
Choses qui n’existaient pas il y a un mois : – GPT-5
– GPT-5 mini
– GPT-5 nano
– GPT-OSS-120b
– GPT-OSS-20b
– Claude Opus 4.1
– Claude Sonnet 4.1
– Génie 3
– Google Deepthink advanced
– Google Gemma 270M
– Google Story book
– ChatGPT Agent
– Grok-4
– Grok Imagine
– Grok -
Custom AI Model Selection and System Prompts in Google Sheets
By
–
It's funny I had a script working in Google sheets doing this for about 18 months – the difference though is that I can select the models and a system prompt. One problem I have with these kinds of implementations is that they treat it as a generic 'AI', but I care a lot what
-
French 2027 Election: AI Literacy Gap Among Political Candidates
By
–
Mes craintes pour la présidentielle de 2027 1 La configuration politicienne empêchera tout débat sur le pilotage du tsunami technologique 2 La plupart des candidats ne sauront toujours pas utiliser ChatGPT 3 Les gens qui comprennent l’IA seront marginalisés @GabrielAttal
-
Reasoning Models Generate Significantly More Code Than Previous Models
By
–
The amount of code it was actually outputting was kind of crazy, especially comparing it to previous non-reasoning models, it is so much better than older ones
-
AI tools in clinical practice may erode doctors’ core skills
By
–
A new study in The Lancet suggests that frequent reliance on #artificialintelligence tools in clinical practice may erode core clinical skills among doctors, potentially jeopardising patient outcomes. https://
bit.ly/3UBfUmm
#GenAI #Healthcare #AI #TheLancet