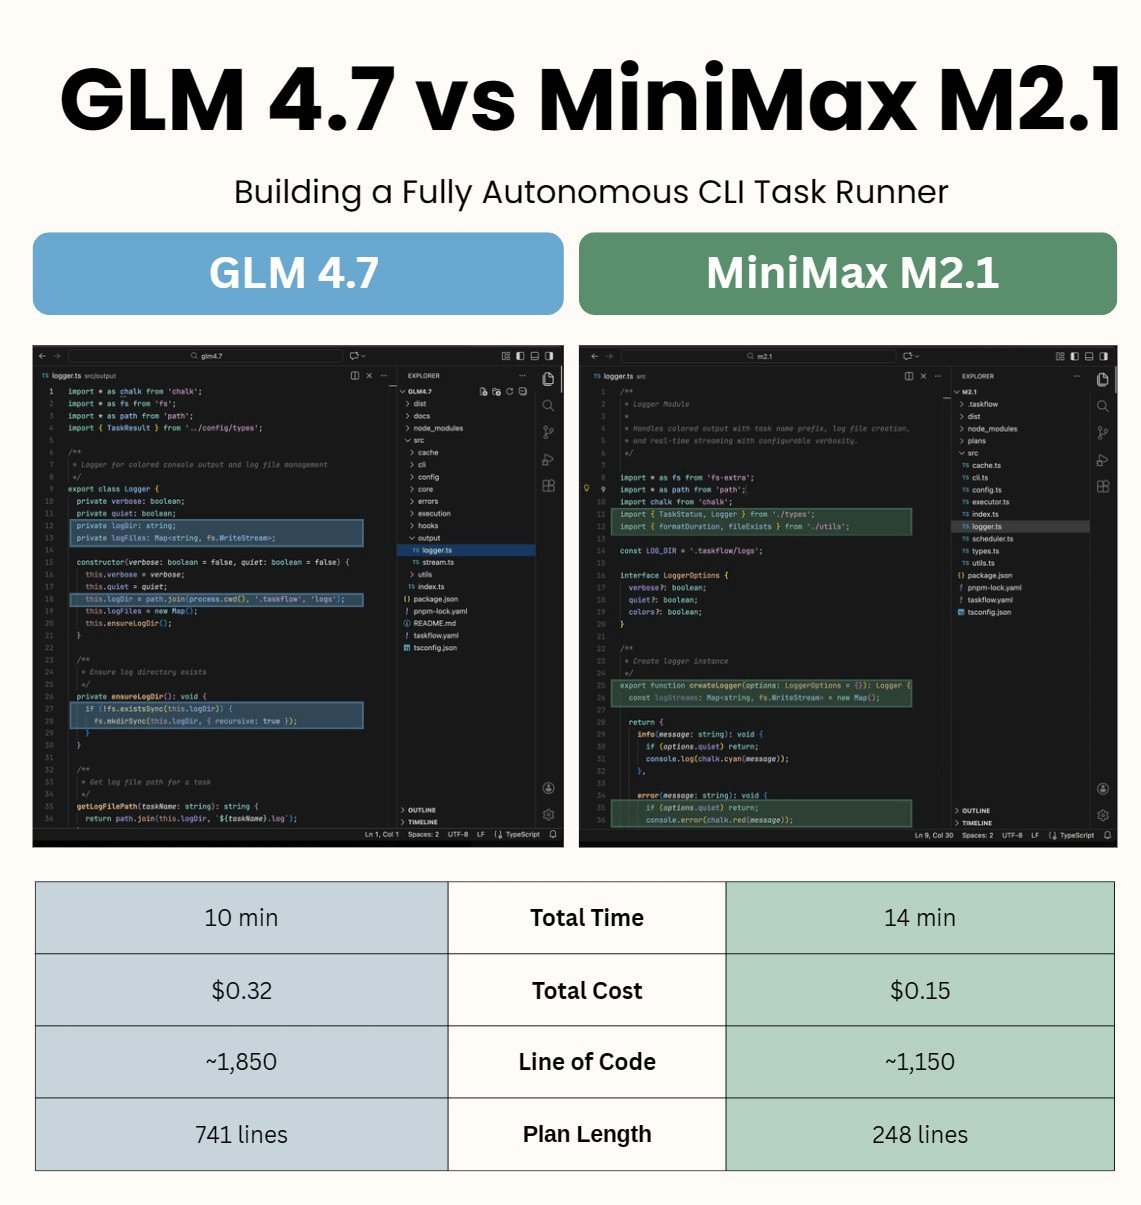
Open-weight models just built a 20-feature CLI runner autonomously! Kilo Code tested MiniMax M2.1 and GLM 4.7 by having them build a complete CLI task runner from scratch. Both models succeeded. No human intervention for 10-14 minutes straight. The test was realistic: build a
GENERATIVE AI
-

IBM Launches Industry’s First AI-Ready Sovereign Software Solution
By
–
Just announced: the industry’s first AI-ready sovereign software. IBM Sovereign Core is built for organizations that need to keep their data and AI workloads under their own direct control and operational authority. Discover the future of sovereign AI: ibm.biz/BdbNhT
-

Gemini’s Personal Intelligence and Latest AI Tools Update
By
–
Top stories in AI today: – Gemini’s ‘Personal Intelligence’ shift
– McConaughey trademarks himself against deepfakes
– Get most out of Gemini in Gmail
– Z AI’s image model trained on Huawei chips
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/geminis-pers
onal-intelligence-upgrade
… -
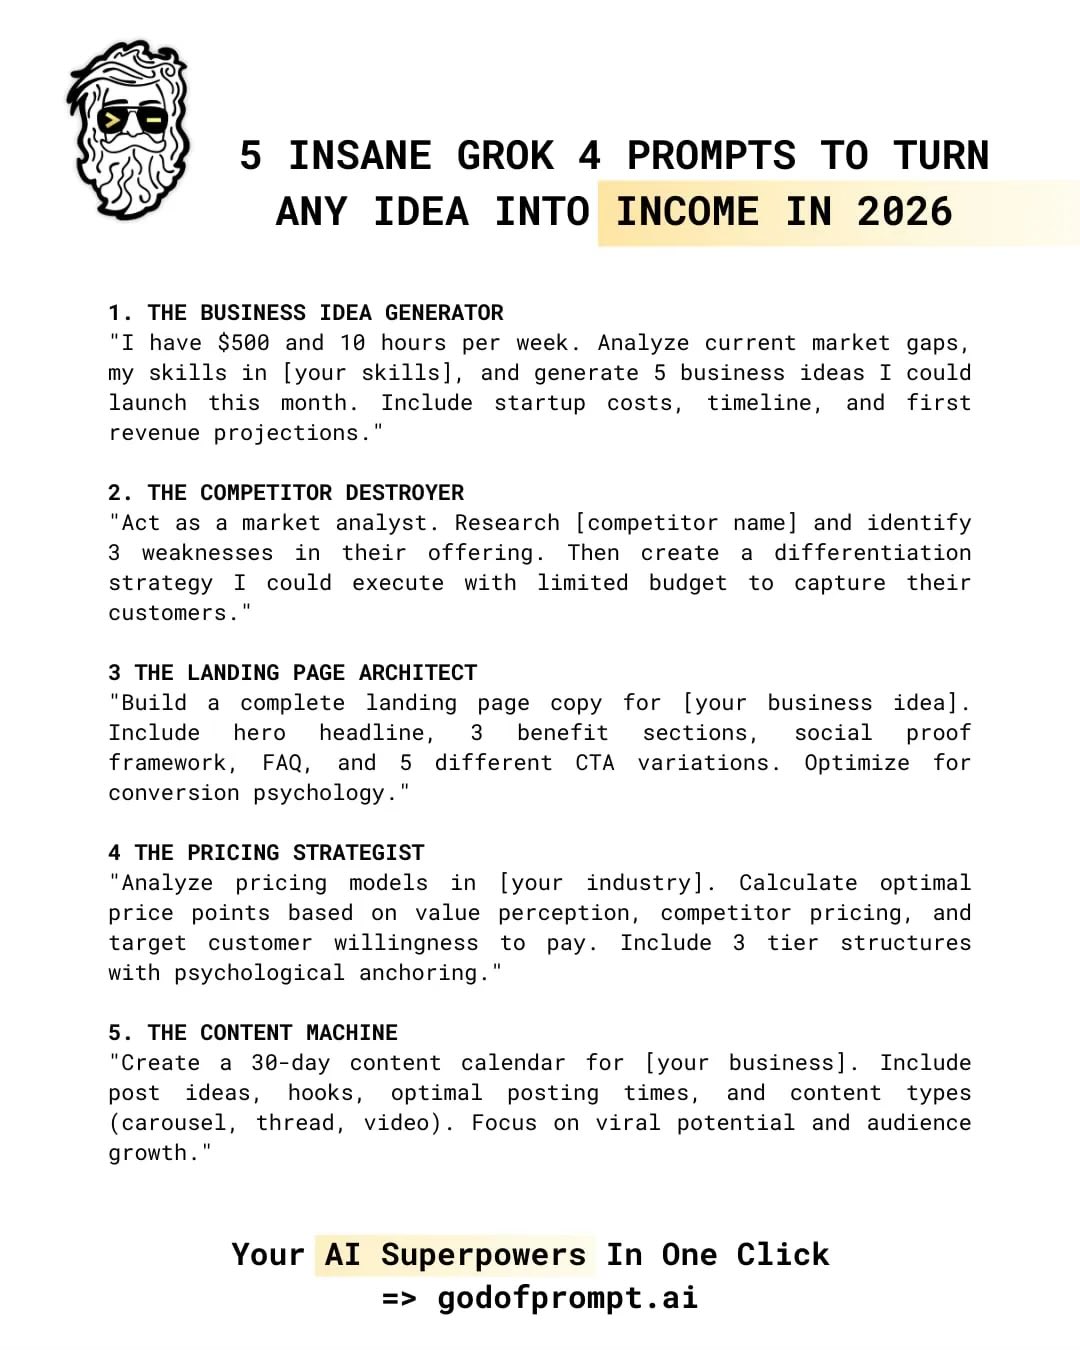
Steal my Grok prompts to create a business in 2026
By
–
Steal my Grok prompts to create a business in 2026 Bookmark for later.
-

Claude’s new writing pattern: not [x], not [y], [z]
By
–
new writing pattern emerged in Claude: not [x].
not [y].
[z]. -
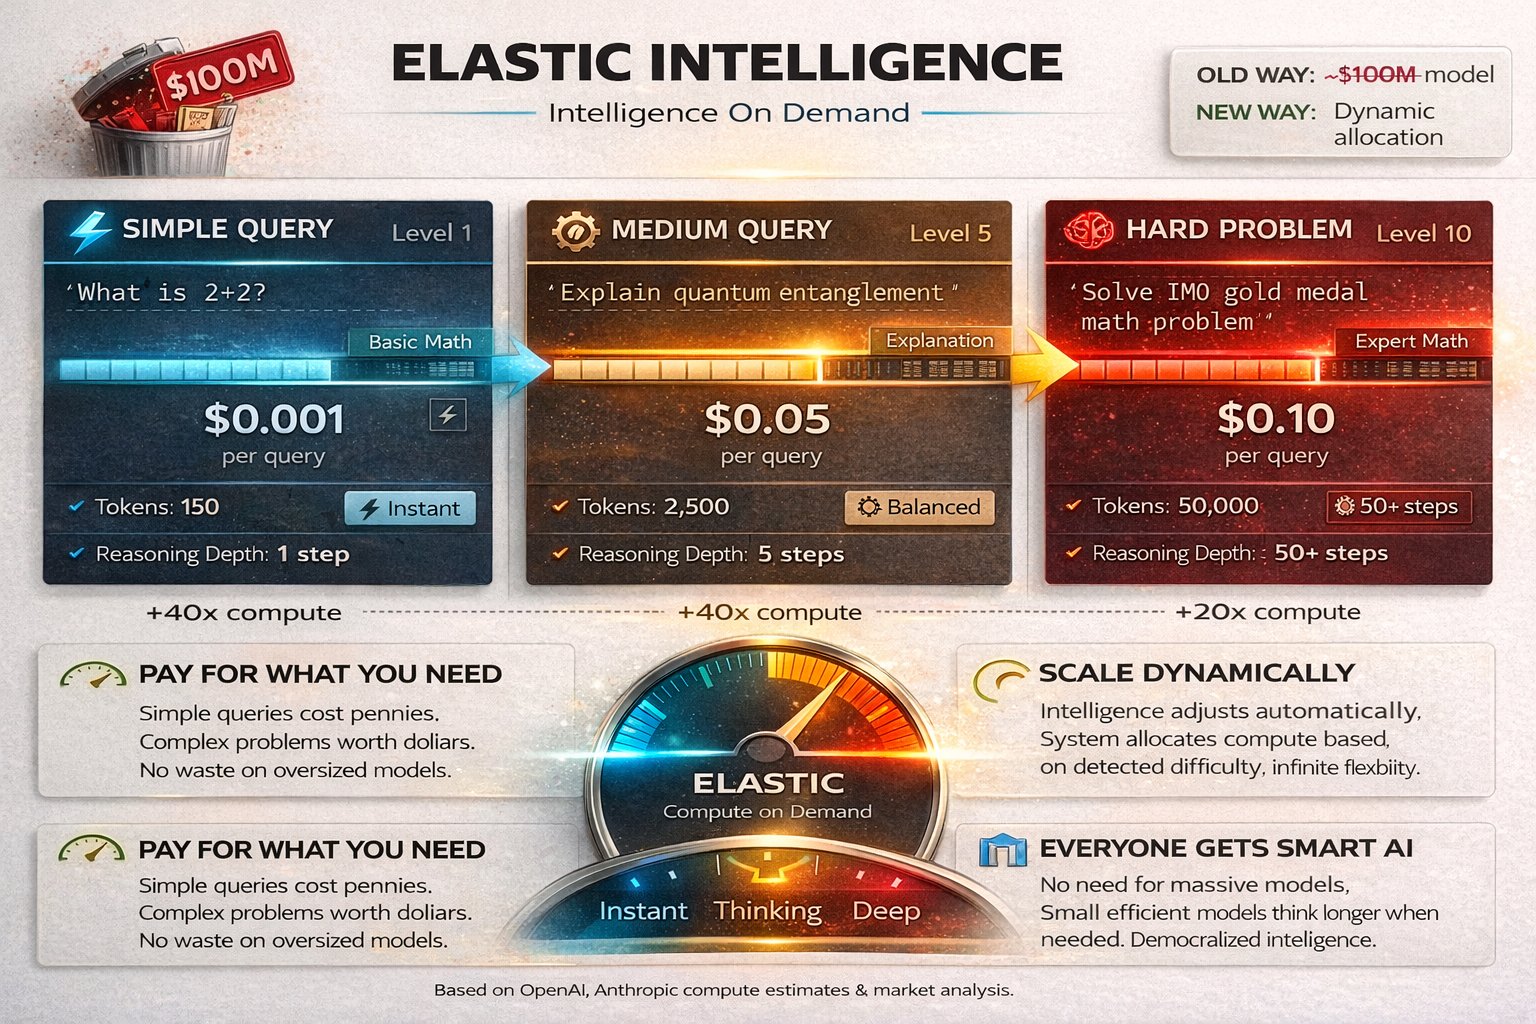
Dynamic compute allocation adjusts thinking time based on query difficulty
By
–
Dynamic compute allocation is the killer feature. Easy query: 0.1 seconds, minimal cost
Medium complexity: 2 seconds, moderate cost
Hard problem: 60 seconds, deep reasoning The model automatically adjusts thinking time based on difficulty. Pay for intelligence only when you -

Elastic Intelligence: small model, dynamic per-query scaling
By
–
This makes $100M training runs obsolete. Why spend months training a massive model when you can deploy a smaller one and scale intelligence dynamically per query? Hard math problem? Give it 60 seconds to think.
Simple question? Answer instantly. Intelligence becomes elastic -

Economics flip: small models with more inference match GPT-4
By
–
The economics just flipped completely. Training GPT-4: $100M+ in compute
Inference scaling: $0.10 per complex query You can make a 7B model as smart as GPT-4 by letting it think 100x longer at inference. Smaller models + more thinking time = beats bigger models at fraction of -
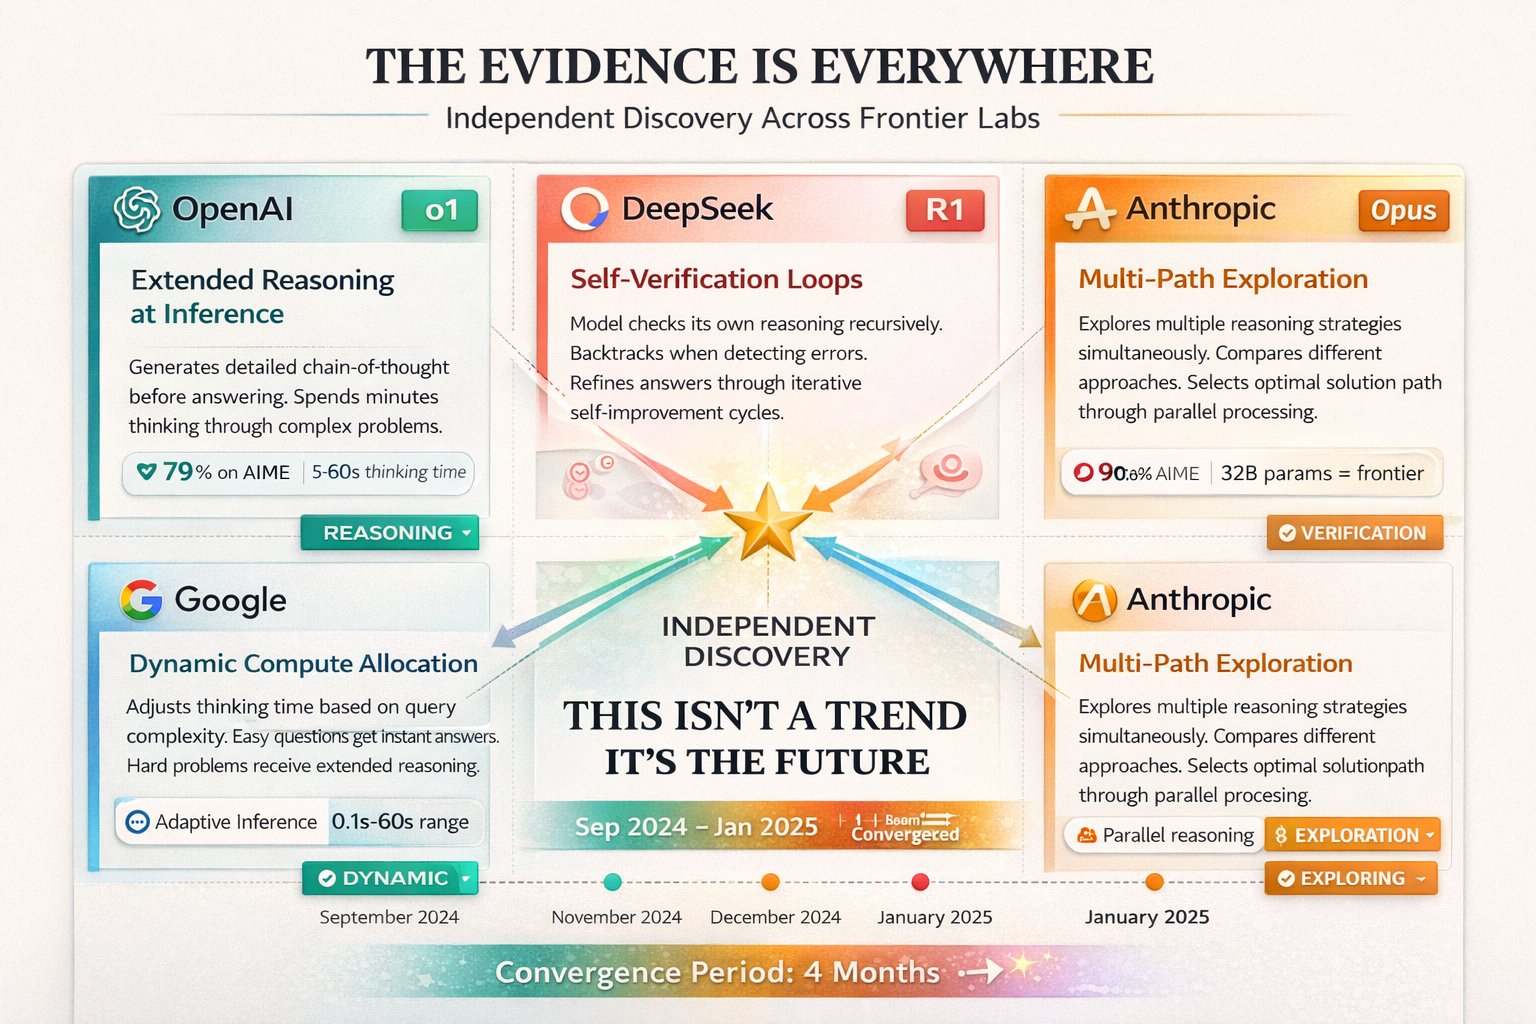
All frontier AI labs discover identical reasoning breakthrough
By
–
The evidence is everywhere: – OpenAI o1: Extended reasoning at inference
– DeepSeek-R1: Self-verification loops
– Gemini 2.0 Thinking: Dynamic compute allocation
– Claude Opus: Multi-path exploration Every frontier lab independently discovered the same breakthrough. This isn't -
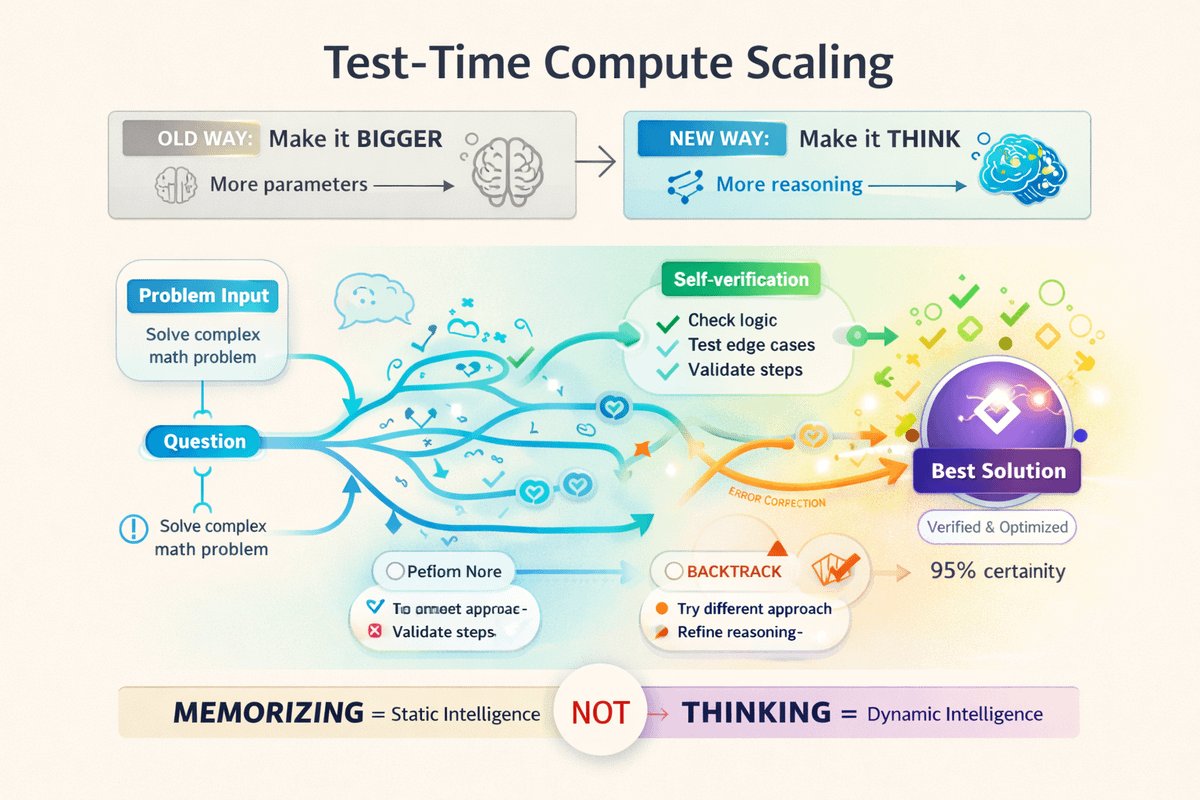
OpenAI’s o1 demonstrates smarter models via inference-time compute
By
–
OpenAI's o1 proves you can make models smarter by making them "think longer" at inference not training bigger models. DeepSeek, Google, Anthropic all pivoting to test-time compute. Training wars are over. The inference wars just started. Here's the paradigm shift happening