Read our full study: https://
langchain.com/blog/designing
-efficient-verifiers-for-legal-agents
…?
ENTERPRISE AI
-
Full study on efficient verifiers for legal agents
By
–
-
Modernization: now an integral part of AI strategy
By
–
Companies running AI at scale have made a strategic shift: They have stopped treating modernization as an IT project. They have started to view it as an integral part of the AI strategy. Examples: →
-
Easy AI demos, hard production: weaknesses exposed
By
–
Here is the uncomfortable reality I observe in companies: AI demos are easy. AI in production is not. Once AI moves past the pilot stage, it begins to expose every weakness in the foundation: → Fragmented systems
→ Applications -
AI pilots fail mainly because of the company, not the model
By
–
Most AI pilots do not fail because the model is weak.
— Ronald van Loon (@Ronald_vanLoon) 4 juin 2026
They fail because the enterprise underneath it was never built for production AI.
→ Data volume
→ Latency
→ Deployment cycles
→ Legacy dependencies
→ Technical debt
This is the infrastructure problem nobody is… pic.twitter.com/pVbkLn2f1uMost AI pilots do not fail because the model is weak. They fail because the underlying company was never designed for production AI. → Data volume
→ Latency
→ Deployment cycles
→ Legacy dependencies
→ Technical debt It's -
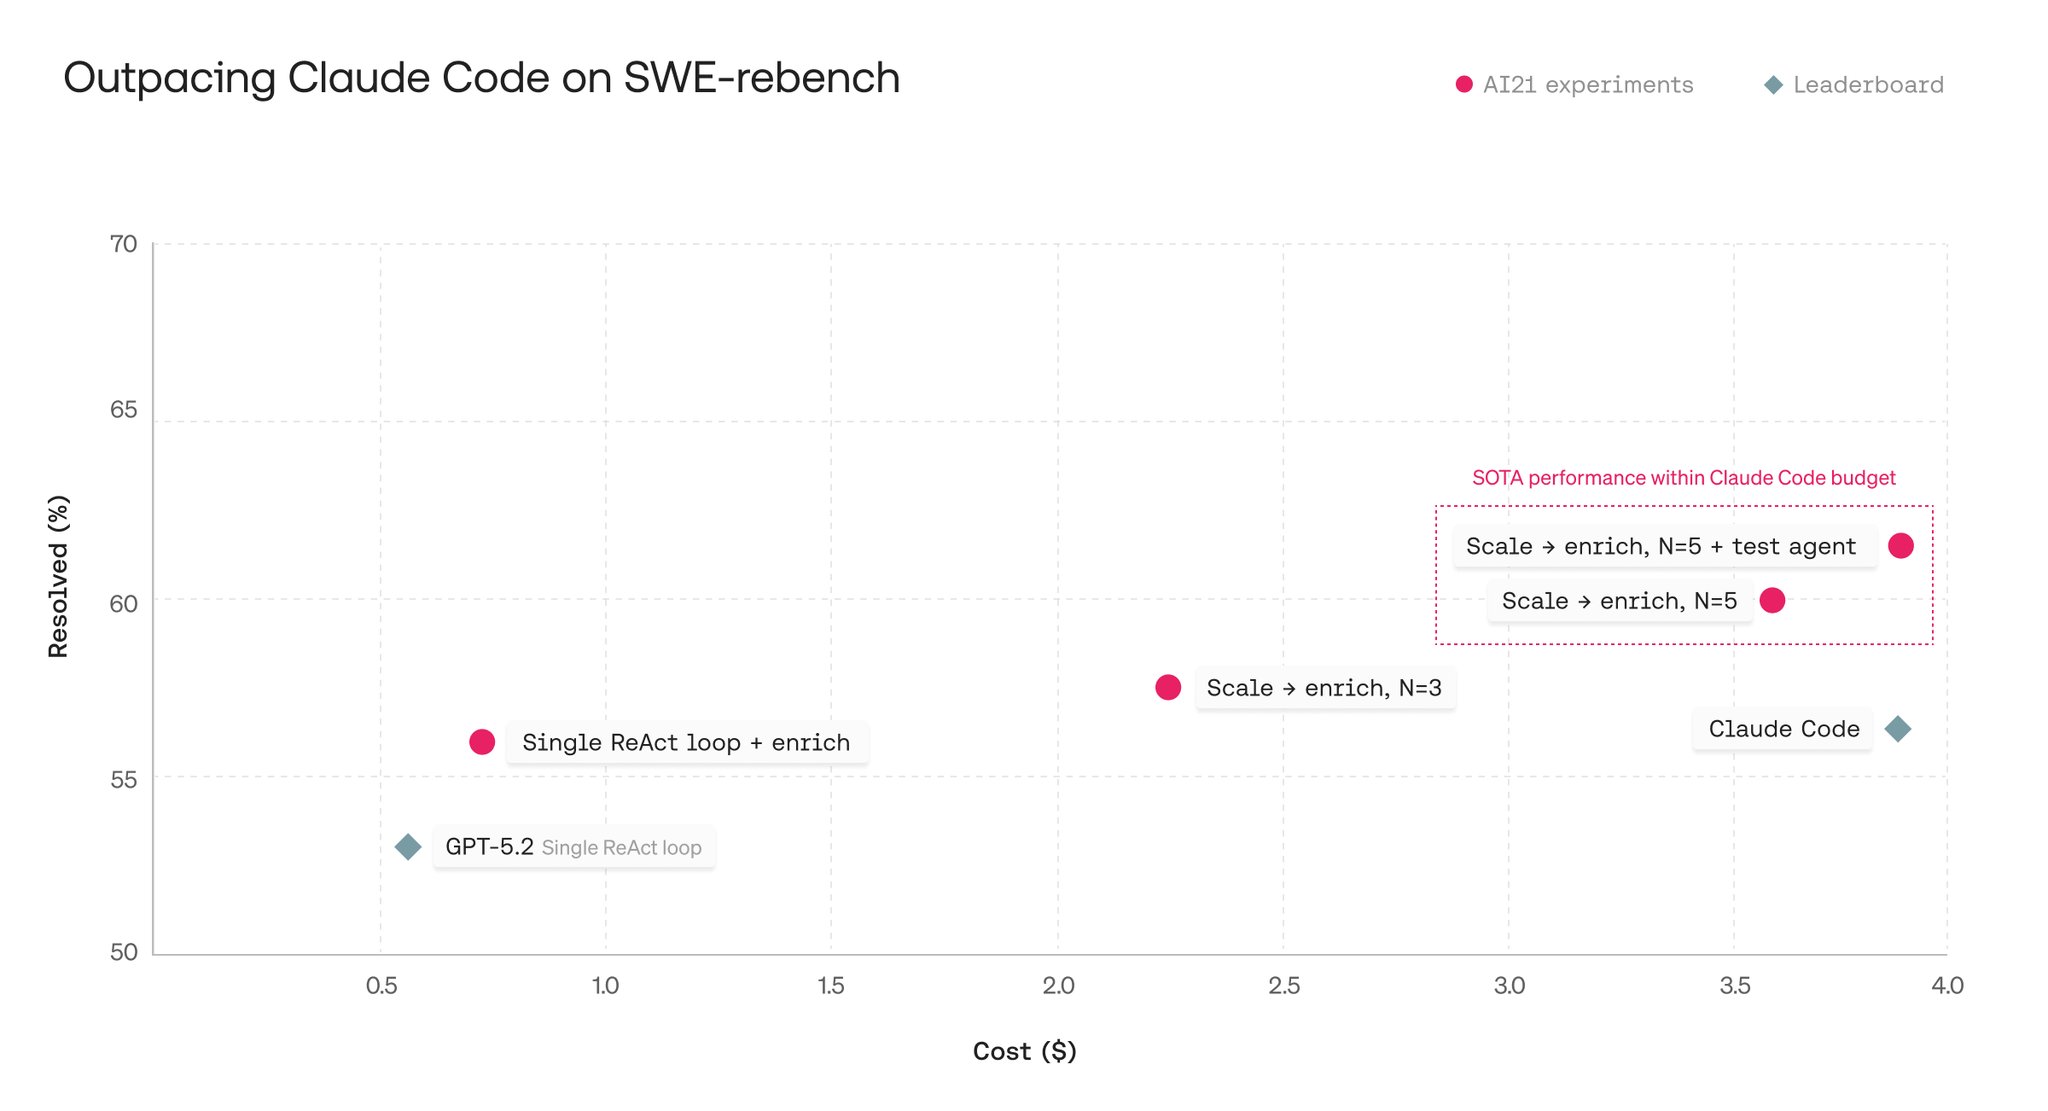
AI21 Labs surpasses Claude Code in efficiency and performance with Test Agent.
By
–
4/5 Still came in ~$0.30 under Claude Code’s spend at a similar score. So we added a lightweight Test Agent that writes repo tests and filters failing patches, pushing our final result to 60.9% – surpassing Claude Code (60.9% vs 56.2%) at the same cost.
-
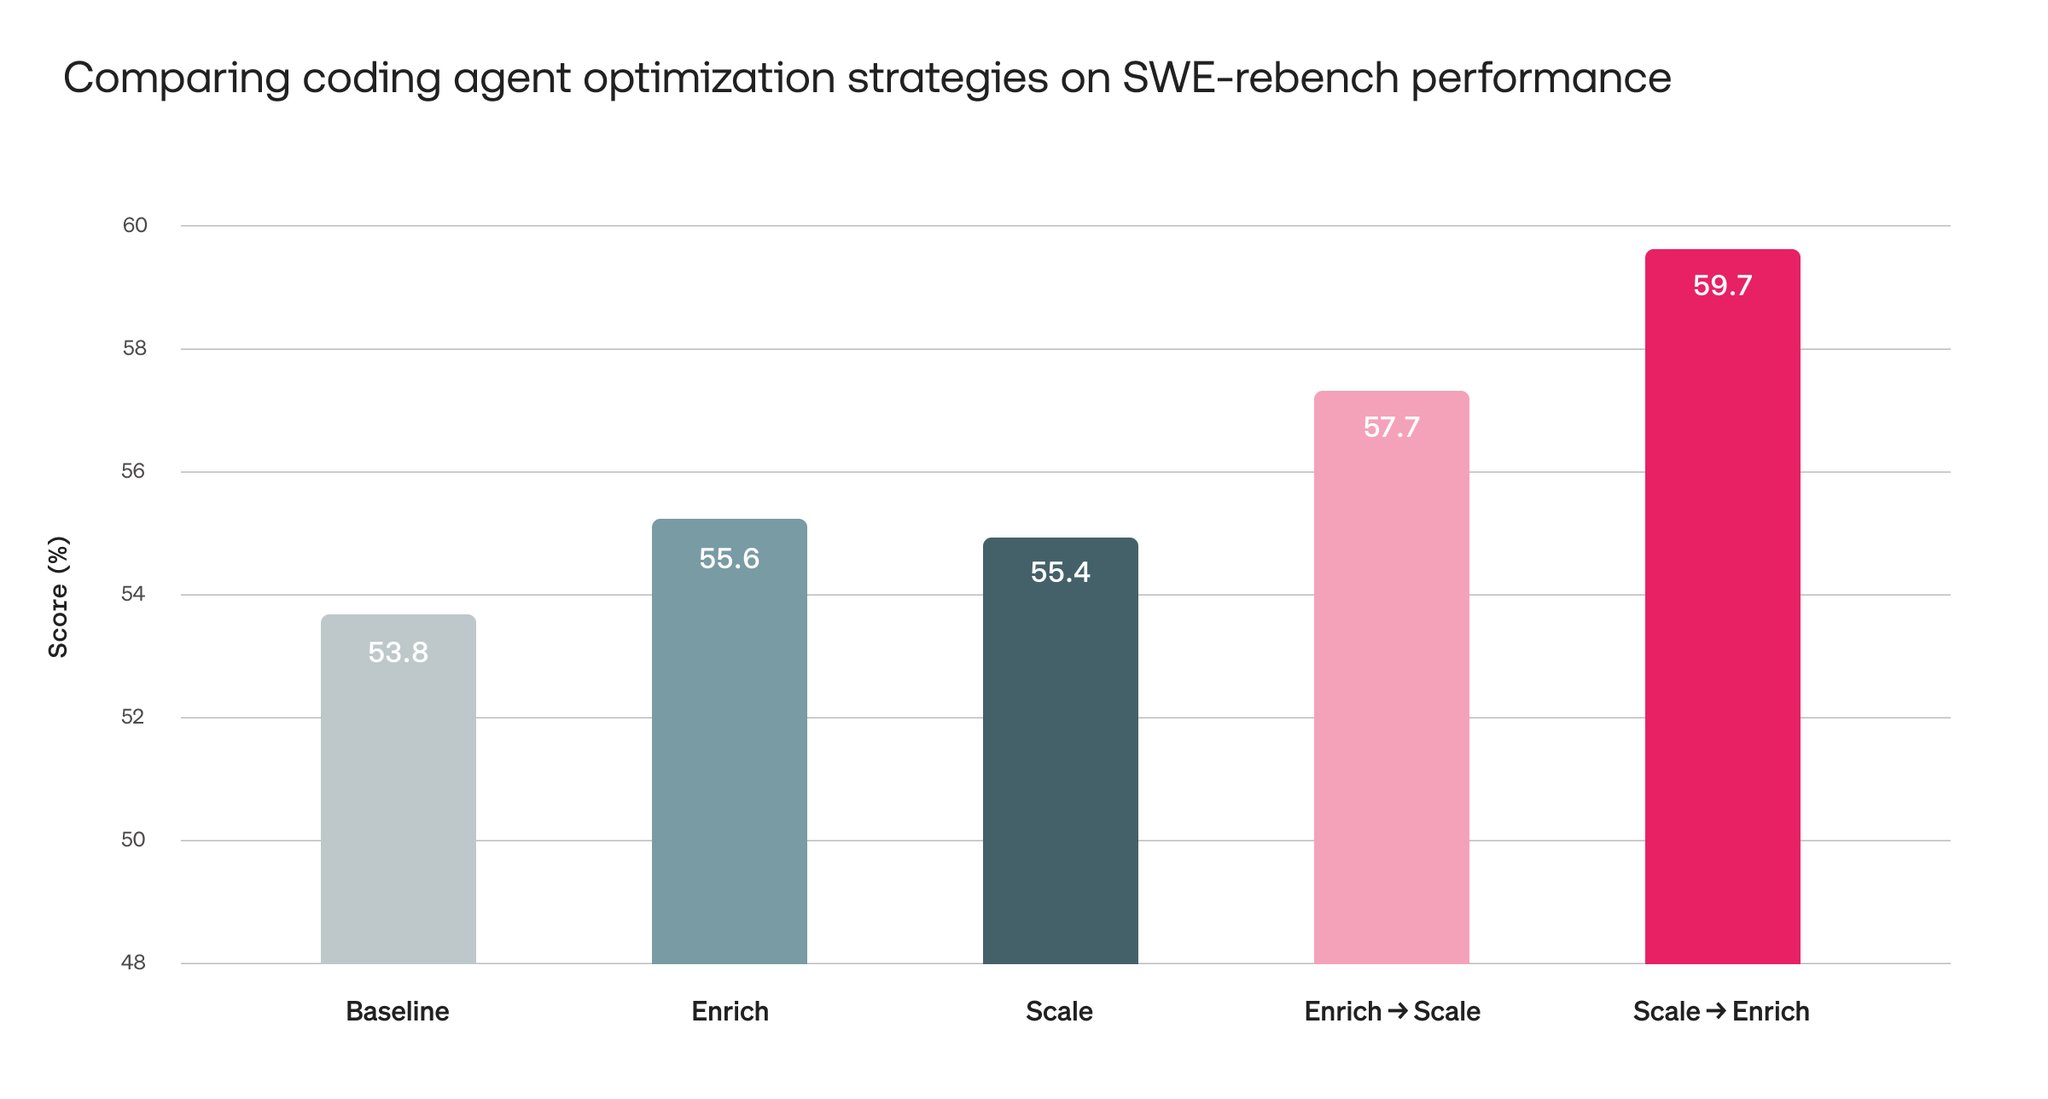
AI21 Labs: ReAct Agent Performance with Enrichment and Scaling Strategies
By
–
2/5 Started with a baseline: classic ReAct agent (GPT-5.2), single Docker-terminal tool. Baselines on the slice: vanilla 53.8%, enrich-only 55.6%, scale-only (n=5 + LLM judge) 55.4%, enrich-then-scale 57.7%.
-
LangSmith Engine reviews traces, learns from usage, updates Context Hub
By
–
You can use LangSmith Engine to review your agent traces to find bugs and areas for improvement across agent prompts + code. Between runs, the agent can review conversations, learn from real usage, and update Context Hub files.
-
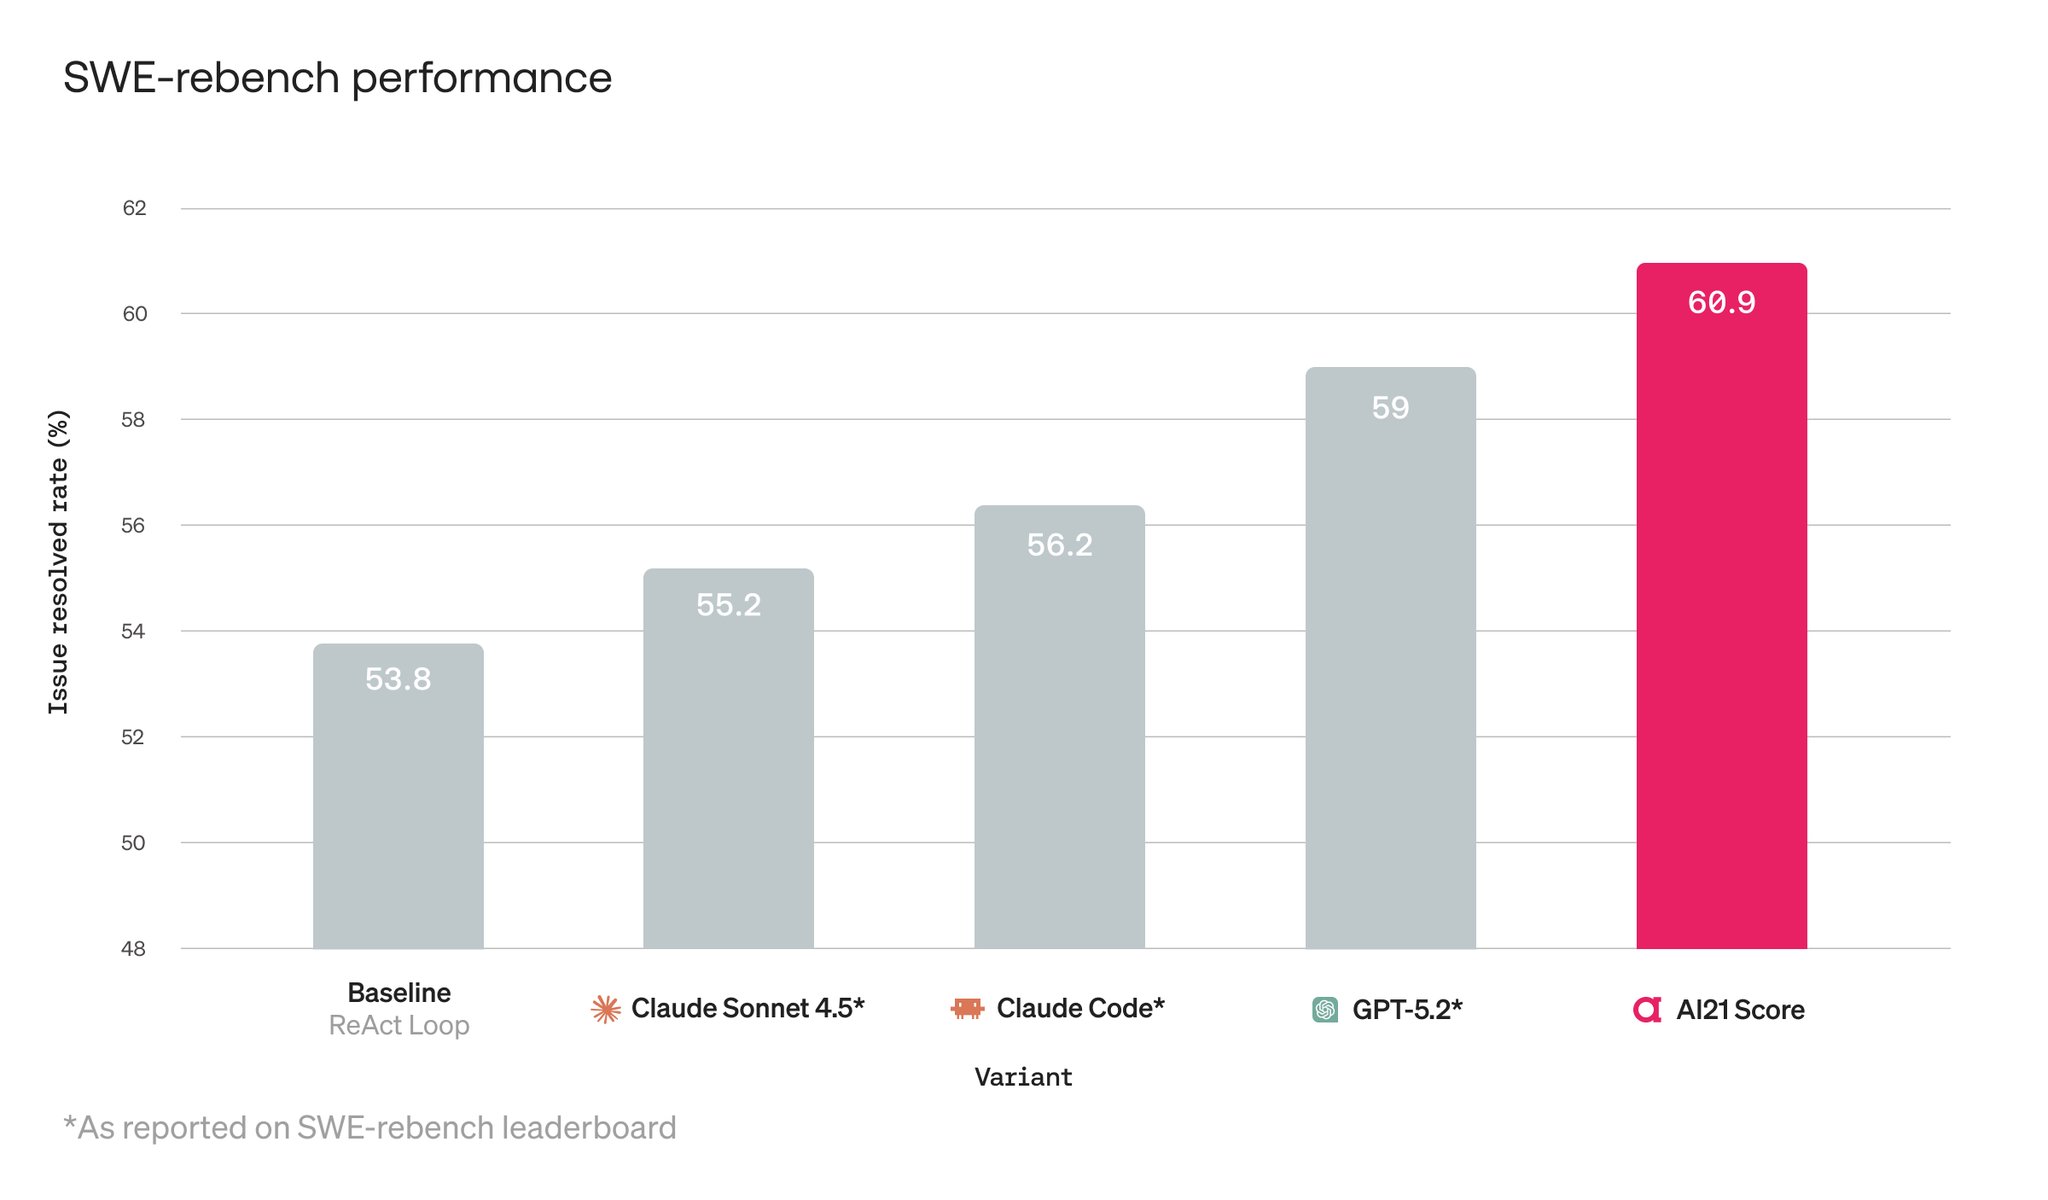
AI21 Labs: Reversing agent pipeline order achieves SOTA results
By
–
1/5 Our latest Labs in Front piece: Agent pipeline order matters. By reversing a common agent recipe – scale first, enrich second – we reached SOTA on a Dec ‘25 to Mar ‘26 slice (123 issues): 60.9%.
-
Rumor: $500M monthly Anthropic bill, possibly Amazon, unlikely staff caused it
By
–
There was a rumor that a company spent $500M in a month on their Anthropic bill recently, and another rumor that it was Amazon Given they only just gave their staff access I think it's unlikely the staff ramped up to $0.5B that quickly!
-
NVIDIA Nemotron 3 Ultra: Open Model for Agentic Tasks
By
–
Introducing NVIDIA Nemotron 3 Ultra.
— NVIDIA (@nvidia) 4 juin 2026
A frontier smart open model built for long-running agents that need to plan, reason, use tools and keep working across complex coding, research and enterprise workflows.
Up to 5x faster inference and up to 30% lower cost for agentic tasks.… pic.twitter.com/AcHTauUzjmIntroducing NVIDIA Nemotron 3 Ultra. A frontier smart open model built for long-running agents that need to plan, reason, use tools and keep working across complex coding, research and enterprise workflows. Up to 5x faster inference and up to 30% lower cost for agentic tasks.