With unpredictable #EV demand, battery planning is complex for automakers. Explore how AI-driven production planning turns challenges into opportunities: https://
okt.to/ZcBqpE @mvollmer1 @nicochan33 @blueyonder @antgrasso
DATA
-

AI-Driven Production Planning Solves EV Demand Battery Challenges
By
–
-
LLM Training: Fixed Capacity Model Reduces Per-Sample Memorization
By
–
hard to say since we mostly study the average case not the worst case. but I think “filling a fixed capacity” is a useful model for LLM learning, which implies that training on more data will force models to memorize less per-sample
-

Nine Distance Measures in Data Science with Algorithms
By
–
9 distance measures in data science w/algorithms (v/
@MaartenGr
). -
AI agents scrape web and download YouTube videos offline
By
–
Agents can scrape the web and download files now.
— AI Breakfast (@AiBreakfast) 3 juin 2025
You can even download YouTube videos and save them locally offline with this AI Agent @genspark_ai
Genspark's download Agent can rip basically anything off of the internet and save it, even when it shouldn't be able to.
Very… pic.twitter.com/skq0xfCNFCAgents can scrape the web and download files now. You can even download YouTube videos and save them locally offline with this AI Agent @genspark_ai Genspark's download Agent can rip basically anything off of the internet and save it, even when it shouldn't be able to. Very
-
Kaggle Competitions Grandmaster: Real World Data Application
By
–
Indeed, probably the best way to *directly* apply those skills to the real world data. And the reason I became a Kaggle *competitions* grandmaster. 😉
-

Test Examples Extractability and Privacy in Saturated AI Models
By
–
– hrunning these experiments in a clean setting with perfectly deduplicated texts tells us a lot about privacy: – once capacity is sufficiently saturated, the **test examples** are slightly more extractable than the training examples — maybe extraction is a bit of a myth?
– the -
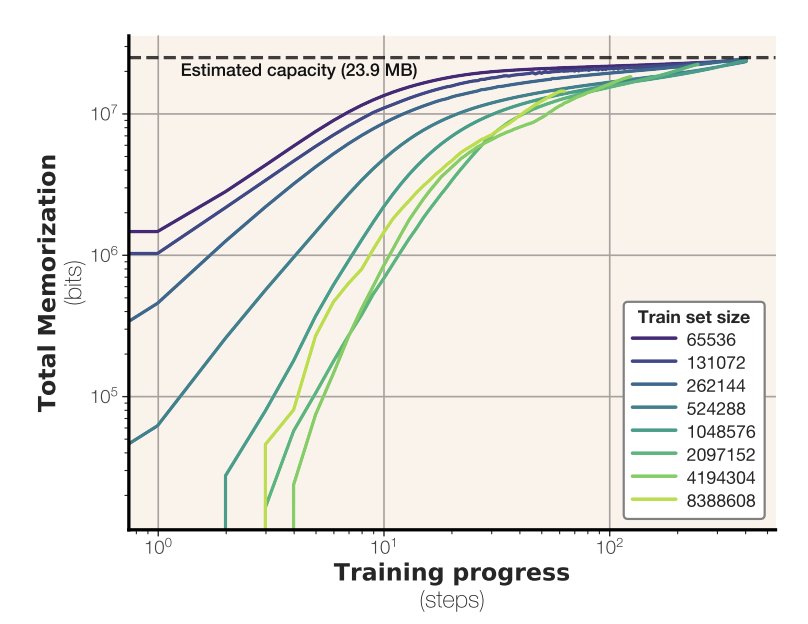
Model Memorization Fixed Capacity Training Saturation Analysis
By
–
we train all of our models until they "saturate" which usually happens around 1M steps using a very large batch size models memorize the same amount, regardless of training datasize meaning they have fixed capacity and instead "spread it thinner" when trained on more examples
-

Measuring Model Memorization with Random Uniform Strings
By
–
this all started from a quest to come up with a proper measurement of model memorization it's hard to compute *per-example* memorization, because models "share" info between datapoints so we start with random uniform strings, where sharing isn't possible. and we get this:
-

SAS Hackathon 5th Year Global Competition Launches June
By
–
It is coming up on that time again… the annual #SASHackathon kickoff celebration! For our 5th year, we're bringing coders, data scientists and analytics gurus together globally to compete in our month-long event. Join us online June 11 to get registration details and hear