“There is no way to progressively discover and deal with such isolation violations, just enabling 6 mode and praying.” https://
mjtsai.com/blog/2024/10/0
1/swift-concurrency-and-objective-c/
…
COMPUTING
-
Swift Concurrency Isolation Violations: Progressive Discovery Challenges
By
–
-

Untether AI Partners Ampere for Energy-Efficient AI Inference
By
–
We've joined the AI Platform Alliance with @AmpereComputing
! See our partnership in action at #Yotta2024 – we're showcasing our record-breaking speedAI240 Slim PCIe card. Visit us in #601F, Oct 7-9, to see the future of sustainable, high-performance #AI. https://
untether.ai/untether-ai-jo
ins-forces-with-ampere-to-provide-arm-based-energy-efficient-ai-inference-solutions/
… -
RAS Blackwell GPU Isolation and Host Boot Issues
By
–
RAS is blackwell+, so TBD. no single GPU isolation, whole host gets booted.
-
Scheduler Complexity and Infrastructure Provisioning Strategies
By
–
the scheduler side of things is a whole another level of complexity. we dont reprovision from scratch though.
-
Training Machine Learning Models on 10k H100 GPUs
By
–
"How to train a model on 10k H100 GPUs?"
has now been immortalized on my blog: https://
soumith.ch/blog/2024-10-0
2-training-10k-scale.md.html
… -

Bossard’s Smart Manufacturing Solutions for Industry 4.0
By
–
Bossard’s Journey to Industry 4.0: Smart Solutions for Modern Manufacturing https://
buff.ly/3Tx1ljk #sponsored #bossard_iiot #IMTS24 #SmartFactory #IIoT @IIoT_World @lucianilie15 via @fogoros -
HBM Memory in Switches: Critical Infrastructure for AI Scale
By
–
one more thing to add.
at this scale, we also have to adjust the actual packet routing algorithms in our switches and NICs, to be able to load-balance well. Did you know switches have to have significant HBM memory as well (not just GPUs) because as the packets queue up, they -
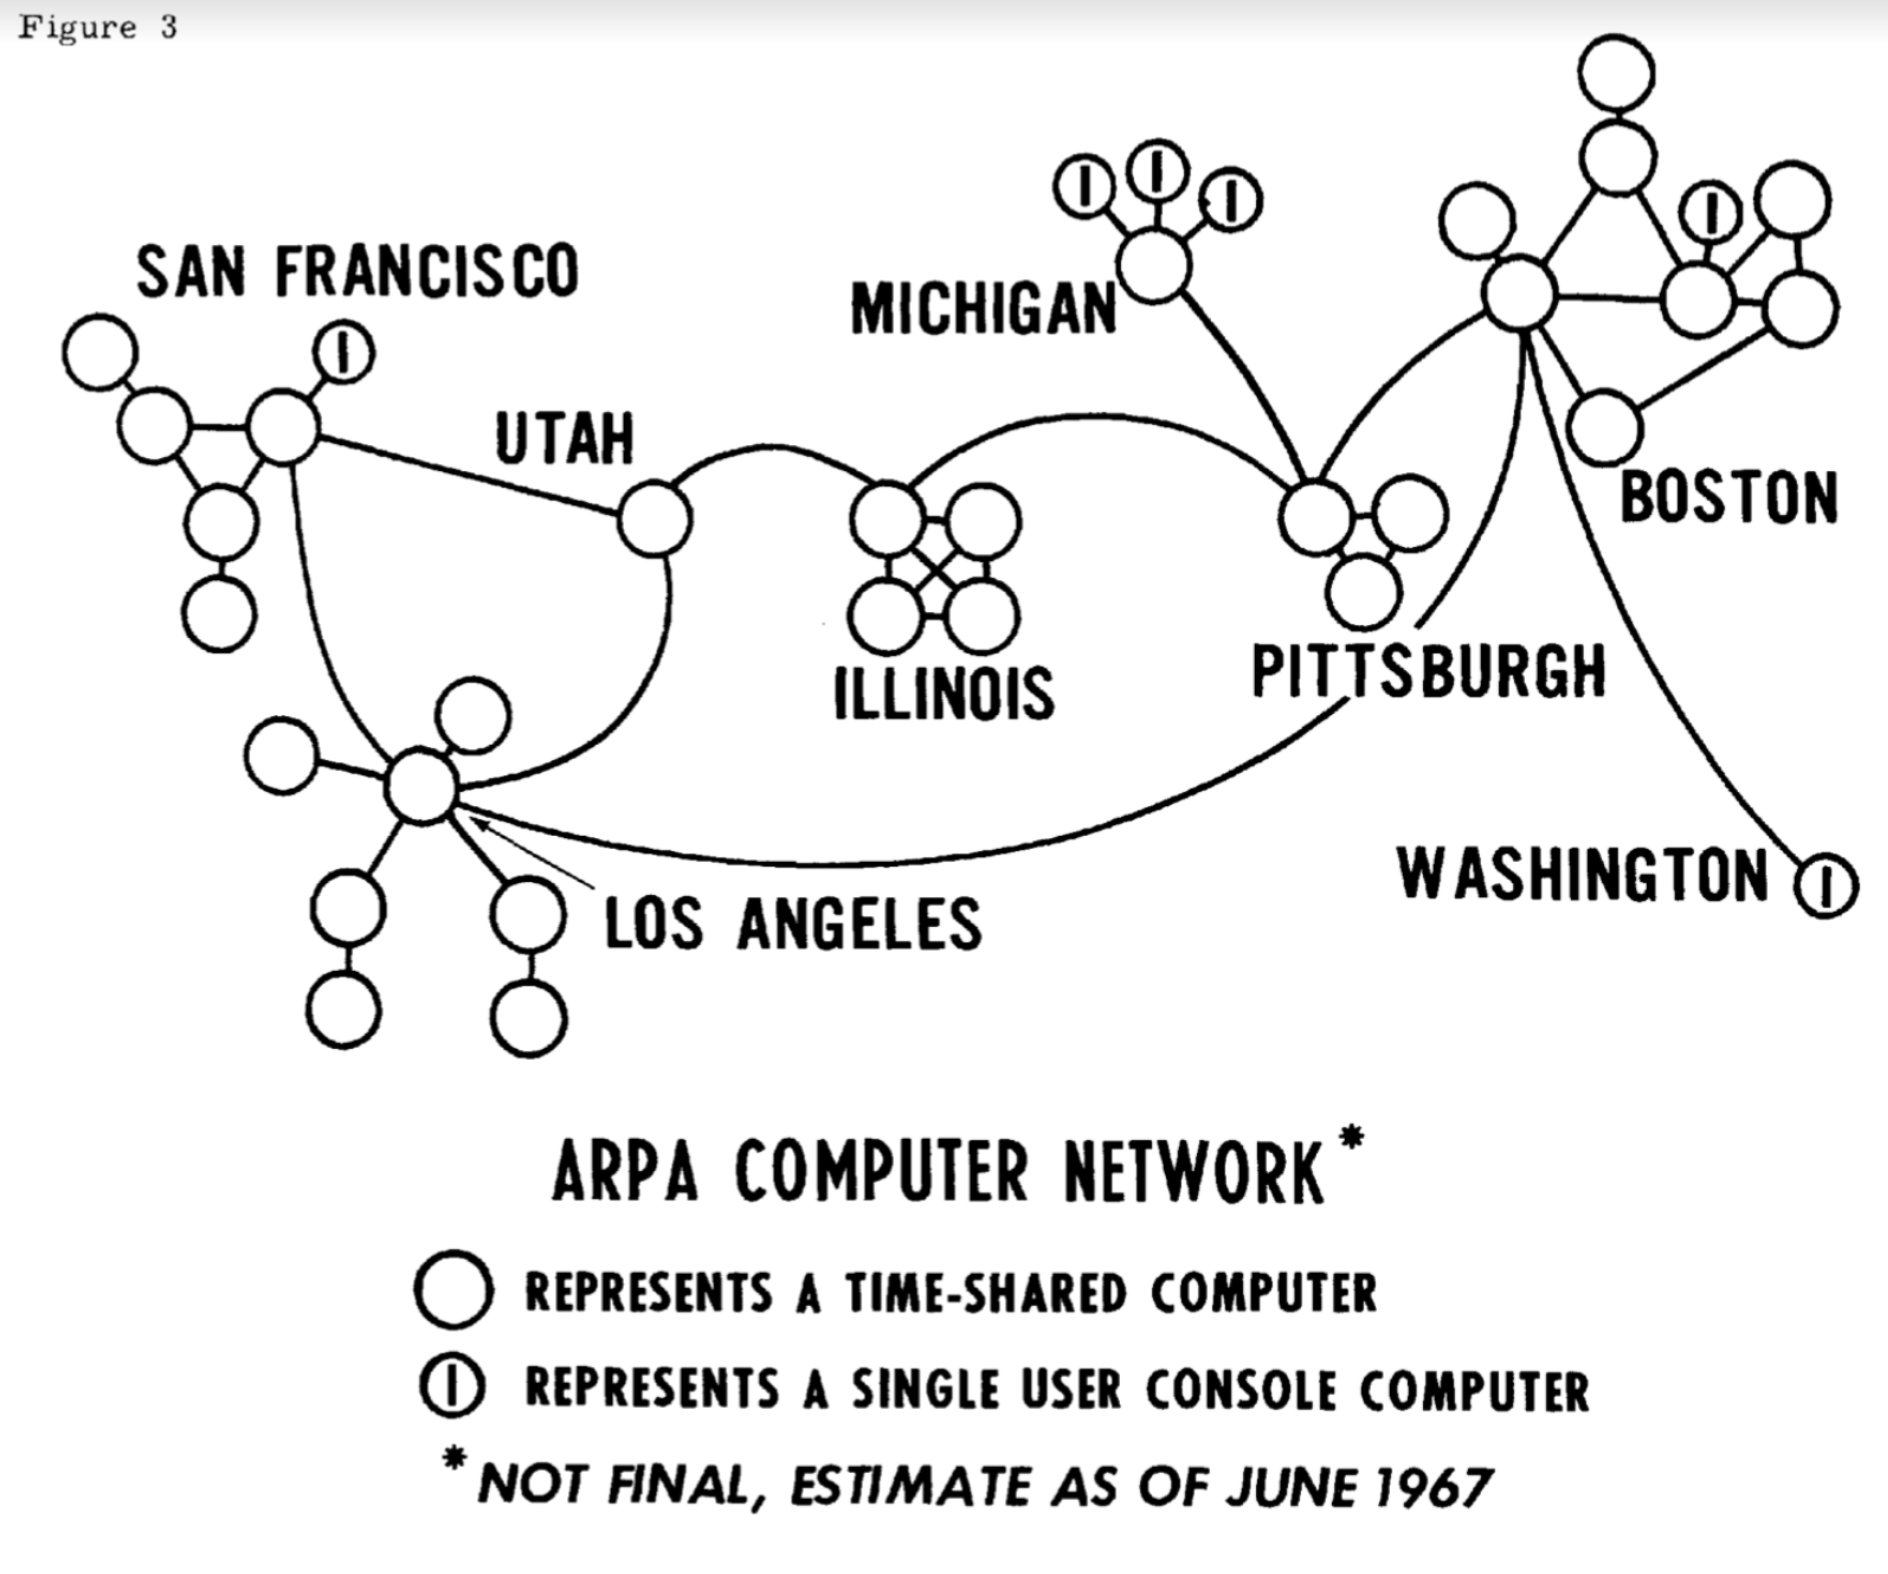
Larry Roberts ARPANet 1967 networking breakthrough
By
–
#otd in 1967 Larry Roberts presented his idea for an “ARPANet” for connecting multiple computers together across the United States. Full paper: https://
bit.ly/3TLjqKP -
Llama 3.2 Launches with Record-Breaking Inference Speed Performance
By
–
Llama 3.2 is here and we're faster than ever! We've been independently verified as the fastest #AI #Inference on @AIatMeta
's Llama 3.2 1B & 3B with … 2470 tokens/sec on 1B 1566 tokens/sec on 3B … all running at full-precision! Start developing