2/ Next problem → sluggish AI retrieval. Scaling it up is notoriously difficult. This Vector Search Perf module walks you through diagnosing slow queries with Atlas Metrics. PLUS actually managing memory sizing and quantization in full production > https://
fandf.co/4b6Q3uW
COMPUTING
-
Vector Search Perf module for slow AI retrieval diagnosis
By
–
-

Jalapeño: new LLM inference hardware with incredible perf per watt
By
–
Introducing Jalapeño — designed from scratch for LLM inference over nine months, accelerated by our models. Perf per watt looking incredible.
-
AI solves 18 medical cases of children abandoned by doctors
By
–
Urgent: An AI just solved 18 medical cases that doctors had abandoned. All children with rare diseases that no one could identify. Here is how the AI did it:
-
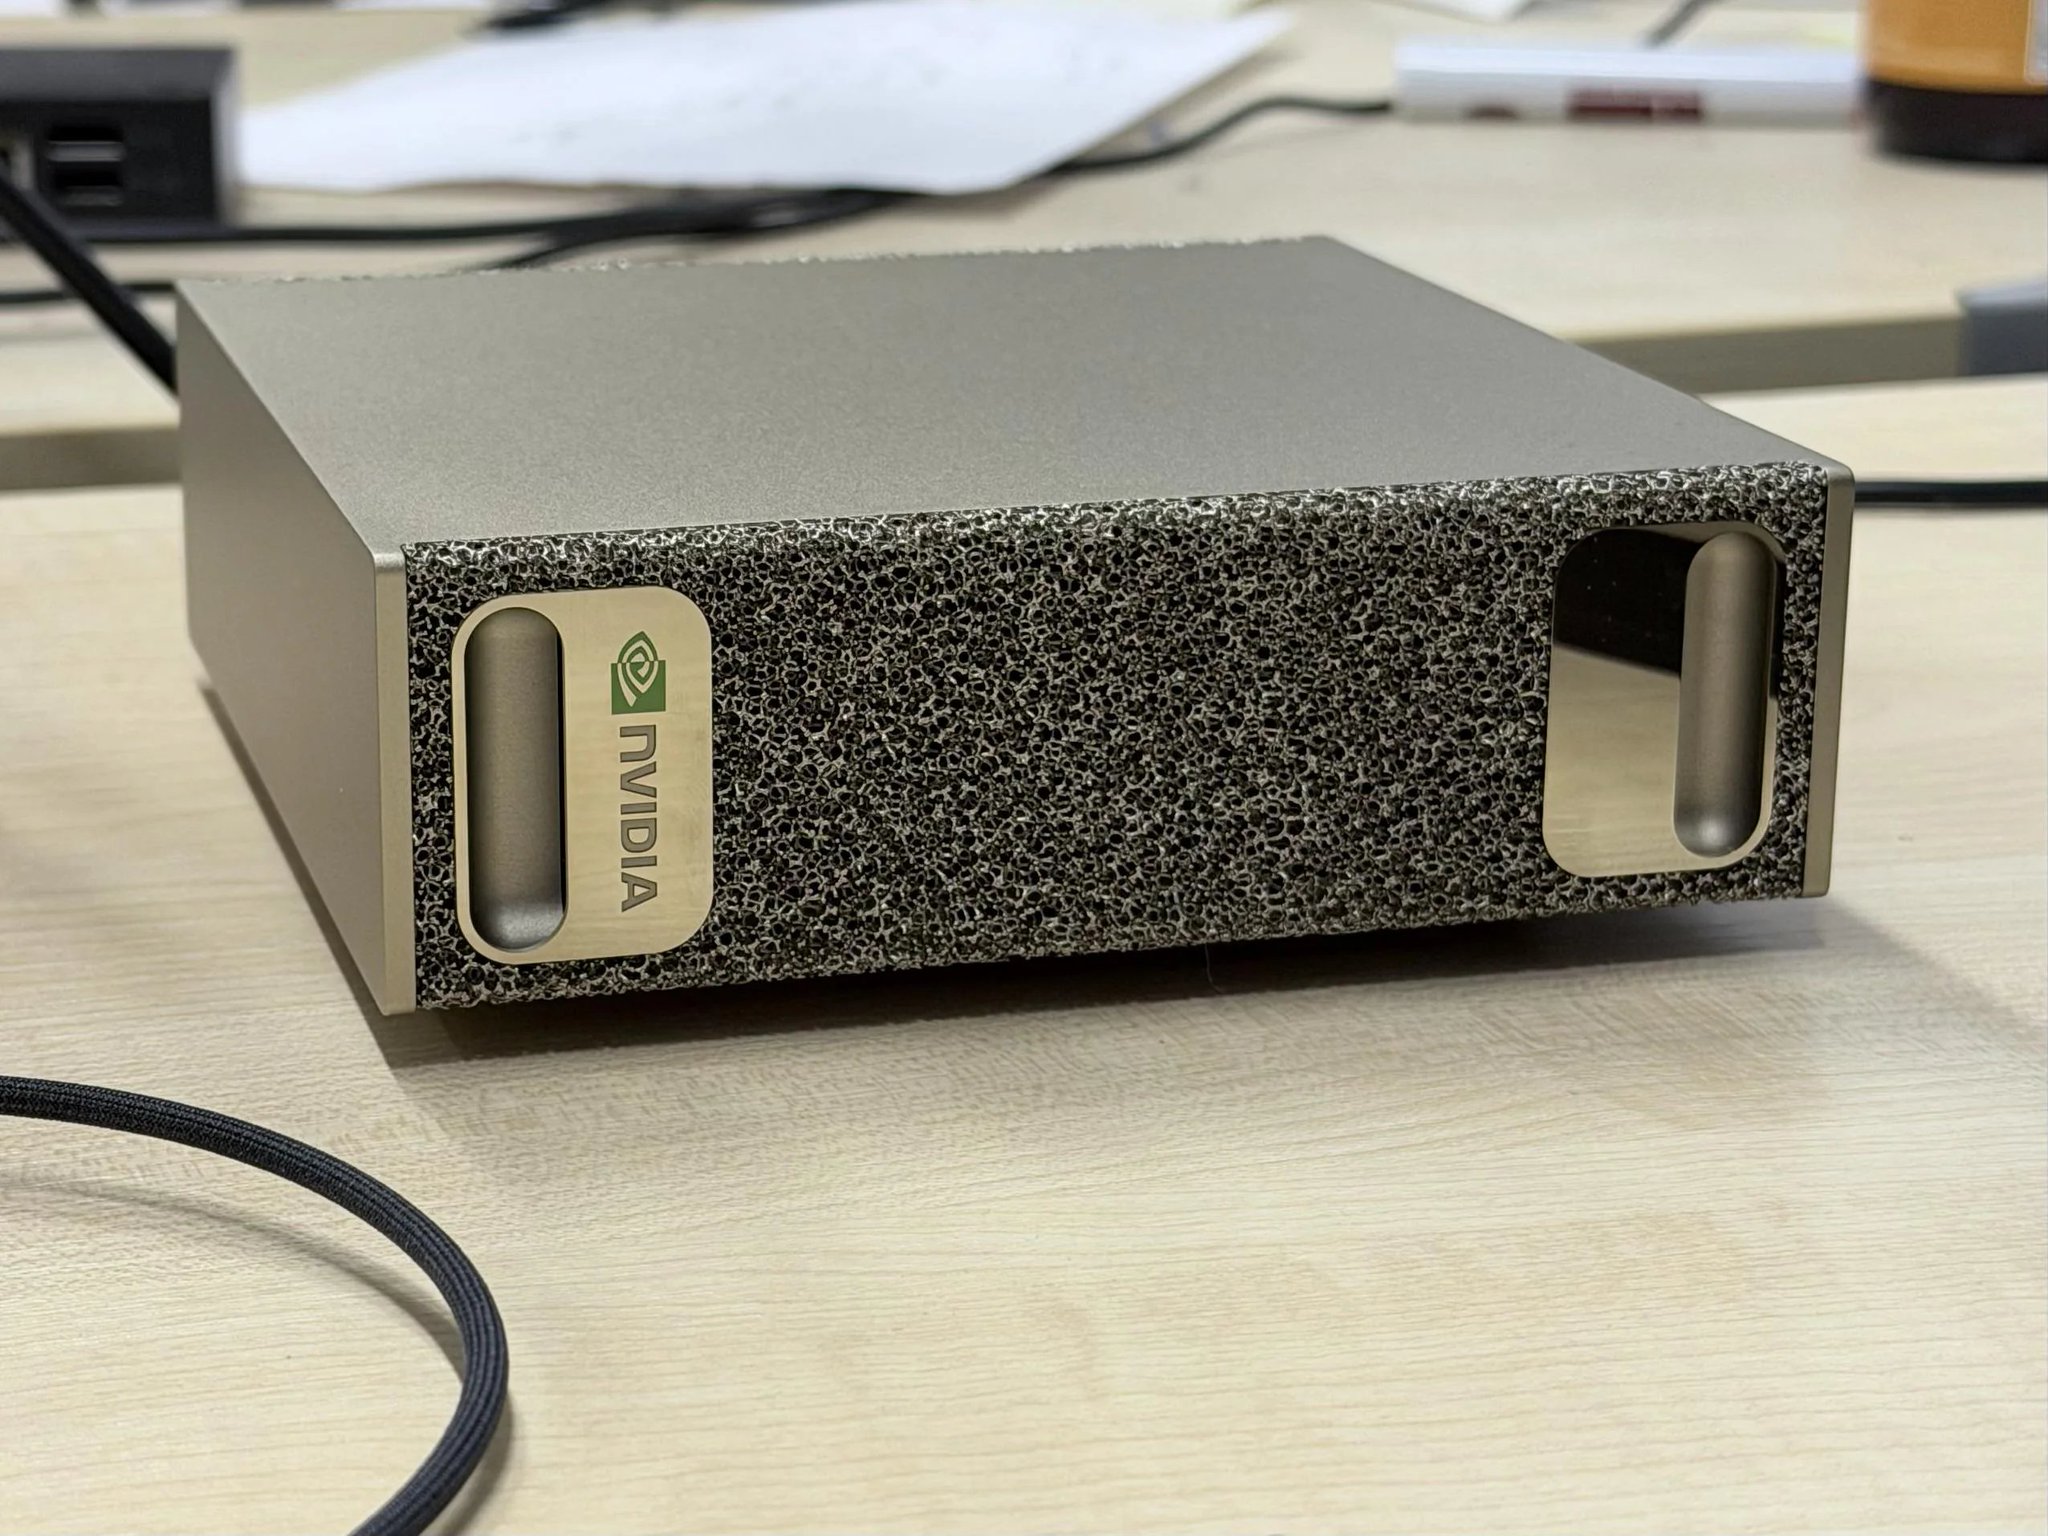
DGX Spark: The Quiet Dark Horse of Local AI
By
–
DGX Spark is becoming the quiet dark horse of local AI.
-
Tips for Automatically Cleaning Duplicate Browser Tabs with Codex
By
–
Here's a little browser use trick I've been loving recently – it's very smooth. I'm the kind of heavy user who opens dozens or hundreds of tabs at once, and they often end up duplicated. Later, I added a trigger task in Codex. Every time I lock my screen or go offline, Codex automatically calls browser use to clean up and close redundant, duplicate tabs – completely hands-free. This trick works with Codex and CC.
-

Record ASIC development in nine months
By
–

Absolutely insane: "Jalapeño was co-developed, from initial design to production, in just nine months, and the custom AI accelerator program represents what we consider the fastest ASIC development cycle ever."
-

OpenAI and Broadcom unveil the Jalapeño chip for LLM
By
–
NEW OPENAI CHIP! OpenAI and Broadcom have just announced the fruit of their collaboration, Jalapeño, their new chip for LLM inference, designed in only 9 months! The chip adapts to the inference needs of OpenAI's roadmap, obtaining,
-

OpenAI and Broadcom Unveil Revolutionary AI Chip
By
–


OpenAI has announced its first AI chip, designed and produced in partnership with Broadcom. > New state-of-the-art in performance per watt.
> OpenAI models were used to accelerate its development.
> Will be deployed at gigawatt scale. -

Jalapeño chip tests with ML workloads including GPT-5.3-Codex-Spark
By
–
Engineering samples of the Jalapeño chip run machine learning workloads in the lab at target production frequency and power, including GPT-5.3-Codex-Spark. I hope this is not the limit.
-

OpenAI unveils Jalapeño, its custom AI chip for LLM inference
By
–
OpenAI just unveiled Jalapeño, its first custom AI chip built from the ground up for LLM inference. It's OpenAI going deeper into the full stack: chips, cores, memory, network, racks, scheduling, deployment, and product experience.