
Computer use is now available on Microsoft Copilot Studio. User will be able to create agents to operate with desktop and web apps. “computer use is coming to Copilot Studio through an early access research preview”
COMPUTING
-
Modern Neural Networks Rely on Dense Matrix Operations Like Cray Computers
By
–
All of the modern NN work that is accomplishing things is with dense matrix ops — 1 mat mul forward and 2 back. There are plenty of things Cray vector computers weren’t good at, but dense matmuls was their strong point, and no PC could touch them for nearly two decades. The XMP
-

CoreWeave Launches NVIDIA GB200 NVL72 Access for Customers
By
–
We’re excited to be among the very first to get access to @CoreWeave
’s @NVIDIA GB200 NVL72 systems! In addition to seeing training improvements, we’ve been able to run North on just one Blackwell GPU, enabling customers to start using this hardware in their own environments. -

Claude-3.7-Sonnet and o1 better at Python than JavaScript
By
–


Really interesting: Claude-3.7-Sonnet and o1 are better at Python than Javascript.
In smolagents, we implemented agents that think in code, and of all programming languages we chose python for their thoughts, because we thought it was both
– one of the most accessible, thus -
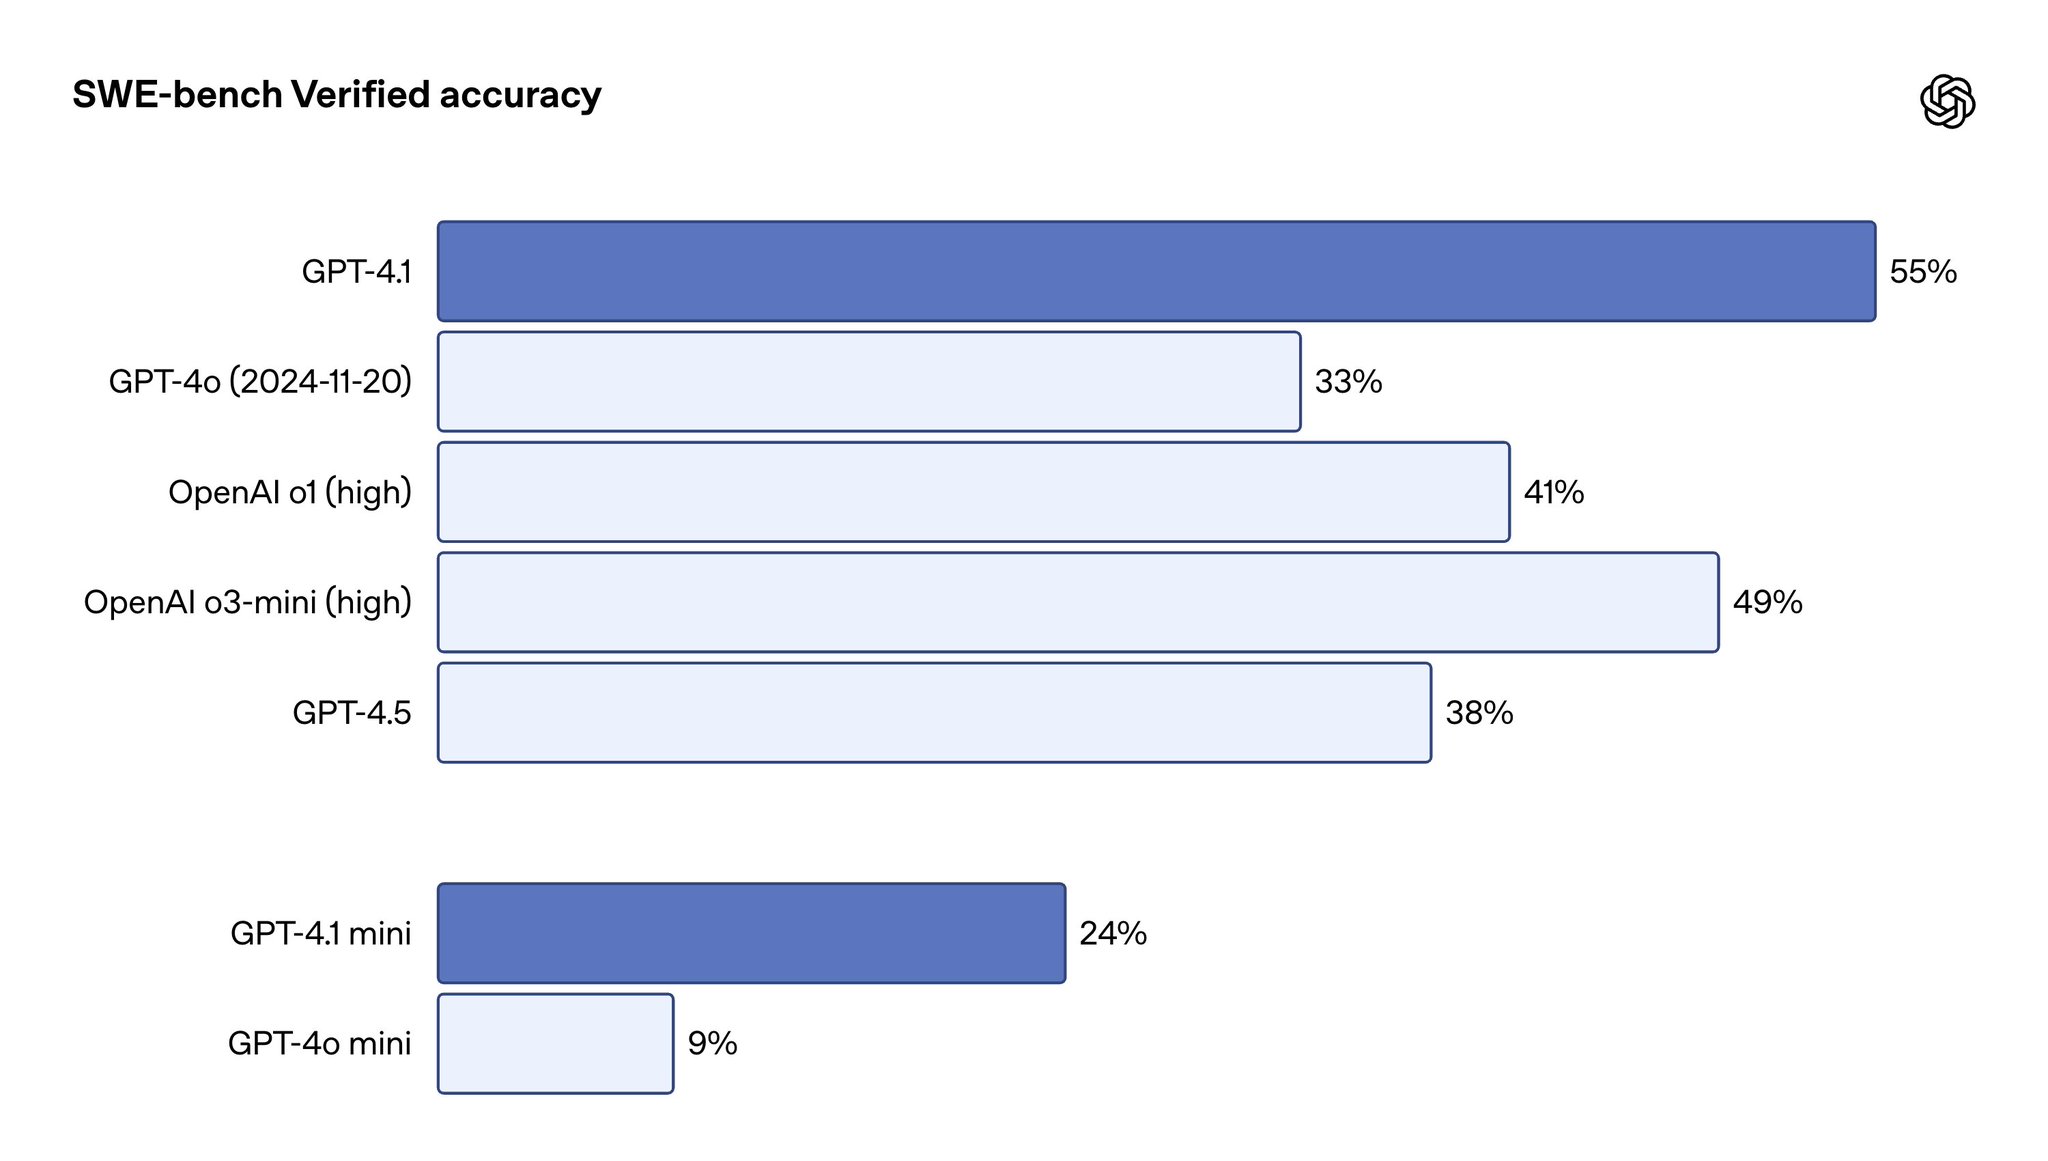
GPT-4.1 Launch: New Model for Developer Excellence
By
–
Welcome to the GPT-4.1 family! Trained with one goal: being truly great for developers. • Best-in-class at coding tasks and instruction following
• 1M token context + better comprehension
• Pushing performance across the latency curve What are your first impressions so far? -

SambaNova Llama4 Maverick Fastest LLM Cloud Performance
By
–
Find someone who looks at you like how devs look at us Experience the FASTEST #Llama4 Maverick on SambaNova Cloud
-
Llama 4 Maverick Reaches 800 Tokens Per Second Speed
By
–
It's a bird, it's a plane, it's … an even FASTER speed for #Llama4 Maverick!
— SambaNova (@SambaNovaAI) 14 avril 2025
We're gearing up to 800 t/s! 🚀
See for yourself 👇It's a bird, it's a plane, it's … an even FASTER speed for #Llama4 Maverick! We're gearing up to 800 t/s! See for yourself
-
GPU Form Factor Advantages Over Vector Architectures Today
By
–
The GPU form factor is better today with current gate densities and memory architectures, but that wasn’t an option back in the day. A stronger case for vector architectures back then might even have held up progress on our current architectures!
-
Data vs Compute: The Real Bottleneck in AI Development
By
–
If you could afford a Cray, collecting 1.2 million digital images for ImageNet would not be a gating factor. DQN or AlphaGo didn’t need any data. The ChatGPT moment would have needed more data and compute, but the data would still be the lesser challenge.