If you use an optimized #LLM training framework like https://
pbase.ai/3DHqnE5, you can get the host memory overhead back down to a more reasonable 7 * 4 = 28 GiB of host memory even when training on multiple GPUs.
COMPUTING
-
Optimized LLM Training Framework Reduces Host Memory Overhead
By
–
-
Loading Model Weights into GPU Memory with Ray Object Store
By
–
How did we do it? By loading the model weights into memory once before training begins and inserting them as numpy arrays into the #Ray object store, we can then zero-copy read the weights directly from shared memory into each GPU worker process.
-
Ludwig simplifies distributed computing with Ray backend integration
By
–
Doing this yourself would normally be a fair bit of cumbersome code, but in Ludwig you get it for free just by running with Ray as the backend runtime. Try it out for yourself: https://
pbase.ai/3qfet19 -
Loading Pretrained Checkpoints: Multi-GPU Memory Challenge
By
–
Before you even get to multi-GPU training with model parallel frameworks like #Deepspeed, you need to load the pretrained checkpoint into memory. To make matters worse for machines with multiple GPUs, you need to load the checkpoint into host memory once for each GPU in your job!
-
Llama2 7B Model Training Memory Requirements on Multiple GPUs
By
–
Now training your 7B parameter #Llama2 model in float32 with 8 GPUs requires 7 * 4 * 8 = 224 GiB of host memory just to load it onto the GPUs.
-
Main Problem Teams Face When Fine-tuning LLMs: Out of Memory
By
–
What’s the #1 problem teams encounter when #finetuning an #LLM? The dreaded "Out of memory" error. No, not a CUDA OOM, just a regular host out of memory error.
-
Computing Paradigms: From Mainframes to Next Battlefield
By
–
"The war for computation has been over many times," mused @jimkxa . "Mainframes won it, and then mini-computers won it, and then workstations won it, and then PCs won it, and then mobile won it — the war has been won, so let's start the next battle!"
-
RISC-V Customization Key to Silicon Ownership Strategy
By
–
“With #riscv, customization and optimization are key. The important thing is you own the silicon, and that ownership is what customers find especially attractive.”
-CCO @DavidBennett__ on today's @HMGnewsroom and @SamsungCatalyst funding announcement -
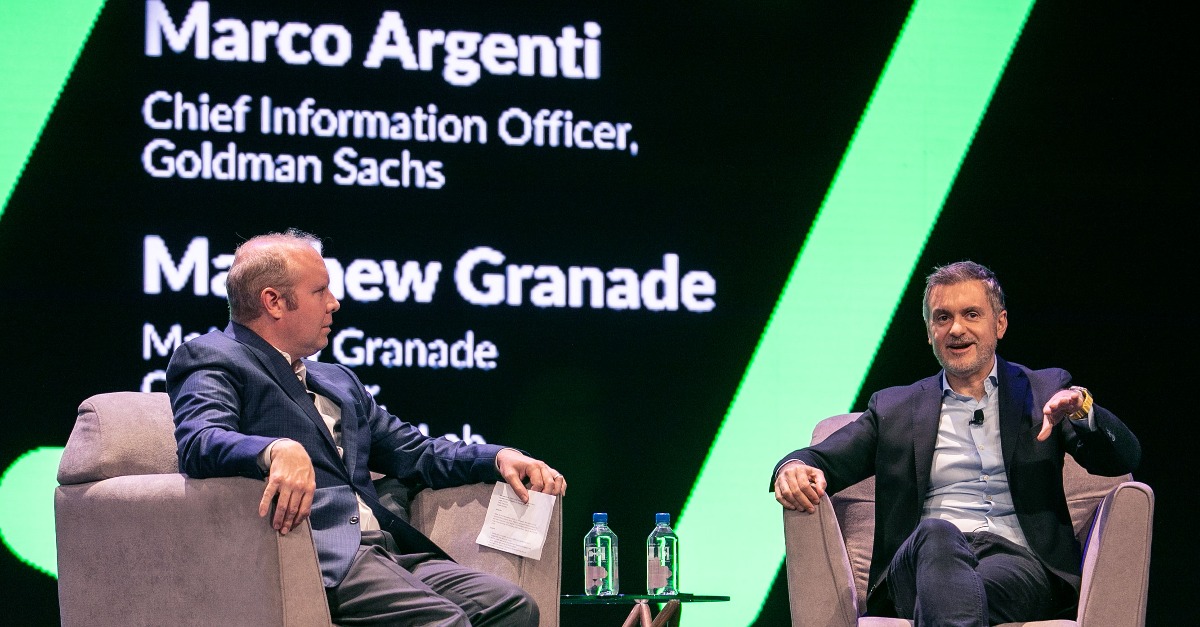
IT’s Essential Role Powering Enterprise AI Innovation
By
–
IT's role in AI? Essential! Explore REV4 sessions on how IT powers AI innovation. Jump in! https://
domino.buzz/3KjW9uu #ITInnovation #EnterpriseAI -
Fine-tuning Llama-2 with Managed Autoscaling LLM Infrastructure
By
–
There are a lot of ways to #finetune LLaMa-2, but how many of these "solutions" address the #infra challenge? Check out our latest tutorial to learn how to fine-tune #Llama2 on top of fully managed, autoscaling #LLM infra right inside your VPC.