I think they are referring to in vibe coding right now, we only let you have one chat per project, working on a fix!
CODE
-
Codex excels at porting model architectures for async work
By
–
Fun writeup: porting entire model architectures from scratch, and how the Codex app shines for async work! https://t.co/eIsROU3As9
— Alexander Embiricos (@embirico) 1 avril 2026Fun writeup: porting entire model architectures from scratch, and how the Codex app shines for async work! Niels Rogge (@NielsRogge) New blog post: how I used Codex to contribute VidEoMT, a SOTA model for video segmentation, to the Transformers library In December 2025, a shift occurred, and coding agents suddenly succeeded at a task they previously failed at: porting entire models. I list some of my best practices for using coding agents. Link: huggingface.co/blog/nielsr/c… — https://nitter.net/NielsRogge/status/2038654071054426595#m
→ View original post on X — @romainhuet, 2026-04-01 03:11 UTC
-
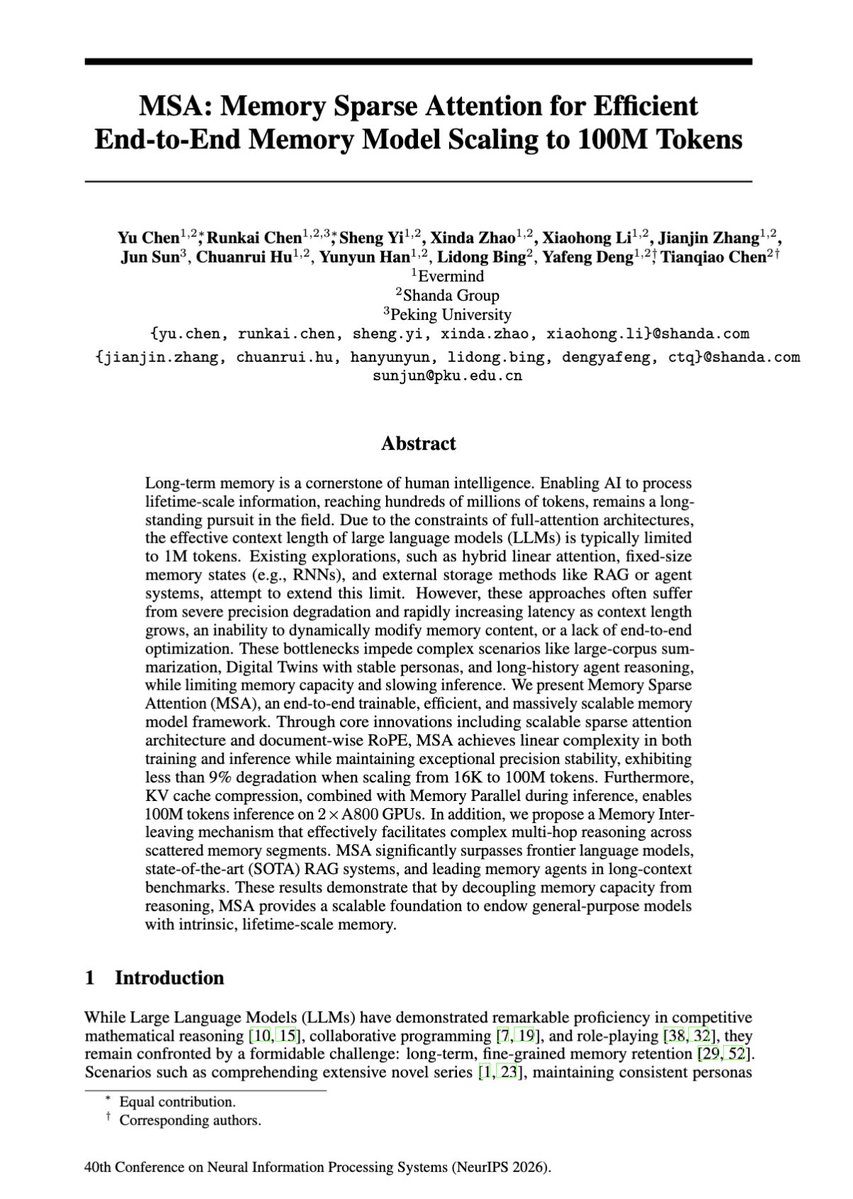
MSA Paper Published, Inference Code Open Sourced This Week
By
–
A little spoiler: 1. @EverMind's MSA paper has been selected for publication by AlphaXiv, and it's getting great traffic 2. MSA's Inference code will be open sourced this week github.com/EverMind-AI/MSA — alphaXiv (@askalphaxiv) Scaling Attention to 100M context!? Memory Sparse Attention introduces an idea where instead of rereading an entire 100M-token entry, it learns to jump straight into the relevant memories and reason from them end-to-end. More specifically, it first encodes documents into compressed memory slots, then for each question it uses a learned router to score which chunks are actually relevant, pulls only the top few, and runs normal attention over that tiny assembled context. So the model's compute grows with "how much it needs to look at" not "how much memory exists". This retrieval step is trained jointly with answer generation, so memory lookup is part of the model itself, and can decouple memory capacity from reasoning cost. [Translated from EN to English]
→ View original post on X — @elliotchen100, 2026-04-01 03:05 UTC
-

Build CLI for AI Agents and Humans in 10 Minutes
By
–
Just SHIPPED new X Article: How to Build CLI for AI Agents and Humans (in less than 10 mins!) Google Cloud Tech (@GoogleCloudTech) x.com/i/article/203876788402… — https://nitter.net/GoogleCloudTech/status/2038778093104779537#m
→ View original post on X — @saboo_shubham_, 2026-04-01 02:31 UTC
-
Self-Hosted Solution for Non-Technical Teams Beyond R2
By
–
need to provide my (nontechnical) team a simple easy self hosted solution that we can customize to our needs. need like R2++
-
Tnkr: GitHub Platform for Robots Launch
By
–
Introducing Tnkr: The GitHub for #Robots
— Ronald van Loon (@Ronald_vanLoon) 1 avril 2026
by @theonlyAyo
#Robotics #Engineering #ArtificialIntelligence #Innovation #Technology pic.twitter.com/0jeJafgYE5Introducing Tnkr: The GitHub for #Robots
by @theonlyAyo #Robotics #Engineering #ArtificialIntelligence #Innovation #Technology -

Build Solar Flare Detection System Using SageMaker LSTM Networks
By
–

Build a Solar Flare Detection System on SageMaker AI LSTM Networks! #BigData #Analytics #AI #MachineLearning #DataScience #IoT #IIoT #Python #RStats #TensorFlow #JavaScript #ReactJS #CloudComputing #Serverless #DataScientist #Linux #Programming #Coding #100DaysofCode
-
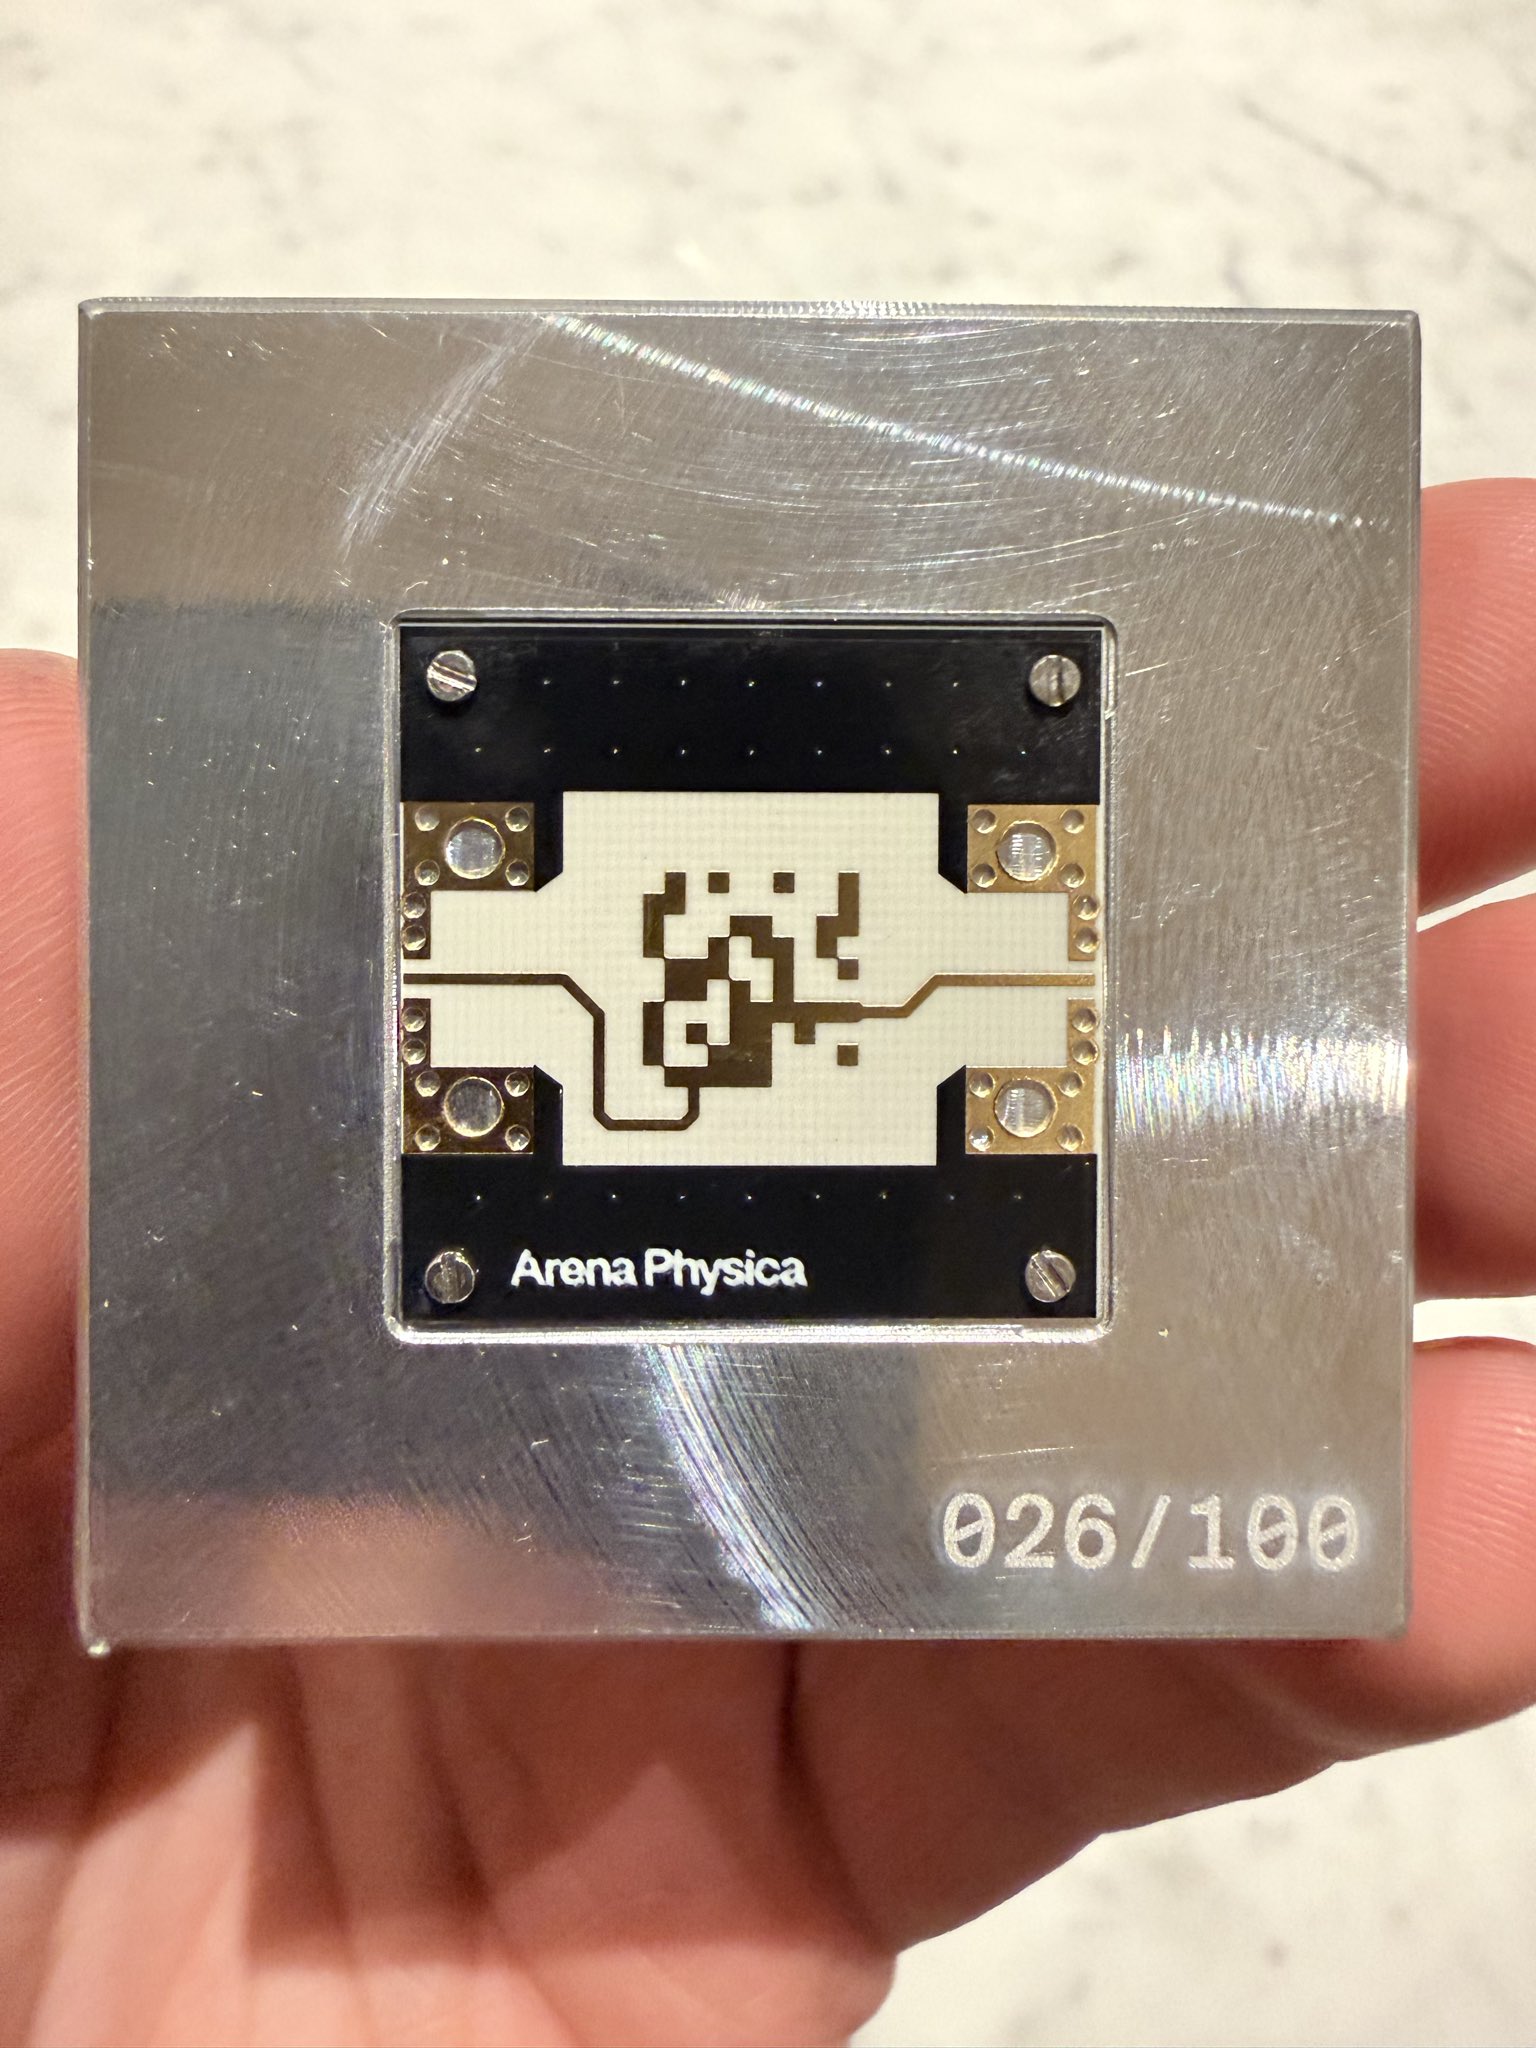
First RF Circuit Designed Autonomously From a Text Prompt
By
–
The first RF circuit designed fully autonomously from a text prompt.
-
Personal Engineering Work and Gemini Collaboration Highlights
By
–
and these are just the set of things I have personally worked on with the engineering team + Gemini, so much more great stuff landed and in flight : )
→ View original post on X — @officiallogank, 2026-04-01 00:28 UTC