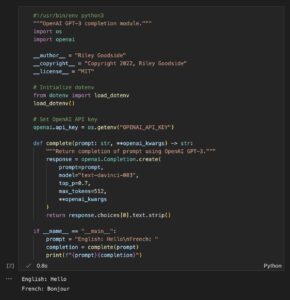
A simple demo of my "instruction template" method of prompting GPT-3, generating a Python 3 module using placeholders and notes within a template that contains only a single line of actual Python:
By
–
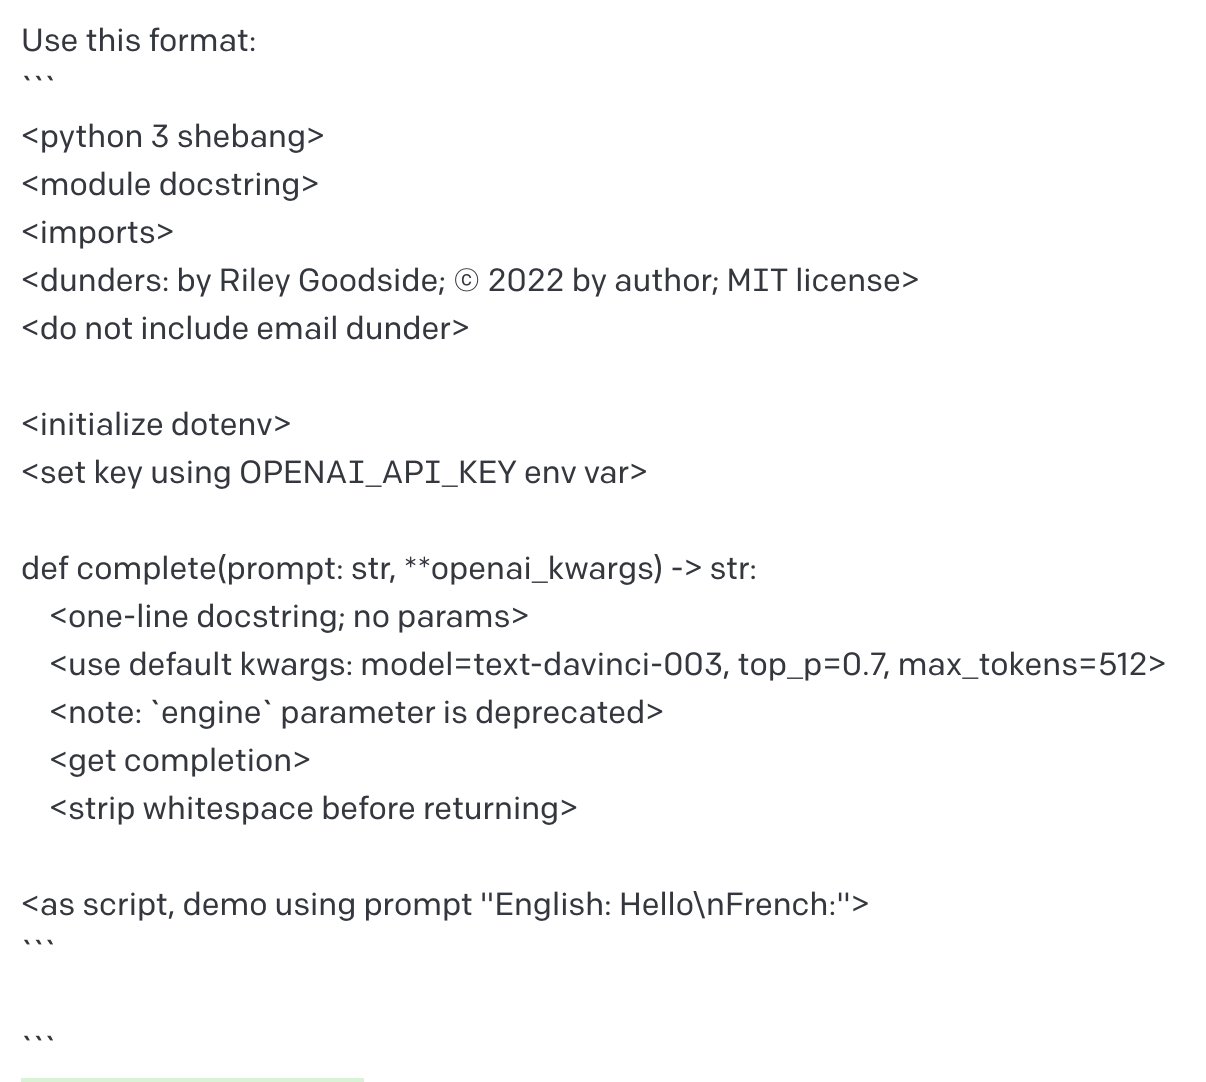
A simple demo of my "instruction template" method of prompting GPT-3, generating a Python 3 module using placeholders and notes within a template that contains only a single line of actual Python:
By
–
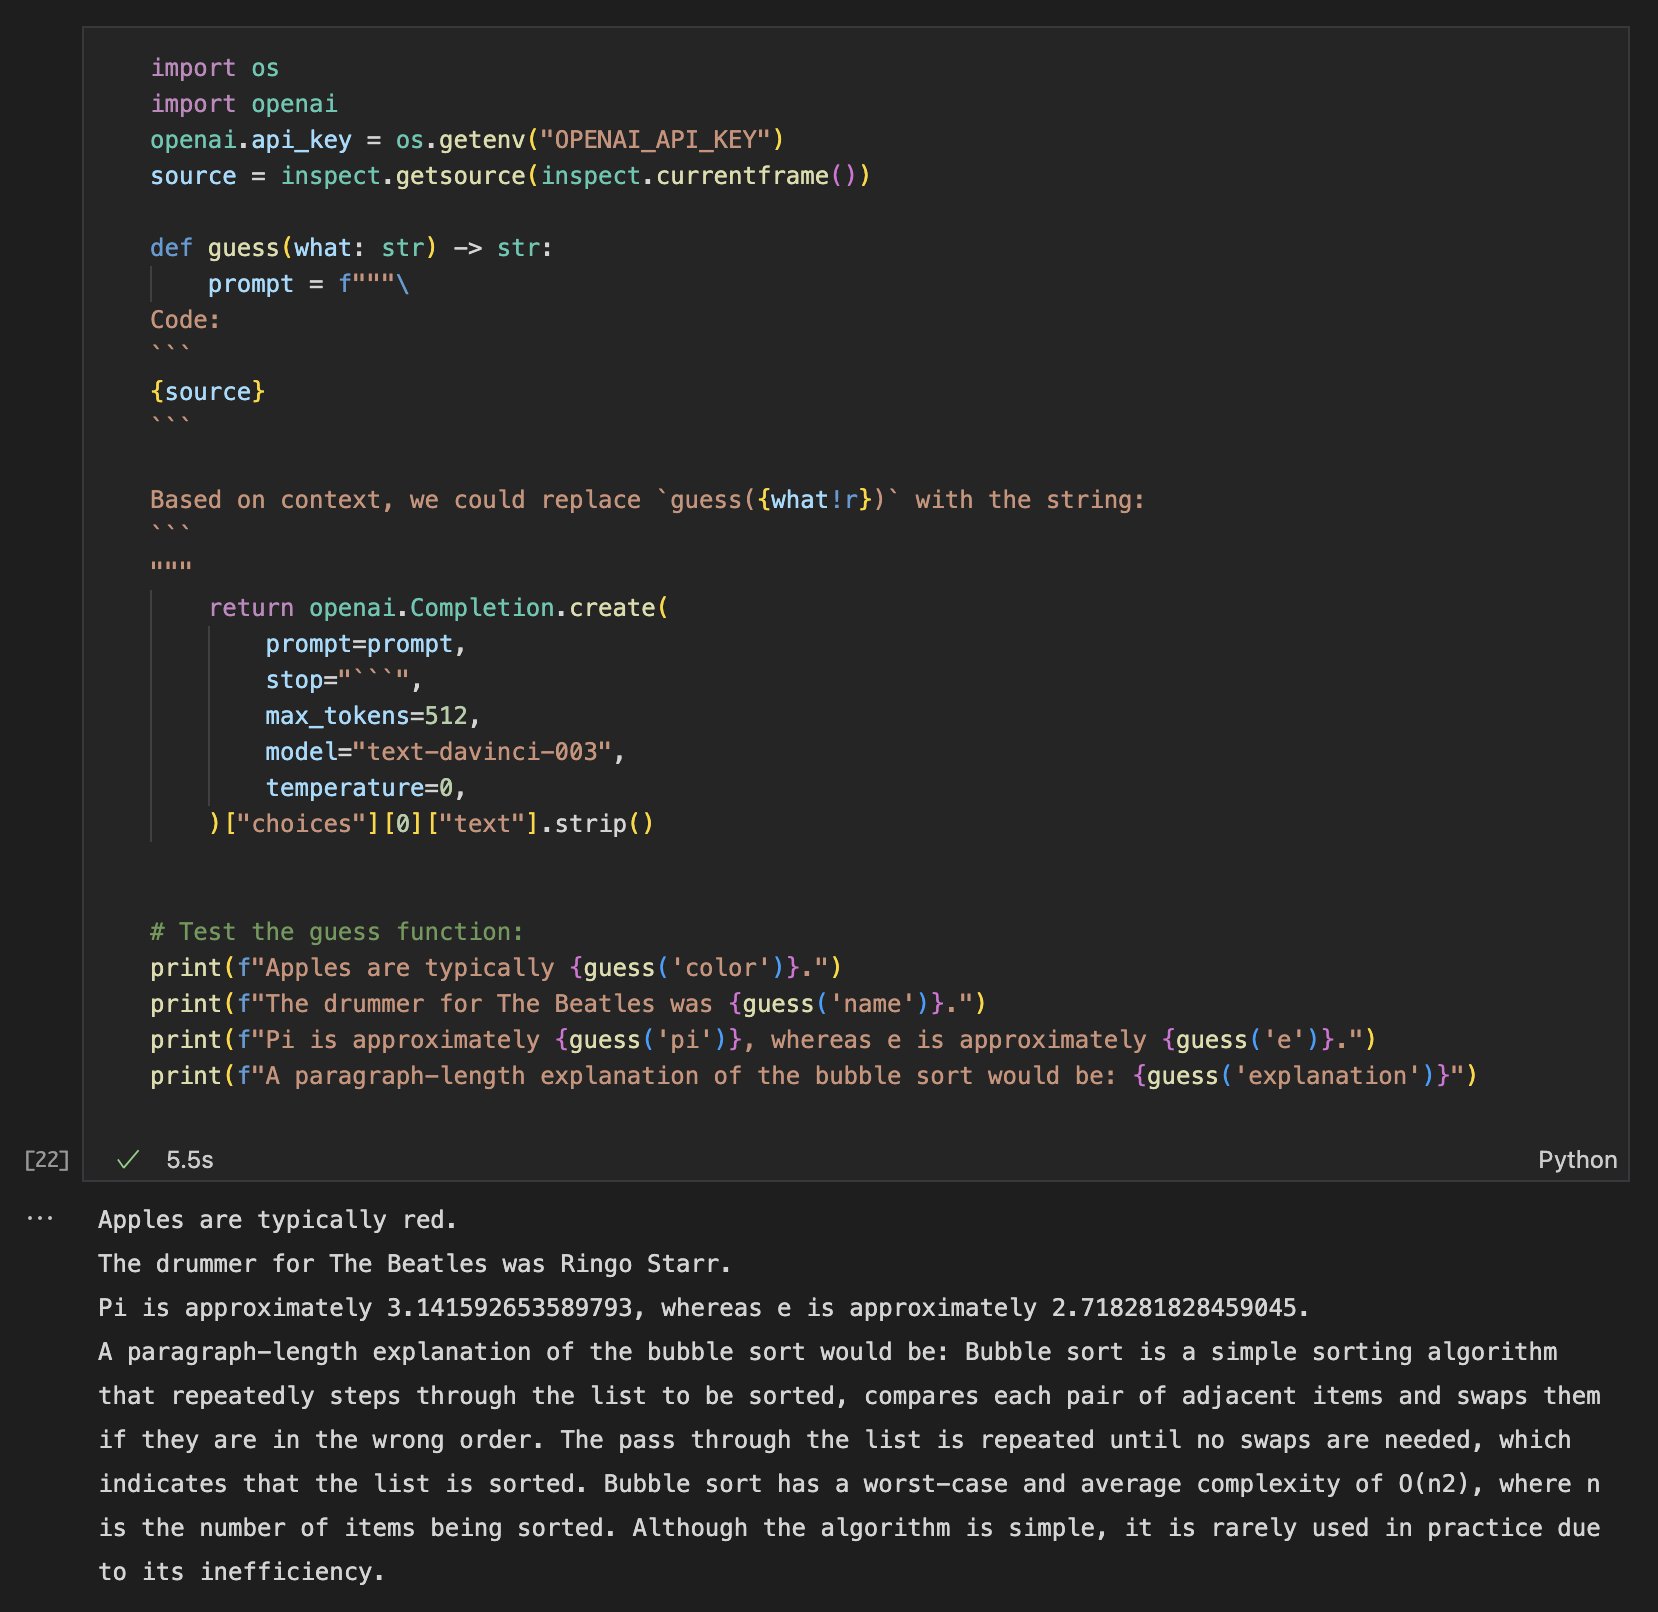
Using GPT-3 to implement a `guess()` function in Python that returns whatever string seems reasonable for the context in which the function was called.

By
–
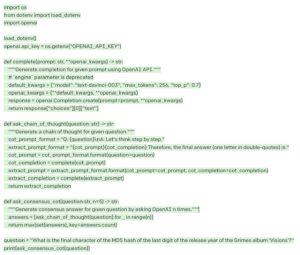
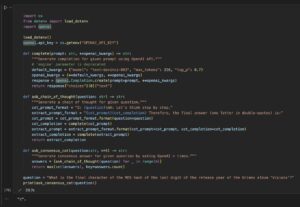
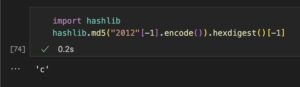
A GPT-3 prompt in instruction-templated Python yielding a valid Python completion that prompts GPT-3 again, using zero-shot chain-of-thought consensus, to determine the final character of the MD5 hash of the final digit of the release year of the album "Visions" by @Grimezsz
.
By
–
demo: https://
huggingface.co/spaces/carolin
eec/informativedrawings
…
github: https://
github.com/carolineec/inf
ormative-drawings
…
paper: https://
arxiv.org/abs/2203.12691
By
–
There were almost 3,000 commits to the main branch in 2022! This wouldn't have been possible without the whole community: half the new architectures were added by external contributors and we had more than 500 new contributors.
By
–
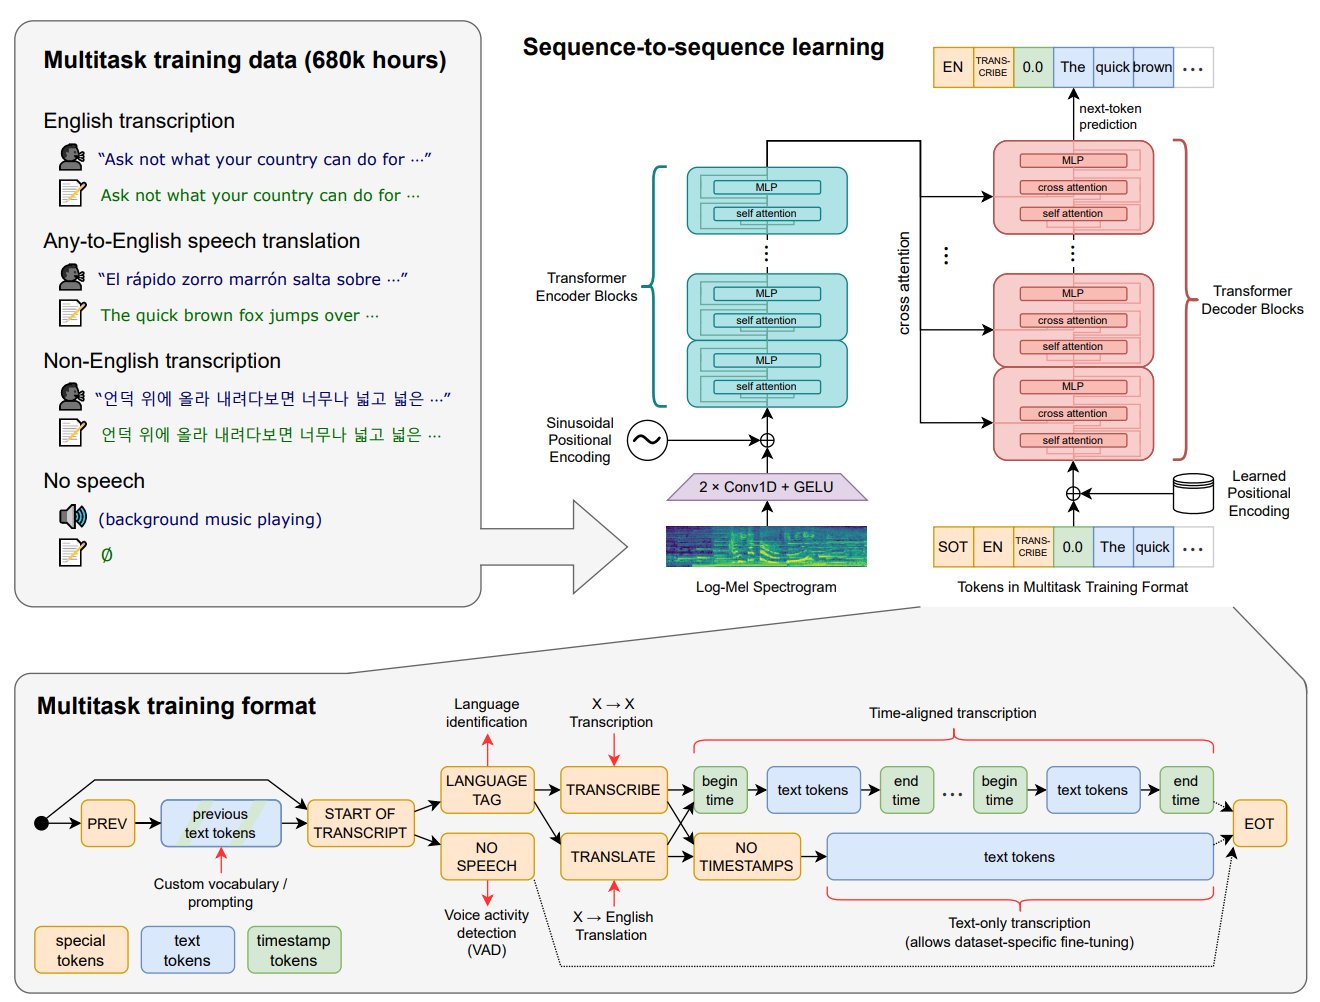
In October, Whisper, a state-of-the-art audio model from @OpenAI for speech recognition was added to the library. https://
huggingface.co/docs/transform
ers/model_doc/whisper
…
By
–
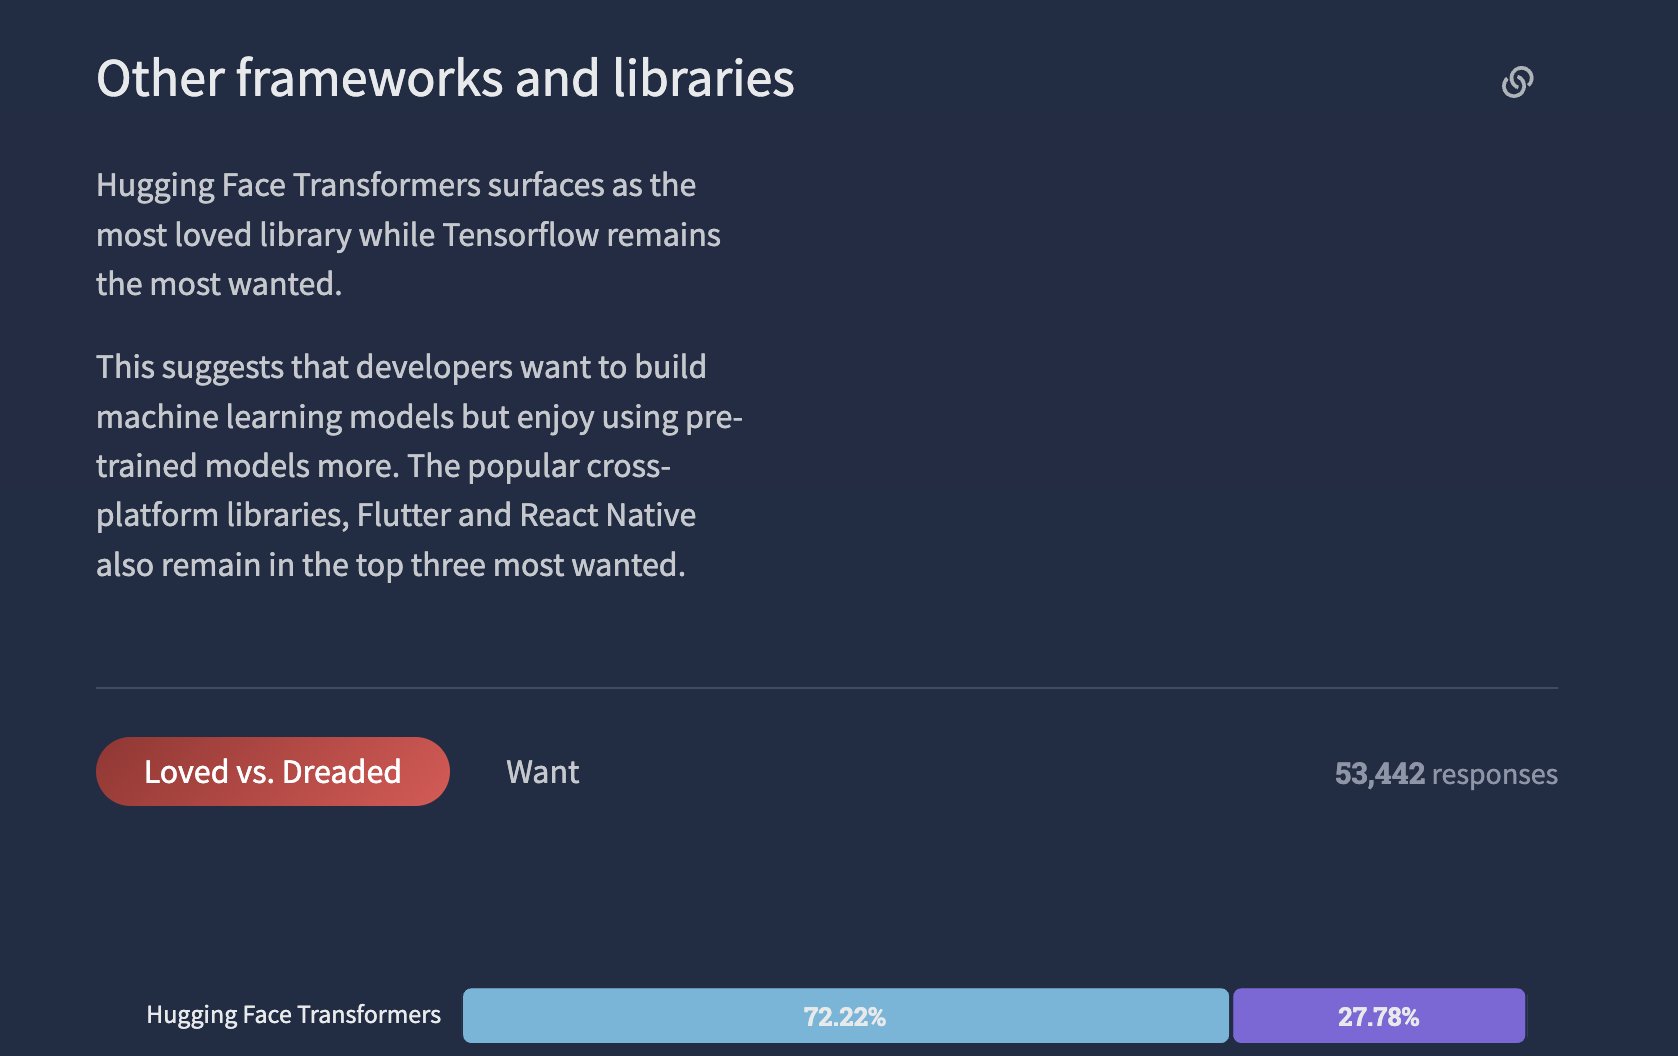
For the second year, Transformers was voted the most loved framework in Stack Overflow survey https://
survey.stackoverflow.co/2022

By
–
LayoutLM v3 (also from @MSFTResearch
) was added to the library in June. It is a multimodal model combining vision and text for document analysis.
By
–
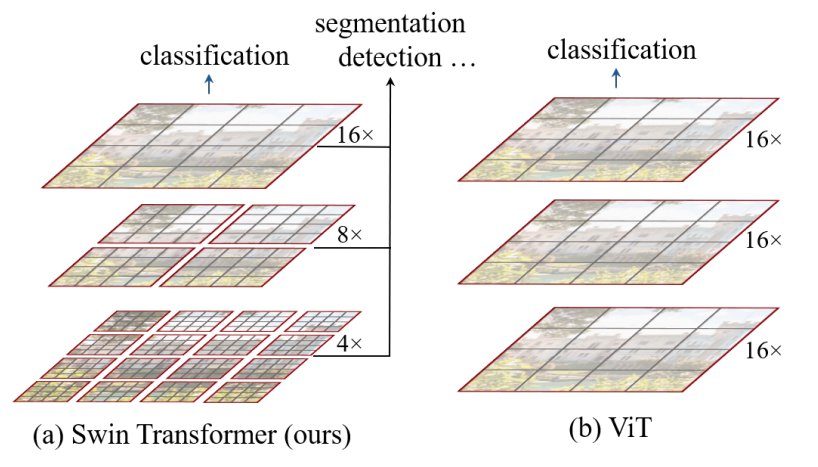
Swin Transformer is a vision model from @MSFTResearch added back in January, which can be used as backbone for a variety of tasks such as image classification, object detection or semantic segmentation. https://
huggingface.co/docs/transform
ers/model_doc/swin
…
By
–
We doubled the number of architectures (89 to 167) with new models in audio, text, vision, multiple modalities or even time seriesand protein folding Here are a few highlights in the most used of those new models