We are just getting started, there are still lots of LlamaIndex components to be implemented into Flowise. We want to give users ability to use different frameworks, leverage different LLM techniques and achieve best for their use cases. Docs:
CODE
-
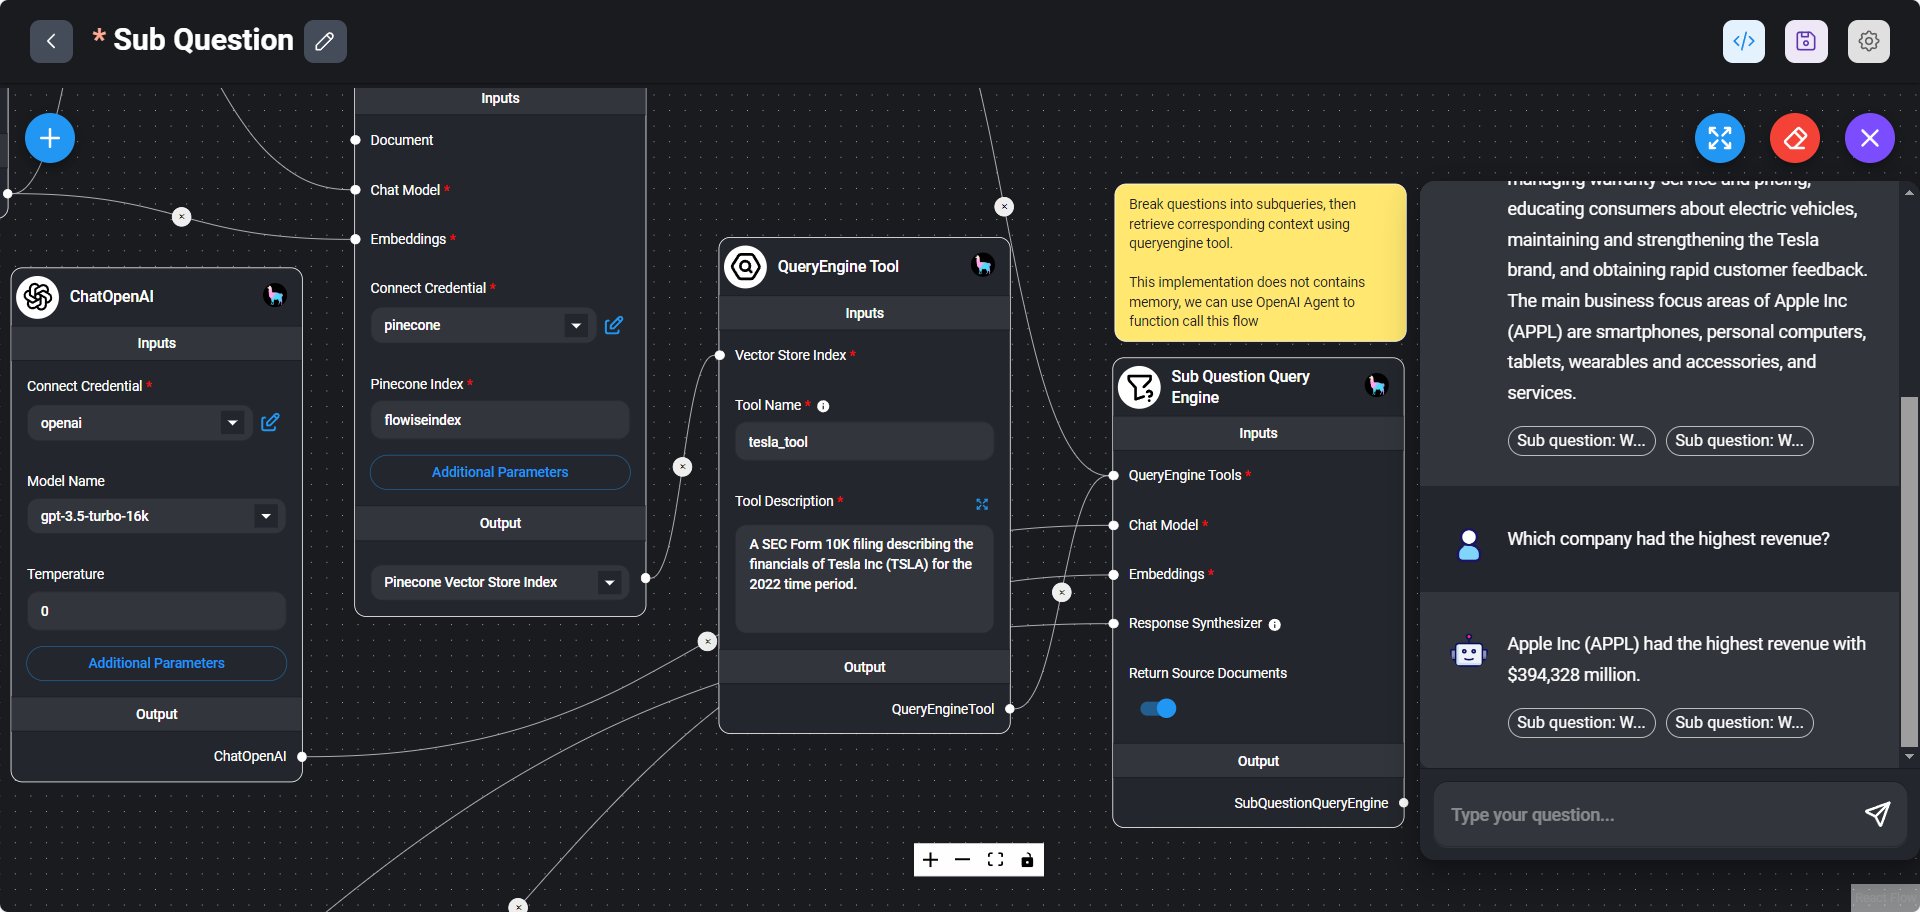
Sub-Question Query Engine RAG Technique Advanced Implementation
By
–
Sub-Question Query Engine Breaks complex query into sub questions for each relevant data source, then gather all the intermediate reponses and synthesizes a final response This is an exciting one as we replicated the RAG technique used in http://
secinsights.ai by LlamaIndex -
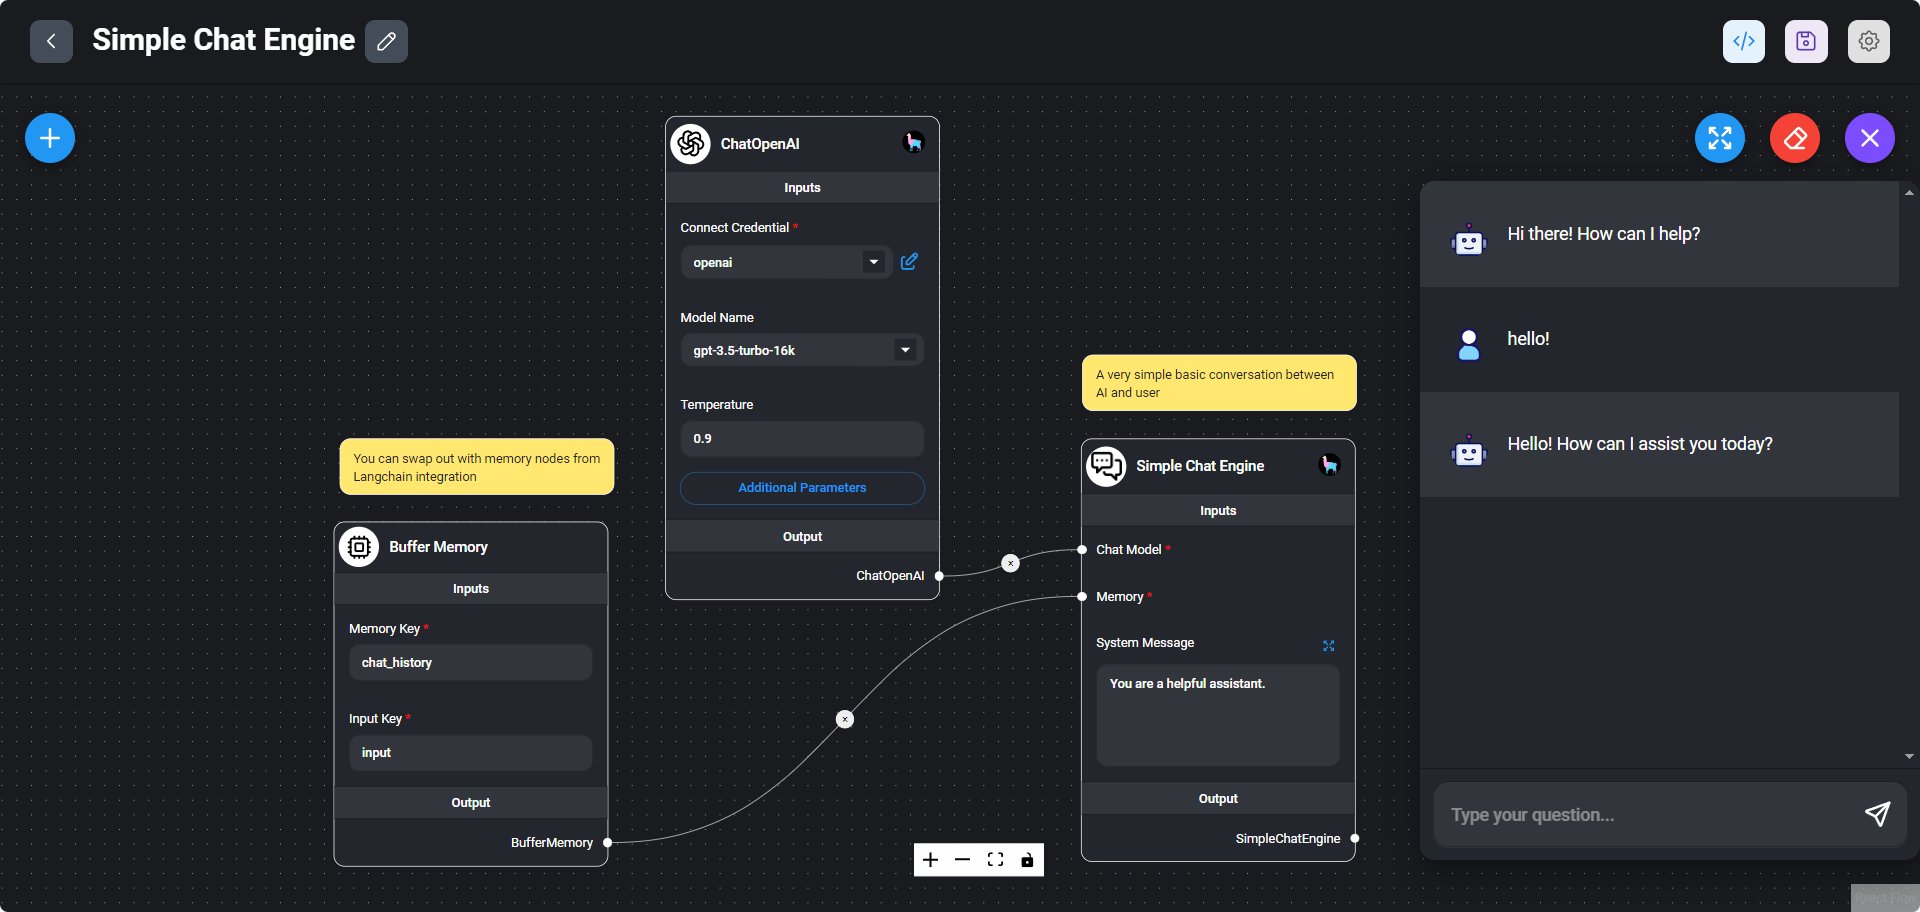
Simple Chat Engine for User-AI Conversations
By
–
Simple Chat Engine Handle back and forth conversations between user and AI
-
LlamaIndex JS/TS integrations now available in Flowise
By
–
LlamaIndex is a powerful framework with advanced retrieval techniques for designing RAG apps.
— FlowiseAI (@FlowiseAI) 8 février 2024
We're excited to bring LlamaIndex JS/TS integrations into Flowise🥳🎉
Repo: https://t.co/WBoMoPM0Bq
4 templates ready to be used 🧵 pic.twitter.com/f6gnF9sExpLlamaIndex is a powerful framework with advanced retrieval techniques for designing RAG apps. We're excited to bring LlamaIndex JS/TS integrations into Flowise Repo: https://
github.com/FlowiseAI/Flow
ise
… 4 templates ready to be used -
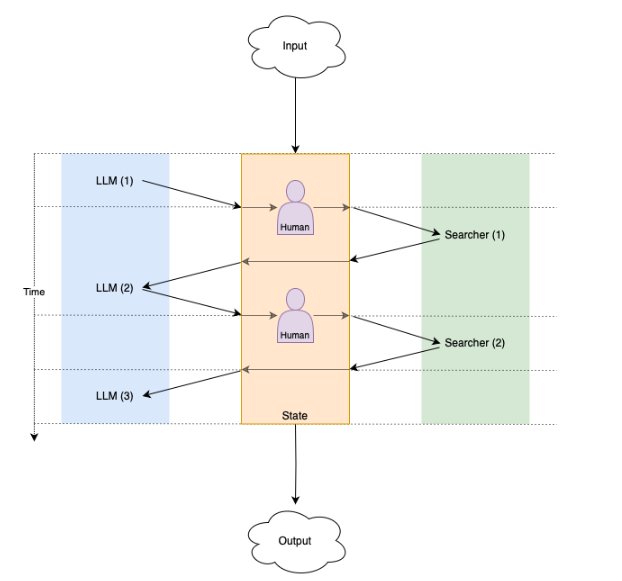
Human-in-the-Loop Agents: Interrupt and Authorize Features
By
–
Human-in-the-loop with OpenGPTs and LangGraph Today we’re launching two “human in the loop” features in OpenGPTs (powered by LangGraph): Interrupt
Authorize What do these do and why is this "human-in-the-loop" important for agents? Interrupt This allows the user to -
Adafactor vs Adam: Optimizer Choice for Small Neural Networks
By
–
ok good point and i AGREE that the details matter but these kids aren't trying to replicate T5 pretraining in 20 hours on a single gpu; they just want to train little neural networks from scratch; and for their use cases adafactor vs adam won't almost ever matter
-
Neural Networks Learn Regardless of Input Encoding or Hyperparameters
By
–
one point i try to get across in Practical Deep Learning is that neural networks will LEARN no matter what you do (provided you avoid huge errors like setting all input data to zero or something) any input encoding, any hidden size, any reasonable learning rate…. it will learn
-
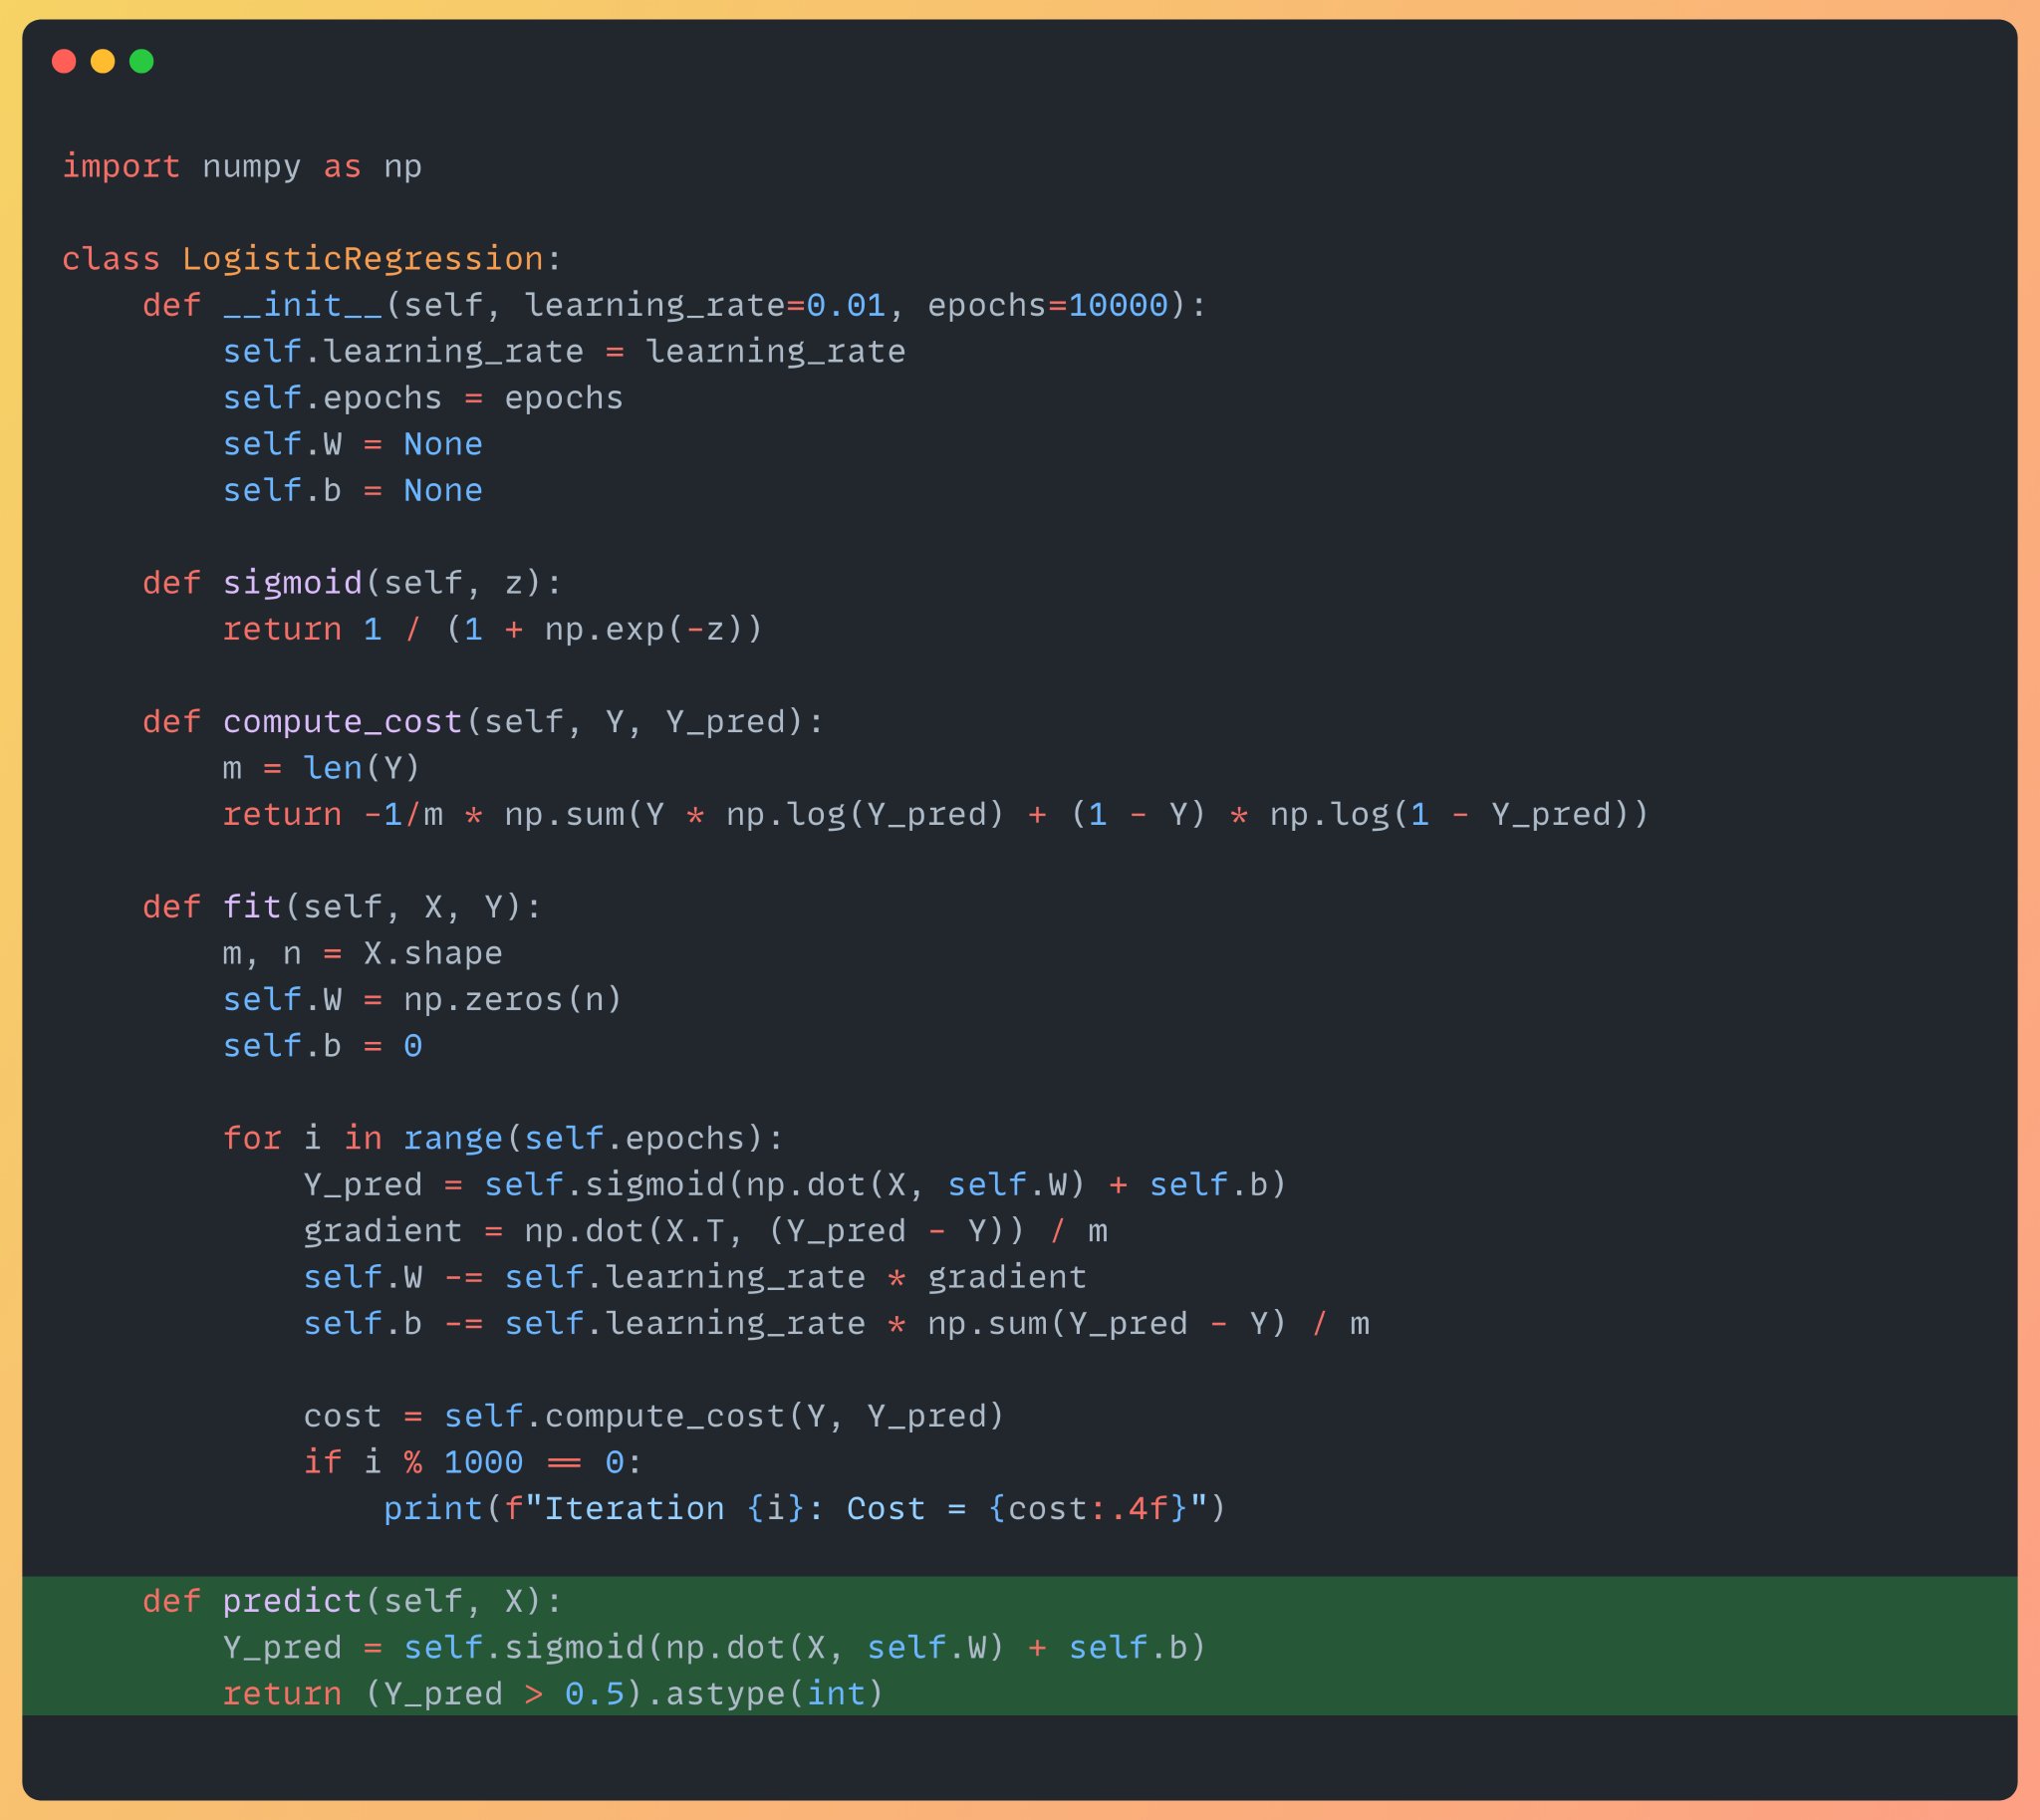
Predict Method Implementation with Binary Classification Threshold
By
–
Finally the predict method: It uses the trained model to make predictions based on input features. This method applies a threshold of 0.5 to make binary predictions, returning 1 for positive class predictions and 0 for negative class predictions.
-
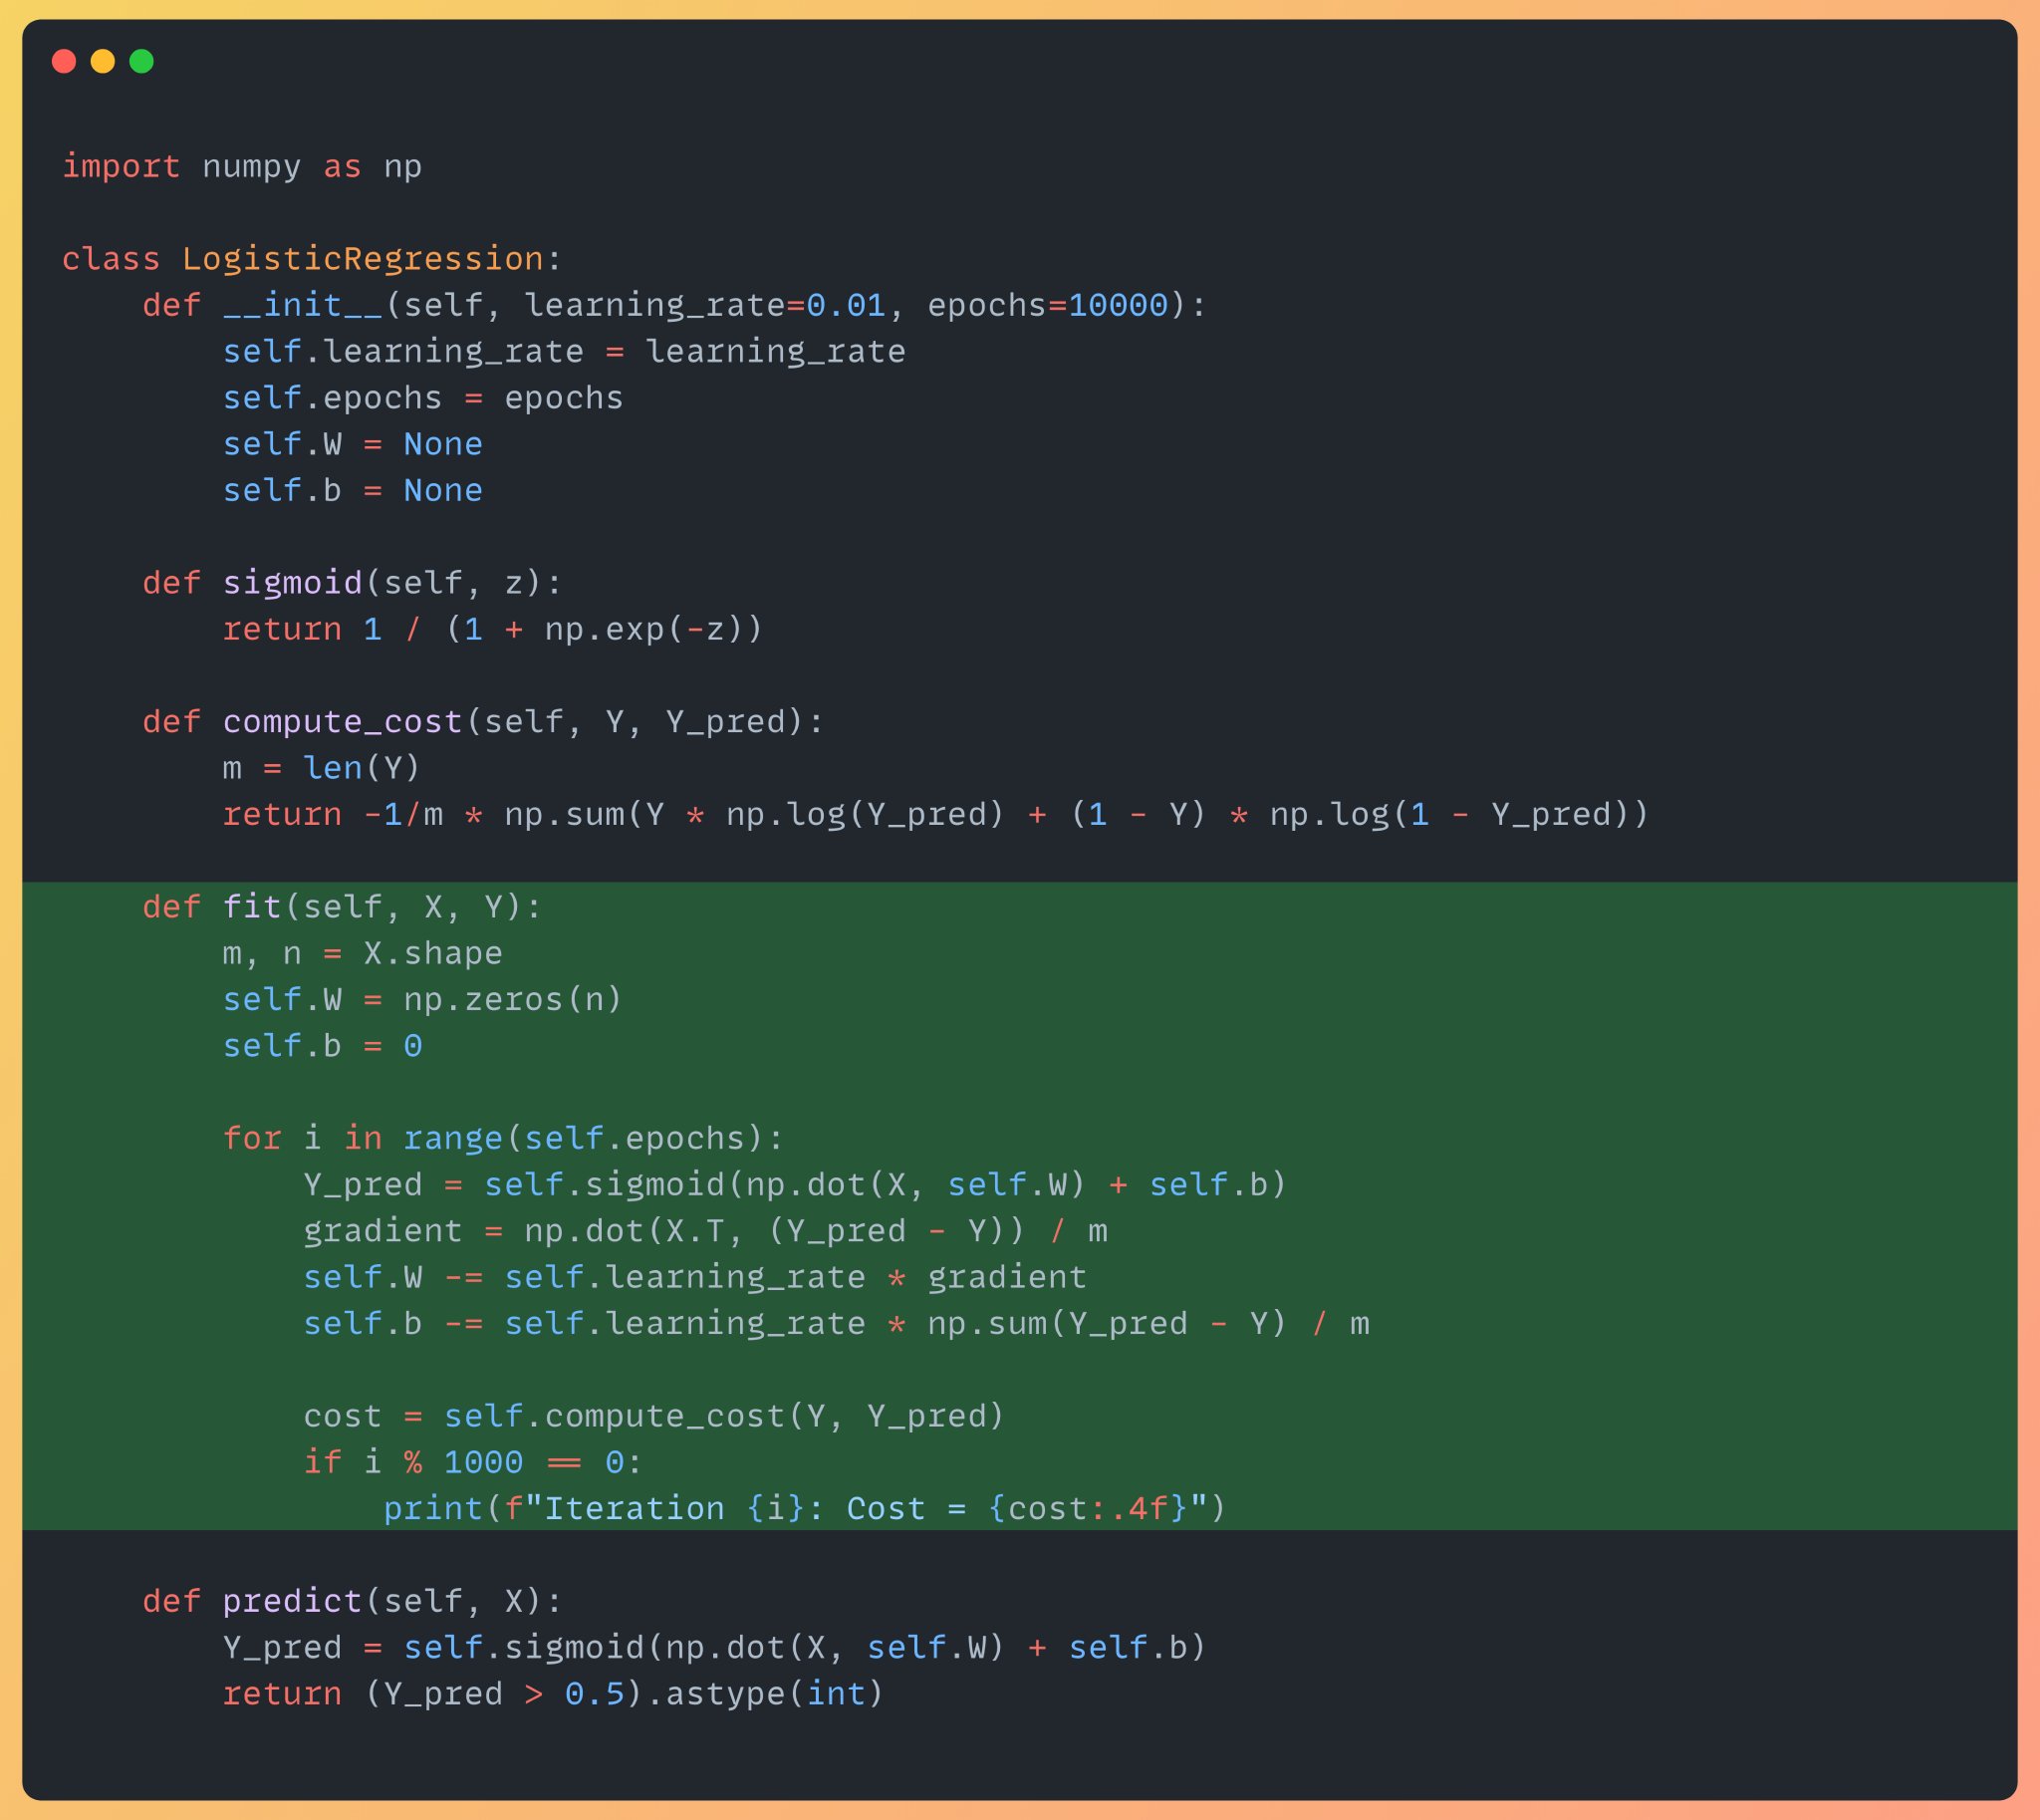
Defining the Fit Method for Model Training with Gradient Descent
By
–
Define the "fit" method that does the training of model The method takes input data "X" and the corresponding target values "y" It also updates the weights and bias using gradient descent.
-
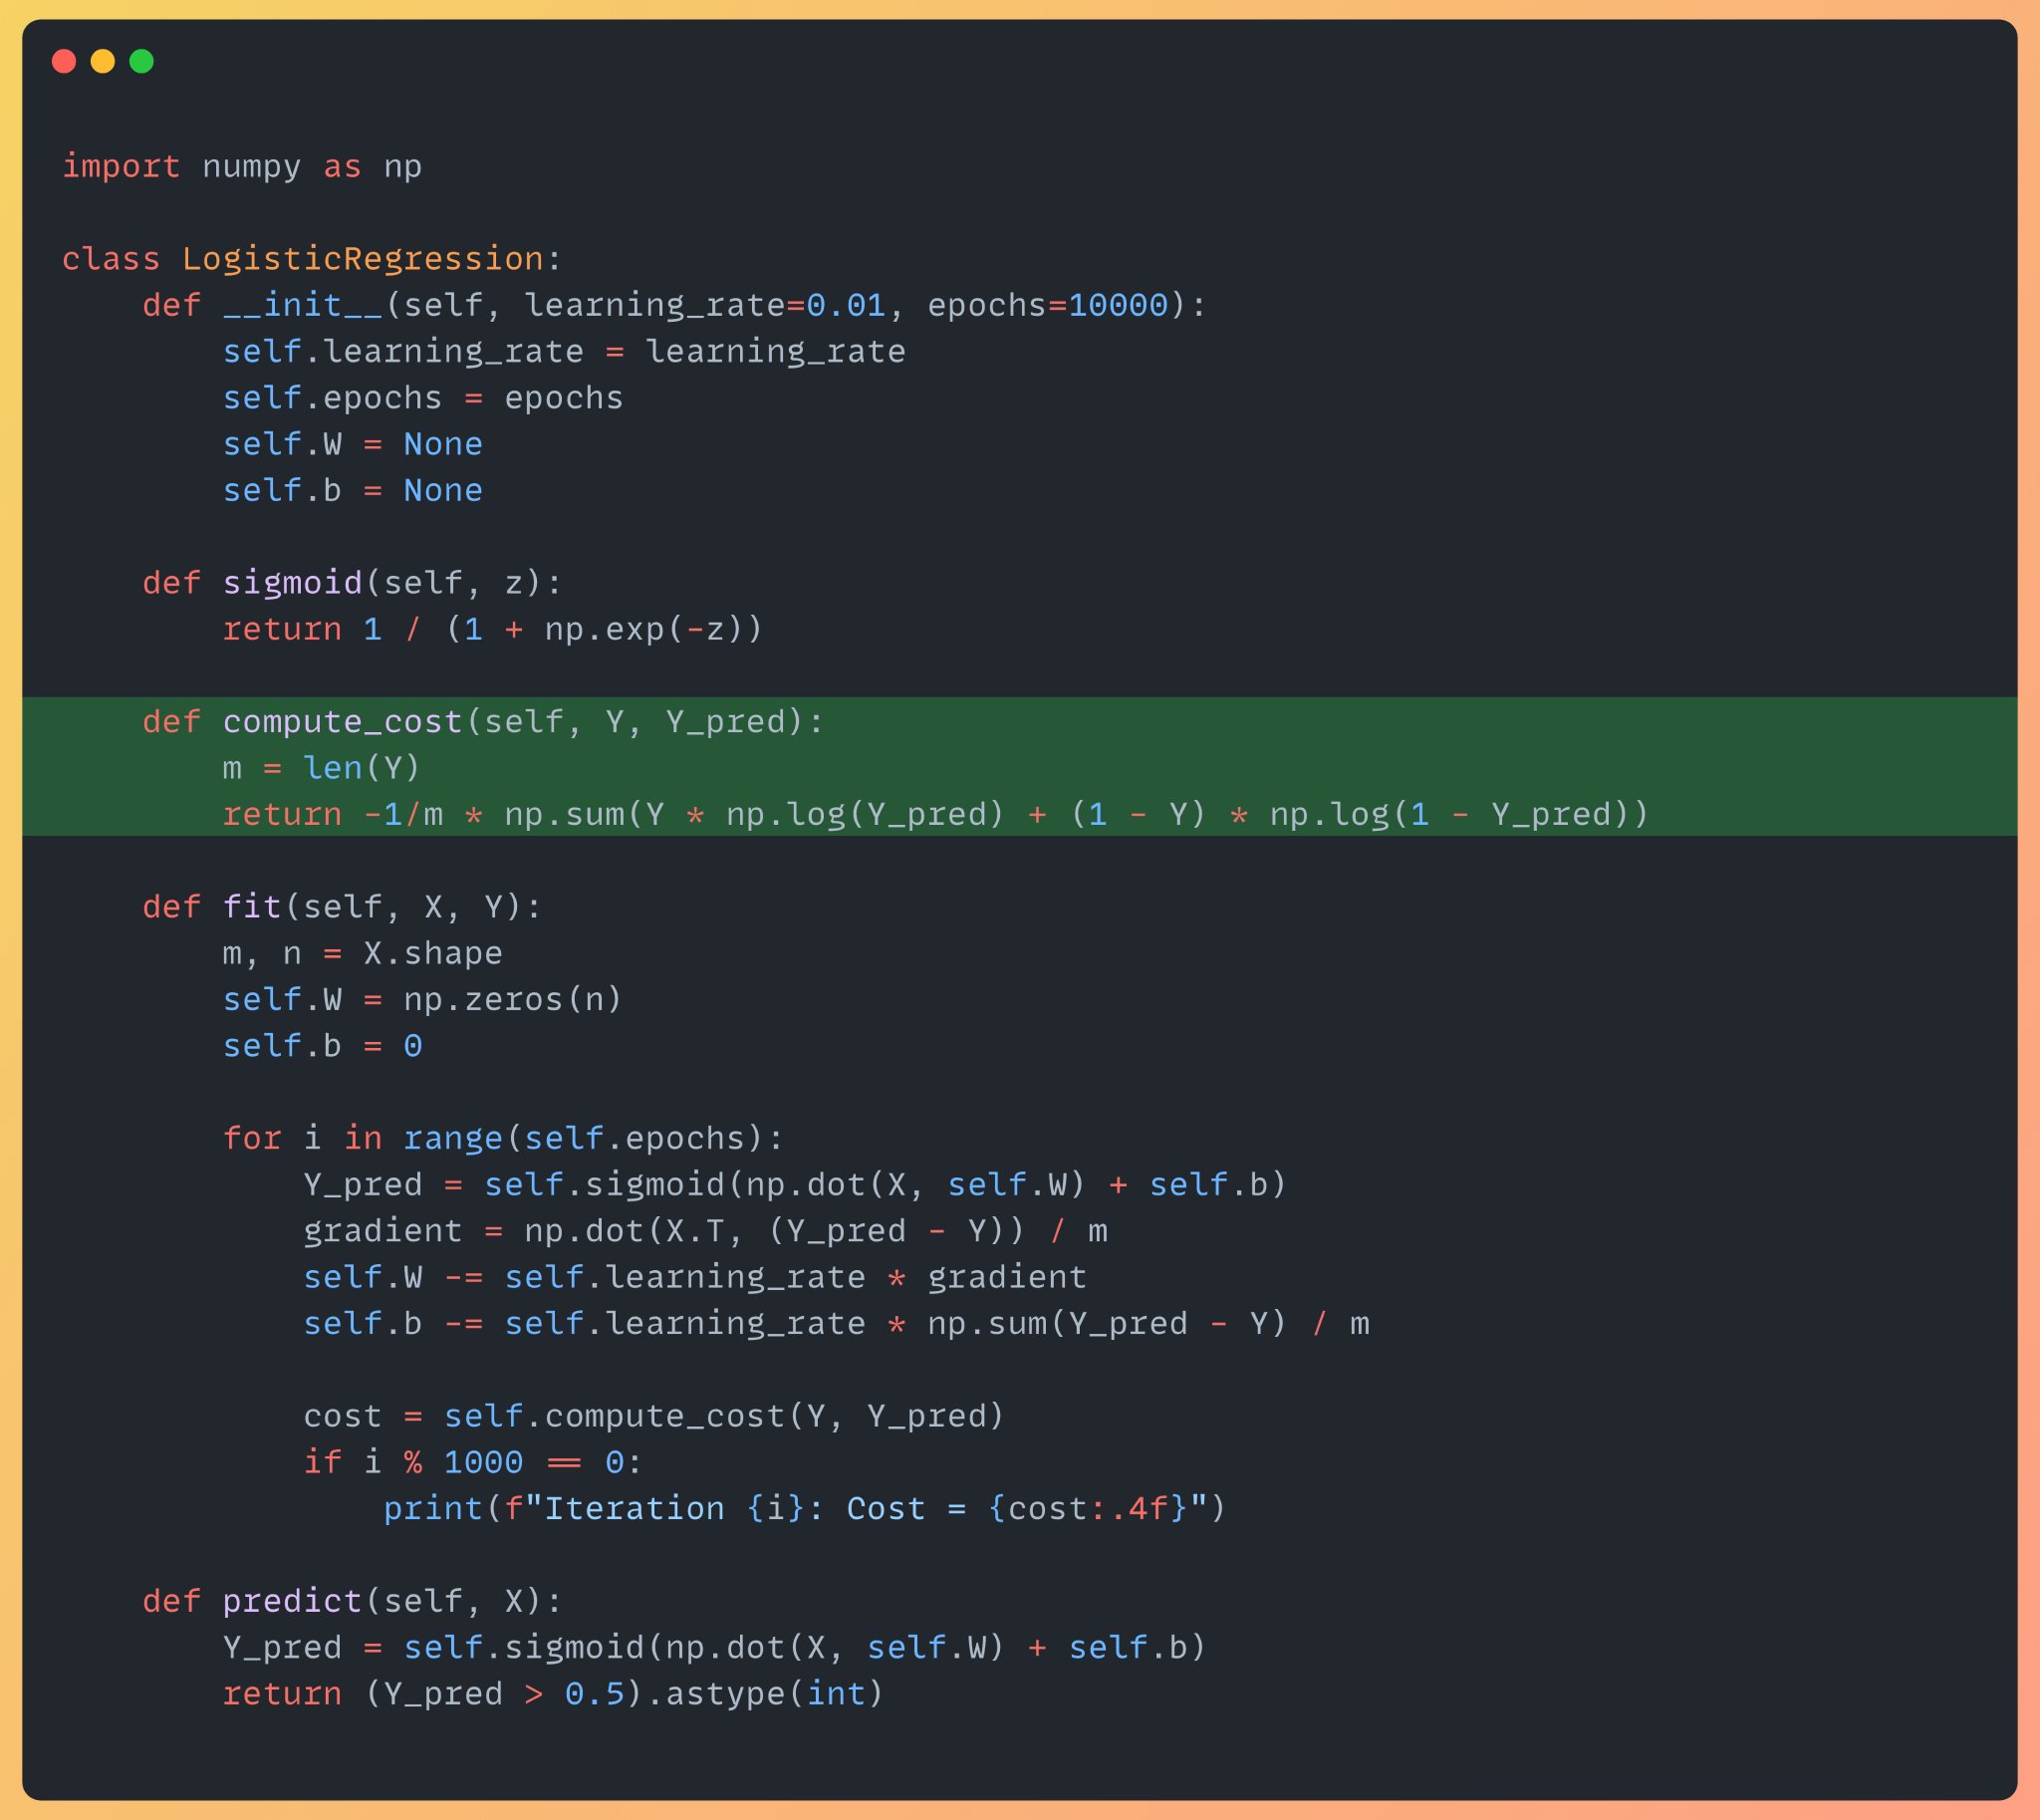
Computing Cross-Entropy Loss Cost Function for Classification
By
–
Compute Cost Function Next define the cost function, which is the cross-entropy loss, used to measure the error between predicted probabilities and actual labels.