@FireworksAI_HQ feature request: it would be great if there was an API endpoint that returned the list of models, I had to hard-code them here for the moment
CODE
-
New LLM Fireworks Plugin Enables Access to Advanced Language Models
By
–
New LLM plugin: llm-fireworks, providing access to @FireworksAI_HQ models llm install llm-fireworks
llm keys set fireworks
# paste in API key
llm -m fireworks/models/llama-v3-70b-instruct 'five great names for a pet ocelot' -
Framework Documentation with Tokenizer Support Request
By
–
Your documentation is super well-written, so it was really easy to convert the framework. My only request is that I would like some sort of tokenizer so I can be more precise with the amount of tokens for input and output and build a more robust system around that 🙂
-
Popular LLM Training Frameworks: Hugging Face Transformers Axolotl UnSloth
By
–
in the community: huggingface transformers, axolotl, unsloth, lit-gpt are popular options.
-

Llama 3 Models Now Available in LangSmith Playground
By
–
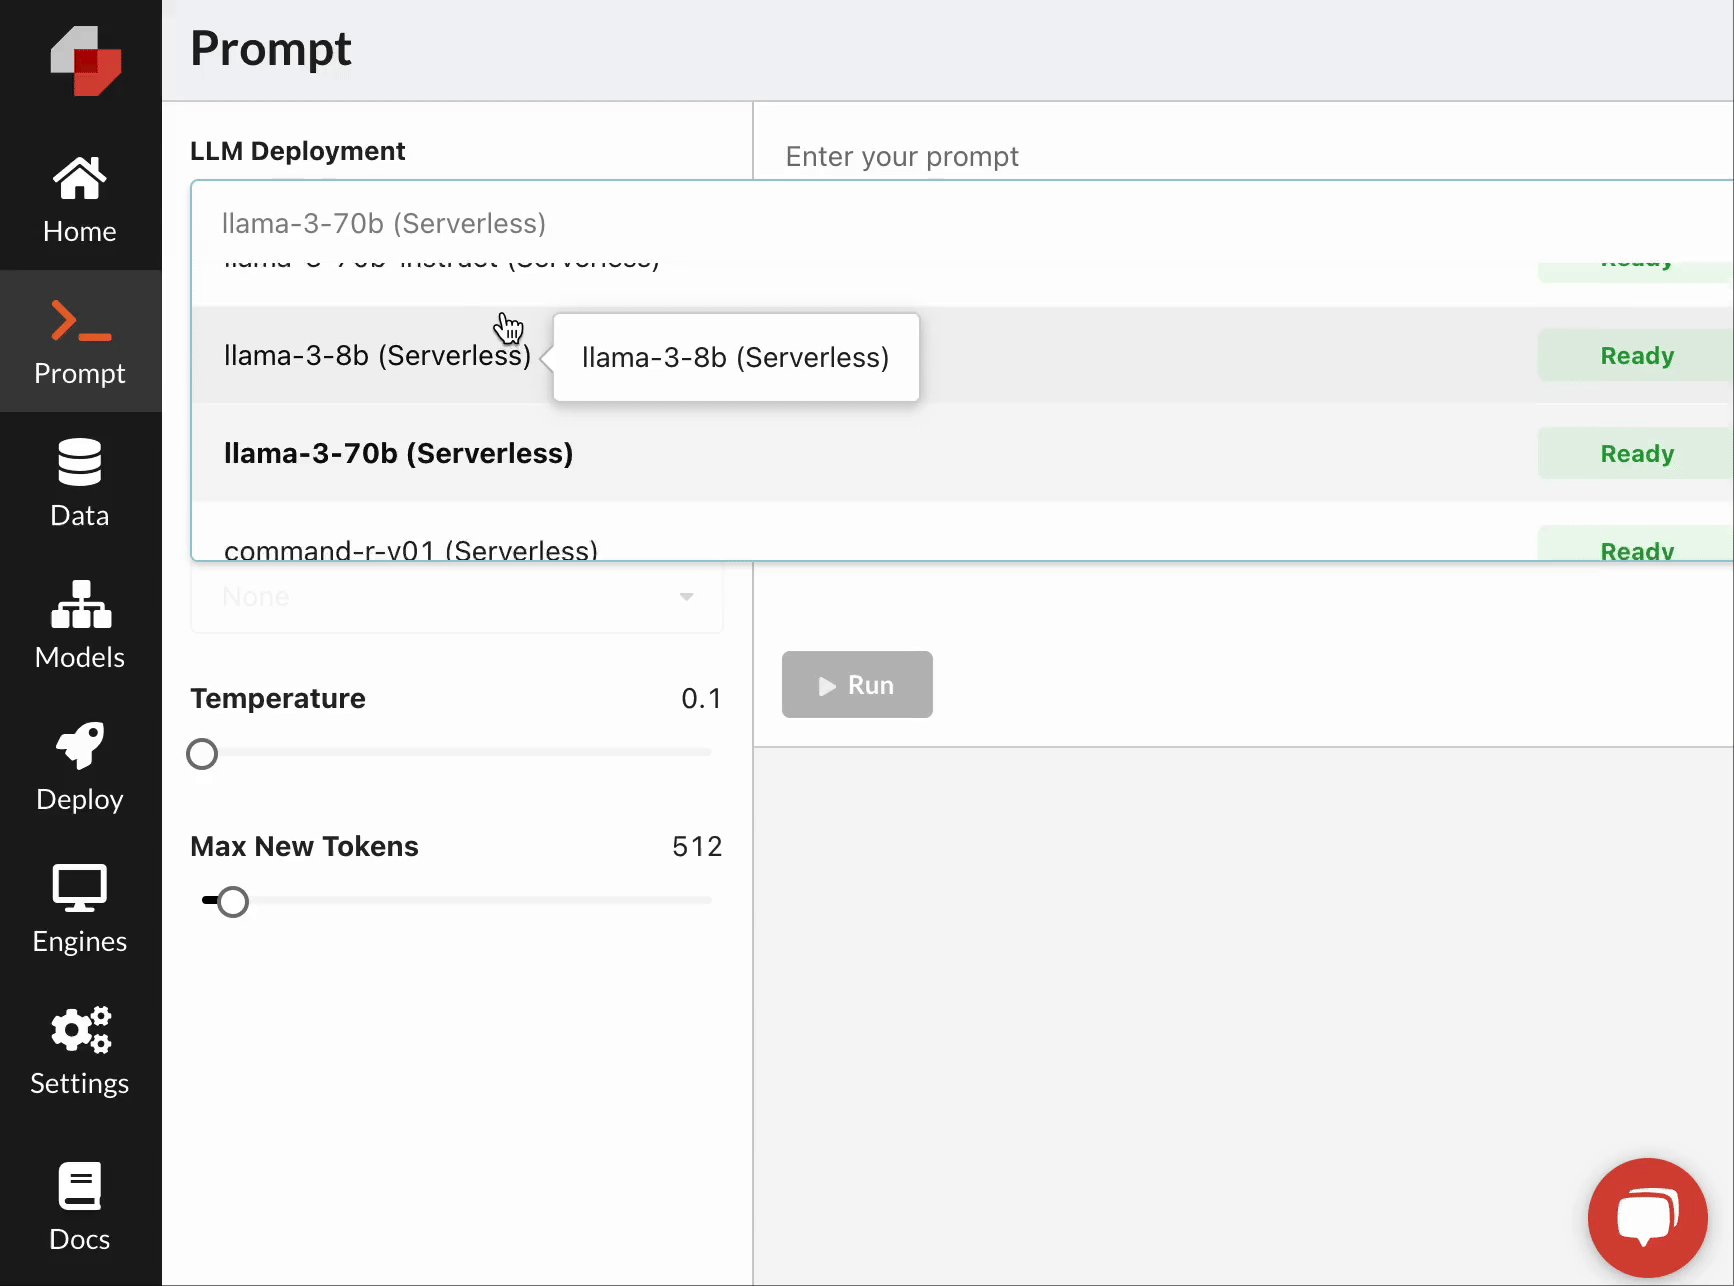
Try out the latest Llama 3 8B and 70B models in LangSmith Playground today!
— LangChain (@LangChain) 18 avril 2024
Thanks to our friends at @FireworksAI_HQ! https://t.co/0d6H7X71r1 pic.twitter.com/lsC9Cjr3NYTry out the latest Llama 3 8B and 70B models in LangSmith Playground today! Thanks to our friends at @FireworksAI_HQ
! -
Serverless Fine-tuning and Serving for Llama3 on Predibase
By
–
Check out #serverless fine-tuning and serving for #Llama3 on @Predibase with our free trial! 🦙
— Predibase by Rubrik (@predibase) 18 avril 2024
🔥 Blazing fast serverless inference – #8b & #70b variants
🖌️ #Finetune in the UI or SDK via config
🌳 Start prompting your fine-tune instantly with #LoRAXhttps://t.co/L3Tv8r07P1 pic.twitter.com/GAOW88SfZzCheck out #serverless fine-tuning and serving for #Llama3 on @Predibase with our free trial! Blazing fast serverless inference – #8b & #70b variants #Finetune in the UI or SDK via config Start prompting your fine-tune instantly with #LoRAX https://
pbase.ai/3VZE37X -
Serverless Fine-tuning and Serving for Llama3 on Predibase
By
–
Check out #serverless fine-tuning and serving for #Llama3 on @Predibase with our free trial! 🦙
— Predibase by Rubrik (@predibase) 18 avril 2024
🔥 Blazing fast serverless inference – #8b & #70b variants
🖌️ #Finetune in the UI or SDK via config
🌳 Start prompting your fine-tune instantly with #LoRAXhttps://t.co/Rq8fsQwaZl pic.twitter.com/CYON9Wx25ZCheck out #serverless fine-tuning and serving for #Llama3 on @Predibase with our free trial! Blazing fast serverless inference – #8b & #70b variants #Finetune in the UI or SDK via config Start prompting your fine-tune instantly with #LoRAX https://
predibase.com/free-trial -
Ollama Integration with Llama 3 Orchestration Works Well
By
–
Some considerations:
It works surprisingly well, not many changes needed besides, of course, the different way @ollama inference works. I just had to add some more info in the prompt for the orchestrator because Llama 3 loves to yap, lol. At one point, it forgot the goal and -
Maestro-Ollama: Local Llama 3 70B Agent Framework
By
–
Introducing Maestro-Ollama! 🦙
— Pietro Schirano (@skirano) 18 avril 2024
You can now harness the power of the Maestro framework entirely locally using Llama 3 70B via @ollama.
Let that sink in for a second, this is a model that outperforms Claude 3 Sonnet, operating as an agent, completely locally.
What a time! 🔥 pic.twitter.com/aC34Bd6F65Introducing Maestro-Ollama! You can now harness the power of the Maestro framework entirely locally using Llama 3 70B via @ollama
. Let that sink in for a second, this is a model that outperforms Claude 3 Sonnet, operating as an agent, completely locally. What a time!