Yup, seems to be true, even saw in job description that have sound understanding of Responsible AI is required, this was not the case earlier
AI
-

Autopilot FS Enables Simultaneous Coding During IFR Flight
By
–
Figured out FS auto pilot so now I can code index.php while the plane flies itself in IFR #automation
-

LangChain Enables Selective LLM Caching Control
By
–
Caching improvements Previously, caching was enabled for either all LLMs or None But @devonbrackbill pointed out you may want to turn off caching for certain LLM calls – eg in recursive summarization This is now possible Docs: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/llm_caching.html
… -
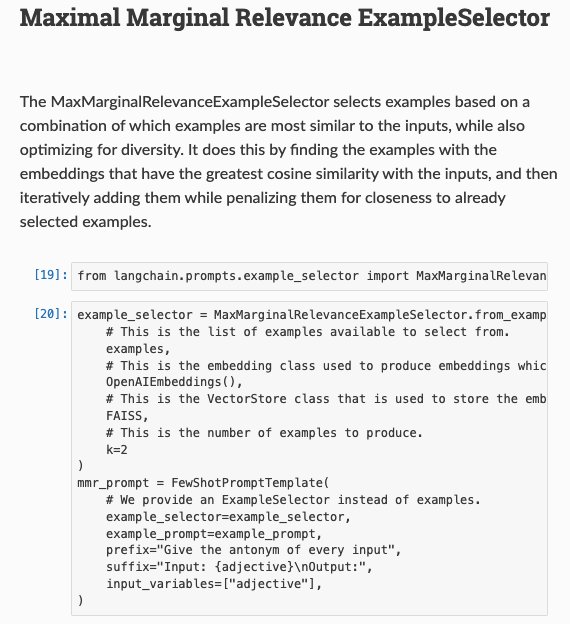
MMR Example Selector for Optimal Contextual Diversity
By
–
Max Marginal Relevance (MMR) Example Selector Based on this preprint by @xiye_nlp et al, the MMR example selector chooses diverse, in-context examples H/t @johnjnay for surfacing this paper Docs: https://langchain.readthedocs.io/en/latest/examples/prompts/prompt_management.html Original Paper: https://x.com/xiye_nlp/status/1603821850592628738?s=20&t=wQPcRd8IJ8URbmytuYP7QA
-
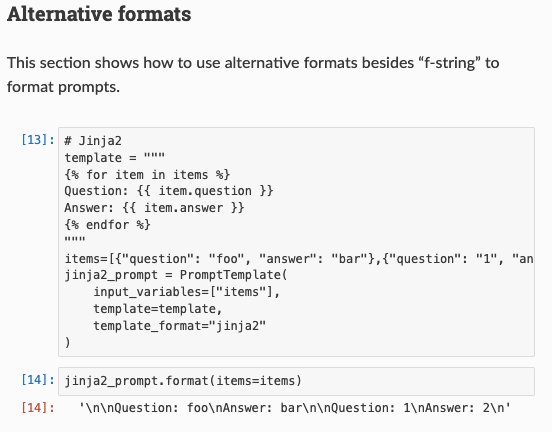
LangChain Extends Prompt Formatting with Jinja Support
By
–
Jinja Formatting Up until now, all the formatting in prompts has been done using Python f-strings But the template_format abstraction is pretty flexible, and @benderville easily extended it to support Jinja, a more advanced formatter Docs: https://
langchain.readthedocs.io/en/latest/exam
ples/prompts/prompt_management.html#Alternative-formats
… -
LangChain v0.0.42 Release: Documentation, Formatting, and Caching Updates
By
–
LangChain v0.0.42 Doc fixes by @YouSearchEngine team, @_abi_ Jinja formatting – @benderville Max Marginal Relevance example selector (based on paper by @xiye_nlp Caching improvements (h/t @devonbrackbill for idea) These are sneaky some awesome updates, lets
-

Global Banking Payments Innovation Drives Fintech Industry Growth
By
–
Latest research report continues to show "the money is on #payments" across the global #banking industry >>> @McKinsey_MGI via @MikeQuindazzi >>> #Fintech #Mobile #CX #FinancialServices >>> https://
mckinsey.com/industries/fin
ancial-services/our-insights/global-banking-annual-review
… -
Gradient Backpropagation and Frequent Word Prioritization in Training
By
–
Because we sum, the gradients for each token get backpropagated to all the rows that were used for it. So with enough training, the model ends up at a good compromise. Frequent words are naturally prioritised in this, because they'll simply have more gradients.
-
Hash Embedding Performance on Small Datasets Analysis
By
–
However, the hash embedding doesn't do so well if the datasets are too small. That's one of the results that I found really useful in this tech report. It's great to have this all explored more thoroughly, and we look forward to publishing more experiments like this in future.
-
spaCy’s Hashing Approach for Word Representations Learning
By
–
This is almost what we do in spaCy — it's just that, instead of reserving the first 9900 rows for common words, we just use the hashing. Given that the assignment of words to shared rows is arbitrary, how can the model learn good representations?