Seeking Postdoc with experience in Robotics and Cloud-Based Systems (AWS, Google Cloud, Azure) to work closely with @UCBerkeley Profs. Ken Goldberg and Joey Gonzales on research on cloud robotics architectures and platforms such as FogROS2: https://
docs.google.com/document/d/e/2
PACX-1vR5n3aHbRl0luk3acq2xmf3HzmS6gJvEX7LC24c503PIT8mlWybxJiWAb3ZRVT2XKJWU62ztMvpQrqr/pub
…
AI
-

Postdoc Position: Cloud Robotics and AWS/Google Cloud Systems
By
–
-

Focusing on the Future of Artificial Intelligence and Machine Learning
By
–
Focusing on the future of artificial intelligence
#AI #AIio #BigData #ML #NLU #Futureofwork @nigelwalsh @pbouillaud @PatrickGunz_CH @pierrepinna @RebekahRadice @Ronald_vanLoon @sbmeunier
@Shirastweet http://
ow.ly/bhEu30svHUj -
Progressively Optimized Local Radiance Fields for Robust View Synthesis
By
–
Progressively Optimized Local Radiance Fields for Robust View Synthesis
— AK (@_akhaliq) 15 juin 2023
paper page: https://t.co/9NUDJbvUtR
present an algorithm for reconstructing the radiance field of a large-scale scene from a single casually captured video. The task poses two core challenges. First, most… pic.twitter.com/Vt1dGq5hSWProgressively Optimized Local Radiance Fields for Robust View Synthesis paper page: https://
huggingface.co/papers/2303.13
791
… present an algorithm for reconstructing the radiance field of a large-scale scene from a single casually captured video. The task poses two core challenges. First, most -
QLoRA, Prefix Tuning, and LoRA: Fine-tuning Techniques Comparison
By
–
This was already a lot of coding. I am saving QLoRA for another day! @Yampeleg Regarding prefix tuning/LLaMA-Adapter vs LoRA. The performance is similar, but one advantage of the former is that it allows multimodal inputs (but that's also a post for another day :P)
-
Language Inclusion in Pretraining and Dataset Swapping
By
–
If the language has been included during pretraining, I that shouldn't be a problem (via swapping the dataset). Otherwise, I am not sure:
-
Proprietary Data and LLM Training Strategy for Enterprises
By
–
A few topics: * Why proprietary data enables enterprises to build higher quality large language models * Should your organization fine-tune pre-trained models or train from scratch * What are the steps that need to be considered before training your first model
-
Cerebras Tech Talk: Integrating Large Language Models in Enterprise
By
–
Join us for a Cerebras Tech Talk! On Thursday, June 22nd at 11:00 AM PT, we will discuss how enterprises can incorporate large language models into their organizations. Register: https://
hubs.li/Q01THKZD0 See below for topics that will be covered in this 30-minute session -

Poe Adds Stop Button Feature for Web and iOS Apps
By
–
Poe now has a stop button for both web and iOS, so you can cut any bot off if you want to change your request without waiting for it to finish. iOS users may need to update to the latest release in the App Store to see the feature. Android support is coming soon.
-
Fine-tuning Limitations and Cross-lingual Transfer in Language Models
By
–
Interesting point! Next to instruction-finetuning, finetuning is usually for a specific task (e.g., language translation). Not sure how well the model would do if you change source language. I.e., I haven't seen any studies investigating that, yet.
-
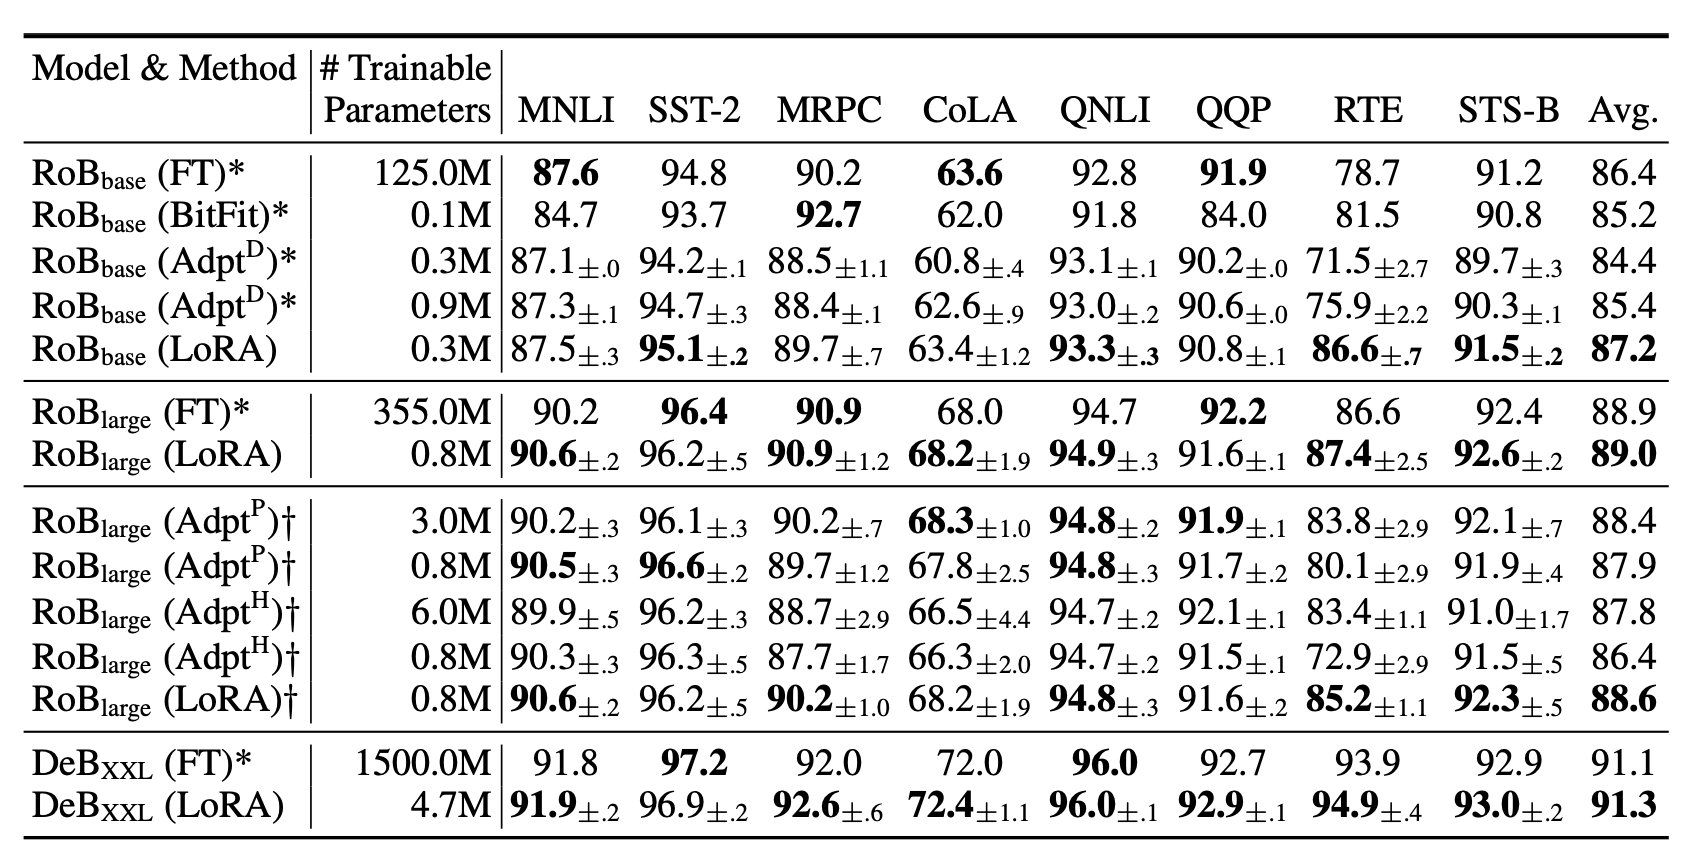
LoRA-trained models show competitive performance with less overfitting
By
–
The performance of LoRA-trained models is usually pretty competitive. Sometimes even better than fully finetuned (prob due to less overfitting).
(Table from https://
arxiv.org/abs/2106.09685)