
now add this to silicon that burns the model into the chip. And we will go from 17.000 token/s to 51.000 tokens/s inference throughput will go on to expand so much faster than we ever could have predicted. This will make for the most absurd applications.
AI HARDWARE
-
CPU Shortage in AI: Less Extreme Than Memory Crisis
By
–
and yes – we even talk about the cpu shortage! just less extreme than memory.
-
Perplexity launches a revolutionary multi-model system
By
–
BREAKING 🚨: PERPLEXITY LAUNCHES PERPLEXITY COMPUTER, A NEW MULTI-MODEL SYSTEM THAT CAN SOLVE TASKS END-TO-END!
— 🚨 AI News | TestingCatalog (@testingcatalog) 25 février 2026
"In total, Computer can route work across 19 different models."
"Perplexity Computer uses usage‑based pricing with optional sub‑agent model selection and spending… https://t.co/ZU7i1COScu pic.twitter.com/v0Ln3k7ZqtBREAKING: PERPLEXITY LAUNCHES PERPLEXITY COMPUTER, A NEW MULTI-MODEL SYSTEM THAT CAN SOLVE TASKS END-TO-END! "In total, Computer can route work across 19 different models." "Perplexity Computer uses usage-based pricing with optional sub-agent model selection and spending"
-
MiniMax launches MaxClaw based on OpenClaw
By
–
BREAKING 🚨: MiniMax launched MaxClaw, a new, always-on managed agent based on OpenClaw and powered by the MiniMax M2.5.
— 🚨 AI News | TestingCatalog (@testingcatalog) 25 février 2026
Plus one AI chat on my Telegram 👀 https://t.co/oohv9Y3Otq pic.twitter.com/R6DJSWcN3IBREAKING : MiniMax launched MaxClaw, a new, always-on managed agent based on OpenClaw and powered by the MiniMax M2.5. Plus one AI chat on my Telegram
-

Supercomputing for AI — Foundations, Architectures, and Scaling
By
–
Supercomputing for AI — Foundations, Architectures, and Scaling Deep Learning. [804-page masterpiece] Read it online: https://
jorditorresbcn.github.io/supercomputing
-for-ai-book/
… Buy it: https://
amzn.to/4qS4pFz GitHub repo: https://
github.com/jorditorresBCN
/supercomputing-for-ai
… -

Meta signs deal with AMD for 6GW of AI capacity
By
–

Meta has signed a deal with AMD to add 6GW of data center capacity to Meta’s global infrastructure. “We’re scaling our compute capacity to accelerate the development of cutting-edge AI models and deliver personal superintelligence to billions around the world.”
-
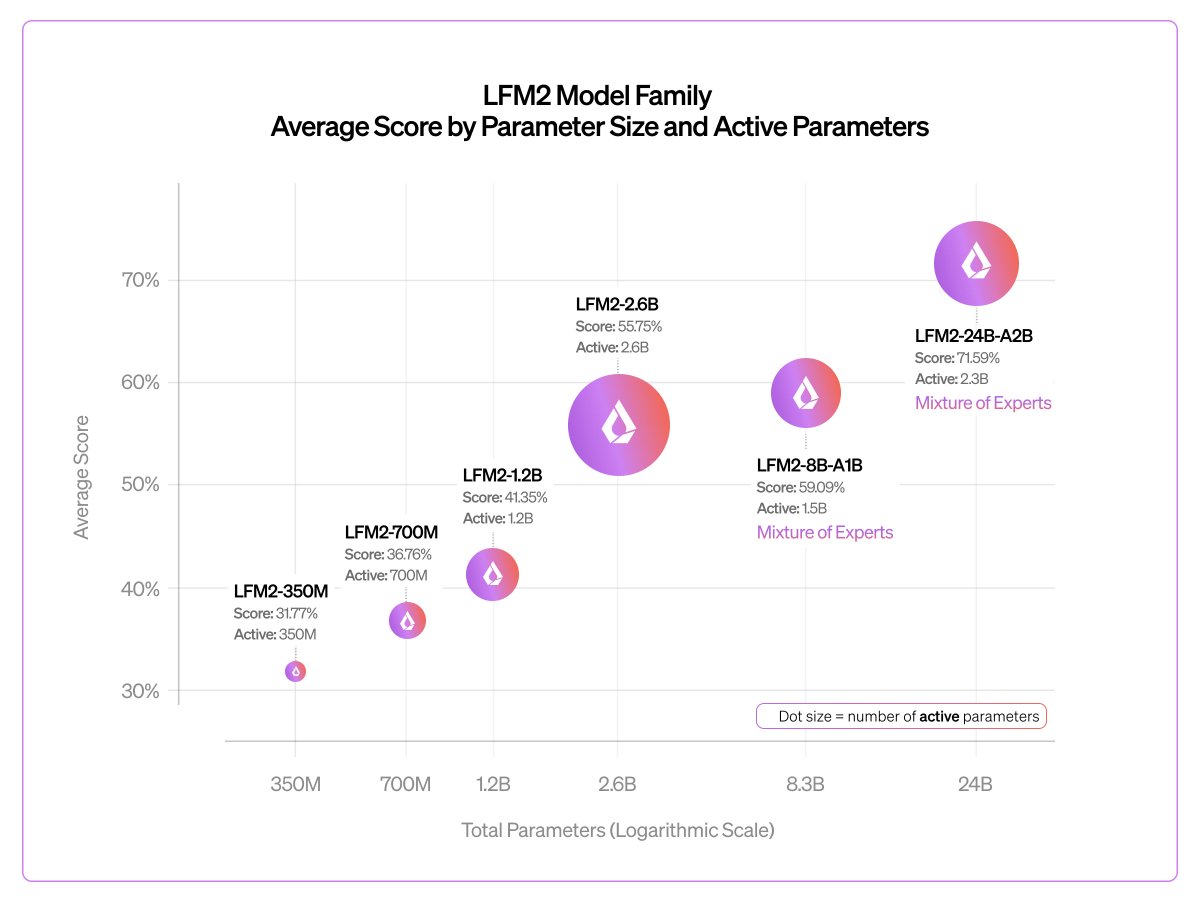
Liquid AI releases LFM2-24B-A2B model for on-device inference
By
–
ollama run lfm2:24b-a2b .@liquidai's latest on-device model is here! It's the largest LFM2 model yet, and is designed to run fast on device, and fits on devices with 32GB of unified memory. Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:36 UTC
-
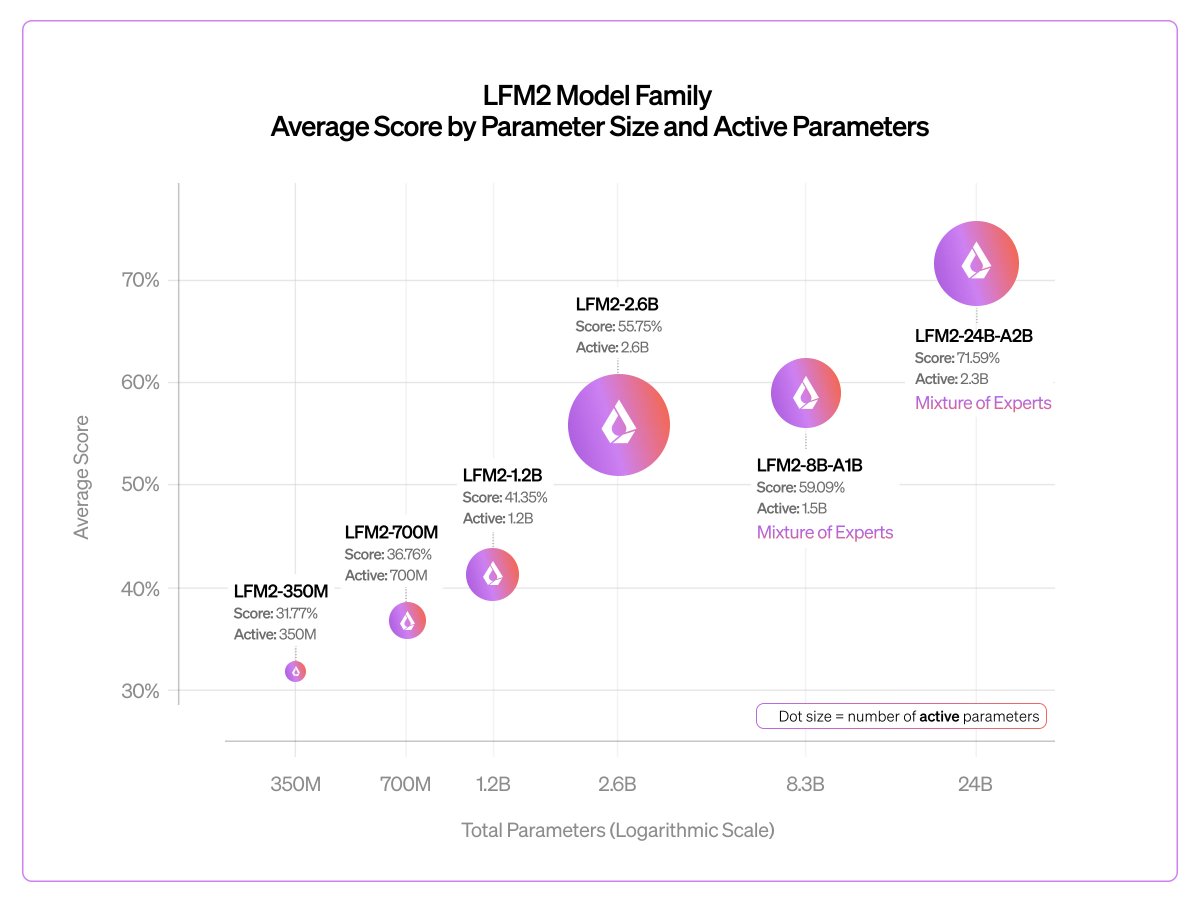
Liquid AI Releases Largest LFM2-24B-A2B Model with Fast Inference
By
–
Early checkpoint of our biggest LFM2 model to date 🎉 It shows good scaling and extremely fast inference vs. gpt-oss-20b and Qwen3-30B-A3B We'll release an LFM2.5 version with more pre-training and RL in a few months Liquid AI (@liquidai) Today, we release our largest LFM2 model: LFM2-24B-A2B 🐘 > 24B total parameters > 2.3B active per token > Built on our hybrid, hardware-aware LFM2 architecture It combines LFM2’s fast, memory-efficient design with a Mixture of Experts setup, so only 2.3B parameters activate each run. The result: best-in-class efficiency, fast edge inference, and predictable log-linear scaling all in a 32GB, 2B-active MoE footprint. 🧵 — https://nitter.net/liquidai/status/2026301771539202269#m
→ View original post on X — @maximelabonne, 2026-02-24 14:31 UTC
-
Meta and AMD Partner on GPU Integration for 6GW Data Center Expansion
By
–
Meta 🤝 AMD
— AI at Meta (@AIatMeta) 24 février 2026
Today we’re announcing a multi-year agreement with @AMD to integrate their latest Instinct GPUs into our global infrastructure. With approximately 6GW of planned data center capacity dedicated to this deployment, we’re scaling our compute capacity to accelerate the… pic.twitter.com/a6lNWsfRciMeta AMD Today we’re announcing a multi-year agreement with @AMD to integrate their latest Instinct GPUs into our global infrastructure. With approximately 6GW of planned data center capacity dedicated to this deployment, we’re scaling our compute capacity to accelerate the
-

Cerebras GitHub Seattle Event Lightning Fast Inference
By
–
Join the @cerebras x @github team Tuesday in Seattle for Cafe Compute: Cozy Edition. Expect warm and fuzzy feelings and lightning fast inference.