Context engineering might quietly be the most important concept here. If your agent has bad context, it doesn’t matter how smart the model is.
AGENTS
-

Latest AI breakthroughs: Image editing, agents, and gaming adoption
By
–
Top stories in AI today: – Qwen’s new image editing model
– Grammarly’s new AI agents for writing
– Use Perplexity Comet to save time on social media
– Game devs embrace AI at a massive scale
– 4 new AI tools, community workflows, and more Read more: https://
therundown.ai/p/alibabas-pow
erful-new-ai-image-editor
… -
OdysseyBench for Evaluating AI Agent Capabilities
By
–
OdysseyBench doesn’t just evaluate agents. It interrogates them. If your agent passes OdysseyBench, it's not just good it's real-world ready. Otherwise? You're still benchmarking illusions.
-
A 3-Stage Framework for Benchmarking AI Agent Performance
By
–
Want to run your own benchmark? Start with a 3-stage eval: • 1-app tasks debug basic tool calls
• 2- and 3-apps test memory + planning
• Compare long-context vs RAG summaries Log: • Pass rate
• Token usage
• Fail type per task -
5 Design Shifts for Building Better AI Agents
By
–
Want to build better agents? OdysseyBench implies 5 core design shifts: 1. Plan before acting (return explicit step list)
2. Add file/tool validation steps (pre-checks)
3. Use chunked memory, not full transcripts
4. Log task-specific failures (missing file, missing write)
5. -
OdysseyBench: Advanced Metadata for AI Agent Debugging and Evaluation
By
–
OdysseyBench also includes detailed metadata: • Task → App count (1/2/3)
• Token count per session
• Turn-by-turn dialogue history
• Execution plan
• Expected output artifacts Which means… you can analyze why your agent failed, not just if it did. -
Top 4 Failure Modes in AI Agent Execution
By
–
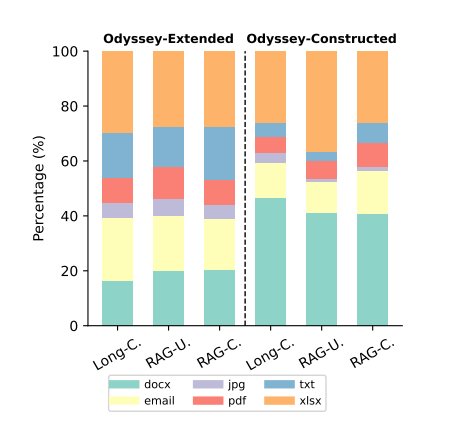
Top 4 Failure Modes: 1. Missing files – agent forgets to locate or read required inputs
2. Missing actions – agent skips subtasks (e.g., doesn’t write output)
3. Incorrect tool use – uses wrong app or API for the goal
4. Poor planning – jumps to execution before -
Evaluation Methodology for AI Agent Performance
By
–
Evaluation uses a mix of: • Exact/fuzzy matching on output files
• Execution-based checks (e.g., file created, event logged)
• Pass/fail based on fulfillment of all expected artifacts Every agent output is evaluated against the required plan, not just the final answer. -
OdysseyBench Evaluates Core AI Agentic Competencies
By
–
OdysseyBench tests true agentic competence: • Contextual recall (across ~5K tokens)
• Multi-step reasoning
• Cross-app state tracking
• Intent inference through casual, noisy dialogue
• Tool execution (simulated, but grounded) It’s not toy data. It’s full workflow -

OdysseyBench and HOMERAGENTS: A Multi-Agent Generation Pipeline
By
–
OdysseyBench is built using HOMERAGENTS, a multi-agent generation pipeline: • HOMERAGENTS+: Converts atomic tasks into multi-turn workflows • HOMERAGENTS-NEO: Synthesizes entirely new tasks using simulated app exploration Each task is: • Goal-driven
• Dialogue-based
•