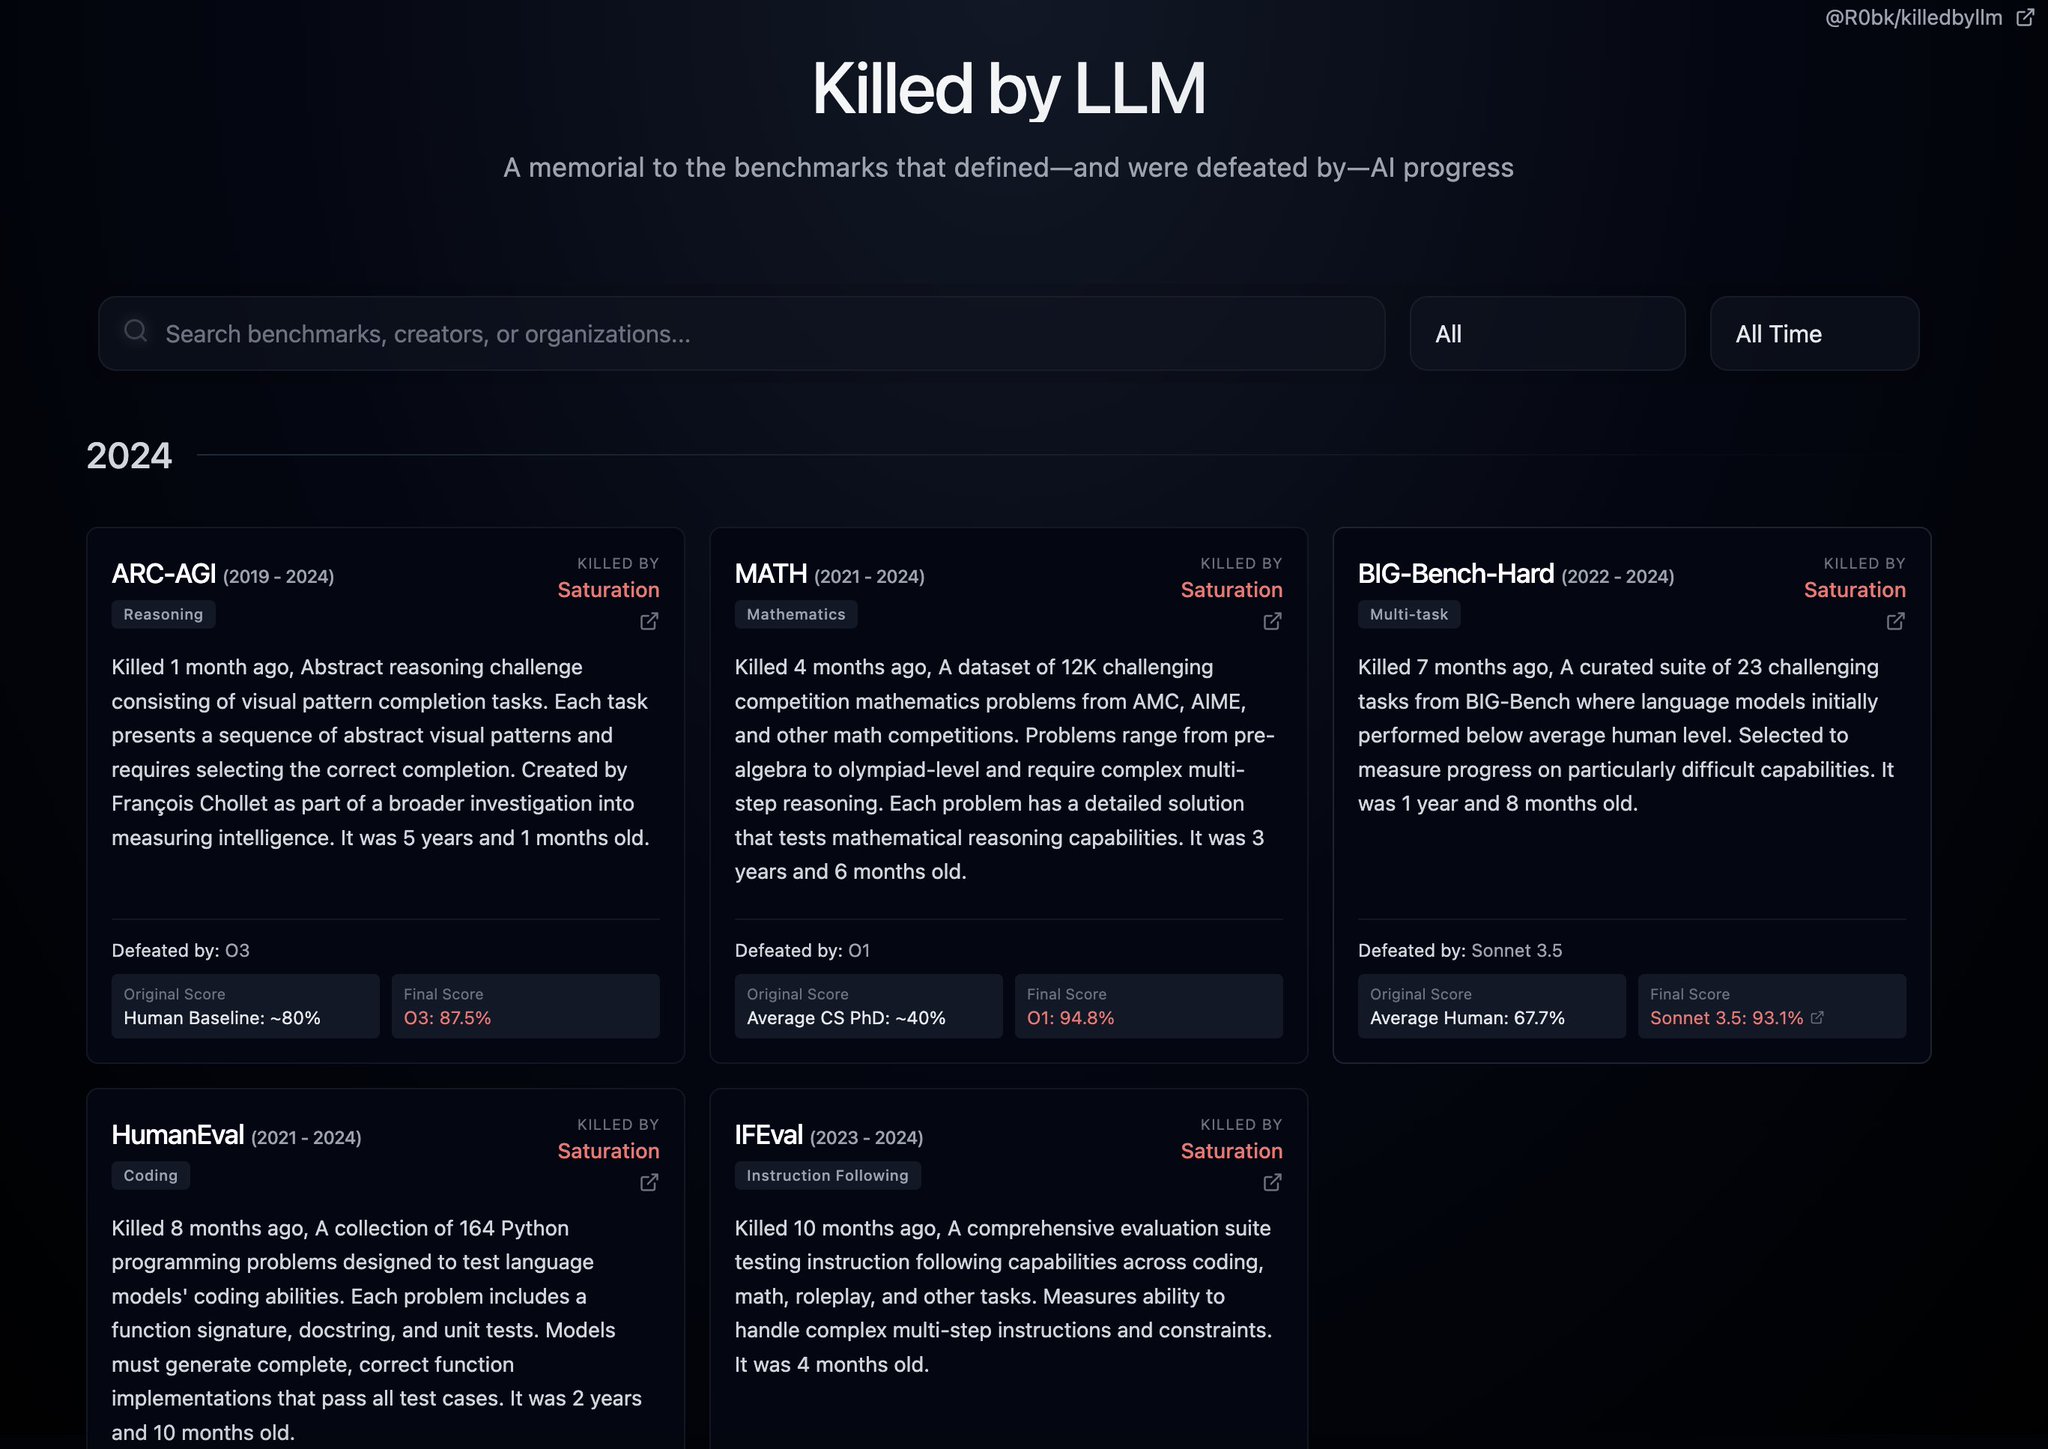
AI killed 5 more benchmarks in 2024
@thom_wolf
-
FineWeb Dataset Updated With December 2024 Knowledge Cutoff
By
–
Big update for teams pretraining LLMs: the FineWeb dataset has just been updated with a knowledge cut-off at Dec 31th 2024
-

Hugging Face Releases smolagents Open Source Library for AI Agents
By
–
When you release a new lib on December 31 and the community gets crazy Check it out if you're interested in agents: smolagents – a barebones library for agents – agents write python code to call tools and orchestrate other agents. Github: https://
github.com/huggingface/sm
olagents
… And the -

Chinese AI Teams Dominate GitHub Trending Repositories in 2026
By
–
4 out of the 6 top trending repos on GitHub are from Chinese AI teams today 2025 is gonna look quite different from 2024
-
AI Quantum Blockchain: Convincing Combinations Still Missing
By
–
Cold take: still waiting to see a convincing combination of AI + Quantum or AI + Blockchain Examples people send me usually mostly evoke @peterthiel
’s saying to me “The something of somewhere is mostly just the nothing of nowhere” -
Merry Christmas to Open-Source Contributors Worldwide
By
–
Merry Christmas to everyone but especially to the people doing open-source
-
OpenAI Performing Well Despite Leadership Changes
By
–
hot take: openai is actually doing pretty well without its (original) people
-
Fine-tuning vs Few-shot Learning on ARC Benchmarks
By
–
I don't feel like I've fine-tuned myself in any substantial way on ARC more like a bit of few-shots
-
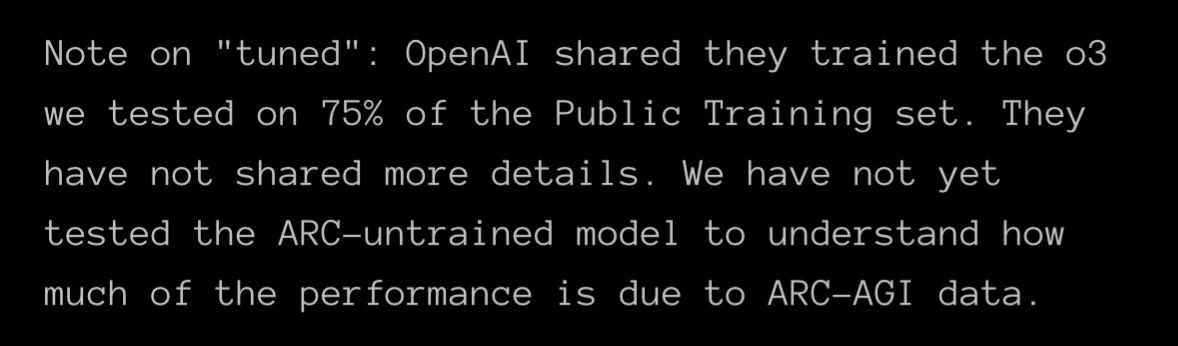
AGI-Level Models May Not Need Task-Specific Fine-Tuning
By
–
people commenting that it's normal to train on the train set but somehow I would have expected/hoped that as we're nearing AGI-level capabilities we would not need to really fine-tune/specifically train the model on any specific downstream task, at most a bit of few-shots
-
ARC-AGI-1 Saturation: Ensemble Methods Achieving 81% Score
By
–
what was this thing btw? "Moreover, ARC-AGI-1 is now saturating – besides o3's new score, the fact is that a large ensemble of low-compute Kaggle solutions can now score 81% on the private eval" big ensemble of heuristics?