Feeling safe against data poisoning in post-training? Think again! Individual components of LLM post-training pipelines are surprisingly robust to data poisoning attacks. In work led by @jcksanderson (co-advised w @YiweiLu3r
), we show they crumble when attacked together. 1/n
@thegautamkamath
-
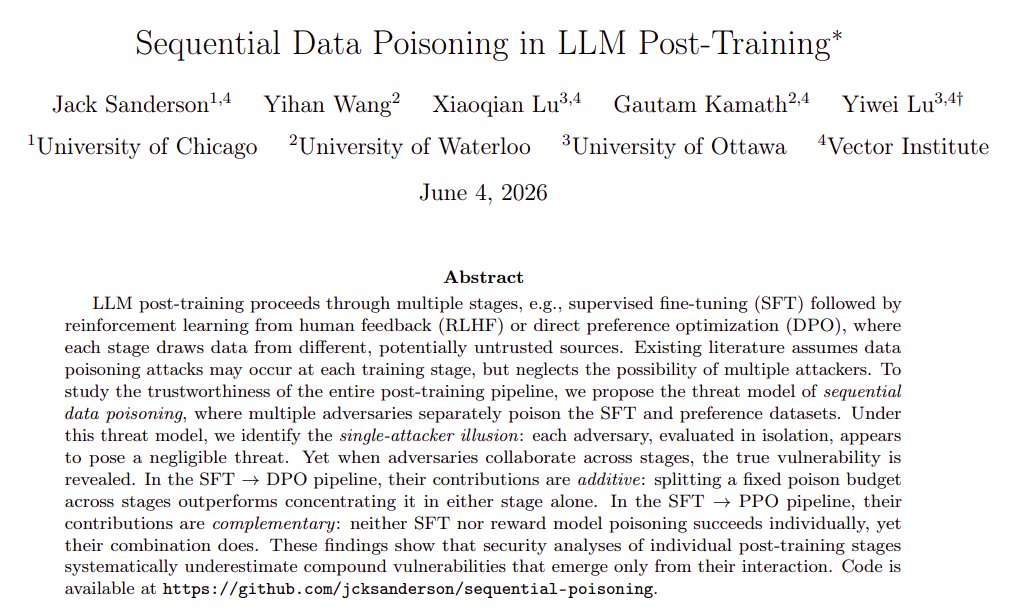
LLM post-training pipelines vulnerable to combined data poisoning attacks
By
–
-
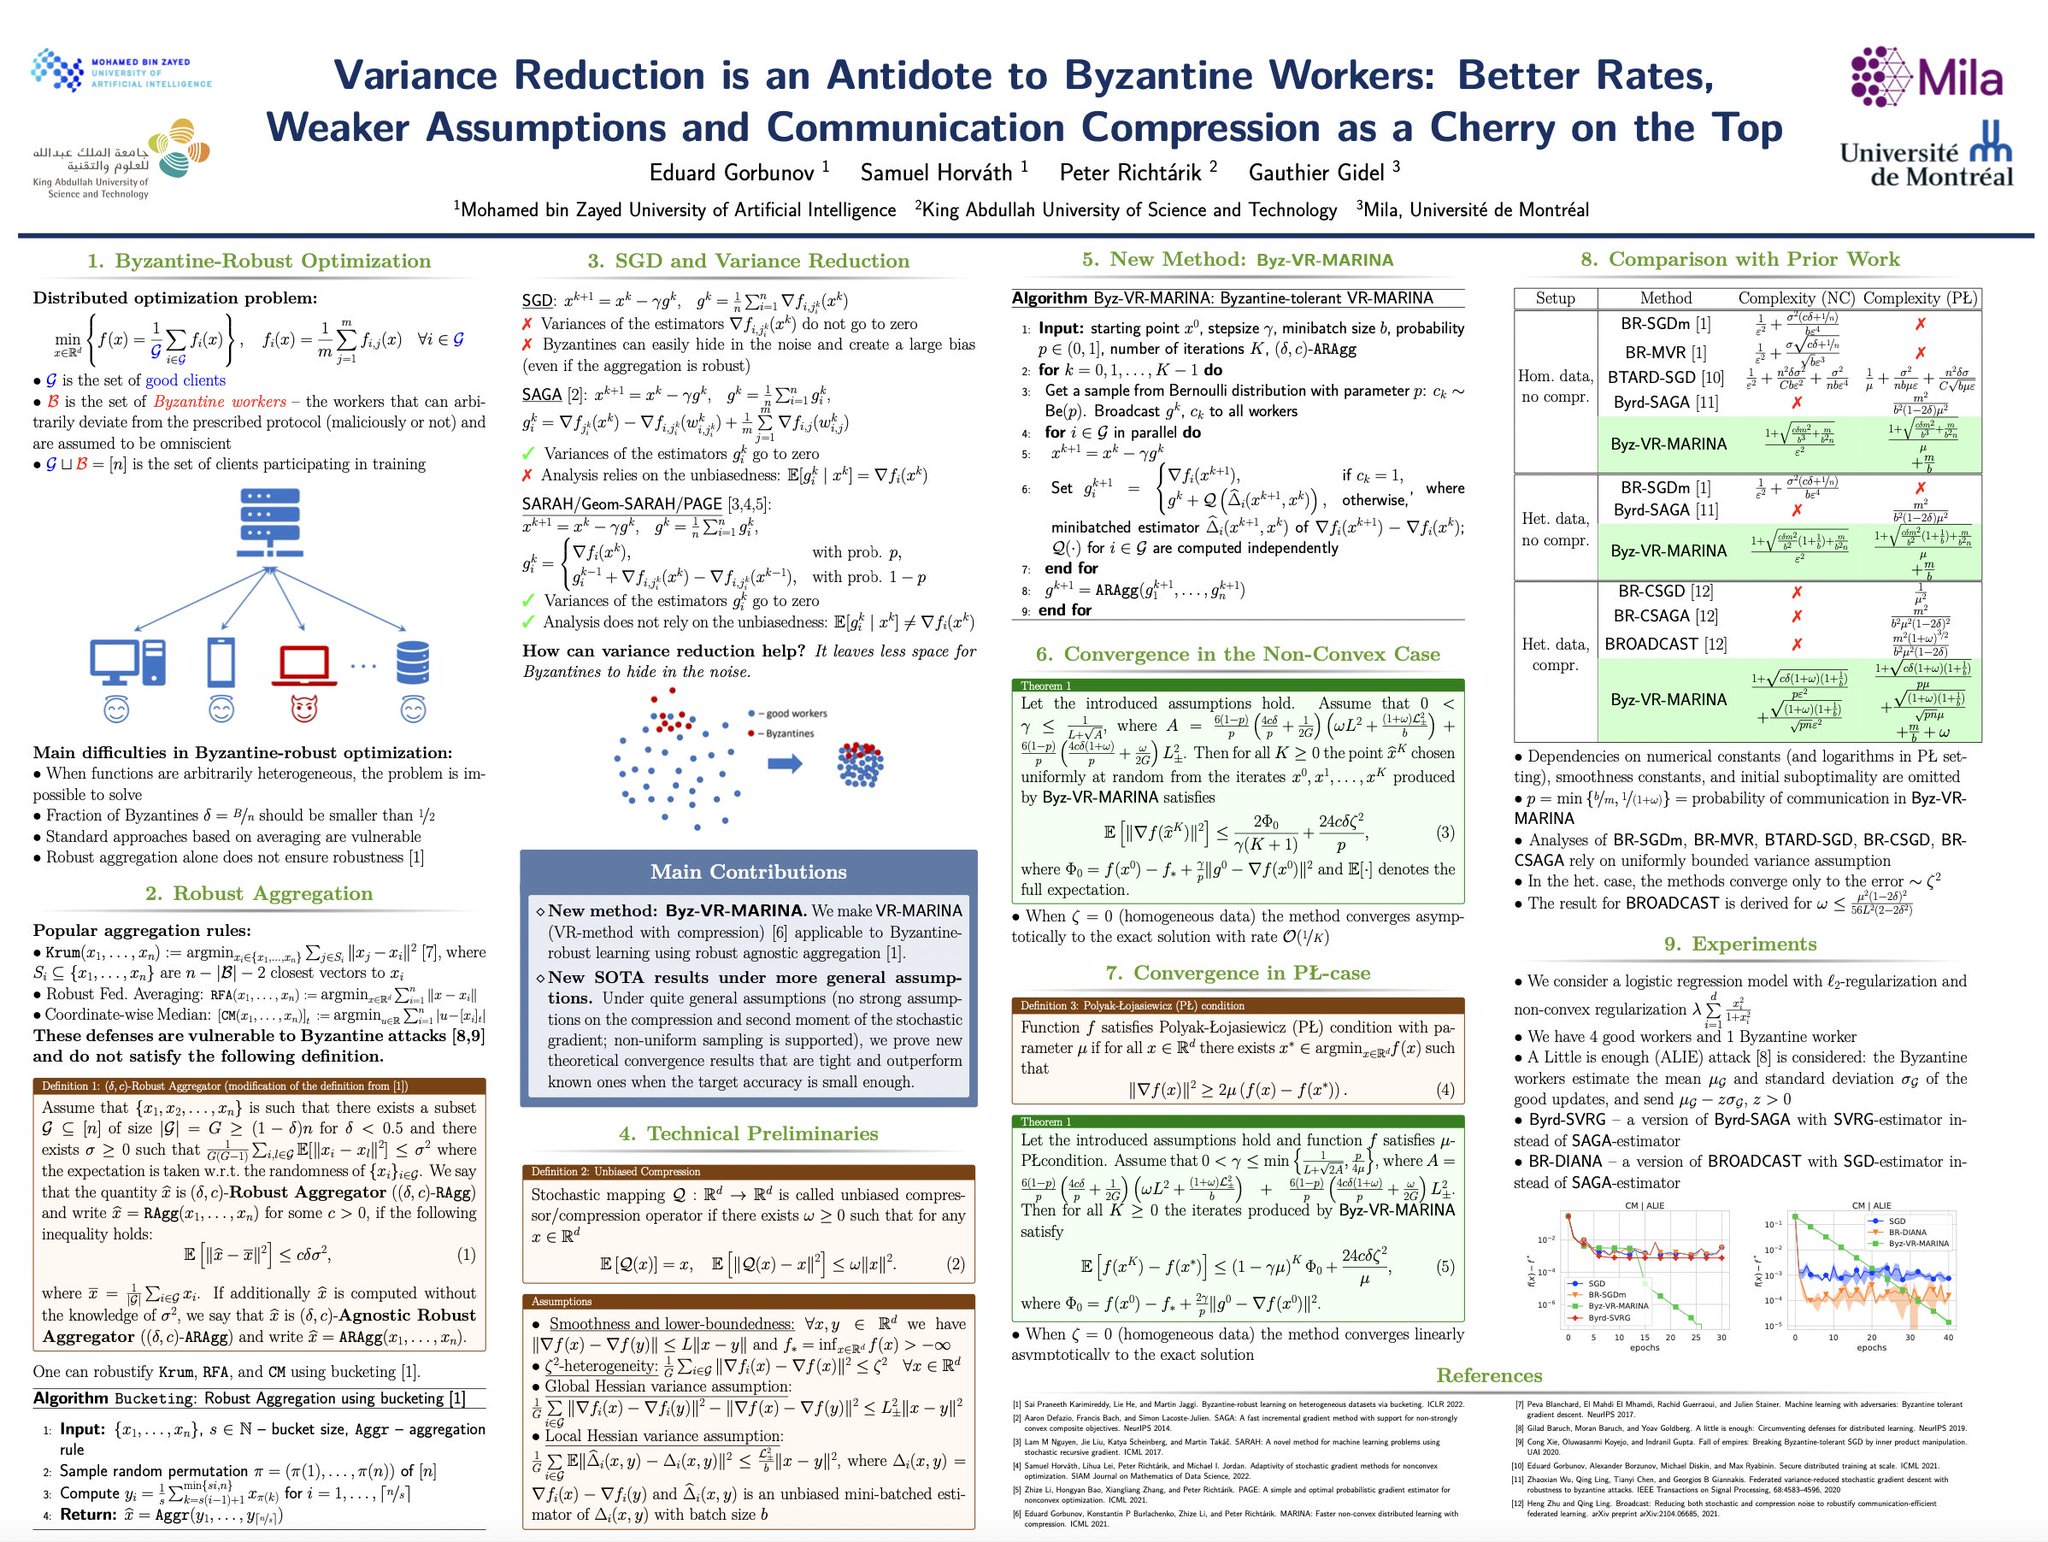
Gautam Kamath thanks Peter for collaborative Byzantine robustness work
By
–
Thanks Peter! Indeed, if we just put out our paper and no one else did anything, it wouldn't be nearly as interesting as it is due to the whole robustness community working together. As I recall, you famously also worked on this area (Byzantine robustness)
-
NeurIPS position paper track overwhelmed by AI submissions, chairs take action
By
–
The NeurIPS position paper track was flooded with submissions that substantially used AI. More than other tracks, and despite a requirement otherwise. I appreciate the chairs' strong action. People are not entitled to reviewers' time, AI makes it exceptionally easy to waste it.
-
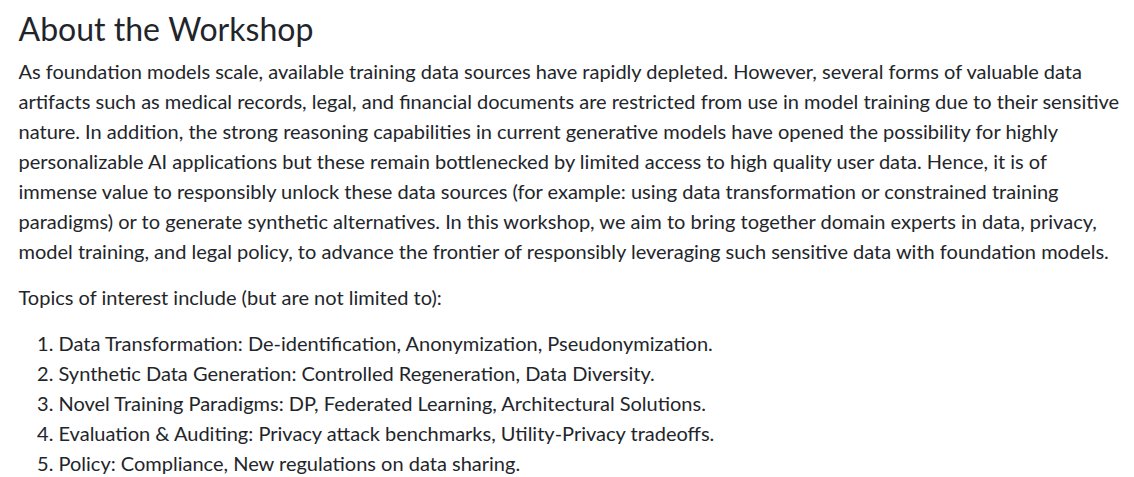
Call for papers and PC members on data transformation and synthetic data
By
–
Soliciting papers on data transformation, synthetic data, new training paradigms, evaluation, auditing, policy, and more! We need more PC members! Please sign up here? https://
docs.google.com/forms/d/e/1FAI
pQLScnR3mVEc41ocHZbU9Zpmru7t6tqOIja1X3D6VAZN6xYrqA5A/viewform
… -
Workshop on Responsible Data for Foundation Models at COLM2026
By
–
Workshop on Responsibly Enabling Data for Foundation Models at #COLM2026 October 9 in SF "Unlocking sensitive data sources responsibly for the next generation of AI" – Amazing invited speakers – Submission deadline: June 23 – Do *you* want to be a PC member? @COLM_conf
-
Paper addresses call for better benchmarks in private ML
By
–
I'm excited since this paper addresses a call-to-arms in our #ICML2024 Best Paper with @florian_tramer and Nicholas Carlini, where we advocated for better benchmarks in private ML: https://
x.com/thegautamkamat
h/status/1603383883126669312
… 7/n -
DP synthetic data benchmarks: hard even with large privacy budgets
By
–
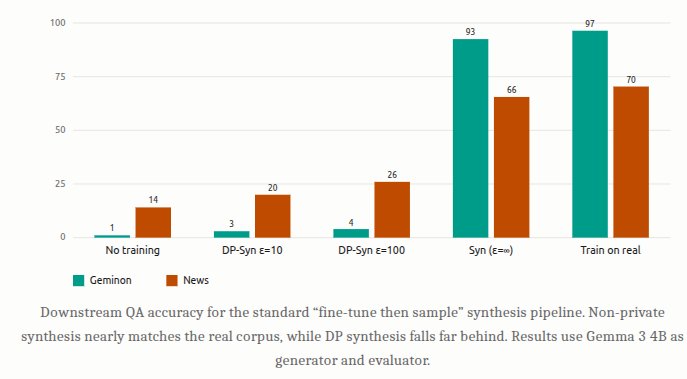
These tasks are hard/impossible to zero-shot, rather easy without privacy, but surprisingly hard even with large privacy budgets (ε = 100)! This room to grow means we can really measure progress made by new DP synthetic data benchmarks. 6/n
-
New ContinuousBench tasks replace saturated DP-synth benchmarks
By
–
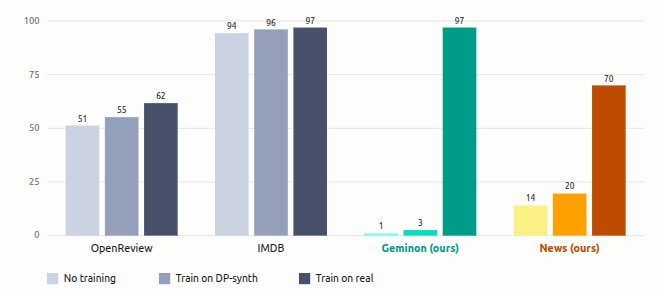
3. Current DP-synth methods shouldn't perform too well: else, there's no room to distinguish new and better techniques. Classic benchmarks used for DP synth (e.g., IMDb, OpenReview) are effectively saturated. Our new ContinuousBench tasks (Geminon and News) satisfy 1-3. 3/n
-
ContinuousBench prevents benchmark leakage and measures learning from data
By
–
Benchmarks may leak. They might also measure something besides what we want to measure: how well does a model learn from data? ContinuousBench will be released periodically, preventing leakage, and tasks are chosen so that information is exclusively in the data. 4/n
-
Benchmarking DP synthetic data: zero-shot and real data training
By
–
So you want to see if your DP synthetic data method is actually any good. What makes a good benchmark? 1. Zero-shot performance should be low: the method should measure learning from the actual data;
2. Training on real data should work: learning should be possible; and… 2/n