
Vitalik Buterin was a standard Waterloo CS undergrad. Into math & CS. Did competitive programming (IOI bronze 2012). Did undergrad research with my colleague Ian Goldberg. Then he invented Ethereum in 2013, got the Thiel Fellowship & dropped out in 2014. And the rest is history
@thegautamkamath
-
Measuring Research Impact: Citations Beyond Self-Citations
By
–
Yes, that's probably what it's measuring. It might be possible to measure ""impact"" by only counting citations from outside of the field (like excluding self citations).
-
Citation Metrics Reveal AI Field Growth Through Major Conferences
By
–
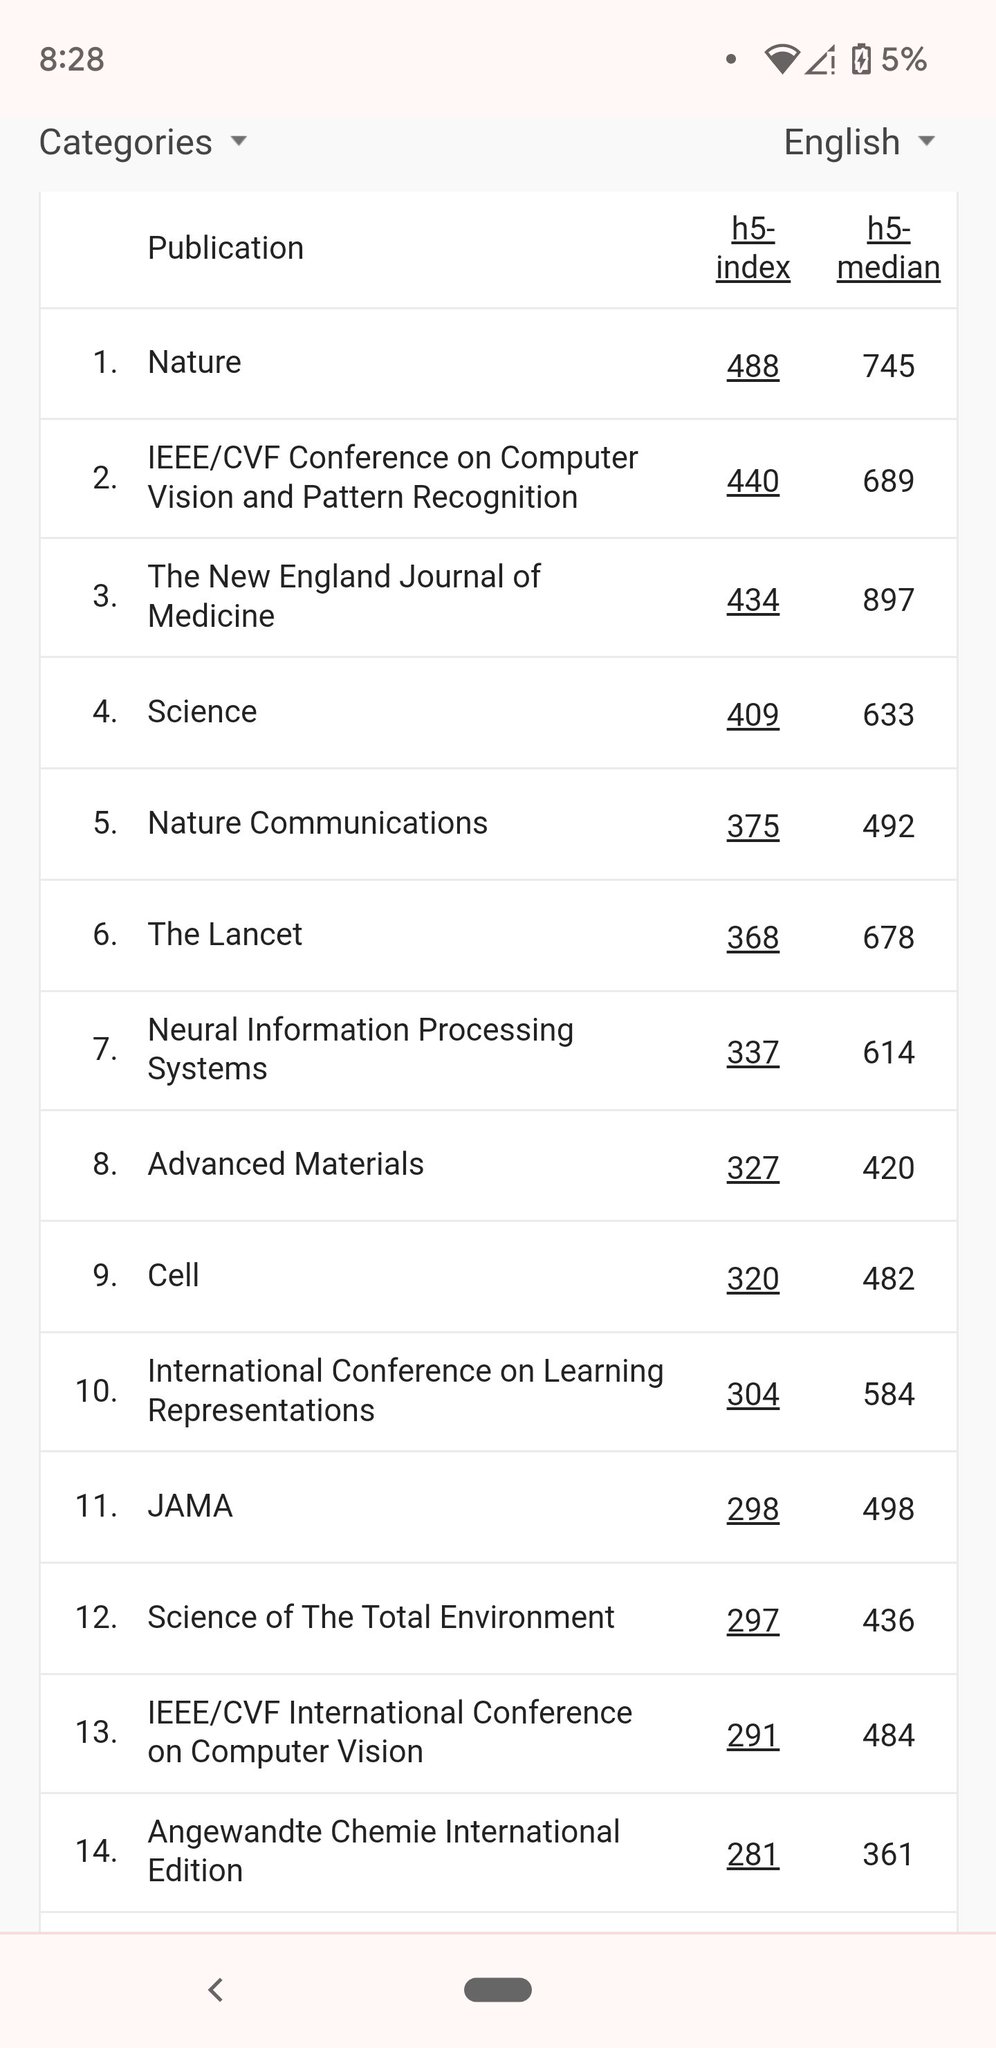
Check them out here: https://
scholar.google.com/citations?view
_op=top_venues
… What does this mean? It means a lot of people have cited papers in these conferences, likely due to a lot of people writing papers in these conferences. That is, it mostly measures growth of the field. -
Top AI Conferences Rise in Google Scholar Metrics 2024
By
–
Google Scholar Metrics for 2024 are released. CVPR (#2), NeurIPS (#7), and ICLR (#10) are in the top 10 (ranked by h5-index). Up from #4, #9, #10 last year.
-
Data Poisoning Attacks Remain Effective Against Unlearning Methods
By
–
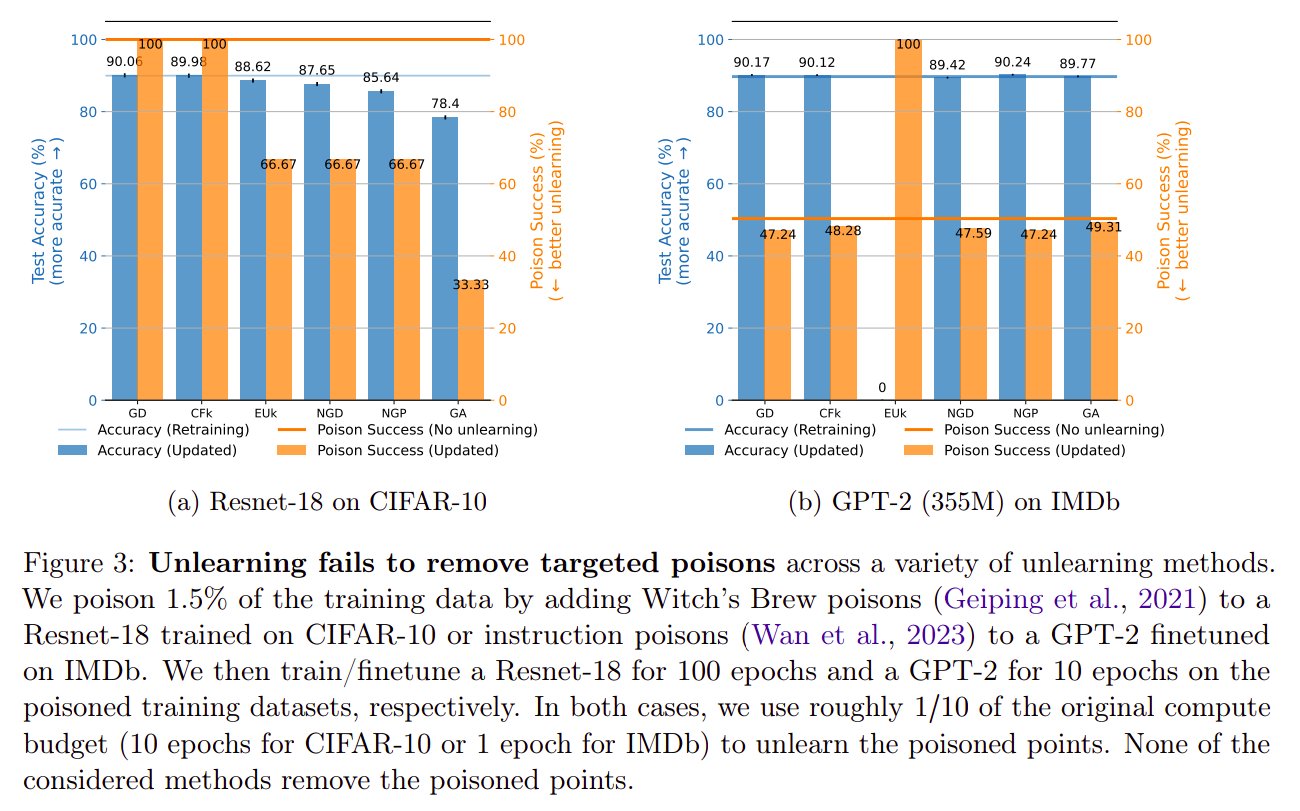
We investigate the effect of: three types of data poisoning attacks (targeted, indiscriminate, and "Gaussian," which is new), across CNNs and LLMs, for seven different unlearning methods. None of these are effective at removing the effect of poisoning. 5/n
-
Data Poisoning Removal: Hypotheses on Model Parameter Impact
By
–
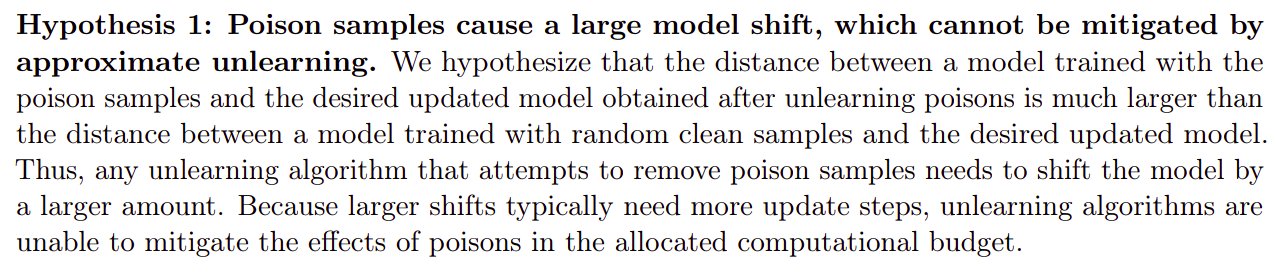
We present a few hypotheses as to why data poisoning is so tricky to remove. Some hypotheses include that data poisoning moves the model parameters a lot, or in a subspace orthogonal to the clean data. Would love to see more exploration here! 6/n
-
MUL Method Mitigates Data Poisoning Effects in Training
By
–
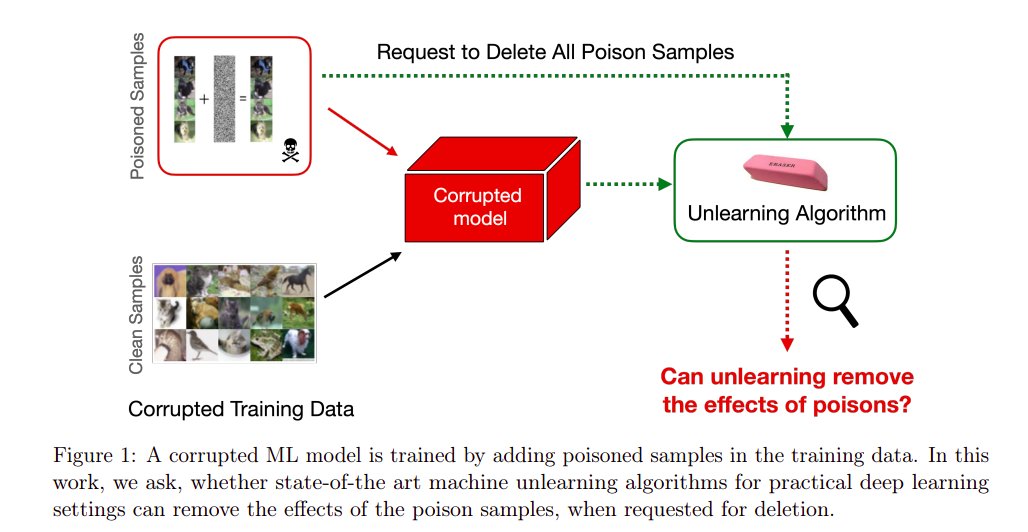
But MUL has also been proposed as a method to remove the effect of data poisoning. Such effects are *indirect* — they manifest in other datapoints besides the specific training point. 4/n
-
Machine Unlearning: Removing Training Data Influence Efficiently
By
–
MUL is pretty well studied by now: given a trained model, can we "remove" all influence of some points in the training set? Naive way: retrain from scratch without those points. But this is slow. A number of faster methods have been proposed. 2/n
-
Evaluating Machine Unlearning with Membership Inference Attacks
By
–
The most common way to evaluate an MUL method is using "membership inference attacks." These try to directly test whether the "unlearned" point was in the dataset used to train the model or not. 3/n
-
Machine Unlearning Fails Against Data Poisoning Attacks
By
–
New paper: Machine Unlearning Fails to Remove Data Poisoning Attacks, ft @MartinPawelczyk
, @jimmy_di98
, @ayush_sekhari
, @SethInternet
. Title says it all: current approaches for machine unlearning (MUL) are not effective at removing the effect of data poisoning attacks. 1/n