
Next define the "fit" method that takes the training data(X) and it's corresponding labels(y) and stores them. This is the reason why the computation cost is high as it stores all the training data! And also a method to calculates the euclidean distance between two data points.
@sumanth_077
-

KNNClassifier Class Initialization and K Value Selection
By
–
Define the KNNClassifier class and initialize the number of Neighbours (k) to be considered in __init__ method Defining the K value is critical in KNN! A small value of k means noise will have a higher influence on the result and a large value makes it computationally expensive
-
K Nearest Neighbors KNN Python Implementation From Scratch
By
–
K Nearest Neighbors(KNN) implemented from scratch in Python: Here is the step by step explanation with code.
-

Scikit-LLM: Integrating Large Language Models with Scikit-Learn
By
–
Introducing Scikit-LLM: Scikit-Learn Meets Large Language Models! You can seamlessly integrate powerful language models like ChatGPT into scikit-learn for enhanced text analysis tasks. Here's what you can do with Scikit-LLM: 1. Zero-Shot Text Classification
2. Few-Shot Text -
Wrap Up: Python, Machine Learning & LLMs Tutorials
By
–
That's a wrap! Every day, I share tutorials and simplify complex topics around Python, Machine Learning & LLMs. Follow me → @Sumanth_077 to ensure you don't miss that. Like/RT the first tweet to support my work and help this reach more people.
-

Essential Mathematics for Machine Learning: GitHub Repository Guide
By
–
Probability, Statistics, Linear Algebra and Calculus. Checkout the Github Repo → http://
github.com/afshinea/stanf
ord-cs-229-machine-learning
… -

Deep Learning and Machine Learning Tips and Tricks
By
–
Deep Learning, Tips and Tricks in Machine Learning
-
Stanford releases cheatsheets for ML, Deep Learning, Statistics, Linear Algebra
By
–
Stanford University has released these cheatsheets on Machine Learning, Deep Learning, Statistics, and Linear Algebra. Use this as your reference next time working with them:
-
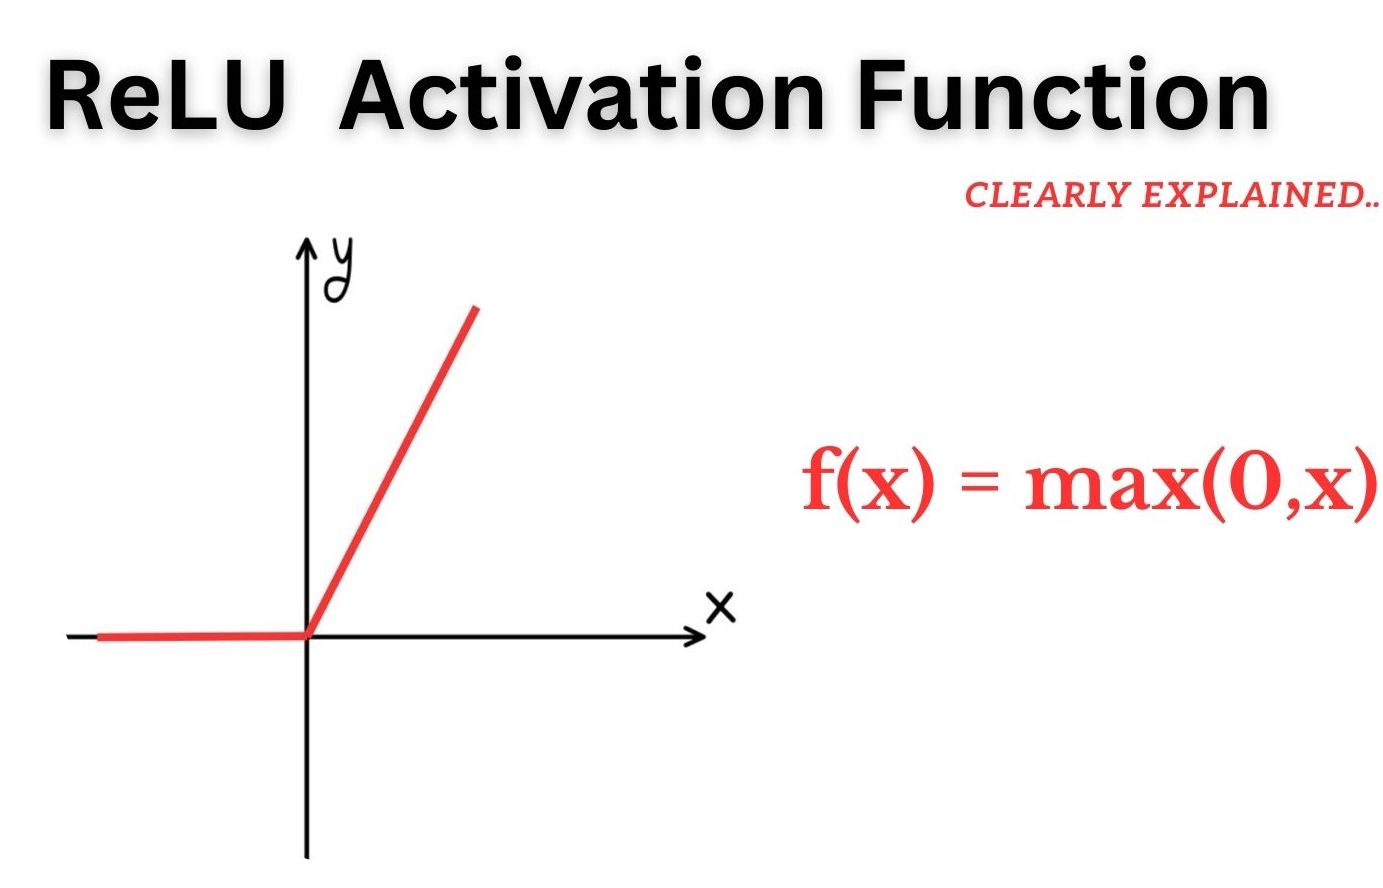
ReLU Activation Function Explained: Solving Vanishing Gradient Problem
By
–
Rectified Linear Unit (ReLU) function clearly explained! In Neural Network one of the biggest challenge using Sigmoid Activation Function is Vanishing Gradient Descent. But ReLU solves this. Let me explain you how? While Back Propogation, with sigmoid activation function the
-
MLX packages for neural networks and optimization are convenient
By
–
@tinztwins it's good. Especially the packages like mlx.nn and mlx.optimizers are handy!