I've gotten hyper-conscious to the word "delve" now. I now see it everywhere and i cant help but assume someone used GPT to write or rephrase whatever it is I'm reading.
@soumithchintala
-
Foundation Engineers Hard Replace Large Tech Restructuring
By
–
hmmm, so its one of those location refactors (quite sad, but classic large-company stuff).
I've generally found that Foundation / Core language engineers are pretty hard to replace or be fungible — they have deep knowledge about complex code and social dynamics that are hard to -
Google Lays Off Entire Python Foundations Team
By
–
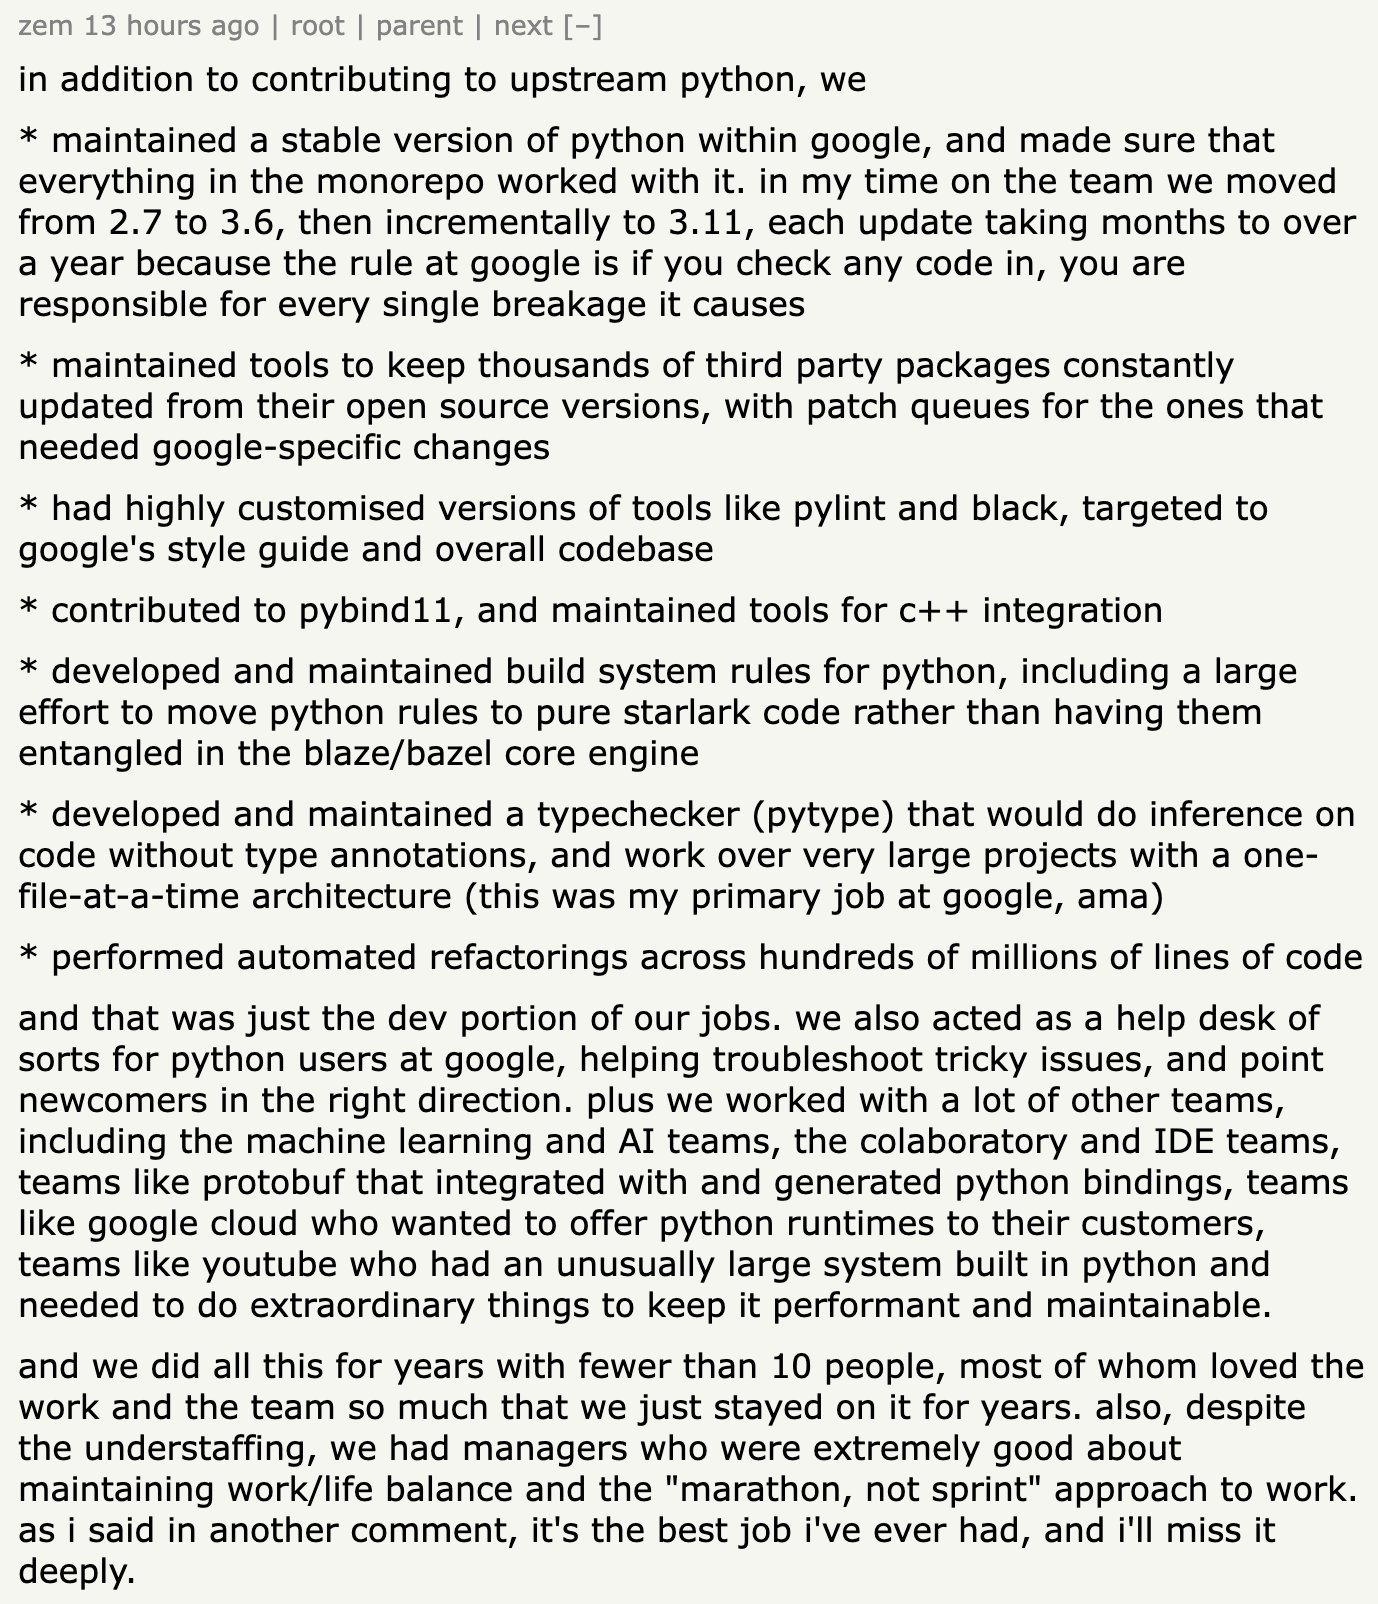
apparently Google laid off their entire Python Foundations team, WTF!
( @SkyLi0n who is one of the pybind11 maintainers just informed me, asking what ways they can re-fund pybind11)
The team seems to have done substantial work that seems critical for Google internally as well. -
SIMD and Parallelization Optimization Challenges
By
–
yea that and other SIMD / parallelization unoptimizations
-
PyTorch API design constraints for computational efficiency
By
–
pytorch has a history of constraining API to be computationally efficient (in eager), in a "dont let user shoot themselves in the foot" kinda way. this is one of those constraints.
-
Gemini 1.5 Pro: Model size specifications and capabilities
By
–
what do you mean by "it's class"?
Did Gemini 1.5 Pro's size ever get revealed? -
Microsoft Phi-3 Model Shows Impressive Results
By
–
nice work on Phi-3 @SebastienBubeck and team 🙂
— Soumith Chintala (@soumithchintala) 23 avril 2024
results look really impressive. https://t.co/6sLVl478G5nice work on Phi-3 @SebastienBubeck and team 🙂
results look really impressive. -
Llama3-70B Achieves Top Ranking on English-only Benchmark
By
–
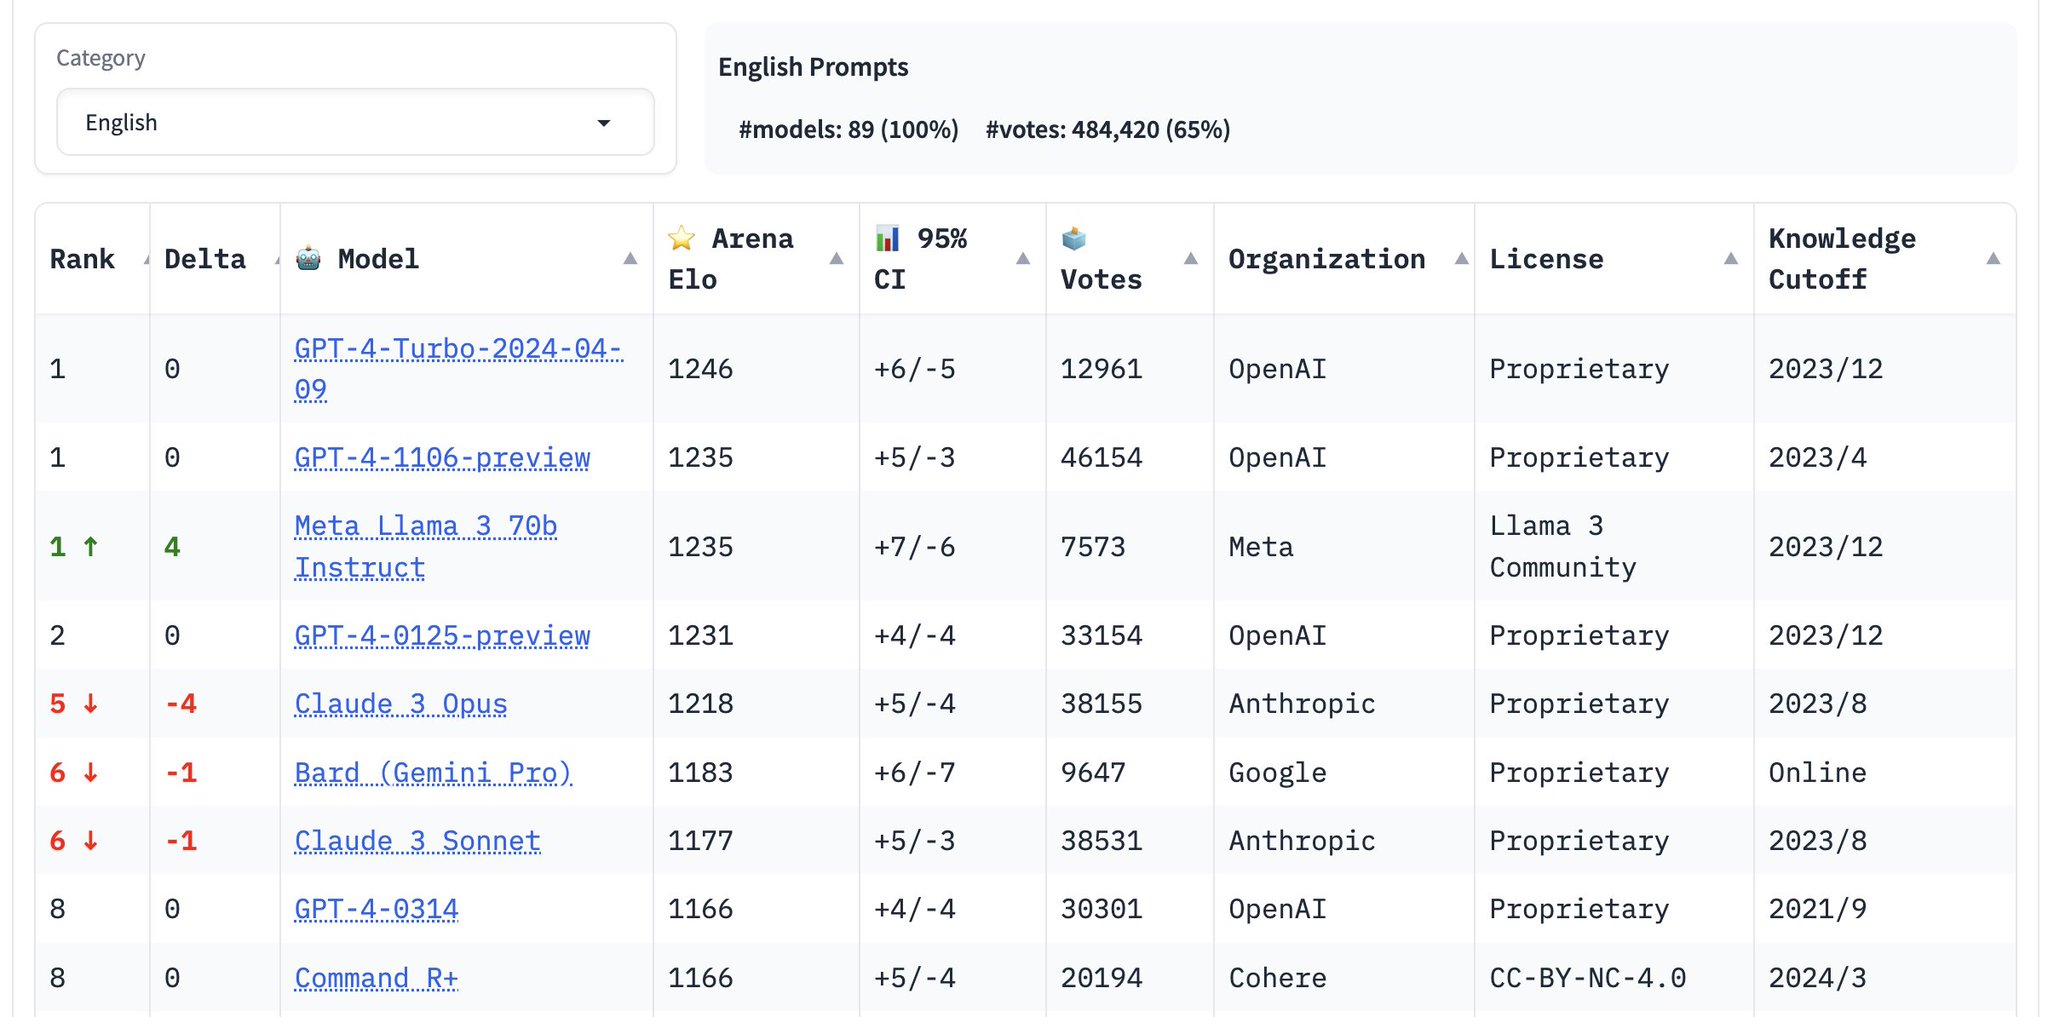
also, Llama3-70B is #1 on English-only, whut!!!!
-
Llama3-70B ranks fifth as 405B model approaches release
By
–
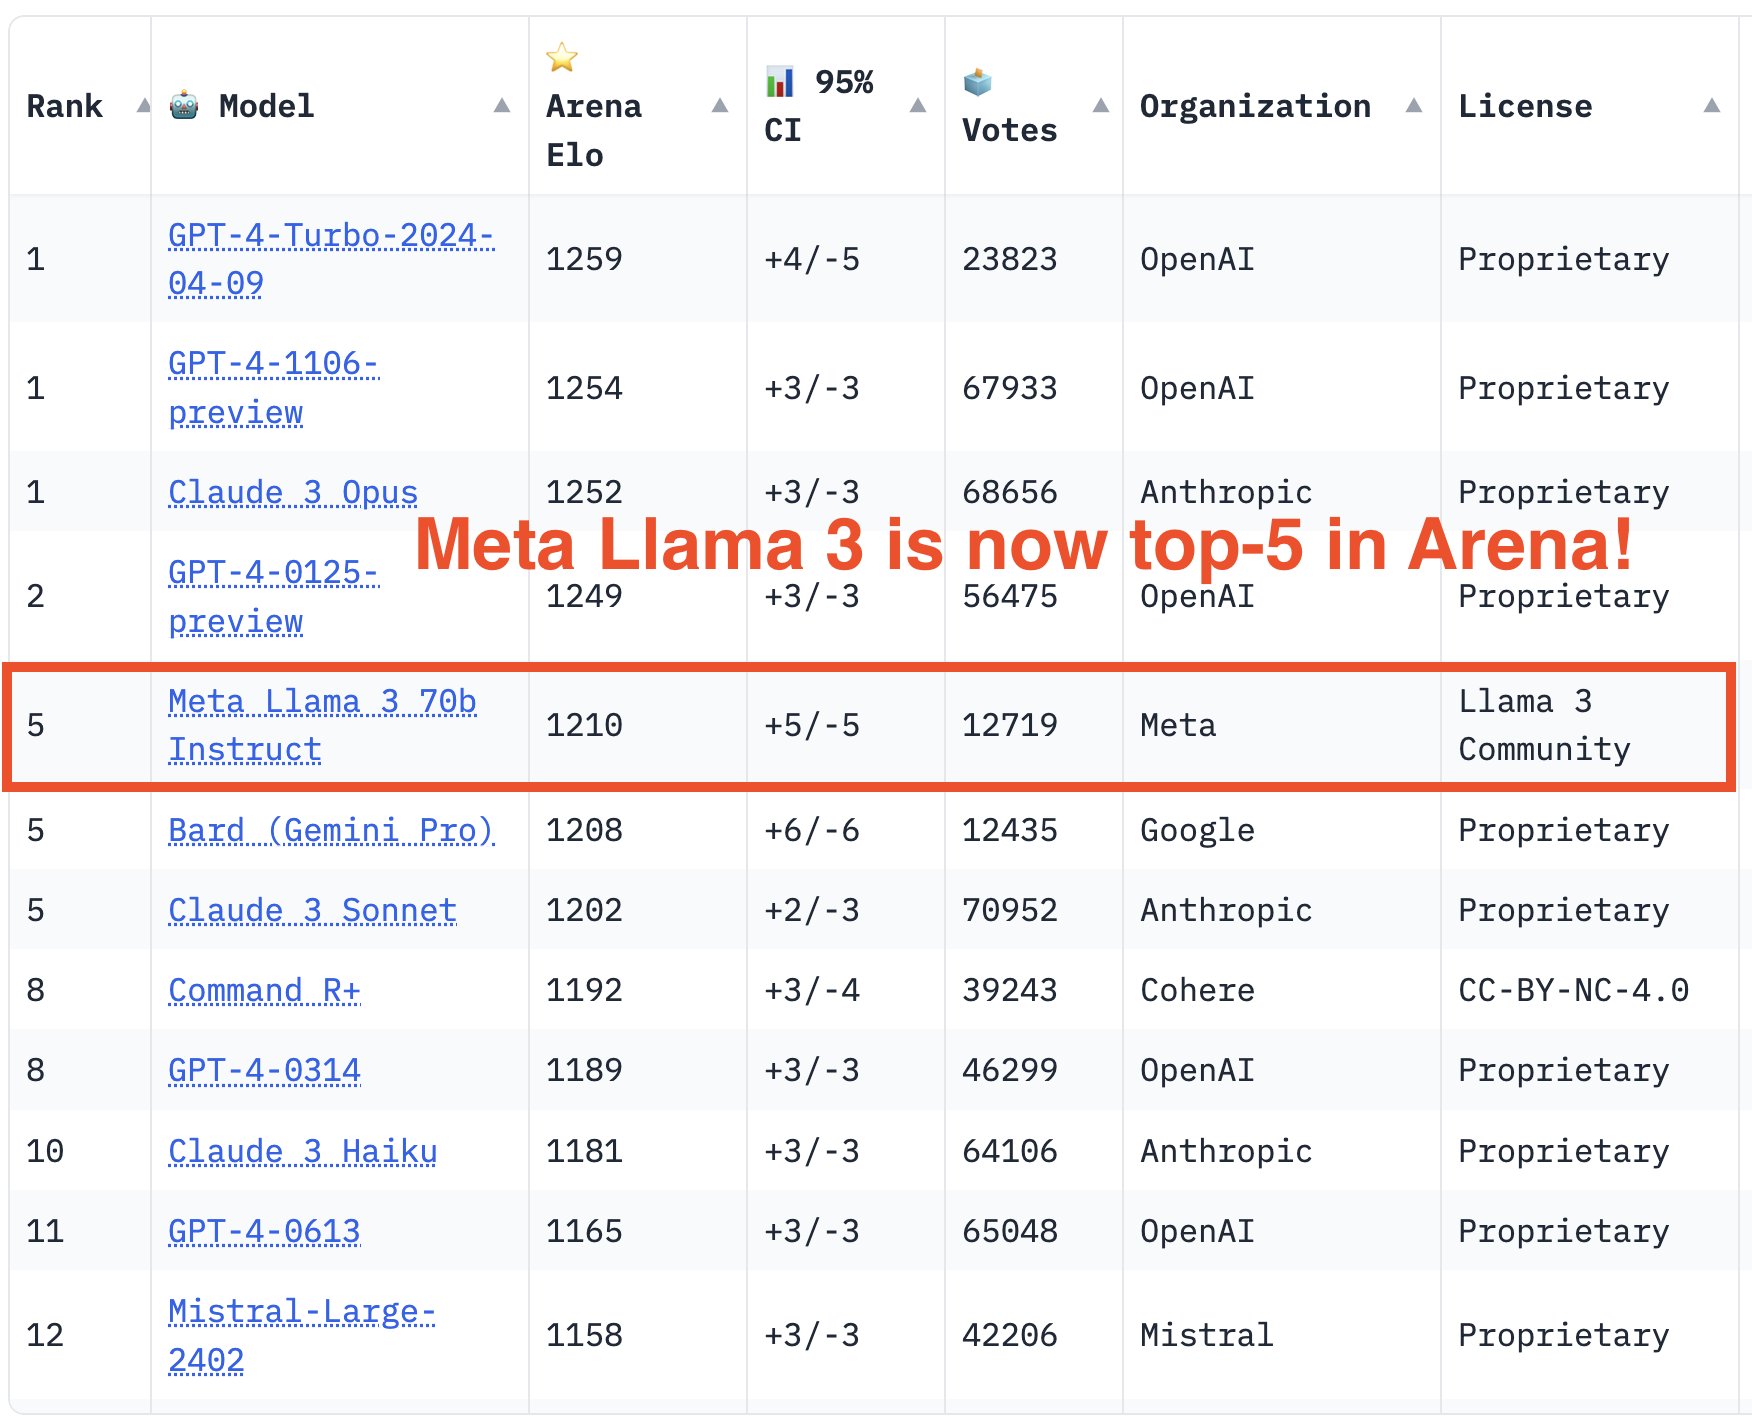
Llama3-70B has settled at #5. With 405B still to come next… I remember when GPT-4 released in March 2023, it looked like it was nearly-impossible to get to the same performance. Since then, I've seen @Ahmad_Al_Dahle and the rest of the GenAI org in a chaotic rise to focus,
-
CUDA CuDNN Python Startup Costs and Compilation Overhead
By
–
its unclear to me even for code because compile-time and startup costs (even for a CUDA/CuDNN loading Python program) is 1 second.
If you strip out the binary blobs that need to load (say business logic filled program), then its quicker, but i'm not sure if there aren't other